primer.ml.generative.multimodal
Multimodal models: images, audio and video into a language model
Run: python -m primer.ml.generative.multimodal
This lesson builds on the transformer of primer.ml.transformer, its
attention (primer.ml.attention) and positions (primer.ml.positional),
and the CLIP image encoder of primer.ml.embeddings.contrastive;
primer.notation explains every symbol from zero.
Level 1: The practitioner's guide
In one sentence. A multimodal model turns images, audio and video into sequences of vectors the same width as a language model's word vectors, so one transformer can read (and, with a codebook, write) all of them; for a practitioner, every picture, second of sound or frame of video is a number of tokens, and that number is the cost, the latency and the limit.
When you need it. You need this lesson the moment a model has to read something that isn't text: a screenshot, a chart, a scanned form, a voice message, a meeting recording, a video clip. Whether you call a hosted vision model or build with an open one, the same questions decide the outcome: how many tokens each input becomes, at what resolution, in what order in the prompt, and whether the model needs the signal at all or only its words. You don't need a multimodal model when the words are all that matters: a transcript of speech is about 3.2 tokens a second where audio tokens are 50 a second (this lesson's rates), and a caption is a few dozen tokens where a 336 × 336 image is 576. The number that shows how fast the naive approach fails: send a 10-second clip at 30 frames a second with 256 tokens a frame and it is 76,800 tokens, more than half of a 128,000-token window, before a single word of the question. Keep one frame a second and it is 2,560.
Your options. From the cheapest to the most control:
| Option | What it does | What it guarantees | What it costs | Where it lives |
|---|---|---|---|---|
| Turn the signal into text first | Transcribe audio (Whisper), caption or OCR an image, then use a text model | The densest input there is: hours of speech in one window | Loses tone, layout, small detail and anything the captioner missed | Your pipeline, ahead of the model |
| A hosted multimodal API | Send the image or audio in the prompt; the vendor's encoder tokenizes it | No infrastructure; a documented token count per image | Tokens per image by area (a 1000 × 1000 image is 1,296 tokens on one API); resizing above a size limit | The vendor's API |
| An open vision-language model | A ViT's patch vectors pass through a projector into the prompt (LLaVA's recipe) | Full control of resolution, tiling and prompt layout | A GPU; 196 to 576 or more tokens per image at your chosen resolution | Your server |
| A compressed-visual family | New cross-attention layers (Flamingo) or a small set of learned queries (BLIP-2's Q-Former) read the image instead of splicing it | A short text sequence however many images; 32 to 64 tokens per image | Some detail lost; a different model family to adopt | The model family you download |
| Align your own projector | Freeze a vision encoder and a language model, train the small adapter between them on captions, then tune on instructions | A model that speaks your domain's pictures, cheaply (stage 1 runs in hours) | Captioned data, then instruction data; a stage-2 fine-tune for behaviour | Your training loop |
| Discrete tokens for generation | Snap image or audio vectors to a learned codebook so the model predicts them like words | One model reads and writes every modality with next-token prediction | 1,024 ids for a 256 × 256 image; 600 ids a second for codec audio | A tokenizer plus the language model |
How to choose. Start from what the model must get out of the signal, then count the tokens.
- Only the words matter (a voicemail, a lecture, a document with plain text): transcribe or OCR to text and use a text model. It is the densest and the cheapest by a wide margin.
- Layout, tone, colour or small detail matters (a chart, a screenshot, a form, a hesitant customer): send the signal itself, at the smallest resolution that still shows the detail, cropped to the region that matters.
- Long video: sample frames (one a second for a lecture, more for anything fast), merge neighbouring patch tokens, and send the soundtrack as a transcript alongside.
- Your own domain, weak results from general models: align a projector on your captions first (cheap and safe, since both big models stay frozen), then instruction-tune.
- Generating pictures or speech from a language model: discrete codebook
tokens for simplicity, or hand the language model's output to a diffusion
model (
primer.ml.generative.diffusion) for finer detail. - Whatever you pick, put the image before the question. The language model is causal, so text placed before an image is scored as if the image were not there; the hosted API's own guidance says the same.
What it costs. Tokens grow with the square of the side: a 224 × 224 image in 16-pixel patches is 196 tokens, a 336 × 336 image in 14-pixel patches is 576, and a 1008 × 1008 image with 2 × 2 neighbours merged is 1,296. Hosted APIs bill the same way: on Claude's API each 28 × 28 pixel block is a visual token, so a 1000 × 1000 image is 1,296 tokens, larger images are downscaled to a long-edge limit (1568 pixels on the standard tier), and at \$1 per million input tokens that image costs about \$1.30 per thousand images. Audio is 50 encoder tokens a second on Whisper's design (a log-mel spectrogram at 100 frames a second, halved by a stride-2 convolution), so a 128,000-token window holds about 43 minutes; speech as text holds about 11 hours; video sampled at one frame a second and 256 tokens a frame holds about 8 minutes, and full-rate video under 20 seconds. Every one of those tokens lengthens the prefill before the first word of the answer and competes with instructions and retrieved documents for attention. Training cost is lopsided: stage-1 alignment trains a projector of a few million numbers between models of billions (this lesson's toy takes 80 pictures from 24% to 99% correct), and BLIP-2 beat the 80-billion-parameter Flamingo on zero-shot VQAv2 by 8.7% with 54 times fewer trainable parameters; it is stage 2, the instruction data, that decides how the model behaves.
What breaks.
- Objects that aren't there. A weakly aligned model describes what pictures like this usually contain; the hosted API warns of the same with low-quality, rotated or very small images (under 200 pixels). Send clear images at a usable size, and verify anything that matters.
- The image after the question. The question's tokens cannot attend forward to an image that follows them. Image first, then the question.
- Unreadable small text. A screenshot downscaled to the size limit loses its small print. Crop to the region, or tile the page, rather than sending one huge image.
- The context window full of frames. 20 minutes of video at one frame a second and 256 tokens a frame is 307,200 tokens, over twice a 128k window. Sample less often, merge tokens, transcribe the audio, or split the clip.
- Sampling that misses the moment. One frame a second is fine for a lecture and useless for a golf swing. Match the frame rate to the speed of what you are looking for.
- Transcribing away the signal. A transcript drops hesitation, tone and who spoke; a caption drops layout. Use text only when the words are enough.
- A codebook that fits nothing. A random codebook is useless at every size (error 0.6 to 2.1 against 0.09 to 0.32 for a learned one in this lesson's sweep); codebooks are learned on the data, and a tokenizer from one domain misbehaves on another.
In the wild. The Vision Transformer (Dosovitskiy et al.) is the front end: a pure transformer over 16 × 16 patches that matched convolutional networks given enough data, and CLIP's ViT (Radford et al.) is the one most vision-language models start from. LLaVA (Liu et al.) is the encode, project and splice recipe, trained on instruction data generated with a language model, scoring 85.1% of GPT-4 on its own multimodal benchmark; Flamingo (Alayrac et al.) reads images through new cross-attention layers between frozen models and learns tasks from a few examples in the prompt; BLIP-2 (Li et al.) compresses each image through a Querying Transformer. Whisper (Radford et al.) is the audio side: an encoder over log-mel spectrograms and a text decoder trained on 680,000 hours of audio, used zero-shot for transcription. For generation, VQ-VAE and DALL-E turned images into codebook ids for a transformer, SoundStream and EnCodec do it for audio with stacked residual codebooks, and Chameleon trains one model on interleaved text and image tokens from the start. Hosted vision APIs expose the same arithmetic as a price list: Claude's vision documentation, the source of the numbers above, counts each 28 × 28 pixel block as a visual token and caps images by long edge and token count. Every paper is linked at the end of the lesson.
Go deeper. Level 2 builds each front end by hand: a 4 × 4 picture cut into four tokens, a Vision Transformer with its projector spliced into a tiny language model and aligned on 80 pictures, a Fourier transform and a log-mel spectrogram from eight samples upward, a codebook learned by k-means with residual stages, and the token arithmetic for video and the context budget. If you only needed to count the tokens and choose, you are done.
Level 2: How it works, from scratch
Imagine a brilliant reader who can take in only one thing: a long row of
index cards, each card holding a short list of numbers. That is a language
model. Every word it reads arrives as one card, the word's vector (see
primer.ml.tokenization and primer.ml.transformer). It has never seen a
photograph or heard a voice.
To tell this reader about a photo, you cut the photo into small squares and write one card per square. To tell it about a voice recording, you write one card for every fiftieth of a second of sound. If the cards are written in the same "handwriting" as the word cards, the reader handles a photo the way it handles a sentence: it pays attention across all the cards at once.
That is the whole idea of a multimodal model, a model that takes in more than one modality (kind of input: text, images, audio, video):
Turn every modality into a sequence of vectors ("tokens") that a transformer can attend over.
Everything in this lesson is a way of making those cards: for images, for sound, for video, and, run backwards, for a model that produces pictures and speech.
flowchart LR
  IMG["Image"] --> VE["Vision encoder<br/>(patches to vectors)"] --> P1["Projector"]
  AUD["Audio"] --> SP["Spectrogram"] --> AE["Audio encoder"] --> P2["Projector"]
  TXT["Text"] --> TOK["Tokenizer"] --> EMB["Embedding table"]
  P1 --> SEQ["One sequence of vectors,<br/>all the same width"]
  P2 --> SEQ
  EMB --> SEQ
  SEQ --> LM["Decoder language model"] --> OUT["Next token:<br/>a word, or a codebook id<br/>for a picture or a sound"]
Reading it: three roads, one destination. Each modality has its own front end (top three rows), and every front end ends in the same place: a list of vectors as wide as the language model's word vectors. From the box "One sequence of vectors" onwards there is no difference between a word, a patch of an image and a slice of sound; the language model attends over all of them together. The last box shows the trick for output: if pictures and sounds can be written as numbered tokens, the model can generate them the way it generates words (see "Generating images and speech" below).
A tiny worked example: a 4×4 picture becomes 4 tokens
Take a grayscale picture of 4×4 pixels, each pixel a brightness from 0 to 15:
 0  1 |  2  3
 4  5 |  6  7
------+------
 8  9 | 10 11
12 13 | 14 15
- Cut it into 2×2 patches (the lines above): 4 patches.
- Flatten each patch into a list, reading row by row: the top-right patch becomes (2, 3, 6, 7).
- Project each list to the model's width, here 2 numbers, by multiplying by a matrix $W_E$ whose first column adds up the patch's top row and whose second column adds up its bottom row.
- Add a position: the patch's (row, column) in the grid, so the model knows where each patch came from.
| Patch | Pixels | Projected | + position | Token |
|---|---|---|---|---|
| top left | 0, 1, 4, 5 | (1, 9) | (0, 0) | (1, 9) |
| top right | 2, 3, 6, 7 | (5, 13) | (0, 1) | (5, 14) |
| bottom left | 8, 9, 12, 13 | (17, 25) | (1, 0) | (18, 25) |
| bottom right | 10, 11, 14, 15 | (21, 29) | (1, 1) | (22, 30) |
The picture is now four tokens of two numbers each: exactly the shape of input a transformer reads. A real model does the same with bigger numbers: patches of 14 or 16 pixels, and hundreds or thousands of numbers per token.
In code: worked_example_patches runs these four steps on this picture and returns the patches, the projections and the tokens.
Images: a Vision Transformer from scratch
primer.ml.cnn_rnn introduced the idea of patches as tokens. Here we build
the whole front end, the Vision Transformer (ViT), and count what it
costs.
Cutting and counting
Everyday picture. Lay a sheet of graph paper over a photo and cut along every fourth line. You get a grid of small tiles, and you can hand them over one by one, left to right and top to bottom, like the words of a sentence.
Tiny example. A 224×224 image in 16-pixel patches is a grid of 224 / 16 = 14 patches down and 14 across: 14 × 14 = 196 tokens. A 336×336 image in 14-pixel patches is 24 × 24 = 576 tokens.
Level 3: the formula and its symbols
$$ N = \frac{H}{P} \cdot \frac{W}{P} $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $H, W$ | the image's height and width, in pixels | 224, 224 |
| $P$ | the side of one square patch, in pixels | 16 |
| $H/P$ | how many patches fit down the image (must be a whole number, so images are resized first) | 14 |
| $W/P$ | how many patches fit across | 14 |
| $\cdot$ | multiply | |
| $N$ | the number of tokens the image becomes | 196 |
Each token starts life as $P \cdot P \cdot C$ numbers, where $C$ is the number of colour channels (3 for red, green, blue): 16 · 16 · 3 = 768.
In words: "the number of image tokens is the number of patches down times the number of patches across."
With the numbers: (224 / 16) · (224 / 16) = 14 · 14 = 196; (336 / 14) · (336 / 14) = 24 · 24 = 576; the worked 4×4 picture in 2-pixel patches gives 2 · 2 = 4.
Level 3: in Python
In Python:
H, W, P = 224, 224, 16
# H/P patches down, times W/P across
(H // P) * (W // P)  # → 196
H, W, P = 336, 336, 14
(H // P) * (W // P)  # → 576
# the worked 4×4 picture in 2-pixel patches
(4 // 2) * (4 // 2)  # → 4
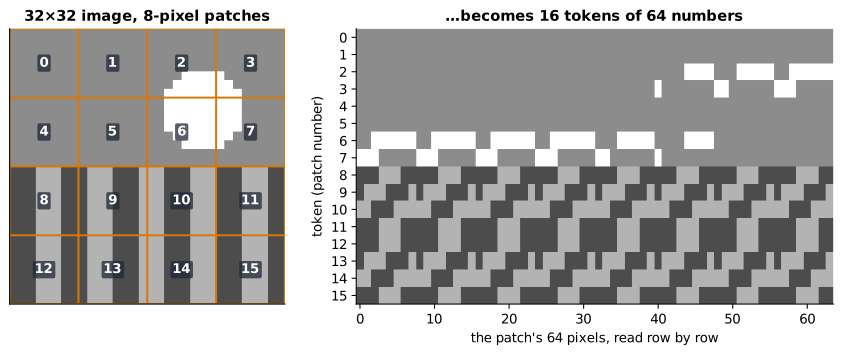
Reading it: on the left, the orange lines cut a 32×32 picture into a 4 × 4 grid, numbered in reading order. On the right, each numbered patch has become one row: its 64 pixels laid end to end. Rows 0 to 7 (the sky, with the sun in patches 2, 3, 6 and 7) are mostly one grey; rows 8 to 15 (the striped field) repeat the same light and dark pattern. Nothing about the picture is lost, but it is now a list of 16 tokens, the same shape as a 16-word sentence.
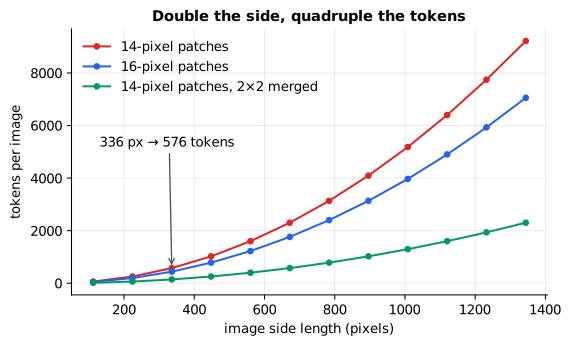
Reading it: the x-axis is the side length of a square image, the y-axis the tokens it becomes. Each curve bends upward because the count grows with the square of the side: double the side and the tokens quadruple. Bigger patches (blue) give fewer tokens than smaller ones (red). The green curve merges each 2×2 block of neighbouring patch vectors into one token before the language model sees them, a common trick that cuts the count by four.
In code: image_to_patches cuts and flattens an image (the cutting is primer.ml.cnn_rnn.patchify), refusing sizes the patch does not divide, and count_image_tokens is the formula above, with an optional merge.
Why it matters in practice. Resolution is a cost dial. Small text in a
screenshot needs a high resolution to be legible, and every doubling of the
side costs four times the tokens (and attention cost grows faster still; see
primer.ml.attention). Systems resize images to a supported size, cut very
large ones into tiles, and merge neighbouring patches to keep the count
manageable.
From patch to token: projection and position
Everyday picture. Every tile gets the same questionnaire: "how bright is your top half? your bottom half? is there an edge?" The answers become the tile's card. Then a sticker with the tile's grid address goes on the card, so shuffling the cards loses nothing.
Tiny example. In the worked example, the questionnaire had two questions (top-row total, bottom-row total), and the sticker was the patch's (row, column).
Level 3: the formula and its symbols
$$ z_i = x_i W_E + p_i $$
Symbols
| Symbol | Meaning here | Shape | In the example (top-right patch) |
|---|---|---|---|
| $i$ | which patch, counting in reading order from 0 | 1 | |
| $x_i$ | patch $i$ flattened into a row of pixels | $1 \times P^2 C$ | (2, 3, 6, 7) |
| $W_E$ | the learned patch-embedding matrix: one column per output number (a bias vector is usually added too; it is left out here) | $P^2 C \times d$ | the 4 × 2 matrix below |
| $x_i W_E$ | a matrix multiply: each output number is the dot product of the patch with one column of $W_E$ | $1 \times d$ | (5, 13) |
| $p_i$ | the learned position vector for slot $i$ | $1 \times d$ | (0, 1) |
| $z_i$ | the finished token for patch $i$ | $1 \times d$ | (5, 14) |
| $d$ | the model width: how many numbers per token | 2 |
$W_E$ in the example is the rows (1, 0), (1, 0), (0, 1), (0, 1): the first two pixels (the patch's top row) feed output 1, the last two (its bottom row) feed output 2.
In words: "each token is its patch multiplied by a learned matrix, plus a learned vector that marks where the patch sits."
With the numbers: (2, 3, 6, 7) · $W_E$ = (2 + 3, 6 + 7) = (5, 13); adding the position (0, 1) gives (5, 14).
Level 3: in Python
In Python:
x_i = [2, 3, 6, 7]
W_E = [[1, 0], [1, 0], [0, 1], [0, 1]]
p_i = [0, 1]
# x_i W_E: dot the patch with each column of W_E
xW = [sum(x * W_E[r][c] for r, x in enumerate(x_i)) for c in range(2)]
xW  # → [5, 13]
# + p_i
[a + b for a, b in zip(xW, p_i)]  # → [5, 14]
Why the position vector? Attention compares every token with every other
and ignores their order (see primer.ml.positional). Without $p_i$, a sky
patch at the top and the same sky colour in a puddle at the bottom would be
the same token, and "the sun is above the field" could not be expressed.
flowchart LR
  IMG["Image<br/>H × W × C"] --> CUT["Cut into N patches<br/>N × P·P·C"]
  CUT --> PROJ["Multiply by W_E<br/>N × d"]
  PROJ --> POS["Add position vectors<br/>N × d"]
  POS --> ENC["Encoder blocks<br/>every patch attends to every patch<br/>(no causal mask)"]
  ENC --> OUT["N image vectors<br/>N × d"]
Reading it: follow the shapes under each box. Only the first two boxes
are new; from "Encoder blocks" on, this is the transformer block of
primer.ml.transformer, run with the causal mask switched off. A sentence
is read left to right, so a text decoder hides the future; a picture has no
future, so every patch may look at every other, above, below and to either
side. The output has one vector per patch, now informed by the whole image.
In code: VisionEncoder holds W_E, the position table and a stack of primer.ml.transformer.TransformerBlock with causal=False; VisionEncoder.embed is the formula above, and calling the encoder runs the blocks.
Why it matters in practice. The vision encoder inside most
vision-language models is a ViT that was first trained as the image half of
CLIP (see primer.ml.embeddings.contrastive). CLIP training pulled its
image vectors towards the vectors of matching captions, so its outputs
already carry meaning a language model can use. That is why builders start
from it instead of training vision from scratch.
Connecting vision to a language model
The projector: a plug adapter
Everyday picture. Your laptop charger has the right voltage but the wrong plug for the wall socket abroad. A small adapter changes the shape, not the power. The vision encoder speaks in vectors of its own width and style; the language model expects vectors shaped like its word embeddings. A projector is the adapter between them.
Tiny example. A vision vector with 2 numbers, (1, 2), must become a language-model vector with 3 numbers.
Level 3: the formula and its symbols
$$ h = v \, W_P $$
Symbols
| Symbol | Meaning here | Shape | In the example |
|---|---|---|---|
| $v$ | one image token from the vision encoder | $1 \times d_{\text{vision}}$ | (1, 2) |
| $W_P$ | the projector's learned matrix | $d_{\text{vision}} \times d_{\text{LM}}$ | rows (1, 0, 1) and (0, 1, 1) |
| $h$ | the same token, now shaped like a word embedding | $1 \times d_{\text{LM}}$ | (1, 2, 3) |
| $d_{\text{vision}}, d_{\text{LM}}$ | the widths of the two models | 2 and 3 |
In words: "multiply each image vector by one learned matrix to turn it into a vector the language model can read."
With the numbers: (1, 2) · $W_P$ = (1·1 + 2·0, 1·0 + 2·1, 1·1 + 2·1) = (1, 2, 3).
Level 3: in Python
In Python:
v = [1, 2]
W_P = [[1, 0, 1], [0, 1, 1]]
# v W_P: dot v with each column of W_P
[sum(v[r] * W_P[r][c] for r in range(2)) for c in range(3)]  # → [1, 2, 3]
Many models use two such layers with a GELU between them (a smooth
"keep the positives" function; see primer.ml.transformer), which is a
small feed-forward network. Either way, the projector is tiny next to the
two models it joins: a few million numbers between models with billions.
In code: Projector is a single linear layer by default and a two-layer MLP when given a hidden width; worked_example_projection computes the (1, 2, 3) above.
Splicing image tokens into the prompt
Everyday picture. Writing a letter and taping a strip of photos into the middle of a sentence. The reader reads the words, then the photos, then the rest of the words, in order.
Tiny example. The prompt "what is this <image>" has four text tokens,
one of them a placeholder. The placeholder is replaced by the image's 4
projected vectors, so the language model reads 3 + 4 = 7 rows.
| Step | Shape (toy model) | Meaning |
|---|---|---|
| image | (8, 8) | an 8×8 grayscale picture |
| patches | (4, 16) | four 4×4 patches, flattened |
| vision encoder output | (4, 16) | four image vectors of width 16 |
| projector output | (4, 24) | four image tokens, as wide as the language model |
| text token vectors | (3, 24) | "what", "is", "this" from the embedding table |
| spliced sequence | (7, 24) | text, then image, in prompt order |
| logits | (7, 12) | a score for each of the 12 vocabulary words, at every position |
flowchart LR
  IMG["Image"] --> VE["Vision encoder<br/>4 × 16"] --> PR["Projector<br/>4 × 24"]
  TXT["Prompt: what is this,<br/>then the image placeholder"] --> TE["Look up text tokens<br/>3 × 24"]
  PR --> SPL["Splice at the placeholder<br/>7 × 24"]
  TE --> SPL
  SPL --> POS["+ positions"] --> DEC["Decoder blocks<br/>(causal)"] --> LOG["Logits<br/>7 × 12"]
Reading it: two front ends meet in the "Splice" box, where the placeholder's single row is replaced by the four projected image rows. After that the language model runs completely unchanged: positions are added (image tokens take up positions too), the causal decoder blocks run, and every row produces scores over the vocabulary. The language model never learns that some rows came from a picture.
Because the decoder is causal, a token can use the image only if it comes after the image. Text before the picture is scored exactly as if there were no picture. That is why prompts usually put the image first and the question after it.
In code: VisionLanguageModel.splice builds the spliced sequence and a flag for each row saying whether it is an image token; calling VisionLanguageModel runs primer.ml.transformer.TinyGPT's blocks on it; build_toy_vlm wires up the toy model in the table.
Why it matters in practice. This "encode, project, splice" design (as in LLaVA) is the simplest and most common. Two other families exist. One adds new cross-attention layers inside the language model that look at the image vectors (as in Flamingo), leaving the text sequence short. Another first compresses any image into a fixed small number of tokens, such as 32 or 64, with a little attention module of learned queries (as in BLIP-2's Q-Former). Both trade some detail for fewer tokens.
How such a model is trained
Everyday picture. Two experts who don't share a language: a photographer and a writer. You hire an interpreter. First, the interpreter learns vocabulary while both experts carry on exactly as they are: the photographer points at pictures, the writer names them. Then all three practise real conversations together, and the writer is allowed to adapt a little too.
That is the usual two-stage recipe:
- Alignment. Freeze the vision encoder and the language model. Train only the projector on image-caption pairs, so the projected image tokens make the language model produce the caption.
- Visual instruction tuning. Train the projector and the language model
(fully, or with LoRA; see
primer.ml.training_stages) on images paired with instructions and answers: "what is unusual about this picture?" followed by a good answer.
In both stages the loss is ordinary next-token cross-entropy (the
negative log of the probability given to the right token; see
primer.ml.losses), counted only on the answer tokens. The model is not
graded on predicting the image tokens or the question it was given.
Tiny example. The answer is "horizontal stripes", two tokens. The model gives the right first token probability 0.5 and the right second token 0.25.
Level 3: the formula and its symbols
$$
L = -\frac{1}{|A|} \sum_{t \in A} \log p\,(y_t \mid \text{image}, y_{ Symbols
Symbol
Meaning here
In the example
$A$
the positions of the answer tokens (the loss mask keeps only these)
2 positions
$\lvert A \rvert$
how many answer tokens there are
2
$t \in A$
"for each position $t$ in the answer"
$y_t$
the correct token at position $t$
"horizontal", then "stripes"
$y_{ every token before position $t$
$p(y_t \mid \ldots)$
the probability the model gives the correct token, given ($\mid$) the image and what came before
0.5, 0.25
$\log$
the natural logarithm; $-\log p$ is 0 when $p = 1$ and grows as $p$ shrinks (see
primer.notation)$-\log 0.5 = 0.693$
$L$
the loss: the average surprise over the answer
1.040
In words: "the loss is the average, over the answer tokens only, of how surprised the model was by each correct token."
With the numbers: −(log 0.5 + log 0.25) / 2 = (0.693 + 1.386) / 2 = 1.040.
Level 3: in Python
In Python:
import math
# probabilities of the right answer tokens
p = [0.5, 0.25]
# −(1/|A|) Σ log p
round(-sum(math.log(q) for q in p) / len(p), 3)  # → 1.04
flowchart TB
  subgraph S1["Stage 1: alignment (image-caption pairs)"]
    direction LR
    V1["Vision encoder<br/>frozen"] --> P1["Projector<br/>TRAINED"] --> L1["Language model<br/>frozen"]
  end
  subgraph S2["Stage 2: visual instruction tuning (image, question, answer)"]
    direction LR
    V2["Vision encoder<br/>frozen"] --> P2["Projector<br/>trained"] --> L2["Language model<br/>trained or LoRA"]
  end
  S1 --> S2
Reading it: the same three boxes appear in both stages; what changes is which ones learn. In stage 1 only the small middle box moves, so it is cheap and it cannot damage what the two big models already know. In stage 2 the language model joins in, so it learns to use the image tokens to follow instructions, answer questions and describe details, not just name things. The vision encoder often stays frozen throughout.
Our toy does stage 1. Its vision encoder and language model are random and frozen; only the projector learns, from 80 small pictures of four patterns (horizontal, vertical, diagonal, checkered), to make the language model's output layer pick the right pattern word.
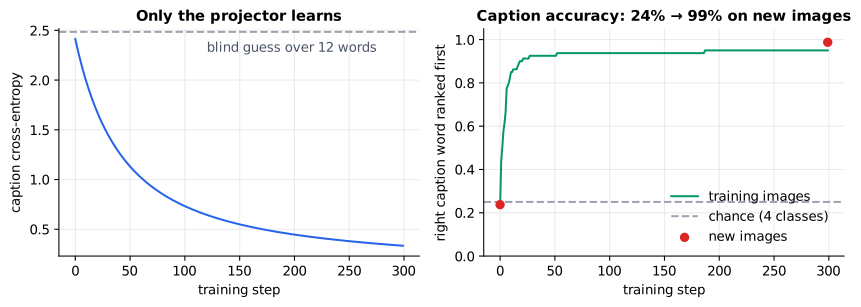
Reading it: on the left, the loss starts near the dashed line, the loss of a blind guess among 12 words (log 12 = 2.48), and falls steadily. On the right, the green line is the share of training images whose correct word scores highest, and the red dots are the same measure on 80 images the projector never saw: 24% before training (chance is 25%) and 99% after. Nothing but the projector changed, which is the point of stage 1: a small adapter is enough to make an existing vision encoder and an existing language model understand each other.
In code: align_projector trains only the projector's weights with cross-entropy on the caption word and returns the loss and accuracy per step; caption_accuracy measures how often the right word wins. The toy scores a pooled image vector directly against the language model's token table (the last step of the real path) rather than back-propagating through every layer.
Why it matters in practice. Stage 1 is cheap enough to run in hours, because almost every weight is frozen. Stage 2 decides the model's behaviour: the quality and variety of the image-instruction data matter more than its size. A common failure of a weakly aligned model is describing objects that are not in the picture, a visual form of hallucination.
Audio: from a waveform to tokens
Sound is a list of numbers
Everyday picture. A microphone is a tiny eardrum. It measures air pressure many thousands of times a second, and the recording is just that list of measurements: the waveform. Drawn on paper, it looks like a seismograph trace.
Tiny example. Speech is usually recorded at a sample rate of 16,000 measurements per second, so one second is 16,000 numbers and a 30-second clip is 480,000. Used directly as tokens that would be ruinous, and the thing that matters, which pitches are sounding, is hidden in the wiggles (top panel of the spectrogram figure below).
How much of each pitch: the Fourier transform
Everyday picture. A prism splits white light into its colours. The Fourier transform splits a sound into its pitches. It works by holding a pure wave of each pitch up against the recording and asking "how well do you line up?". A pitch that is present lines up again and again and scores high; a pitch that is absent lines up as often as it clashes and scores zero.
Tiny example. Eight samples of a wave that goes up and down twice: (1, 0, −1, 0, 1, 0, −1, 0). Line it up against a wave that also cycles twice, cos: (1, 0, −1, 0, 1, 0, −1, 0). Multiply matching positions and add: 1 + 0 + 1 + 0 + 1 + 0 + 1 + 0 = 4. A wave that cycles once agrees for half its length and disagrees for the other half: it scores 0.
Level 3: the formula and its symbols
$$ \lvert X_k \rvert = \sqrt{\left(\sum_{n=0}^{N-1} x_n \cos\frac{2\pi k n}{N}\right)^2 + \left(\sum_{n=0}^{N-1} x_n \sin\frac{2\pi k n}{N}\right)^2} $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $x_n$ | the $n$-th sample of the recording | (1, 0, −1, 0, 1, 0, −1, 0) |
| $N$ | how many samples | 8 |
| $n$ | a counter over the samples, from 0 to $N-1$ | 0, 1, …, 7 |
| $k$ | which pitch we are testing: a wave that completes $k$ cycles in the $N$ samples | 2 |
| $\cos, \sin$ | the cosine and sine waves (sine is the same wave shifted a quarter cycle, so a pitch that starts at a different moment is still caught) | |
| $2\pi$ | one full cycle, in the units cos and sin use | |
| $\sum_{n=0}^{N-1}$ | add up over every sample | |
| $\sqrt{a^2 + b^2}$ | the length of the pair (cosine score, sine score) | $\sqrt{4^2 + 0^2} = 4$ |
| $\lvert X_k \rvert$ | how much of pitch $k$ the recording holds | 4 |
Bin $k$ is the frequency $f_k = k \cdot f_s / N$ in hertz (cycles per second), where $f_s$ is the sample rate. If the 8 samples were taken over one second, $f_s = 8$ and bin 2 is 2 Hz. Textbooks write the same thing with complex numbers, $X_k = \sum_n x_n e^{-2\pi i k n / N}$; the cosine part and the sine part are exactly the two sums above.
In words: "for each pitch, correlate the recording with a cosine and a sine of that pitch, and take the length of the two scores."
With the numbers: for $k = 2$ the cosine sum is 4 and the sine sum is 0, so $\lvert X_2 \rvert = 4$. For $k = 1$ both sums are 0. Bin 6 also scores 4: with only 8 samples, a wave cycling 6 times is indistinguishable from one cycling 8 − 6 = 2 times, so the top half of the bins mirrors the bottom half and only bins 0 to $N/2$ are kept.
Level 3: in Python
In Python:
import math
x = [1, 0, -1, 0, 1, 0, -1, 0]
N = len(x)
def magnitude(k):
    c = sum(x_n * math.cos(2 * math.pi * k * n / N) for n, x_n in enumerate(x))
    s = sum(x_n * math.sin(2 * math.pi * k * n / N) for n, x_n in enumerate(x))
    return math.sqrt(c ** 2 + s ** 2)
[round(magnitude(k), 6) for k in range(N)]  # → [0.0, 0.0, 4.0, 0.0, 0.0, 0.0, 4.0, 0.0]
# f_k = k · f_s / N, with 8 samples a second
2 * 8 / N  # → 2.0
In code: dft_magnitudes is this formula for every k at once, written from the definition (the tests check it against NumPy's fast Fourier transform, which computes the same numbers far faster).
The spectrogram: one Fourier transform per slice
Everyday picture. A piano roll, or sheet music: time runs left to right, pitch runs bottom to top, and a mark means "this note is sounding now". To make one from a recording, listen through a short window, say 25 milliseconds, ask "which pitches are in here?", slide the window along a little, and ask again. That is the short-time Fourier transform (STFT), and its picture is a spectrogram.
Each slice is faded in and out with a Hann window (a smooth hump from 0 up to 1 and back) before measuring, because chopping a wave off abruptly creates a click, and a click contains every pitch at once.
Tiny example. Speech systems commonly use 25 ms windows (400 samples at 16 kHz) that start every 10 ms (160 samples). How many windows fit in one second?
Level 3: the formula and its symbols
$$ T = 1 + \left\lfloor \frac{L - N}{H} \right\rfloor $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $L$ | the recording's length, in samples | 16,000 |
| $N$ | the window length, in samples | 400 (25 ms) |
| $H$ | the hop: how far the window moves each step | 160 (10 ms) |
| $\lfloor \cdot \rfloor$ | floor: round down to a whole number (a part-window at the end is dropped) | $\lfloor 97.5 \rfloor = 97$ |
| $T$ | the number of frames (columns of the spectrogram) | 98 |
In words: "one window fits at the start; after that, count how many whole hops still leave room for a full window."
With the numbers: 1 + ⌊(16,000 − 400) / 160⌋ = 1 + ⌊97.5⌋ = 98 frames per second, which is why speech models talk about "100 frames a second".
Level 3: in Python
In Python:
L, N, H = 16000, 400, 160
# 1 + ⌊(L − N) / H⌋
1 + (L - N) // H  # → 98
flowchart LR
  W["Waveform<br/>L samples"] --> F["Slice into frames<br/>T × N"]
  F --> HW["Fade each frame<br/>(Hann window)"]
  HW --> DFT["Fourier transform<br/>per frame<br/>T × (N/2 + 1)"]
  DFT --> MEL["Pool into mel bands<br/>T × n_mels"]
  MEL --> LOG["Take the log<br/>log-mel spectrogram"]
Reading it: a flat list of samples becomes a grid. The first three boxes are the STFT; the shape under the Fourier box says each frame now holds one number per frequency bin. The last two boxes, explained next, shrink those bins into a few dozen bands spaced the way ears hear, and put loudness on a log scale. The result, a log-mel spectrogram, is what speech models actually read.
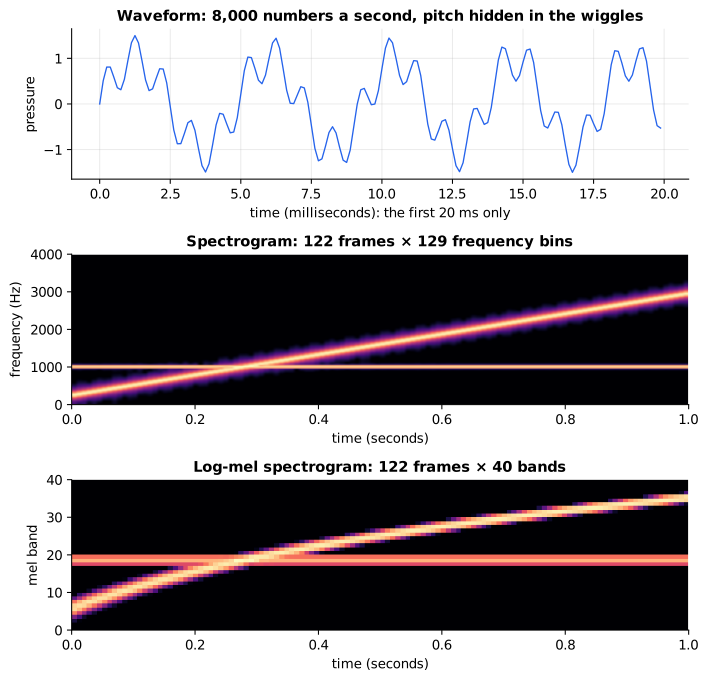
Reading it: the signal is a whistle sliding from 200 Hz to 3000 Hz over a steady, quieter 1000 Hz hum, sampled 8,000 times a second. Top: the first 20 ms of the waveform, where both sounds are tangled into one wiggle. Middle: the spectrogram, time across and frequency up, brighter meaning louder. The two sounds separate cleanly: a flat line for the hum and a straight rising line for the whistle. Bottom: the log-mel version with 40 bands. The rising line now curves, climbing fast through the low bands and slowly through the high ones, because mel bands are narrow at low pitch and wide at high pitch, which is also where ears are more and less sensitive.
In code: stft slices, windows (with hann) and measures every frame; frame_count is the formula above; log_mel_spectrogram adds the mel pooling and the log.
The mel scale: spacing pitch the way ears do
Everyday picture. On a piano, every octave takes up the same width of keyboard, yet each octave doubles the frequency: the A keys are at 110, 220, 440 and 880 Hz. Ears work the same way above about 1,000 Hz: a jump from 1,000 to 2,000 Hz sounds about as big as a jump from 2,000 to 4,000. The mel scale relabels frequencies so that equal steps in mel sound like equal steps in pitch.
Tiny example. By construction 1,000 Hz is 1,000 mel. The 7,000 Hz from 1,000 to 8,000 Hz shrinks to just 1,840 mel.
Level 3: the formula and its symbols
$$ m = 2595 \, \log_{10}!\left(1 + \frac{f}{700}\right) $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $f$ | a frequency in hertz | 700 |
| $f / 700$ | frequency measured in units of 700 Hz; below about 700 Hz the scale is nearly straight, above it the log takes over | 1 |
| $\log_{10}$ | the base-10 logarithm: "10 to what power gives this?"; it turns ratios into equal steps (see primer.notation) |
$\log_{10} 2 = 0.301$ |
| 2595 | a constant chosen so that 1,000 Hz comes out as 1,000 mel | |
| $m$ | the same frequency in mel | 781.2 |
In words: "mel is a log of the frequency, gently straightened below 700 Hz and scaled so that 1,000 Hz is 1,000 mel."
With the numbers: 2595 · log₁₀(1 + 700/700) = 2595 · 0.301 = 781.2; 1,000 Hz gives 1,000.0; 4,000 Hz gives 2,146.1; 8,000 Hz gives 2,840.0.
Level 3: in Python
In Python:
import math
def mel(f):
    return 2595 * math.log10(1 + f / 700)
round(mel(700), 1)  # → 781.2
round(mel(1000), 1)  # → 1000.0
round(mel(4000), 1)  # → 2146.1
A mel filterbank turns the hundreds of frequency bins into a few dozen bands: triangles evenly spaced in mel, so narrow at low frequencies and wide at high ones. Each band adds up the energy under its triangle. Loudness is also heard by ratio, so the last step takes the log.
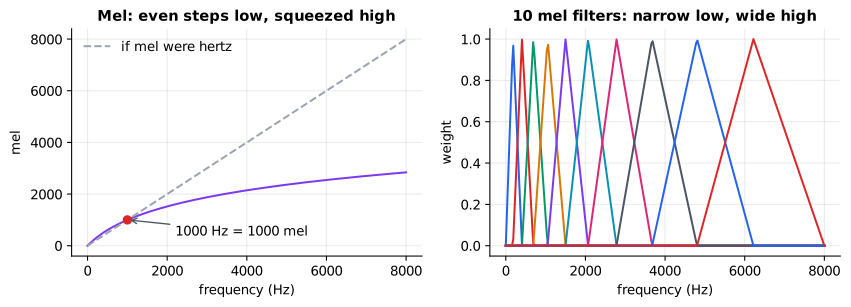
Reading it: on the left, the purple curve is the formula and the dashed line is where it would be if mel were simply hertz. They agree near the bottom (the red dot, 1,000 Hz = 1,000 mel) and part ways above: the top 7,000 Hz of the range is squeezed into under 2,000 mel. On the right are 10 mel filters for 16 kHz audio. Each peaks at 1 and overlaps its neighbours; the low ones are a few bins wide and the top one spans over 3,000 Hz. Detail is spent where ears, and speech, need it.
In code: hz_to_mel is the formula, and mel_filterbank builds the triangles, evenly spaced in mel.
Speech recognition: an encoder over frames, a decoder for text
Everyday picture. A court stenographer listens to a whole sentence, then types it out word by word, glancing back at what they heard as they go.
Tiny example. Take a 30-second clip. With 10 ms hops it is 3,000 frames of 80 mel bands each. A small convolution that moves two frames at a time halves that to 1,500 encoder positions: 50 audio tokens per second. A transformer encoder attends over all 1,500 at once, and a decoder writes the transcript as text tokens, attending both to its own words so far and to the encoder's output. This is the design of Whisper.
flowchart LR
  A["30 s of audio"] --> LM["Log-mel spectrogram<br/>3000 frames × 80 bands"]
  LM --> CV["Convolution, stride 2<br/>1500 positions"]
  CV --> ENC["Encoder blocks<br/>(no causal mask)"]
  ENC --> X["Cross-attention:<br/>decoder reads the audio"]
  DEC["Decoder blocks<br/>(causal)"] --> X
  X --> TXT["Text tokens,<br/>one at a time"]
  TXT -.-> DEC
Reading it: the left half is a front end like the image one: turn the
signal into a grid, shrink it, and run a non-causal encoder so every moment
of sound can inform every other. The right half is a text decoder with one
extra step, cross-attention, where its queries come from the text written
so far and its keys and values come from the audio (see
primer.ml.transformer for encoders and decoders). The dotted arrow is the
generation loop: each new word is fed back in.
In code: audio_tokens counts encoder positions from a clip's length, the hop and the downsampling.
Why it matters in practice. The same audio encoder can feed a general language model instead of a dedicated decoder: add a projector, splice the audio tokens into the prompt, and the model can answer questions about a recording, exactly as with images. Fifty tokens a second is manageable for a short voice message and expensive for an hour-long meeting.
Generating images and speech: discrete tokens from a codebook
So far the model reads pictures and sound. To write them, a language model needs them as something it can predict one at a time from a fixed vocabulary, the way it predicts words.
Everyday picture. A paint-by-numbers kit comes with a palette of numbered pots. Any small area of a picture is described by the number of the pot closest to its colour. The whole picture becomes a grid of pot numbers, and anyone with the same palette can repaint it. The palette is a codebook; snapping to the nearest entry is vector quantization.
Tiny example. A codebook of three 2-number entries: $c_0 = (0, 0)$, $c_1 = (1, 0)$, $c_2 = (0, 1)$. The vector $z = (0.9, 0.2)$ has squared distances 0.85, 0.05 and 1.45 to them, so it becomes id 1. Decoding id 1 gives back (1, 0): close, not exact.
Level 3: the formula and its symbols
$$ q(z) = \arg\min_{k \in {0, \ldots, K-1}} \lVert z - c_k \rVert^2 $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $z$ | one vector to encode: an image patch's vector or a slice of sound | (0.9, 0.2) |
| $c_k$ | codebook entry number $k$ | $c_1 = (1, 0)$ |
| $K$ | the codebook size: how many entries | 3 |
| $k \in {0, \ldots, K-1}$ | "$k$ ranges over the entry numbers" | 0, 1, 2 |
| $\lVert z - c_k \rVert^2$ | squared distance: subtract, square each difference, add | $(0.9-1)^2 + (0.2-0)^2 = 0.05$ |
| $\arg\min_k$ | "the $k$ that gives the smallest value" (the position of the minimum, not the minimum itself) | 1 |
| $q(z)$ | the id that replaces $z$ | 1 |
In words: "replace each vector by the number of its nearest codebook entry."
With the numbers: distances squared to $c_0, c_1, c_2$ are 0.81 + 0.04 = 0.85, 0.01 + 0.04 = 0.05 and 0.81 + 0.64 = 1.45; the smallest is 0.05, at $k = 1$.
Level 3: in Python
In Python:
z = [0.9, 0.2]
codebook = [[0, 0], [1, 0], [0, 1]]
# ‖z − c_k‖² for each entry
d2 = [sum((a - b) ** 2 for a, b in zip(z, c)) for c in codebook]
[round(d, 2) for d in d2]  # → [0.85, 0.05, 1.45]
# arg min: the position of the smallest
d2.index(min(d2))  # → 1
flowchart LR
  IN["Picture or sound"] --> E["Encoder<br/>vectors"]
  E --> Q["Snap to nearest<br/>codebook entry"]
  Q --> IDS["Ids, like word tokens<br/>e.g. 17, 803, 4, ..."]
  IDS --> LM["Language model<br/>learns to predict ids<br/>after text"]
  LM --> GEN["Generated ids"]
  GEN --> LOOK["Look up codebook<br/>vectors"]
  LOOK --> D["Decoder"] --> OUTP["Pixels or waveform"]
Reading it: the top row is used during training: real pictures and
sounds are encoded, snapped to the codebook, and become sequences of ids
that sit in the training text next to their descriptions. The language
model learns to continue a caption with ids the same way it learns to
continue a sentence with words; its vocabulary is simply enlarged by $K$
entries. At generation time (bottom row) the model writes ids, the codebook
turns them back into vectors, and a decoder paints pixels or synthesises a
waveform. The encoder, codebook and decoder together are a VQ-VAE (see
primer.ml.generative.autoencoders).
How is the codebook chosen? It is learned so that the entries sit where the
data actually is, which amounts to k-means clustering (see
primer.ml.embeddings.clustering): snap every vector to its nearest entry,
move each entry to the average of the vectors that chose it, and repeat.
For audio, one codebook is rarely precise enough, so neural audio codecs
use residual vector quantization: a second codebook encodes what the
first one missed, a third what the second missed, and so on. Each moment
of sound becomes a small stack of ids.
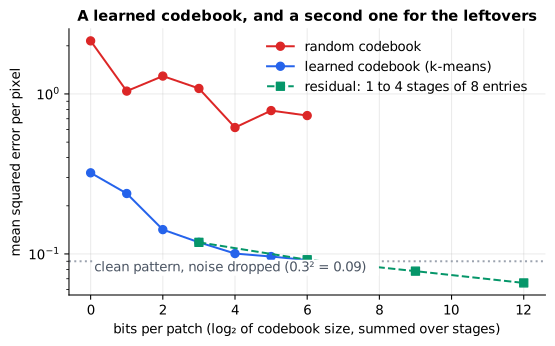
Reading it: the x-axis is bits per patch: a codebook of $K$ entries costs log₂ $K$ bits per id, so 64 entries is 6 bits. The y-axis (log scale) is the reconstruction error on patches of new pictures, not the ones the codebook was learned from. Random codebooks (red) are useless at every size: their entries sit where no data lives. Learned codebooks (blue) fall fast and then flatten near the dotted line, which is the error you would get by reproducing each clean pattern perfectly and dropping only the pixel noise. The green squares stack 8-entry codebooks, each learned on the previous one's leftovers: after four stages (12 bits) they reach below the dotted line, because the extra codes start describing the noise of each particular patch too.
In code: quantize is the arg min above and dequantize the lookup; kmeans_codebook learns a codebook; learn_residual_codebooks and residual_quantize stack codebooks on the leftovers.
Why it matters in practice. Discrete tokens let one model read and
write every modality with one mechanism, next-token prediction. The costs
are real: a 256×256 image compressed eight-fold per side is 32 × 32 =
1,024 ids (the scheme of the original DALL·E), and a neural audio codec
running at 75 frames a second with 8 codebooks writes 600 ids a second. The
other road to generating images is diffusion (see
primer.ml.generative.diffusion): the language model supplies text or
vectors that condition a diffusion model, which paints the pixels in many
small denoising steps. Discrete tokens are simpler to bolt onto a language
model; diffusion usually renders finer detail.
Video: pictures over time
Everyday picture. A flipbook. Each page is a picture, and neighbouring pages are almost identical. To follow the story you don't need to look at every page; a glance at every tenth page shows what happens.
Tiny example. A 10-second clip at 30 frames a second, with each frame cut into 256 tokens (224×224 in 14-pixel patches): 300 frames × 256 = 76,800 tokens, more than half of a 128,000-token context, for ten seconds. Keeping one frame a second gives 10 × 256 = 2,560.
Level 3: the formula and its symbols
$$ N_{\text{video}} = \frac{D \cdot r}{t} \cdot \frac{H}{P} \cdot \frac{W}{P} $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $D$ | the clip's duration, in seconds | 10 |
| $r$ | frames kept per second (the sampling rate, often far below the video's own frame rate) | 30, then 1 |
| $t$ | the tubelet depth: how many consecutive frames share one token, when a patch is cut through time as well as space | 1 |
| $D \cdot r / t$ | how many frame slots become tokens | 300, then 10 |
| $\frac{H}{P} \cdot \frac{W}{P}$ | tokens per frame, from the image formula | 16 · 16 = 256 |
| $N_{\text{video}}$ | the clip's total tokens | 76,800, then 2,560 |
In words: "count the frames you keep, divide by how many frames each token spans, and multiply by the tokens per frame."
With the numbers: (10 · 30 / 1) · 16 · 16 = 300 · 256 = 76,800; at one frame a second, (10 · 1 / 1) · 256 = 2,560; sampling 2 frames a second in tubelets 2 frames deep gives (10 · 2 / 2) · 256 = 2,560 again, while covering twice as many moments.
Level 3: in Python
In Python:
H = W = 224
P = 14
tokens_per_frame = (H // P) * (W // P)
tokens_per_frame  # → 256
D, r, t = 10, 30, 1
D * r // t * tokens_per_frame  # → 76800
# one frame a second
D, r, t = 10, 1, 1
D * r // t * tokens_per_frame  # → 2560
flowchart LR
  V["Video<br/>30 frames a second"] --> S["Sample frames<br/>e.g. 1 a second"]
  S --> ENC["Vision encoder per frame<br/>(or tubelets across frames)"]
  ENC --> M["Merge neighbouring<br/>patch tokens"]
  M --> PR["Projector"]
  PR --> SEQ["Frame tokens,<br/>with timestamps as text"]
  SEQ --> LM["Language model"]
Reading it: each box from left to right cuts the token count. Frame sampling throws away near-duplicate pages of the flipbook; tubelets and merging squeeze each kept moment into fewer tokens. A short text timestamp before each frame's tokens ("at 0:05") lets the model say when something happened. What is left is the image pipeline, repeated once per kept frame.
In code: video_tokens is the formula, and sample_frames picks the evenly spaced frames to keep.
Why it matters in practice. Sampling is a bet that nothing important happens between the frames you keep: one frame a second is fine for a lecture and useless for a golf swing. Real systems adapt: more frames for short or fast clips, fewer and smaller ones for long recordings, and a transcript of the soundtrack alongside.
What it costs: tokens per second and the context budget
Everyday picture. Packing a suitcase. Text is neatly folded shirts; images are shoes; video is an inflatable boat. The suitcase (the context window) is the same size whatever you pack.
Tiny example. A 128,000-token window holds 128,000 / 256 = 500 seconds, about 8 minutes, of video sampled at one frame a second, before a single word of the question. The same window holds about 11 hours of speech written out as text.
| Input | Tokens per second | Minutes in 128k tokens |
|---|---|---|
| speech written as text (about 150 words a minute, about 1.3 tokens a word) | 3.2 | 656 |
| speech as audio-encoder tokens | 50 | 43 |
| video, 1 frame a second, 256 tokens a frame | 256 | 8.3 |
| audio as codec tokens (75 frames × 8 codebooks) | 600 | 3.6 |
| video, 30 frames a second, 256 tokens a frame | 7,680 | 0.3 |
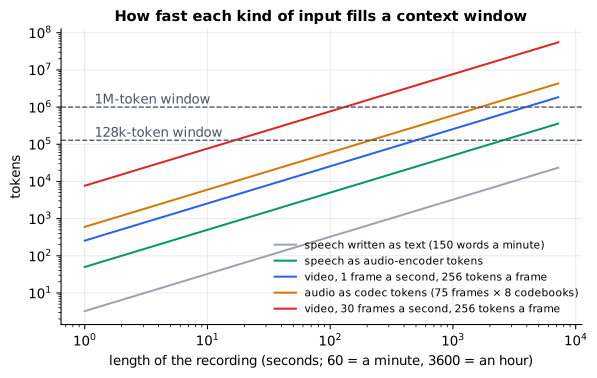
Reading it: both axes are logarithmic, so each line is the same slope shifted up or down by its tokens per second. Read across at a dashed line (a context window) to see how long a recording of each kind fits. Text (grey) is so dense that hours of speech fit easily. Audio tokens (green) fill a 128k window in about 43 minutes, sampled video (blue) in about 8, and full-rate video (red) in under 20 seconds. The gap between the grey line and the others is the price of keeping the raw signal instead of words.
In code: seconds_that_fit divides a window by a rate, and TOKENS_PER_SECOND holds the rates in the table.
Why it matters in practice. Every image and second of audio is billed
and computed like text: it takes room in the context window, lengthens the
prefill before the first word of the answer (see primer.ml.inference),
and competes with instructions and retrieved documents for attention (see
primer.agents.context). The practical levers follow from the formulas:
send the smallest resolution that still shows the detail you need, crop to
the region that matters, sample fewer frames, and transcribe audio to text
when the words matter and the tone does not.
In 20 seconds
- One idea: every modality becomes a sequence of vectors as wide as the language model's word vectors; after that it is ordinary attention.
- Images: a Vision Transformer cuts a picture into patches, projects each one, adds a position, and runs non-causal encoder blocks. Tokens = (H/P)·(W/P), so they grow with the square of the resolution.
- Connecting to a language model: a small projector maps image vectors into the embedding space, and they are spliced into the prompt. Train the projector first with everything frozen, then fine-tune on image instructions.
- Audio: waveform, then a log-mel spectrogram (a Fourier transform per 25 ms slice, pooled into ear-shaped bands), then an encoder: about 50 tokens a second.
- Generating pictures and sound: snap vectors to a learned codebook so they become ids a language model can predict like words; or hand off to a diffusion model.
- Video and cost: frames multiply image tokens by time; sample frames, merge tokens, and remember that text is by far the densest input.
Self-test questions
How can a chatbot "see" a photo, explained without jargon? The photo is cut into a grid of small squares, and each square is described by a list of numbers in the same format the model uses for words. The model then reads the squares and the words of your question together, paying attention to whichever squares help answer it. It never sees the picture as a picture: it reads it as a few hundred extra "words".
How many tokens is a 448×448 image with 14-pixel patches? And if each 2×2 block of neighbours is merged? 448 / 14 = 32 patches a side, so 32 × 32 = 1,024 tokens. Merging 2×2 blocks divides by 4: 256 tokens. Doubling the side from 224 would have quadrupled the count.
Why does a Vision Transformer need position vectors, and why is its attention not causal? Attention ignores order, so without positions the model sees an unordered bag of patches and cannot tell the sky from the ground. It is not causal because a picture has no "future": every patch may use every other, and hiding half the image would only throw information away.
What does the projector do, and why train it first with both big models frozen? It maps each image vector into the language model's embedding space, so image tokens look like something the language model can use. Training it alone first is cheap (it is tiny) and safe (the frozen models keep all they know). Only once the two sides understand each other is the language model tuned on image instructions.
In a prompt, why does it matter whether the image comes before or after the question? The language model is causal: a token can only attend to tokens before it. Question tokens placed after the image can look at it while being processed; question tokens placed before it cannot. The answer comes after both either way, but putting the image first lets the whole question be read in light of the picture.
Why does a speech model read a log-mel spectrogram rather than raw samples? Raw audio is 16,000 numbers a second with pitch hidden in the wiggles. The spectrogram makes pitch explicit (which frequencies sound at each moment), the mel bands spend detail where ears and speech need it, the log matches how loudness is heard, and 100 frames a second is far fewer positions to attend over.
How can a model that only predicts tokens produce an image or a voice? Encode pictures or sounds into vectors, snap each vector to its nearest entry in a learned codebook, and use the entry numbers as extra vocabulary. The model learns to predict those ids after a caption, and a decoder turns generated ids back into pixels or a waveform. The alternative is to have the model condition a diffusion model that paints the image.
A 20-minute video goes to a model with a 128,000-token window. What goes wrong, and what can be done? At one frame a second and 256 tokens a frame it is 1,200 × 256 = 307,200 tokens, more than twice the window, before any question. Options: sample far fewer frames (one every 5 seconds gives 61,440), merge neighbouring patch tokens, lower the resolution, transcribe the soundtrack to text, or split the video and summarise the parts.
The papers behind this lesson
- Dosovitskiy et al., An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale (2020): https://arxiv.org/abs/2010.11929. Showed that a plain transformer over image patches matches convolutional networks when trained on enough data: the Vision Transformer. Annotated companion
- Radford et al., Learning Transferable Visual Models From Natural Language Supervision (CLIP, 2021): https://arxiv.org/abs/2103.00020. Trained an image encoder and a text encoder into one shared space; its image encoder is the starting point of many vision-language models. Annotated companion
- Alayrac et al., Flamingo: a Visual Language Model for Few-Shot Learning (2022): https://arxiv.org/abs/2204.14198. Connected a frozen vision encoder to a frozen language model through new cross-attention layers, handling images and video interleaved with text. Annotated companion
- Liu et al., Visual Instruction Tuning (LLaVA, 2023): https://arxiv.org/abs/2304.08485. The encode, project and splice recipe, trained in two stages: align the projector, then tune on image instructions. Annotated companion
- Radford et al., Robust Speech Recognition via Large-Scale Weak Supervision (Whisper, 2022): https://arxiv.org/abs/2212.04356. An encoder over log-mel spectrograms and a text decoder, trained on 680,000 hours of transcribed audio. Annotated companion
- van den Oord, Vinyals & Kavukcuoglu, Neural Discrete Representation Learning (VQ-VAE, 2017): https://arxiv.org/abs/1711.00937. Learned a codebook inside an autoencoder, turning images and audio into discrete tokens. Annotated companion
- Zeghidour et al., SoundStream: An End-to-End Neural Audio Codec (2021): https://arxiv.org/abs/2107.03312. Residual vector quantization for audio: a stack of codebooks, each encoding the previous one's error.
- Ramesh et al., Zero-Shot Text-to-Image Generation (DALL·E, 2021): https://arxiv.org/abs/2102.12092. Generated images as sequences of discrete codebook tokens after the text, with one transformer.
- Arnab et al., ViViT: A Video Vision Transformer (2021): https://arxiv.org/abs/2103.15691. Extended patches through time as tubelets, and compared ways to factorise attention over space and time.
Further reading
- Dosovitskiy et al., An Image is Worth 16x16 Words (ViT, 2020): https://arxiv.org/abs/2010.11929
- Liu et al., Visual Instruction Tuning (LLaVA, 2023): https://arxiv.org/abs/2304.08485
- Liu et al., Improved Baselines with Visual Instruction Tuning (LLaVA-1.5, 2023): https://arxiv.org/abs/2310.03744
- Li et al., BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models (2023): https://arxiv.org/abs/2301.12597
- Alayrac et al., Flamingo (2022): https://arxiv.org/abs/2204.14198
- Radford et al., Whisper (2022): https://arxiv.org/abs/2212.04356 and its code: https://github.com/openai/whisper
- Défossez et al., High Fidelity Neural Audio Compression (EnCodec, 2022): https://arxiv.org/abs/2210.13438
- van den Oord et al., Neural Discrete Representation Learning (VQ-VAE, 2017): https://arxiv.org/abs/1711.00937
- Chameleon Team, Chameleon: Mixed-Modal Early-Fusion Foundation Models (2024): https://arxiv.org/abs/2405.09818
- Arnab et al., ViViT: A Video Vision Transformer (2021): https://arxiv.org/abs/2103.15691
1r""" 2# Multimodal models: images, audio and video into a language model 3 4Run: `python -m primer.ml.generative.multimodal` 5 6This lesson builds on the transformer of `primer.ml.transformer`, its 7attention (`primer.ml.attention`) and positions (`primer.ml.positional`), 8and the CLIP image encoder of `primer.ml.embeddings.contrastive`; 9`primer.notation` explains every symbol from zero. 10 11## Level 1: The practitioner's guide 12 13**In one sentence.** A multimodal model turns images, audio and video into 14sequences of vectors the same width as a language model's word vectors, so 15one transformer can read (and, with a codebook, write) all of them; for a 16practitioner, every picture, second of sound or frame of video is a number 17of tokens, and that number is the cost, the latency and the limit. 18 19**When you need it.** You need this lesson the moment a model has to read 20something that isn't text: a screenshot, a chart, a scanned form, a voice 21message, a meeting recording, a video clip. Whether you call a hosted 22vision model or build with an open one, the same questions decide the 23outcome: how many tokens each input becomes, at what resolution, in what 24order in the prompt, and whether the model needs the signal at all or only 25its words. You don't need a multimodal model when the words are all that 26matters: a transcript of speech is about 3.2 tokens a second where audio 27tokens are 50 a second (this lesson's rates), and a caption is a few dozen 28tokens where a 336 × 336 image is 576. The number that shows how fast the 29naive approach fails: send a 10-second clip at 30 frames a second with 30256 tokens a frame and it is 76,800 tokens, more than half of a 31128,000-token window, before a single word of the question. Keep one frame 32a second and it is 2,560. 33 34**Your options.** From the cheapest to the most control: 35 36| Option | What it does | What it guarantees | What it costs | Where it lives | 37|---|---|---|---|---| 38| Turn the signal into text first | Transcribe audio (Whisper), caption or OCR an image, then use a text model | The densest input there is: hours of speech in one window | Loses tone, layout, small detail and anything the captioner missed | Your pipeline, ahead of the model | 39| A hosted multimodal API | Send the image or audio in the prompt; the vendor's encoder tokenizes it | No infrastructure; a documented token count per image | Tokens per image by area (a 1000 × 1000 image is 1,296 tokens on one API); resizing above a size limit | The vendor's API | 40| An open vision-language model | A ViT's patch vectors pass through a projector into the prompt (LLaVA's recipe) | Full control of resolution, tiling and prompt layout | A GPU; 196 to 576 or more tokens per image at your chosen resolution | Your server | 41| A compressed-visual family | New cross-attention layers (Flamingo) or a small set of learned queries (BLIP-2's Q-Former) read the image instead of splicing it | A short text sequence however many images; 32 to 64 tokens per image | Some detail lost; a different model family to adopt | The model family you download | 42| Align your own projector | Freeze a vision encoder and a language model, train the small adapter between them on captions, then tune on instructions | A model that speaks your domain's pictures, cheaply (stage 1 runs in hours) | Captioned data, then instruction data; a stage-2 fine-tune for behaviour | Your training loop | 43| Discrete tokens for generation | Snap image or audio vectors to a learned codebook so the model predicts them like words | One model reads and writes every modality with next-token prediction | 1,024 ids for a 256 × 256 image; 600 ids a second for codec audio | A tokenizer plus the language model | 44 45**How to choose.** Start from what the model must get out of the signal, 46then count the tokens. 47 48- Only the words matter (a voicemail, a lecture, a document with plain 49 text): transcribe or OCR to text and use a text model. It is the densest 50 and the cheapest by a wide margin. 51- Layout, tone, colour or small detail matters (a chart, a screenshot, a 52 form, a hesitant customer): send the signal itself, at the smallest 53 resolution that still shows the detail, cropped to the region that 54 matters. 55- Long video: sample frames (one a second for a lecture, more for anything 56 fast), merge neighbouring patch tokens, and send the soundtrack as a 57 transcript alongside. 58- Your own domain, weak results from general models: align a projector on 59 your captions first (cheap and safe, since both big models stay frozen), 60 then instruction-tune. 61- Generating pictures or speech from a language model: discrete codebook 62 tokens for simplicity, or hand the language model's output to a diffusion 63 model (`primer.ml.generative.diffusion`) for finer detail. 64- Whatever you pick, put the image before the question. The language model 65 is causal, so text placed before an image is scored as if the image were 66 not there; the hosted API's own guidance says the same. 67 68**What it costs.** Tokens grow with the square of the side: a 224 × 224 69image in 16-pixel patches is 196 tokens, a 336 × 336 image in 14-pixel 70patches is 576, and a 1008 × 1008 image with 2 × 2 neighbours merged is 711,296. Hosted APIs bill the same way: on Claude's API each 28 × 28 pixel 72block is a visual token, so a 1000 × 1000 image is 1,296 tokens, larger 73images are downscaled to a long-edge limit (1568 pixels on the standard 74tier), and at \$1 per million input tokens that image costs about \$1.30 75per thousand images. Audio is 50 encoder tokens a second on Whisper's 76design (a log-mel spectrogram at 100 frames a second, halved by a stride-2 77convolution), so a 128,000-token window holds about 43 minutes; speech as 78text holds about 11 hours; video sampled at one frame a second and 256 79tokens a frame holds about 8 minutes, and full-rate video under 20 80seconds. Every one of those tokens lengthens the prefill before the first 81word of the answer and competes with instructions and retrieved documents 82for attention. Training cost is lopsided: stage-1 alignment trains a 83projector of a few million numbers between models of billions (this 84lesson's toy takes 80 pictures from 24% to 99% correct), and BLIP-2 beat 85the 80-billion-parameter Flamingo on zero-shot VQAv2 by 8.7% with 54 86times fewer trainable parameters; it is stage 2, the instruction data, 87that decides how the model behaves. 88 89**What breaks.** 90 91- **Objects that aren't there.** A weakly aligned model describes what 92 pictures like this usually contain; the hosted API warns of the same 93 with low-quality, rotated or very small images (under 200 pixels). Send 94 clear images at a usable size, and verify anything that matters. 95- **The image after the question.** The question's tokens cannot attend 96 forward to an image that follows them. Image first, then the question. 97- **Unreadable small text.** A screenshot downscaled to the size limit 98 loses its small print. Crop to the region, or tile the page, rather than 99 sending one huge image. 100- **The context window full of frames.** 20 minutes of video at one frame 101 a second and 256 tokens a frame is 307,200 tokens, over twice a 128k 102 window. Sample less often, merge tokens, transcribe the audio, or split 103 the clip. 104- **Sampling that misses the moment.** One frame a second is fine for a 105 lecture and useless for a golf swing. Match the frame rate to the speed 106 of what you are looking for. 107- **Transcribing away the signal.** A transcript drops hesitation, tone 108 and who spoke; a caption drops layout. Use text only when the words are 109 enough. 110- **A codebook that fits nothing.** A random codebook is useless at every 111 size (error 0.6 to 2.1 against 0.09 to 0.32 for a learned one in this 112 lesson's sweep); codebooks are learned on the data, and a tokenizer from 113 one domain misbehaves on another. 114 115**In the wild.** The Vision Transformer (Dosovitskiy et al.) is the front 116end: a pure transformer over 16 × 16 patches that matched convolutional 117networks given enough data, and CLIP's ViT (Radford et al.) is the one 118most vision-language models start from. LLaVA (Liu et al.) is the encode, 119project and splice recipe, trained on instruction data generated with a 120language model, scoring 85.1% of GPT-4 on its own multimodal benchmark; 121Flamingo (Alayrac et al.) reads images through new cross-attention layers 122between frozen models and learns tasks from a few examples in the prompt; 123BLIP-2 (Li et al.) compresses each image through a Querying Transformer. 124Whisper (Radford et al.) is the audio side: an encoder over log-mel 125spectrograms and a text decoder trained on 680,000 hours of audio, used 126zero-shot for transcription. For generation, VQ-VAE and DALL-E turned 127images into codebook ids for a transformer, SoundStream and EnCodec do it 128for audio with stacked residual codebooks, and Chameleon trains one model 129on interleaved text and image tokens from the start. Hosted vision APIs 130expose the same arithmetic as a price list: Claude's vision documentation, 131the source of the numbers above, counts each 28 × 28 pixel block as a 132visual token and caps images by long edge and token count. Every paper is 133linked at the end of the lesson. 134 135**Go deeper.** Level 2 builds each front end by hand: a 4 × 4 picture cut 136into four tokens, a Vision Transformer with its projector spliced into a 137tiny language model and aligned on 80 pictures, a Fourier transform and a 138log-mel spectrogram from eight samples upward, a codebook learned by 139k-means with residual stages, and the token arithmetic for video and the 140context budget. If you only needed to count the tokens and choose, you are 141done. 142 143## Level 2: How it works, from scratch 144 145Imagine a brilliant reader who can take in only one thing: a long row of 146index cards, each card holding a short list of numbers. That is a language 147model. Every word it reads arrives as one card, the word's vector (see 148`primer.ml.tokenization` and `primer.ml.transformer`). It has never seen a 149photograph or heard a voice. 150 151To tell this reader about a photo, you cut the photo into small squares and 152write one card per square. To tell it about a voice recording, you write one 153card for every fiftieth of a second of sound. If the cards are written in the 154same "handwriting" as the word cards, the reader handles a photo the way it 155handles a sentence: it pays attention across all the cards at once. 156 157That is the whole idea of a **multimodal model**, a model that takes in more 158than one **modality** (kind of input: text, images, audio, video): 159 160> Turn every modality into a sequence of vectors ("tokens") that a transformer 161> can attend over. 162 163Everything in this lesson is a way of making those cards: for images, for 164sound, for video, and, run backwards, for a model that *produces* pictures 165and speech. 166 167```mermaid 168flowchart LR 169 IMG["Image"] --> VE["Vision encoder<br/>(patches to vectors)"] --> P1["Projector"] 170 AUD["Audio"] --> SP["Spectrogram"] --> AE["Audio encoder"] --> P2["Projector"] 171 TXT["Text"] --> TOK["Tokenizer"] --> EMB["Embedding table"] 172 P1 --> SEQ["One sequence of vectors,<br/>all the same width"] 173 P2 --> SEQ 174 EMB --> SEQ 175 SEQ --> LM["Decoder language model"] --> OUT["Next token:<br/>a word, or a codebook id<br/>for a picture or a sound"] 176``` 177 178**Reading it:** three roads, one destination. Each modality has its own 179front end (top three rows), and every front end ends in the same place: a 180list of vectors as wide as the language model's word vectors. From the box 181"One sequence of vectors" onwards there is no difference between a word, a 182patch of an image and a slice of sound; the language model attends over all 183of them together. The last box shows the trick for *output*: if pictures and 184sounds can be written as numbered tokens, the model can generate them the 185way it generates words (see "Generating images and speech" below). 186 187## A tiny worked example: a 4×4 picture becomes 4 tokens 188 189Take a grayscale picture of 4×4 pixels, each pixel a brightness from 0 to 15: 190 191```text 192 0 1 | 2 3 193 4 5 | 6 7 194------+------ 195 8 9 | 10 11 19612 13 | 14 15 197``` 198 1991. **Cut** it into 2×2 **patches** (the lines above): 4 patches. 2002. **Flatten** each patch into a list, reading row by row: the top-right 201 patch becomes (2, 3, 6, 7). 2023. **Project** each list to the model's width, here 2 numbers, by 203 multiplying by a matrix $W_E$ whose first column adds up the patch's top 204 row and whose second column adds up its bottom row. 2054. **Add a position**: the patch's (row, column) in the grid, so the model 206 knows where each patch came from. 207 208| Patch | Pixels | Projected | + position | Token | 209|--------------|-----------------|-----------|------------|--------------| 210| top left | 0, 1, 4, 5 | (1, 9) | (0, 0) | **(1, 9)** | 211| top right | 2, 3, 6, 7 | (5, 13) | (0, 1) | **(5, 14)** | 212| bottom left | 8, 9, 12, 13 | (17, 25) | (1, 0) | **(18, 25)** | 213| bottom right | 10, 11, 14, 15 | (21, 29) | (1, 1) | **(22, 30)** | 214 215The picture is now four tokens of two numbers each: exactly the shape of 216input a transformer reads. A real model does the same with bigger numbers: 217patches of 14 or 16 pixels, and hundreds or thousands of numbers per token. 218 219**In code:** `worked_example_patches` runs these four steps on this picture and returns the patches, the projections and the tokens. 220 221## Images: a Vision Transformer from scratch 222 223`primer.ml.cnn_rnn` introduced the idea of patches as tokens. Here we build 224the whole front end, the **Vision Transformer** (ViT), and count what it 225costs. 226 227### Cutting and counting 228 229**Everyday picture.** Lay a sheet of graph paper over a photo and cut along 230every fourth line. You get a grid of small tiles, and you can hand them over 231one by one, left to right and top to bottom, like the words of a sentence. 232 233**Tiny example.** A 224×224 image in 16-pixel patches is a grid of 234224 / 16 = 14 patches down and 14 across: 14 × 14 = **196** tokens. A 235336×336 image in 14-pixel patches is 24 × 24 = **576** tokens. 236 237$$ 238N = \frac{H}{P} \cdot \frac{W}{P} 239$$ 240 241**Symbols** 242 243| Symbol | Meaning here | In the example | 244|---|---|---| 245| $H, W$ | the image's height and width, in pixels | 224, 224 | 246| $P$ | the side of one square patch, in pixels | 16 | 247| $H/P$ | how many patches fit down the image (must be a whole number, so images are resized first) | 14 | 248| $W/P$ | how many patches fit across | 14 | 249| $\cdot$ | multiply | | 250| $N$ | the number of tokens the image becomes | 196 | 251 252Each token starts life as $P \cdot P \cdot C$ numbers, where $C$ is the 253number of colour channels (3 for red, green, blue): 16 · 16 · 3 = 768. 254 255**In words:** "the number of image tokens is the number of patches down 256times the number of patches across." 257 258**With the numbers:** (224 / 16) · (224 / 16) = 14 · 14 = 196; (336 / 14) · 259(336 / 14) = 24 · 24 = 576; the worked 4×4 picture in 2-pixel patches gives 2602 · 2 = 4. 261 262**In Python:** 263 264```python 265H, W, P = 224, 224, 16 266# H/P patches down, times W/P across 267(H // P) * (W // P) # → 196 268H, W, P = 336, 336, 14 269(H // P) * (W // P) # → 576 270# the worked 4×4 picture in 2-pixel patches 271(4 // 2) * (4 // 2) # → 4 272``` 273 274 275 276**Reading it:** on the left, the orange lines cut a 32×32 picture into a 2774 × 4 grid, numbered in reading order. On the right, each numbered patch has 278become one row: its 64 pixels laid end to end. Rows 0 to 7 (the sky, with 279the sun in patches 2, 3, 6 and 7) are mostly one grey; rows 8 to 15 (the 280striped field) repeat the same light and dark pattern. Nothing about the 281picture is lost, but it is now a list of 16 tokens, the same shape as a 28216-word sentence. 283 284 285 286**Reading it:** the x-axis is the side length of a square image, the y-axis 287the tokens it becomes. Each curve bends upward because the count grows with 288the *square* of the side: double the side and the tokens quadruple. Bigger 289patches (blue) give fewer tokens than smaller ones (red). The green curve 290merges each 2×2 block of neighbouring patch vectors into one token before 291the language model sees them, a common trick that cuts the count by four. 292 293**In code:** `image_to_patches` cuts and flattens an image (the cutting is `primer.ml.cnn_rnn.patchify`), refusing sizes the patch does not divide, and `count_image_tokens` is the formula above, with an optional merge. 294 295**Why it matters in practice.** Resolution is a cost dial. Small text in a 296screenshot needs a high resolution to be legible, and every doubling of the 297side costs four times the tokens (and attention cost grows faster still; see 298`primer.ml.attention`). Systems resize images to a supported size, cut very 299large ones into tiles, and merge neighbouring patches to keep the count 300manageable. 301 302### From patch to token: projection and position 303 304**Everyday picture.** Every tile gets the same questionnaire: "how bright is 305your top half? your bottom half? is there an edge?" The answers become the 306tile's card. Then a sticker with the tile's grid address goes on the card, 307so shuffling the cards loses nothing. 308 309**Tiny example.** In the worked example, the questionnaire had two 310questions (top-row total, bottom-row total), and the sticker was the patch's 311(row, column). 312 313$$ 314z_i = x_i W_E + p_i 315$$ 316 317**Symbols** 318 319| Symbol | Meaning here | Shape | In the example (top-right patch) | 320|---|---|---|---| 321| $i$ | which patch, counting in reading order from 0 | | 1 | 322| $x_i$ | patch $i$ flattened into a row of pixels | $1 \times P^2 C$ | (2, 3, 6, 7) | 323| $W_E$ | the learned **patch-embedding** matrix: one column per output number (a bias vector is usually added too; it is left out here) | $P^2 C \times d$ | the 4 × 2 matrix below | 324| $x_i W_E$ | a **matrix multiply**: each output number is the dot product of the patch with one column of $W_E$ | $1 \times d$ | (5, 13) | 325| $p_i$ | the learned position vector for slot $i$ | $1 \times d$ | (0, 1) | 326| $z_i$ | the finished token for patch $i$ | $1 \times d$ | (5, 14) | 327| $d$ | the model width: how many numbers per token | | 2 | 328 329$W_E$ in the example is the rows (1, 0), (1, 0), (0, 1), (0, 1): the first 330two pixels (the patch's top row) feed output 1, the last two (its bottom 331row) feed output 2. 332 333**In words:** "each token is its patch multiplied by a learned matrix, plus 334a learned vector that marks where the patch sits." 335 336**With the numbers:** (2, 3, 6, 7) · $W_E$ = (2 + 3, 6 + 7) = (5, 13); adding 337the position (0, 1) gives (5, 14). 338 339**In Python:** 340 341```python 342x_i = [2, 3, 6, 7] 343W_E = [[1, 0], [1, 0], [0, 1], [0, 1]] 344p_i = [0, 1] 345# x_i W_E: dot the patch with each column of W_E 346xW = [sum(x * W_E[r][c] for r, x in enumerate(x_i)) for c in range(2)] 347xW # → [5, 13] 348# + p_i 349[a + b for a, b in zip(xW, p_i)] # → [5, 14] 350``` 351 352Why the position vector? Attention compares every token with every other 353and ignores their order (see `primer.ml.positional`). Without $p_i$, a sky 354patch at the top and the same sky colour in a puddle at the bottom would be 355the same token, and "the sun is above the field" could not be expressed. 356 357```mermaid 358flowchart LR 359 IMG["Image<br/>H × W × C"] --> CUT["Cut into N patches<br/>N × P·P·C"] 360 CUT --> PROJ["Multiply by W_E<br/>N × d"] 361 PROJ --> POS["Add position vectors<br/>N × d"] 362 POS --> ENC["Encoder blocks<br/>every patch attends to every patch<br/>(no causal mask)"] 363 ENC --> OUT["N image vectors<br/>N × d"] 364``` 365 366**Reading it:** follow the shapes under each box. Only the first two boxes 367are new; from "Encoder blocks" on, this is the transformer block of 368`primer.ml.transformer`, run with the causal mask switched off. A sentence 369is read left to right, so a text decoder hides the future; a picture has no 370future, so every patch may look at every other, above, below and to either 371side. The output has one vector per patch, now informed by the whole image. 372 373**In code:** `VisionEncoder` holds W_E, the position table and a stack of `primer.ml.transformer.TransformerBlock` with `causal=False`; `VisionEncoder.embed` is the formula above, and calling the encoder runs the blocks. 374 375**Why it matters in practice.** The vision encoder inside most 376vision-language models is a ViT that was first trained as the image half of 377CLIP (see `primer.ml.embeddings.contrastive`). CLIP training pulled its 378image vectors towards the vectors of matching captions, so its outputs 379already carry meaning a language model can use. That is why builders start 380from it instead of training vision from scratch. 381 382## Connecting vision to a language model 383 384### The projector: a plug adapter 385 386**Everyday picture.** Your laptop charger has the right voltage but the 387wrong plug for the wall socket abroad. A small adapter changes the shape, 388not the power. The vision encoder speaks in vectors of its own width and 389style; the language model expects vectors shaped like its word embeddings. 390A **projector** is the adapter between them. 391 392**Tiny example.** A vision vector with 2 numbers, (1, 2), must become a 393language-model vector with 3 numbers. 394 395$$ 396h = v \, W_P 397$$ 398 399**Symbols** 400 401| Symbol | Meaning here | Shape | In the example | 402|---|---|---|---| 403| $v$ | one image token from the vision encoder | $1 \times d_{\text{vision}}$ | (1, 2) | 404| $W_P$ | the projector's learned matrix | $d_{\text{vision}} \times d_{\text{LM}}$ | rows (1, 0, 1) and (0, 1, 1) | 405| $h$ | the same token, now shaped like a word embedding | $1 \times d_{\text{LM}}$ | (1, 2, 3) | 406| $d_{\text{vision}}, d_{\text{LM}}$ | the widths of the two models | | 2 and 3 | 407 408**In words:** "multiply each image vector by one learned matrix to turn it 409into a vector the language model can read." 410 411**With the numbers:** (1, 2) · $W_P$ = (1·1 + 2·0, 1·0 + 2·1, 1·1 + 2·1) = 412(1, 2, 3). 413 414**In Python:** 415 416```python 417v = [1, 2] 418W_P = [[1, 0, 1], [0, 1, 1]] 419# v W_P: dot v with each column of W_P 420[sum(v[r] * W_P[r][c] for r in range(2)) for c in range(3)] # → [1, 2, 3] 421``` 422 423Many models use two such layers with a **GELU** between them (a smooth 424"keep the positives" function; see `primer.ml.transformer`), which is a 425small feed-forward network. Either way, the projector is tiny next to the 426two models it joins: a few million numbers between models with billions. 427 428**In code:** `Projector` is a single linear layer by default and a two-layer MLP when given a hidden width; `worked_example_projection` computes the (1, 2, 3) above. 429 430### Splicing image tokens into the prompt 431 432**Everyday picture.** Writing a letter and taping a strip of photos into the 433middle of a sentence. The reader reads the words, then the photos, then the 434rest of the words, in order. 435 436**Tiny example.** The prompt "what is this `<image>`" has four text tokens, 437one of them a placeholder. The placeholder is replaced by the image's 4 438projected vectors, so the language model reads 3 + 4 = **7** rows. 439 440| Step | Shape (toy model) | Meaning | 441|---|---|---| 442| image | (8, 8) | an 8×8 grayscale picture | 443| patches | (4, 16) | four 4×4 patches, flattened | 444| vision encoder output | (4, 16) | four image vectors of width 16 | 445| projector output | (4, 24) | four image tokens, as wide as the language model | 446| text token vectors | (3, 24) | "what", "is", "this" from the embedding table | 447| spliced sequence | (7, 24) | text, then image, in prompt order | 448| logits | (7, 12) | a score for each of the 12 vocabulary words, at every position | 449 450```mermaid 451flowchart LR 452 IMG["Image"] --> VE["Vision encoder<br/>4 × 16"] --> PR["Projector<br/>4 × 24"] 453 TXT["Prompt: what is this,<br/>then the image placeholder"] --> TE["Look up text tokens<br/>3 × 24"] 454 PR --> SPL["Splice at the placeholder<br/>7 × 24"] 455 TE --> SPL 456 SPL --> POS["+ positions"] --> DEC["Decoder blocks<br/>(causal)"] --> LOG["Logits<br/>7 × 12"] 457``` 458 459**Reading it:** two front ends meet in the "Splice" box, where the 460placeholder's single row is replaced by the four projected image rows. 461After that the language model runs completely unchanged: positions are 462added (image tokens take up positions too), the causal decoder blocks run, 463and every row produces scores over the vocabulary. The language model never 464learns that some rows came from a picture. 465 466Because the decoder is causal, a token can use the image only if it comes 467*after* the image. Text before the picture is scored exactly as if there 468were no picture. That is why prompts usually put the image first and the 469question after it. 470 471**In code:** `VisionLanguageModel.splice` builds the spliced sequence and a flag for each row saying whether it is an image token; calling `VisionLanguageModel` runs `primer.ml.transformer.TinyGPT`'s blocks on it; `build_toy_vlm` wires up the toy model in the table. 472 473**Why it matters in practice.** This "encode, project, splice" design (as in 474LLaVA) is the simplest and most common. Two other families exist. One adds 475new cross-attention layers inside the language model that look at the image 476vectors (as in Flamingo), leaving the text sequence short. Another first 477compresses any image into a fixed small number of tokens, such as 32 or 64, 478with a little attention module of learned queries (as in BLIP-2's 479Q-Former). Both trade some detail for fewer tokens. 480 481### How such a model is trained 482 483**Everyday picture.** Two experts who don't share a language: a 484photographer and a writer. You hire an interpreter. First, the interpreter 485learns vocabulary while both experts carry on exactly as they are: the 486photographer points at pictures, the writer names them. Then all three 487practise real conversations together, and the writer is allowed to adapt a 488little too. 489 490That is the usual two-stage recipe: 491 4921. **Alignment.** Freeze the vision encoder and the language model. Train 493 only the projector on image-caption pairs, so the projected image tokens 494 make the language model produce the caption. 4952. **Visual instruction tuning.** Train the projector and the language model 496 (fully, or with LoRA; see `primer.ml.training_stages`) on images paired 497 with instructions and answers: "what is unusual about this picture?" 498 followed by a good answer. 499 500In both stages the loss is ordinary next-token **cross-entropy** (the 501negative log of the probability given to the right token; see 502`primer.ml.losses`), counted only on the answer tokens. The model is not 503graded on predicting the image tokens or the question it was given. 504 505**Tiny example.** The answer is "horizontal stripes", two tokens. The model 506gives the right first token probability 0.5 and the right second token 0.25. 507 508$$ 509L = -\frac{1}{|A|} \sum_{t \in A} \log p\,(y_t \mid \text{image}, y_{<t}) 510$$ 511 512**Symbols** 513 514| Symbol | Meaning here | In the example | 515|---|---|---| 516| $A$ | the positions of the answer tokens (the **loss mask** keeps only these) | 2 positions | 517| $\lvert A \rvert$ | how many answer tokens there are | 2 | 518| $t \in A$ | "for each position $t$ in the answer" | | 519| $y_t$ | the correct token at position $t$ | "horizontal", then "stripes" | 520| $y_{<t}$ | every token before position $t$ | | 521| $p(y_t \mid \ldots)$ | the probability the model gives the correct token, given ($\mid$) the image and what came before | 0.5, 0.25 | 522| $\log$ | the natural logarithm; $-\log p$ is 0 when $p = 1$ and grows as $p$ shrinks (see `primer.notation`) | $-\log 0.5 = 0.693$ | 523| $L$ | the loss: the average surprise over the answer | 1.040 | 524 525**In words:** "the loss is the average, over the answer tokens only, of how 526surprised the model was by each correct token." 527 528**With the numbers:** −(log 0.5 + log 0.25) / 2 = (0.693 + 1.386) / 2 = 529**1.040**. 530 531**In Python:** 532 533```python 534import math 535# probabilities of the right answer tokens 536p = [0.5, 0.25] 537# −(1/|A|) Σ log p 538round(-sum(math.log(q) for q in p) / len(p), 3) # → 1.04 539``` 540 541```mermaid 542flowchart TB 543 subgraph S1["Stage 1: alignment (image-caption pairs)"] 544 direction LR 545 V1["Vision encoder<br/>frozen"] --> P1["Projector<br/>TRAINED"] --> L1["Language model<br/>frozen"] 546 end 547 subgraph S2["Stage 2: visual instruction tuning (image, question, answer)"] 548 direction LR 549 V2["Vision encoder<br/>frozen"] --> P2["Projector<br/>trained"] --> L2["Language model<br/>trained or LoRA"] 550 end 551 S1 --> S2 552``` 553 554**Reading it:** the same three boxes appear in both stages; what changes is 555which ones learn. In stage 1 only the small middle box moves, so it is cheap 556and it cannot damage what the two big models already know. In stage 2 the 557language model joins in, so it learns to *use* the image tokens to follow 558instructions, answer questions and describe details, not just name things. 559The vision encoder often stays frozen throughout. 560 561Our toy does stage 1. Its vision encoder and language model are random and 562frozen; only the projector learns, from 80 small pictures of four patterns 563(horizontal, vertical, diagonal, checkered), to make the language model's 564output layer pick the right pattern word. 565 566 567 568**Reading it:** on the left, the loss starts near the dashed line, the loss 569of a blind guess among 12 words (log 12 = 2.48), and falls steadily. On the 570right, the green line is the share of training images whose correct word 571scores highest, and the red dots are the same measure on 80 images the 572projector never saw: 24% before training (chance is 25%) and 99% after. 573Nothing but the projector changed, which is the point of stage 1: a small 574adapter is enough to make an existing vision encoder and an existing 575language model understand each other. 576 577**In code:** `align_projector` trains only the projector's weights with cross-entropy on the caption word and returns the loss and accuracy per step; `caption_accuracy` measures how often the right word wins. The toy scores a pooled image vector directly against the language model's token table (the last step of the real path) rather than back-propagating through every layer. 578 579**Why it matters in practice.** Stage 1 is cheap enough to run in hours, 580because almost every weight is frozen. Stage 2 decides the model's 581behaviour: the quality and variety of the image-instruction data matter 582more than its size. A common failure of a weakly aligned model is 583describing objects that are not in the picture, a visual form of 584hallucination. 585 586## Audio: from a waveform to tokens 587 588### Sound is a list of numbers 589 590**Everyday picture.** A microphone is a tiny eardrum. It measures air 591pressure many thousands of times a second, and the recording is just that 592list of measurements: the **waveform**. Drawn on paper, it looks like a 593seismograph trace. 594 595**Tiny example.** Speech is usually recorded at a **sample rate** of 16,000 596measurements per second, so one second is 16,000 numbers and a 30-second 597clip is 480,000. Used directly as tokens that would be ruinous, and the 598thing that matters, which pitches are sounding, is hidden in the wiggles 599(top panel of the spectrogram figure below). 600 601### How much of each pitch: the Fourier transform 602 603**Everyday picture.** A prism splits white light into its colours. The 604**Fourier transform** splits a sound into its pitches. It works by holding 605a pure wave of each pitch up against the recording and asking "how well do 606you line up?". A pitch that is present lines up again and again and scores 607high; a pitch that is absent lines up as often as it clashes and scores 608zero. 609 610**Tiny example.** Eight samples of a wave that goes up and down twice: 611(1, 0, −1, 0, 1, 0, −1, 0). Line it up against a wave that also cycles 612twice, cos: (1, 0, −1, 0, 1, 0, −1, 0). Multiply matching positions and add: 6131 + 0 + 1 + 0 + 1 + 0 + 1 + 0 = 4. A wave that cycles once agrees for half 614its length and disagrees for the other half: it scores 0. 615 616$$ 617\lvert X_k \rvert = \sqrt{\left(\sum_{n=0}^{N-1} x_n \cos\frac{2\pi k n}{N}\right)^2 + \left(\sum_{n=0}^{N-1} x_n \sin\frac{2\pi k n}{N}\right)^2} 618$$ 619 620**Symbols** 621 622| Symbol | Meaning here | In the example | 623|---|---|---| 624| $x_n$ | the $n$-th sample of the recording | (1, 0, −1, 0, 1, 0, −1, 0) | 625| $N$ | how many samples | 8 | 626| $n$ | a counter over the samples, from 0 to $N-1$ | 0, 1, …, 7 | 627| $k$ | which pitch we are testing: a wave that completes $k$ cycles in the $N$ samples | 2 | 628| $\cos, \sin$ | the cosine and sine waves (sine is the same wave shifted a quarter cycle, so a pitch that starts at a different moment is still caught) | | 629| $2\pi$ | one full cycle, in the units cos and sin use | | 630| $\sum_{n=0}^{N-1}$ | add up over every sample | | 631| $\sqrt{a^2 + b^2}$ | the length of the pair (cosine score, sine score) | $\sqrt{4^2 + 0^2} = 4$ | 632| $\lvert X_k \rvert$ | how much of pitch $k$ the recording holds | 4 | 633 634Bin $k$ is the frequency $f_k = k \cdot f_s / N$ in **hertz** (cycles per 635second), where $f_s$ is the sample rate. If the 8 samples were taken over 636one second, $f_s = 8$ and bin 2 is 2 Hz. Textbooks write the same thing 637with complex numbers, $X_k = \sum_n x_n e^{-2\pi i k n / N}$; the cosine 638part and the sine part are exactly the two sums above. 639 640**In words:** "for each pitch, correlate the recording with a cosine and a 641sine of that pitch, and take the length of the two scores." 642 643**With the numbers:** for $k = 2$ the cosine sum is 4 and the sine sum is 0, 644so $\lvert X_2 \rvert = 4$. For $k = 1$ both sums are 0. Bin 6 also scores 4: 645with only 8 samples, a wave cycling 6 times is indistinguishable from one 646cycling 8 − 6 = 2 times, so the top half of the bins mirrors the bottom half 647and only bins 0 to $N/2$ are kept. 648 649**In Python:** 650 651```python 652import math 653x = [1, 0, -1, 0, 1, 0, -1, 0] 654N = len(x) 655def magnitude(k): 656 c = sum(x_n * math.cos(2 * math.pi * k * n / N) for n, x_n in enumerate(x)) 657 s = sum(x_n * math.sin(2 * math.pi * k * n / N) for n, x_n in enumerate(x)) 658 return math.sqrt(c ** 2 + s ** 2) 659[round(magnitude(k), 6) for k in range(N)] # → [0.0, 0.0, 4.0, 0.0, 0.0, 0.0, 4.0, 0.0] 660# f_k = k · f_s / N, with 8 samples a second 6612 * 8 / N # → 2.0 662``` 663 664**In code:** `dft_magnitudes` is this formula for every k at once, written from the definition (the tests check it against NumPy's fast Fourier transform, which computes the same numbers far faster). 665 666### The spectrogram: one Fourier transform per slice 667 668**Everyday picture.** A piano roll, or sheet music: time runs left to 669right, pitch runs bottom to top, and a mark means "this note is sounding 670now". To make one from a recording, listen through a short window, say 67125 milliseconds, ask "which pitches are in here?", slide the window along a 672little, and ask again. That is the **short-time Fourier transform** (STFT), 673and its picture is a **spectrogram**. 674 675Each slice is faded in and out with a **Hann window** (a smooth hump from 0 676up to 1 and back) before measuring, because chopping a wave off abruptly 677creates a click, and a click contains every pitch at once. 678 679**Tiny example.** Speech systems commonly use 25 ms windows (400 samples at 68016 kHz) that start every 10 ms (160 samples). How many windows fit in one 681second? 682 683$$ 684T = 1 + \left\lfloor \frac{L - N}{H} \right\rfloor 685$$ 686 687**Symbols** 688 689| Symbol | Meaning here | In the example | 690|---|---|---| 691| $L$ | the recording's length, in samples | 16,000 | 692| $N$ | the window length, in samples | 400 (25 ms) | 693| $H$ | the **hop**: how far the window moves each step | 160 (10 ms) | 694| $\lfloor \cdot \rfloor$ | **floor**: round down to a whole number (a part-window at the end is dropped) | $\lfloor 97.5 \rfloor = 97$ | 695| $T$ | the number of frames (columns of the spectrogram) | 98 | 696 697**In words:** "one window fits at the start; after that, count how many 698whole hops still leave room for a full window." 699 700**With the numbers:** 1 + ⌊(16,000 − 400) / 160⌋ = 1 + ⌊97.5⌋ = **98** 701frames per second, which is why speech models talk about "100 frames a 702second". 703 704**In Python:** 705 706```python 707L, N, H = 16000, 400, 160 708# 1 + ⌊(L − N) / H⌋ 7091 + (L - N) // H # → 98 710``` 711 712```mermaid 713flowchart LR 714 W["Waveform<br/>L samples"] --> F["Slice into frames<br/>T × N"] 715 F --> HW["Fade each frame<br/>(Hann window)"] 716 HW --> DFT["Fourier transform<br/>per frame<br/>T × (N/2 + 1)"] 717 DFT --> MEL["Pool into mel bands<br/>T × n_mels"] 718 MEL --> LOG["Take the log<br/>log-mel spectrogram"] 719``` 720 721**Reading it:** a flat list of samples becomes a grid. The first three 722boxes are the STFT; the shape under the Fourier box says each frame now 723holds one number per frequency bin. The last two boxes, explained next, 724shrink those bins into a few dozen bands spaced the way ears hear, and put 725loudness on a log scale. The result, a **log-mel spectrogram**, is what 726speech models actually read. 727 728 729 730**Reading it:** the signal is a whistle sliding from 200 Hz to 3000 Hz over 731a steady, quieter 1000 Hz hum, sampled 8,000 times a second. Top: the first 73220 ms of the waveform, where both sounds are tangled into one wiggle. 733Middle: the spectrogram, time across and frequency up, brighter meaning 734louder. The two sounds separate cleanly: a flat line for the hum and a 735straight rising line for the whistle. Bottom: the log-mel version with 40 736bands. The rising line now *curves*, climbing fast through the low bands and 737slowly through the high ones, because mel bands are narrow at low pitch and 738wide at high pitch, which is also where ears are more and less sensitive. 739 740**In code:** `stft` slices, windows (with `hann`) and measures every frame; `frame_count` is the formula above; `log_mel_spectrogram` adds the mel pooling and the log. 741 742### The mel scale: spacing pitch the way ears do 743 744**Everyday picture.** On a piano, every octave takes up the same width of 745keyboard, yet each octave *doubles* the frequency: the A keys are at 110, 746220, 440 and 880 Hz. Ears work the same way above about 1,000 Hz: a jump 747from 1,000 to 2,000 Hz sounds about as big as a jump from 2,000 to 4,000. 748The **mel scale** relabels frequencies so that equal steps in mel sound like 749equal steps in pitch. 750 751**Tiny example.** By construction 1,000 Hz is 1,000 mel. The 7,000 Hz from 7521,000 to 8,000 Hz shrinks to just 1,840 mel. 753 754$$ 755m = 2595 \, \log_{10}\!\left(1 + \frac{f}{700}\right) 756$$ 757 758**Symbols** 759 760| Symbol | Meaning here | In the example | 761|---|---|---| 762| $f$ | a frequency in hertz | 700 | 763| $f / 700$ | frequency measured in units of 700 Hz; below about 700 Hz the scale is nearly straight, above it the log takes over | 1 | 764| $\log_{10}$ | the base-10 **logarithm**: "10 to what power gives this?"; it turns ratios into equal steps (see `primer.notation`) | $\log_{10} 2 = 0.301$ | 765| 2595 | a constant chosen so that 1,000 Hz comes out as 1,000 mel | | 766| $m$ | the same frequency in mel | 781.2 | 767 768**In words:** "mel is a log of the frequency, gently straightened below 769700 Hz and scaled so that 1,000 Hz is 1,000 mel." 770 771**With the numbers:** 2595 · log₁₀(1 + 700/700) = 2595 · 0.301 = **781.2**; 7721,000 Hz gives 1,000.0; 4,000 Hz gives 2,146.1; 8,000 Hz gives 2,840.0. 773 774**In Python:** 775 776```python 777import math 778def mel(f): 779 return 2595 * math.log10(1 + f / 700) 780round(mel(700), 1) # → 781.2 781round(mel(1000), 1) # → 1000.0 782round(mel(4000), 1) # → 2146.1 783``` 784 785A **mel filterbank** turns the hundreds of frequency bins into a few dozen 786bands: triangles evenly spaced in mel, so narrow at low frequencies and wide 787at high ones. Each band adds up the energy under its triangle. Loudness is 788also heard by ratio, so the last step takes the log. 789 790 791 792**Reading it:** on the left, the purple curve is the formula and the dashed 793line is where it would be if mel were simply hertz. They agree near the 794bottom (the red dot, 1,000 Hz = 1,000 mel) and part ways above: the top 7957,000 Hz of the range is squeezed into under 2,000 mel. On the right are 10 796mel filters for 16 kHz audio. Each peaks at 1 and overlaps its neighbours; 797the low ones are a few bins wide and the top one spans over 3,000 Hz. Detail 798is spent where ears, and speech, need it. 799 800**In code:** `hz_to_mel` is the formula, and `mel_filterbank` builds the triangles, evenly spaced in mel. 801 802### Speech recognition: an encoder over frames, a decoder for text 803 804**Everyday picture.** A court stenographer listens to a whole sentence, then 805types it out word by word, glancing back at what they heard as they go. 806 807**Tiny example.** Take a 30-second clip. With 10 ms hops it is 3,000 frames 808of 80 mel bands each. A small convolution that moves two frames at a time 809halves that to **1,500** encoder positions: **50 audio tokens per second**. 810A transformer encoder attends over all 1,500 at once, and a decoder writes 811the transcript as text tokens, attending both to its own words so far and 812to the encoder's output. This is the design of Whisper. 813 814```mermaid 815flowchart LR 816 A["30 s of audio"] --> LM["Log-mel spectrogram<br/>3000 frames × 80 bands"] 817 LM --> CV["Convolution, stride 2<br/>1500 positions"] 818 CV --> ENC["Encoder blocks<br/>(no causal mask)"] 819 ENC --> X["Cross-attention:<br/>decoder reads the audio"] 820 DEC["Decoder blocks<br/>(causal)"] --> X 821 X --> TXT["Text tokens,<br/>one at a time"] 822 TXT -.-> DEC 823``` 824 825**Reading it:** the left half is a front end like the image one: turn the 826signal into a grid, shrink it, and run a non-causal encoder so every moment 827of sound can inform every other. The right half is a text decoder with one 828extra step, cross-attention, where its queries come from the text written 829so far and its keys and values come from the audio (see 830`primer.ml.transformer` for encoders and decoders). The dotted arrow is the 831generation loop: each new word is fed back in. 832 833**In code:** `audio_tokens` counts encoder positions from a clip's length, the hop and the downsampling. 834 835**Why it matters in practice.** The same audio encoder can feed a general 836language model instead of a dedicated decoder: add a projector, splice the 837audio tokens into the prompt, and the model can answer questions about a 838recording, exactly as with images. Fifty tokens a second is manageable for 839a short voice message and expensive for an hour-long meeting. 840 841## Generating images and speech: discrete tokens from a codebook 842 843So far the model *reads* pictures and sound. To *write* them, a language 844model needs them as something it can predict one at a time from a fixed 845vocabulary, the way it predicts words. 846 847**Everyday picture.** A paint-by-numbers kit comes with a palette of 848numbered pots. Any small area of a picture is described by the number of 849the pot closest to its colour. The whole picture becomes a grid of pot 850numbers, and anyone with the same palette can repaint it. The palette is a 851**codebook**; snapping to the nearest entry is **vector quantization**. 852 853**Tiny example.** A codebook of three 2-number entries: $c_0 = (0, 0)$, 854$c_1 = (1, 0)$, $c_2 = (0, 1)$. The vector $z = (0.9, 0.2)$ has squared 855distances 0.85, 0.05 and 1.45 to them, so it becomes id **1**. Decoding id 1 856gives back (1, 0): close, not exact. 857 858$$ 859q(z) = \arg\min_{k \in \{0, \ldots, K-1\}} \lVert z - c_k \rVert^2 860$$ 861 862**Symbols** 863 864| Symbol | Meaning here | In the example | 865|---|---|---| 866| $z$ | one vector to encode: an image patch's vector or a slice of sound | (0.9, 0.2) | 867| $c_k$ | codebook entry number $k$ | $c_1 = (1, 0)$ | 868| $K$ | the codebook size: how many entries | 3 | 869| $k \in \{0, \ldots, K-1\}$ | "$k$ ranges over the entry numbers" | 0, 1, 2 | 870| $\lVert z - c_k \rVert^2$ | squared distance: subtract, square each difference, add | $(0.9-1)^2 + (0.2-0)^2 = 0.05$ | 871| $\arg\min_k$ | "the $k$ that gives the smallest value" (the position of the minimum, not the minimum itself) | 1 | 872| $q(z)$ | the id that replaces $z$ | 1 | 873 874**In words:** "replace each vector by the number of its nearest codebook 875entry." 876 877**With the numbers:** distances squared to $c_0, c_1, c_2$ are 8780.81 + 0.04 = 0.85, 0.01 + 0.04 = 0.05 and 0.81 + 0.64 = 1.45; the 879smallest is 0.05, at $k = 1$. 880 881**In Python:** 882 883```python 884z = [0.9, 0.2] 885codebook = [[0, 0], [1, 0], [0, 1]] 886# ‖z − c_k‖² for each entry 887d2 = [sum((a - b) ** 2 for a, b in zip(z, c)) for c in codebook] 888[round(d, 2) for d in d2] # → [0.85, 0.05, 1.45] 889# arg min: the position of the smallest 890d2.index(min(d2)) # → 1 891``` 892 893```mermaid 894flowchart LR 895 IN["Picture or sound"] --> E["Encoder<br/>vectors"] 896 E --> Q["Snap to nearest<br/>codebook entry"] 897 Q --> IDS["Ids, like word tokens<br/>e.g. 17, 803, 4, ..."] 898 IDS --> LM["Language model<br/>learns to predict ids<br/>after text"] 899 LM --> GEN["Generated ids"] 900 GEN --> LOOK["Look up codebook<br/>vectors"] 901 LOOK --> D["Decoder"] --> OUTP["Pixels or waveform"] 902``` 903 904**Reading it:** the top row is used during training: real pictures and 905sounds are encoded, snapped to the codebook, and become sequences of ids 906that sit in the training text next to their descriptions. The language 907model learns to continue a caption with ids the same way it learns to 908continue a sentence with words; its vocabulary is simply enlarged by $K$ 909entries. At generation time (bottom row) the model writes ids, the codebook 910turns them back into vectors, and a decoder paints pixels or synthesises a 911waveform. The encoder, codebook and decoder together are a VQ-VAE (see 912`primer.ml.generative.autoencoders`). 913 914How is the codebook chosen? It is learned so that the entries sit where the 915data actually is, which amounts to k-means clustering (see 916`primer.ml.embeddings.clustering`): snap every vector to its nearest entry, 917move each entry to the average of the vectors that chose it, and repeat. 918For audio, one codebook is rarely precise enough, so neural audio codecs 919use **residual vector quantization**: a second codebook encodes what the 920first one missed, a third what the second missed, and so on. Each moment 921of sound becomes a small stack of ids. 922 923 924 925**Reading it:** the x-axis is bits per patch: a codebook of $K$ entries 926costs log₂ $K$ bits per id, so 64 entries is 6 bits. The y-axis (log scale) 927is the reconstruction error on patches of *new* pictures, not the ones the 928codebook was learned from. Random codebooks (red) are useless at every 929size: their entries sit where no data lives. Learned codebooks (blue) fall 930fast and then flatten near the dotted line, which is the error you would get 931by reproducing each clean pattern perfectly and dropping only the pixel 932noise. The green squares stack 8-entry codebooks, each learned on the 933previous one's leftovers: after four stages (12 bits) they reach below the 934dotted line, because the extra codes start describing the noise of each 935particular patch too. 936 937**In code:** `quantize` is the arg min above and `dequantize` the lookup; `kmeans_codebook` learns a codebook; `learn_residual_codebooks` and `residual_quantize` stack codebooks on the leftovers. 938 939**Why it matters in practice.** Discrete tokens let one model read and 940write every modality with one mechanism, next-token prediction. The costs 941are real: a 256×256 image compressed eight-fold per side is 32 × 32 = 9421,024 ids (the scheme of the original DALL·E), and a neural audio codec 943running at 75 frames a second with 8 codebooks writes 600 ids a second. The 944other road to generating images is diffusion (see 945`primer.ml.generative.diffusion`): the language model supplies text or 946vectors that *condition* a diffusion model, which paints the pixels in many 947small denoising steps. Discrete tokens are simpler to bolt onto a language 948model; diffusion usually renders finer detail. 949 950## Video: pictures over time 951 952**Everyday picture.** A flipbook. Each page is a picture, and neighbouring 953pages are almost identical. To follow the story you don't need to look at 954every page; a glance at every tenth page shows what happens. 955 956**Tiny example.** A 10-second clip at 30 frames a second, with each frame 957cut into 256 tokens (224×224 in 14-pixel patches): 300 frames × 256 = 958**76,800 tokens**, more than half of a 128,000-token context, for ten 959seconds. Keeping one frame a second gives 10 × 256 = **2,560**. 960 961$$ 962N_{\text{video}} = \frac{D \cdot r}{t} \cdot \frac{H}{P} \cdot \frac{W}{P} 963$$ 964 965**Symbols** 966 967| Symbol | Meaning here | In the example | 968|---|---|---| 969| $D$ | the clip's duration, in seconds | 10 | 970| $r$ | frames kept per second (the **sampling rate**, often far below the video's own frame rate) | 30, then 1 | 971| $t$ | the **tubelet** depth: how many consecutive frames share one token, when a patch is cut through time as well as space | 1 | 972| $D \cdot r / t$ | how many frame slots become tokens | 300, then 10 | 973| $\frac{H}{P} \cdot \frac{W}{P}$ | tokens per frame, from the image formula | 16 · 16 = 256 | 974| $N_{\text{video}}$ | the clip's total tokens | 76,800, then 2,560 | 975 976**In words:** "count the frames you keep, divide by how many frames each 977token spans, and multiply by the tokens per frame." 978 979**With the numbers:** (10 · 30 / 1) · 16 · 16 = 300 · 256 = 76,800; at one 980frame a second, (10 · 1 / 1) · 256 = 2,560; sampling 2 frames a second in 981tubelets 2 frames deep gives (10 · 2 / 2) · 256 = 2,560 again, while 982covering twice as many moments. 983 984**In Python:** 985 986```python 987H = W = 224 988P = 14 989tokens_per_frame = (H // P) * (W // P) 990tokens_per_frame # → 256 991D, r, t = 10, 30, 1 992D * r // t * tokens_per_frame # → 76800 993# one frame a second 994D, r, t = 10, 1, 1 995D * r // t * tokens_per_frame # → 2560 996``` 997 998```mermaid 999flowchart LR 1000 V["Video<br/>30 frames a second"] --> S["Sample frames<br/>e.g. 1 a second"] 1001 S --> ENC["Vision encoder per frame<br/>(or tubelets across frames)"] 1002 ENC --> M["Merge neighbouring<br/>patch tokens"] 1003 M --> PR["Projector"] 1004 PR --> SEQ["Frame tokens,<br/>with timestamps as text"] 1005 SEQ --> LM["Language model"] 1006``` 1007 1008**Reading it:** each box from left to right cuts the token count. Frame 1009sampling throws away near-duplicate pages of the flipbook; tubelets and 1010merging squeeze each kept moment into fewer tokens. A short text timestamp 1011before each frame's tokens ("at 0:05") lets the model say *when* something 1012happened. What is left is the image pipeline, repeated once per kept frame. 1013 1014**In code:** `video_tokens` is the formula, and `sample_frames` picks the evenly spaced frames to keep. 1015 1016**Why it matters in practice.** Sampling is a bet that nothing important 1017happens between the frames you keep: one frame a second is fine for a 1018lecture and useless for a golf swing. Real systems adapt: more frames for 1019short or fast clips, fewer and smaller ones for long recordings, and a 1020transcript of the soundtrack alongside. 1021 1022## What it costs: tokens per second and the context budget 1023 1024**Everyday picture.** Packing a suitcase. Text is neatly folded shirts; 1025images are shoes; video is an inflatable boat. The suitcase (the context 1026window) is the same size whatever you pack. 1027 1028**Tiny example.** A 128,000-token window holds 128,000 / 256 = **500 1029seconds**, about 8 minutes, of video sampled at one frame a second, before 1030a single word of the question. The same window holds about 11 hours of 1031speech written out as text. 1032 1033| Input | Tokens per second | Minutes in 128k tokens | 1034|---|---|---| 1035| speech written as text (about 150 words a minute, about 1.3 tokens a word) | 3.2 | 656 | 1036| speech as audio-encoder tokens | 50 | 43 | 1037| video, 1 frame a second, 256 tokens a frame | 256 | 8.3 | 1038| audio as codec tokens (75 frames × 8 codebooks) | 600 | 3.6 | 1039| video, 30 frames a second, 256 tokens a frame | 7,680 | 0.3 | 1040 1041 1042 1043**Reading it:** both axes are logarithmic, so each line is the same slope 1044shifted up or down by its tokens per second. Read across at a dashed line 1045(a context window) to see how long a recording of each kind fits. Text 1046(grey) is so dense that hours of speech fit easily. Audio tokens (green) 1047fill a 128k window in about 43 minutes, sampled video (blue) in about 8, 1048and full-rate video (red) in under 20 seconds. The gap between the grey 1049line and the others is the price of keeping the raw signal instead of 1050words. 1051 1052**In code:** `seconds_that_fit` divides a window by a rate, and `TOKENS_PER_SECOND` holds the rates in the table. 1053 1054**Why it matters in practice.** Every image and second of audio is billed 1055and computed like text: it takes room in the context window, lengthens the 1056prefill before the first word of the answer (see `primer.ml.inference`), 1057and competes with instructions and retrieved documents for attention (see 1058`primer.agents.context`). The practical levers follow from the formulas: 1059send the smallest resolution that still shows the detail you need, crop to 1060the region that matters, sample fewer frames, and transcribe audio to text 1061when the words matter and the tone does not. 1062 1063## In 20 seconds 1064 1065- **One idea:** every modality becomes a sequence of vectors as wide as the 1066 language model's word vectors; after that it is ordinary attention. 1067- **Images:** a Vision Transformer cuts a picture into patches, projects each 1068 one, adds a position, and runs non-causal encoder blocks. Tokens = 1069 (H/P)·(W/P), so they grow with the square of the resolution. 1070- **Connecting to a language model:** a small projector maps image vectors 1071 into the embedding space, and they are spliced into the prompt. Train the 1072 projector first with everything frozen, then fine-tune on image 1073 instructions. 1074- **Audio:** waveform, then a log-mel spectrogram (a Fourier transform per 1075 25 ms slice, pooled into ear-shaped bands), then an encoder: about 50 1076 tokens a second. 1077- **Generating pictures and sound:** snap vectors to a learned codebook so 1078 they become ids a language model can predict like words; or hand off to a 1079 diffusion model. 1080- **Video and cost:** frames multiply image tokens by time; sample frames, 1081 merge tokens, and remember that text is by far the densest input. 1082 1083## Self-test questions 1084 1085**How can a chatbot "see" a photo, explained without jargon?** 1086The photo is cut into a grid of small squares, and each square is described 1087by a list of numbers in the same format the model uses for words. The model 1088then reads the squares and the words of your question together, paying 1089attention to whichever squares help answer it. It never sees the picture 1090as a picture: it reads it as a few hundred extra "words". 1091 1092**How many tokens is a 448×448 image with 14-pixel patches? And if each 10932×2 block of neighbours is merged?** 1094448 / 14 = 32 patches a side, so 32 × 32 = 1,024 tokens. Merging 2×2 1095blocks divides by 4: 256 tokens. Doubling the side from 224 would have 1096quadrupled the count. 1097 1098**Why does a Vision Transformer need position vectors, and why is its 1099attention not causal?** 1100Attention ignores order, so without positions the model sees an unordered 1101bag of patches and cannot tell the sky from the ground. It is not causal 1102because a picture has no "future": every patch may use every other, and 1103hiding half the image would only throw information away. 1104 1105**What does the projector do, and why train it first with both big models 1106frozen?** 1107It maps each image vector into the language model's embedding space, so 1108image tokens look like something the language model can use. Training it 1109alone first is cheap (it is tiny) and safe (the frozen models keep all 1110they know). Only once the two sides understand each other is the language 1111model tuned on image instructions. 1112 1113**In a prompt, why does it matter whether the image comes before or after 1114the question?** 1115The language model is causal: a token can only attend to tokens before it. 1116Question tokens placed after the image can look at it while being 1117processed; question tokens placed before it cannot. The answer comes after 1118both either way, but putting the image first lets the whole question be read 1119in light of the picture. 1120 1121**Why does a speech model read a log-mel spectrogram rather than raw 1122samples?** 1123Raw audio is 16,000 numbers a second with pitch hidden in the wiggles. The 1124spectrogram makes pitch explicit (which frequencies sound at each moment), 1125the mel bands spend detail where ears and speech need it, the log matches 1126how loudness is heard, and 100 frames a second is far fewer positions to 1127attend over. 1128 1129**How can a model that only predicts tokens produce an image or a voice?** 1130Encode pictures or sounds into vectors, snap each vector to its nearest 1131entry in a learned codebook, and use the entry numbers as extra vocabulary. 1132The model learns to predict those ids after a caption, and a decoder turns 1133generated ids back into pixels or a waveform. The alternative is to have 1134the model condition a diffusion model that paints the image. 1135 1136**A 20-minute video goes to a model with a 128,000-token window. What goes 1137wrong, and what can be done?** 1138At one frame a second and 256 tokens a frame it is 1,200 × 256 = 307,200 1139tokens, more than twice the window, before any question. Options: sample 1140far fewer frames (one every 5 seconds gives 61,440), merge neighbouring 1141patch tokens, lower the resolution, transcribe the soundtrack to text, or 1142split the video and summarise the parts. 1143 1144## The papers behind this lesson 1145 1146- **Dosovitskiy et al., *An Image is Worth 16x16 Words: Transformers for 1147 Image Recognition at Scale* (2020)**: https://arxiv.org/abs/2010.11929. 1148 Showed that a plain transformer over image patches matches convolutional 1149 networks when trained on enough data: the Vision Transformer. 1150 [Annotated companion](../../../papers/vit.html) 1151- **Radford et al., *Learning Transferable Visual Models From Natural 1152 Language Supervision* (CLIP, 2021)**: https://arxiv.org/abs/2103.00020. 1153 Trained an image encoder and a text encoder into one shared space; its 1154 image encoder is the starting point of many vision-language models. 1155 [Annotated companion](../../../papers/clip.html) 1156- **Alayrac et al., *Flamingo: a Visual Language Model for Few-Shot 1157 Learning* (2022)**: https://arxiv.org/abs/2204.14198. Connected a frozen 1158 vision encoder to a frozen language model through new cross-attention 1159 layers, handling images and video interleaved with text. 1160 [Annotated companion](../../../papers/flamingo.html) 1161- **Liu et al., *Visual Instruction Tuning* (LLaVA, 2023)**: 1162 https://arxiv.org/abs/2304.08485. The encode, project and splice recipe, 1163 trained in two stages: align the projector, then tune on image 1164 instructions. 1165 [Annotated companion](../../../papers/llava.html) 1166- **Radford et al., *Robust Speech Recognition via Large-Scale Weak 1167 Supervision* (Whisper, 2022)**: https://arxiv.org/abs/2212.04356. An 1168 encoder over log-mel spectrograms and a text decoder, trained on 680,000 1169 hours of transcribed audio. 1170 [Annotated companion](../../../papers/whisper.html) 1171- **van den Oord, Vinyals & Kavukcuoglu, *Neural Discrete Representation 1172 Learning* (VQ-VAE, 2017)**: https://arxiv.org/abs/1711.00937. Learned a 1173 codebook inside an autoencoder, turning images and audio into discrete 1174 tokens. 1175 [Annotated companion](../../../papers/vq-vae.html) 1176- **Zeghidour et al., *SoundStream: An End-to-End Neural Audio Codec* 1177 (2021)**: https://arxiv.org/abs/2107.03312. Residual vector quantization 1178 for audio: a stack of codebooks, each encoding the previous one's error. 1179- **Ramesh et al., *Zero-Shot Text-to-Image Generation* (DALL·E, 2021)**: 1180 https://arxiv.org/abs/2102.12092. Generated images as sequences of 1181 discrete codebook tokens after the text, with one transformer. 1182- **Arnab et al., *ViViT: A Video Vision Transformer* (2021)**: 1183 https://arxiv.org/abs/2103.15691. Extended patches through time as 1184 tubelets, and compared ways to factorise attention over space and time. 1185 1186## Further reading 1187 1188- Dosovitskiy et al., *An Image is Worth 16x16 Words* (ViT, 2020): https://arxiv.org/abs/2010.11929 1189- Liu et al., *Visual Instruction Tuning* (LLaVA, 2023): https://arxiv.org/abs/2304.08485 1190- Liu et al., *Improved Baselines with Visual Instruction Tuning* (LLaVA-1.5, 2023): https://arxiv.org/abs/2310.03744 1191- Li et al., *BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models* (2023): https://arxiv.org/abs/2301.12597 1192- Alayrac et al., *Flamingo* (2022): https://arxiv.org/abs/2204.14198 1193- Radford et al., *Whisper* (2022): https://arxiv.org/abs/2212.04356 and its code: https://github.com/openai/whisper 1194- Défossez et al., *High Fidelity Neural Audio Compression* (EnCodec, 2022): https://arxiv.org/abs/2210.13438 1195- van den Oord et al., *Neural Discrete Representation Learning* (VQ-VAE, 2017): https://arxiv.org/abs/1711.00937 1196- Chameleon Team, *Chameleon: Mixed-Modal Early-Fusion Foundation Models* (2024): https://arxiv.org/abs/2405.09818 1197- Arnab et al., *ViViT: A Video Vision Transformer* (2021): https://arxiv.org/abs/2103.15691 1198""" 1199 1200from __future__ import annotations 1201 1202import numpy as np 1203 1204from primer._show import banner, matrix, say, table, takeaway 1205from primer.ml.attention import softmax 1206from primer.ml.cnn_rnn import patchify 1207from primer.ml.transformer import TinyGPT, TransformerBlock, gelu, layer_norm 1208 1209# --------------------------------------------------------------------------- 1210# 1. Images into tokens: patches, projection, positions 1211# --------------------------------------------------------------------------- 1212 1213 1214def image_to_patches(image: np.ndarray, patch: int) -> np.ndarray: 1215 """Cut an (H, W) or (H, W, C) image into square patches, one flattened row each. 1216 1217 Returns (number of patches, patch·patch·C), row by row from the top left. 1218 The cutting itself is `primer.ml.cnn_rnn.patchify`; this adds the check 1219 that the patch size divides the image, because a ragged edge would give 1220 a last patch with pixels missing. 1221 """ 1222 image = np.asarray(image) 1223 if image.ndim == 2: 1224 image = image[:, :, None] # grayscale: one colour channel 1225 h, w, _ = image.shape 1226 if h % patch or w % patch: 1227 raise ValueError(f"a {patch}-pixel patch does not divide a {h}×{w} image; resize or pad it first") 1228 return patchify(image, patch) 1229 1230 1231def count_image_tokens(height: int, width: int, patch: int, merge: int = 1) -> int: 1232 """Tokens for one image: (H/P)·(W/P) patches, divided by merge² if neighbours are pooled. 1233 1234 Many vision-language models merge each merge×merge block of neighbouring 1235 patch vectors into one token before the language model sees them, which 1236 cuts the count by merge². 1237 """ 1238 if height % patch or width % patch: 1239 raise ValueError("resize the image to a multiple of the patch size first") 1240 grid_h, grid_w = height // patch, width // patch 1241 return (grid_h * grid_w) // (merge * merge) 1242 1243 1244# The hand-checkable example from the lesson: pixel brightnesses 0 to 15. 1245WORKED_IMAGE = np.arange(16).reshape(4, 4) 1246# Column 1 adds up a patch's top row of pixels, column 2 its bottom row. 1247WORKED_W_E = np.array([[1, 0], [1, 0], [0, 1], [0, 1]]) 1248# One position vector per patch: (row, column) of the patch in the grid. 1249WORKED_POSITIONS = np.array([[0, 0], [0, 1], [1, 0], [1, 1]]) 1250 1251 1252def worked_example_patches() -> dict[str, np.ndarray]: 1253 """The 4×4 image cut into four 2×2 patches, projected, then given positions. 1254 1255 | patch | pixels | x·W_E | + position | token | 1256 |--------------|--------------|----------|------------|----------| 1257 | top left | 0, 1, 4, 5 | (1, 9) | (0, 0) | (1, 9) | 1258 | top right | 2, 3, 6, 7 | (5, 13) | (0, 1) | (5, 14) | 1259 | bottom left | 8, 9, 12, 13 | (17, 25) | (1, 0) | (18, 25) | 1260 | bottom right | 10, 11, 14, 15 | (21, 29) | (1, 1) | (22, 30) | 1261 """ 1262 patches = image_to_patches(WORKED_IMAGE, patch=2) # (4, 4): 4 patches of 4 pixels 1263 projected = patches @ WORKED_W_E # (4, 2): each patch squeezed to 2 numbers 1264 return dict(patches=patches, projected=projected, tokens=projected + WORKED_POSITIONS) 1265 1266 1267class VisionEncoder: 1268 """A Vision Transformer, forward pass only: patches -> vectors -> encoder blocks. 1269 1270 ```text 1271 image (H, W, C) -> patches (N, P·P·C) -> ·W_E + b_E (N, d) -> + positions (N, d) 1272 -> n_layers × TransformerBlock(causal=False) -> LayerNorm (N, d) 1273 ``` 1274 1275 The blocks are `primer.ml.transformer.TransformerBlock` with the causal 1276 mask switched off: a picture has no "future", so every patch may attend 1277 to every other. Weights are random; this shows the machinery. 1278 """ 1279 1280 def __init__(self, image_size: int, patch: int, channels: int, d_model: int, n_layers: int, n_heads: int, seed: int = 0): 1281 rng = np.random.default_rng(seed) 1282 self.patch = patch 1283 self.n_patches = count_image_tokens(image_size, image_size, patch) 1284 patch_dim = patch * patch * channels 1285 # Scaled init keeps each token's numbers near unit size whatever the patch size. 1286 self.W_E = rng.normal(0, 1 / np.sqrt(patch_dim), (patch_dim, d_model)) 1287 self.b_E = np.zeros(d_model) 1288 # Learned positions, one vector per patch slot, as ViT does (std 0.02 as in GPT-2). 1289 self.pos = rng.normal(0, 0.02, (self.n_patches, d_model)) 1290 self.blocks = [TransformerBlock(d_model, n_heads, causal=False, seed=seed + 10 * i + 1) for i in range(n_layers)] 1291 1292 def embed(self, image: np.ndarray) -> np.ndarray: 1293 """(N, d): each patch projected to model width, plus its position vector.""" 1294 return image_to_patches(image, self.patch) @ self.W_E + self.b_E + self.pos 1295 1296 def __call__(self, image: np.ndarray) -> np.ndarray: 1297 """(N, d): one context-aware vector per patch, the image's tokens.""" 1298 x = self.embed(image) 1299 for block in self.blocks: 1300 x = block(x) 1301 return layer_norm(x) 1302 1303 1304# --------------------------------------------------------------------------- 1305# 2. The projector, and a toy vision-language model 1306# --------------------------------------------------------------------------- 1307 1308 1309class Projector: 1310 """Maps vision vectors into the language model's embedding space. 1311 1312 `hidden=None` is a single linear layer, v·W + b. With `hidden` set it is 1313 a two-layer MLP, GELU(v·W1 + b1)·W2 + b2: the same shape as a 1314 transformer's feed-forward network (`primer.ml.transformer.FeedForward`), 1315 with a different width on each side. 1316 """ 1317 1318 def __init__(self, d_in: int, d_out: int, hidden: int | None = None, seed: int = 0): 1319 rng = np.random.default_rng(seed) 1320 self.hidden = hidden 1321 if hidden is None: 1322 self.W = rng.normal(0, 1 / np.sqrt(d_in), (d_in, d_out)) 1323 self.b = np.zeros(d_out) 1324 else: 1325 self.W1 = rng.normal(0, 1 / np.sqrt(d_in), (d_in, hidden)) 1326 self.b1 = np.zeros(hidden) 1327 self.W2 = rng.normal(0, 1 / np.sqrt(hidden), (hidden, d_out)) 1328 self.b2 = np.zeros(d_out) 1329 1330 def __call__(self, v: np.ndarray) -> np.ndarray: 1331 # (N, d_in) -> (N, d_out): each image token translated on its own. 1332 if self.hidden is None: 1333 return v @ self.W + self.b 1334 return gelu(v @ self.W1 + self.b1) @ self.W2 + self.b2 1335 1336 1337# The worked linear projection: a 2-number vision vector into a 3-number text space. 1338WORKED_V = np.array([1, 2]) 1339WORKED_W_P = np.array([[1, 0, 1], [0, 1, 1]]) 1340 1341 1342def worked_example_projection() -> np.ndarray: 1343 """(1, 2)·W_P = (1·1 + 2·0, 1·0 + 2·1, 1·1 + 2·1) = (1, 2, 3).""" 1344 return WORKED_V @ WORKED_W_P 1345 1346 1347# A vocabulary small enough to print. Id 0 is the image placeholder. 1348TEXT_VOCAB = ["<image>", "a", "photo", "of", "horizontal", "vertical", "diagonal", "checkered", "stripes", "what", "is", "this"] 1349IMAGE = 0 1350CLASS_NAMES = ["horizontal", "vertical", "diagonal", "checkered"] 1351CLASS_WORD_IDS = np.array([TEXT_VOCAB.index(w) for w in CLASS_NAMES]) 1352 1353 1354class VisionLanguageModel: 1355 """Vision encoder -> projector -> image tokens spliced into a decoder language model. 1356 1357 The language model is `primer.ml.transformer.TinyGPT`. Instead of looking 1358 up every position in its token table, the image placeholder is replaced 1359 by the projected image tokens; everything after that is TinyGPT's own 1360 forward pass. 1361 """ 1362 1363 def __init__(self, vision: VisionEncoder, projector: Projector, lm: TinyGPT): 1364 self.vision, self.projector, self.lm = vision, projector, lm 1365 1366 def splice(self, ids: np.ndarray, image: np.ndarray) -> tuple[np.ndarray, np.ndarray]: 1367 """(L, d_lm) input vectors with the image tokens where `IMAGE` was, and an is-image flag per row.""" 1368 image_tokens = self.projector(self.vision(image)) # (N, d_lm) 1369 rows, flags = [], [] 1370 for token_id in ids: 1371 if token_id == IMAGE: 1372 rows.append(image_tokens) 1373 flags += [True] * len(image_tokens) 1374 else: 1375 rows.append(self.lm.wte[token_id][None, :]) # a text token: its row of the table 1376 flags.append(False) 1377 return np.concatenate(rows), np.array(flags) 1378 1379 def __call__(self, ids: np.ndarray, image: np.ndarray) -> np.ndarray: 1380 """(L, vocab) logits: row i scores every possible next token after position i.""" 1381 x, _ = self.splice(ids, image) 1382 x = x + self.lm.wpe[: len(x)] # positions count image tokens too 1383 for block in self.lm.blocks: 1384 x = block(x) 1385 return layer_norm(x, self.lm.lnf_g, self.lm.lnf_b) @ self.lm.wte.T 1386 1387 1388def build_toy_vlm(seed: int = 0) -> VisionLanguageModel: 1389 """An 8×8 grayscale ViT (4 patches, width 16), a linear projector, and a width-24 TinyGPT.""" 1390 vision = VisionEncoder(image_size=8, patch=4, channels=1, d_model=16, n_layers=2, n_heads=2, seed=seed) 1391 projector = Projector(16, 24, seed=seed + 1) 1392 lm = TinyGPT(vocab_size=len(TEXT_VOCAB), d_model=24, n_layers=2, n_heads=2, max_len=32, seed=seed + 2) 1393 return VisionLanguageModel(vision, projector, lm) 1394 1395 1396def toy_images(n_per_class: int, size: int = 8, seed: int = 0) -> tuple[np.ndarray, np.ndarray]: 1397 """Four kinds of 8×8 grayscale picture (horizontal, vertical, diagonal, checkered), with noise. 1398 1399 Each image gets its own contrast, brightness and pixel noise, so no two 1400 are identical. Returns (images (4n, size, size), labels (4n,)). 1401 """ 1402 rng = np.random.default_rng(seed) 1403 r, c = np.mgrid[0:size, 0:size] 1404 # 2-pixel-wide bands, so every 4×4 patch holds a full light-and-dark cycle of its pattern. 1405 patterns = [(r // 2) % 2, (c // 2) % 2, ((r + c) // 2) % 2, (r // 2 + c // 2) % 2] 1406 images, labels = [], [] 1407 for label, pattern in enumerate(patterns): 1408 for _ in range(n_per_class): 1409 contrast, brightness = rng.uniform(0.6, 1.4), rng.uniform(-0.3, 0.3) 1410 images.append(contrast * pattern + brightness + 0.3 * rng.standard_normal((size, size))) 1411 labels.append(label) 1412 return np.array(images, dtype=float), np.array(labels) 1413 1414 1415def _pooled_features(model: VisionLanguageModel, images: np.ndarray) -> np.ndarray: 1416 """(B, d_vision): the mean of each image's vision tokens. The encoder is frozen, so these can be computed once.""" 1417 return np.array([model.vision(im).mean(axis=0) for im in images]) 1418 1419 1420def caption_accuracy(model: VisionLanguageModel, images: np.ndarray, labels: np.ndarray) -> float: 1421 """Share of images whose projected tokens score their own class word highest in the whole vocabulary.""" 1422 h = model.projector(_pooled_features(model, images)) # (B, d_lm) 1423 predicted = (h @ model.lm.wte.T).argmax(axis=1) # scored against every word, as the output layer does 1424 return float(np.mean(predicted == CLASS_WORD_IDS[labels])) 1425 1426 1427def align_projector(model: VisionLanguageModel, images: np.ndarray, labels: np.ndarray, steps: int = 300, lr: float = 2.0) -> dict[str, list[float]]: 1428 """Stage 1 of training: fit only the (linear) projector so each image says its caption word. 1429 1430 The loss is cross-entropy on the caption word, scored by the language 1431 model's own output layer (its tied token table). The vision encoder and 1432 the language model are frozen: only `projector.W` and `projector.b` move. 1433 A real model sends the image tokens through every language-model layer 1434 and back-propagates through them; this toy scores the pooled image 1435 vector against the token table directly, the last step of that same path. 1436 """ 1437 v = _pooled_features(model, images) # (B, d_vision), fixed while training 1438 wte = model.lm.wte # (vocab, d_lm), frozen 1439 target = CLASS_WORD_IDS[labels] 1440 history: dict[str, list[float]] = {"loss": [], "accuracy": []} 1441 for _ in range(steps): 1442 h = model.projector(v) # (B, d_lm) 1443 p = softmax(h @ wte.T) # (B, vocab) 1444 history["loss"].append(float(-np.mean(np.log(p[np.arange(len(v)), target])))) 1445 history["accuracy"].append(float(np.mean(p.argmax(axis=1) == target))) 1446 # Gradient of mean cross-entropy: (p - one_hot) flows back through the frozen table. 1447 d_logits = p.copy() 1448 d_logits[np.arange(len(v)), target] -= 1 1449 d_h = d_logits @ wte / len(v) # (B, d_lm) 1450 model.projector.W -= lr * v.T @ d_h 1451 model.projector.b -= lr * d_h.sum(axis=0) 1452 return history 1453 1454 1455# --------------------------------------------------------------------------- 1456# 3. Audio: waveform -> spectrogram -> tokens 1457# --------------------------------------------------------------------------- 1458 1459 1460def tone(freq: float, seconds: float, sample_rate: int) -> np.ndarray: 1461 """A pure sine wave: the waveform of a single steady pitch.""" 1462 t = np.arange(int(seconds * sample_rate)) / sample_rate 1463 return np.sin(2 * np.pi * freq * t) 1464 1465 1466def chirp(f_start: float, f_end: float, seconds: float, sample_rate: int) -> np.ndarray: 1467 """A sine whose pitch rises steadily from f_start to f_end, like a whistle sliding up.""" 1468 t = np.arange(int(seconds * sample_rate)) / sample_rate 1469 # Phase is the running total of frequency: f(t) = f_start + (f_end - f_start)·t/T. 1470 return np.sin(2 * np.pi * (f_start * t + (f_end - f_start) * t**2 / (2 * seconds))) 1471 1472 1473def _dft_basis(n: int, n_bins: int) -> tuple[np.ndarray, np.ndarray]: 1474 """(n, n_bins) cosine and sine waves: column k completes k cycles in n samples.""" 1475 k = np.arange(n_bins)[None, :] 1476 t = np.arange(n)[:, None] 1477 angle = 2 * np.pi * k * t / n 1478 return np.cos(angle), np.sin(angle) 1479 1480 1481def dft_magnitudes(x) -> np.ndarray: 1482 """|X_k| for k = 0..n-1: how much of the wave that cycles k times the signal contains. 1483 1484 Written as the definition, with no fast Fourier transform: correlate the 1485 signal with a cosine and a sine of each frequency, and take the length 1486 of the pair. 1487 """ 1488 x = np.asarray(x, dtype=float) 1489 cos, sin = _dft_basis(len(x), len(x)) 1490 return np.sqrt((x @ cos) ** 2 + (x @ sin) ** 2) 1491 1492 1493def frame_count(n_samples: int, window: int, hop: int) -> int: 1494 """Whole windows that fit: 1 + ⌊(L - N) / H⌋.""" 1495 return 1 + (n_samples - window) // hop 1496 1497 1498def hann(n: int) -> np.ndarray: 1499 """A window that rises from 0 to 1 and back, so each slice fades in and out instead of starting with a click.""" 1500 return 0.5 - 0.5 * np.cos(2 * np.pi * np.arange(n) / (n - 1)) 1501 1502 1503def stft(x: np.ndarray, window: int, hop: int) -> np.ndarray: 1504 """Short-time Fourier transform magnitudes: (frames, window//2 + 1). 1505 1506 Slide a window of `window` samples along the signal in steps of `hop`, 1507 fade each slice with a Hann window, and measure every frequency in it. 1508 Only bins 0..window/2 are kept: for a real signal the rest mirror them. 1509 """ 1510 t = frame_count(len(x), window, hop) 1511 starts = np.arange(t)[:, None] * hop 1512 frames = x[starts + np.arange(window)[None, :]] * hann(window) # (T, window) 1513 cos, sin = _dft_basis(window, window // 2 + 1) 1514 return np.sqrt((frames @ cos) ** 2 + (frames @ sin) ** 2) 1515 1516 1517def hz_to_mel(f): 1518 """mel(f) = 2595·log10(1 + f/700): roughly even steps below 700 Hz, ratios above.""" 1519 return 2595 * np.log10(1 + np.asarray(f, dtype=float) / 700) 1520 1521 1522def mel_to_hz(m): 1523 """The inverse of `hz_to_mel`.""" 1524 return 700 * (10 ** (np.asarray(m, dtype=float) / 2595) - 1) 1525 1526 1527def mel_filterbank(n_mels: int, n_fft: int, sample_rate: int) -> np.ndarray: 1528 """(n_mels, n_fft//2 + 1) triangular filters, evenly spaced in mel, so wider in hertz as pitch rises. 1529 1530 Filter m rises from 0 at mel point m to 1 at point m+1 and falls back to 1531 0 at point m+2. Multiplying a spectrogram by this matrix's transpose 1532 adds up each band's energy: many fine bins become a few bands. 1533 """ 1534 edges = mel_to_hz(np.linspace(0, hz_to_mel(sample_rate / 2), n_mels + 2)) # n_mels + 2 edges in Hz 1535 freqs = np.arange(n_fft // 2 + 1) * sample_rate / n_fft # the frequency of each spectrogram bin 1536 lo, centre, hi = edges[:-2, None], edges[1:-1, None], edges[2:, None] 1537 rising = (freqs - lo) / (centre - lo) 1538 falling = (hi - freqs) / (hi - centre) 1539 return np.maximum(0, np.minimum(rising, falling)) 1540 1541 1542def log_mel_spectrogram(x: np.ndarray, sample_rate: int, window: int, hop: int, n_mels: int) -> np.ndarray: 1543 """(frames, n_mels): power per mel band, on a log scale because loudness is heard by ratio too.""" 1544 power = stft(x, window, hop) ** 2 1545 return np.log10(power @ mel_filterbank(n_mels, window, sample_rate).T + 1e-10) 1546 1547 1548def audio_tokens(seconds: float, hop_ms: float = 10, downsample: int = 2) -> int: 1549 """Encoder positions for a clip: one spectrogram frame per hop, halved by a stride-2 convolution.""" 1550 return int(round(seconds * 1000 / hop_ms)) // downsample 1551 1552 1553# --------------------------------------------------------------------------- 1554# 4. Discrete tokens for outputs: vector quantization 1555# --------------------------------------------------------------------------- 1556 1557 1558def quantize(Z: np.ndarray, codebook: np.ndarray) -> np.ndarray: 1559 """(n,) ids: for each row of Z, the number of the nearest codebook entry.""" 1560 # ‖z - c‖² for every pair, (n, K), without a Python loop. 1561 d2 = (Z**2).sum(axis=1)[:, None] - 2 * Z @ codebook.T + (codebook**2).sum(axis=1)[None, :] 1562 return d2.argmin(axis=1) 1563 1564 1565def dequantize(ids: np.ndarray, codebook: np.ndarray) -> np.ndarray: 1566 """(n, d): look each id up in the codebook. What a decoder receives back.""" 1567 return codebook[ids] 1568 1569 1570def quantization_error(Z: np.ndarray, codebook: np.ndarray) -> float: 1571 """Mean squared difference between each vector and the codebook entry it snaps to.""" 1572 return float(np.mean((Z - dequantize(quantize(Z, codebook), codebook)) ** 2)) 1573 1574 1575def kmeans_codebook(Z: np.ndarray, k: int, iters: int = 20, seed: int = 0) -> np.ndarray: 1576 """Learn k codebook entries with k-means: snap every vector, move each entry to its vectors' mean. 1577 1578 VQ-VAE learns its codebook inside a network, but the update it converges 1579 to is this one (see `primer.ml.embeddings.clustering` for k-means). 1580 """ 1581 rng = np.random.default_rng(seed) 1582 codebook = Z[rng.choice(len(Z), size=k, replace=False)].copy() # start from k real vectors 1583 for _ in range(iters): 1584 ids = quantize(Z, codebook) 1585 for j in range(k): 1586 members = Z[ids == j] 1587 if len(members): # an entry nobody chose keeps its place rather than becoming NaN 1588 codebook[j] = members.mean(axis=0) 1589 return codebook 1590 1591 1592def learn_residual_codebooks(Z: np.ndarray, k: int, stages: int, seed: int = 0) -> list[np.ndarray]: 1593 """Residual vector quantization: each new codebook is learned on what the previous ones missed.""" 1594 books, residual = [], Z.copy() 1595 for s in range(stages): 1596 book = kmeans_codebook(residual, k, seed=seed + s) 1597 residual = residual - dequantize(quantize(residual, book), book) 1598 books.append(book) 1599 return books 1600 1601 1602def residual_quantize(Z: np.ndarray, codebooks: list[np.ndarray]) -> tuple[np.ndarray, np.ndarray]: 1603 """(ids (stages, n), reconstruction (n, d)): one id per stage per vector; the sum of their entries rebuilds it.""" 1604 ids, recon, residual = [], np.zeros_like(Z, dtype=float), Z.astype(float) 1605 for book in codebooks: 1606 stage_ids = quantize(residual, book) 1607 recon = recon + book[stage_ids] 1608 residual = residual - book[stage_ids] 1609 ids.append(stage_ids) 1610 return np.array(ids), recon 1611 1612 1613# --------------------------------------------------------------------------- 1614# 5. Video and the context budget 1615# --------------------------------------------------------------------------- 1616 1617 1618def video_tokens(seconds: float, sample_fps: float, tokens_per_frame: int, tubelet: int = 1) -> int: 1619 """(seconds · sampled frames per second / frames per tubelet) · tokens per frame.""" 1620 frames = int(round(seconds * sample_fps)) 1621 return (frames // tubelet) * tokens_per_frame 1622 1623 1624def sample_frames(n_frames: int, video_fps: float, target_fps: float) -> np.ndarray: 1625 """Indices of the frames kept when sampling a video at `target_fps`: evenly spaced, starting at 0.""" 1626 step = video_fps / target_fps 1627 return np.floor(np.arange(0, n_frames, step)).astype(int) 1628 1629 1630def seconds_that_fit(context_tokens: int, tokens_per_second: float) -> float: 1631 """How many seconds of a stream fit in a context window, ignoring the prompt and the answer.""" 1632 return context_tokens / tokens_per_second 1633 1634 1635# --------------------------------------------------------------------------- 1636# 6. Figures 1637# --------------------------------------------------------------------------- 1638 1639 1640# Rough tokens per second of input, for comparing modalities (see the lesson for where each comes from). 1641TOKENS_PER_SECOND = { 1642 "speech written as text (150 words a minute)": 150 * 1.3 / 60, 1643 "speech as audio-encoder tokens": audio_tokens(1), 1644 "video, 1 frame a second, 256 tokens a frame": video_tokens(1, 1, 256), 1645 "audio as codec tokens (75 frames × 8 codebooks)": 75 * 8, 1646 "video, 30 frames a second, 256 tokens a frame": video_tokens(1, 30, 256), 1647} 1648 1649SAMPLE_RATE = 8000 # samples per second for the lesson's synthetic audio 1650 1651 1652def demo_signal(seconds: float = 1.0) -> np.ndarray: 1653 """A whistle sliding up from 200 Hz to 3000 Hz over a steady, quieter 1000 Hz hum.""" 1654 return chirp(200, 3000, seconds, SAMPLE_RATE) + 0.5 * tone(1000, seconds, SAMPLE_RATE) 1655 1656 1657def toy_picture(size: int = 32) -> np.ndarray: 1658 """A 32×32 grayscale scene to cut into patches: a sun above a striped field.""" 1659 r, c = np.mgrid[0:size, 0:size] 1660 sky = 0.25 + 0.3 * (r < size // 2) 1661 sun = ((r - 9) ** 2 + (c - 22) ** 2 < 25) * 0.6 1662 field = (r >= size // 2) * (0.3 + 0.4 * ((c // 3) % 2)) 1663 return np.clip(sky * (r < size // 2) + sun + field, 0, 1) 1664 1665 1666def codebook_sweep(sizes=(1, 2, 4, 8, 16, 32, 64), seed: int = 0) -> list[dict]: 1667 """Quantization error on new toy-image patches, for learned and random codebooks of each size. 1668 1669 The codebook is learned on one set of images and scored on another, so a 1670 large codebook cannot look good by memorising the noise it was fitted to. 1671 """ 1672 patches = np.concatenate([image_to_patches(im, 4) for im in toy_images(30)[0]]) 1673 new = np.concatenate([image_to_patches(im, 4) for im in toy_images(30, seed=99)[0]]) 1674 rng = np.random.default_rng(seed) 1675 lo, hi = patches.min(), patches.max() 1676 rows = [] 1677 for k in sizes: 1678 random = rng.uniform(lo, hi, (k, patches.shape[1])) 1679 rows.append(dict(k=k, bits=float(np.log2(k)), learned=quantization_error(new, kmeans_codebook(patches, k, seed=seed)), 1680 random=quantization_error(new, random))) 1681 return rows 1682 1683 1684# --------------------------------------------------------------------------- 1685# 6. Figures 1686# --------------------------------------------------------------------------- 1687 1688 1689def figures() -> dict: 1690 """Plot this lesson's data. matplotlib is imported here, and only here, 1691 so the lesson itself needs nothing beyond NumPy.""" 1692 import matplotlib 1693 1694 matplotlib.use("Agg") 1695 import matplotlib.pyplot as plt 1696 1697 BLUE, RED, GREEN, AMBER, PURPLE, MUTED = "#2563eb", "#dc2626", "#059669", "#d97706", "#7c3aed", "#9ca3af" 1698 figs = {} 1699 1700 # --- 1. An image cut into patches, and the token matrix it becomes -------- 1701 picture = toy_picture() 1702 patches = image_to_patches(picture, 8) 1703 fig, (a1, a2) = plt.subplots(1, 2, figsize=(9, 3.8), gridspec_kw=dict(width_ratios=[1, 1.6])) 1704 a1.imshow(picture, cmap="gray", vmin=0, vmax=1) 1705 for edge in range(0, 33, 8): 1706 a1.axhline(edge - 0.5, color=AMBER, lw=1.5) 1707 a1.axvline(edge - 0.5, color=AMBER, lw=1.5) 1708 for i in range(16): 1709 a1.text((i % 4) * 8 + 3.5, (i // 4) * 8 + 3.5, str(i), color="white", ha="center", va="center", fontweight="bold", 1710 bbox=dict(boxstyle="round,pad=0.15", fc="#1f2937", ec="none", alpha=0.75)) 1711 a1.set_xticks([]) 1712 a1.set_yticks([]) 1713 a1.grid(False) 1714 a1.set_title("32×32 image, 8-pixel patches") 1715 a2.imshow(patches, cmap="gray", vmin=0, vmax=1, aspect="auto") 1716 a2.set_yticks(range(16)) 1717 a2.set_ylabel("token (patch number)") 1718 a2.set_xlabel("the patch's 64 pixels, read row by row") 1719 a2.grid(False) 1720 a2.set_title("…becomes 16 tokens of 64 numbers") 1721 fig.tight_layout() 1722 figs["patches"] = fig 1723 1724 # --- 2. Tokens per image as resolution grows -------------------------------- 1725 sides = np.arange(112, 1345, 112) 1726 fig, ax = plt.subplots(figsize=(6.4, 3.6)) 1727 for patch, merge, color, label in ((14, 1, RED, "14-pixel patches"), (16, 1, BLUE, "16-pixel patches"), 1728 (14, 2, GREEN, "14-pixel patches, 2×2 merged")): 1729 ax.plot(sides, [count_image_tokens(s, s, patch, merge) for s in sides], "o-", color=color, label=label, ms=4) 1730 ax.annotate("336 px → 576 tokens", xy=(336, 576), xytext=(130, 5200), arrowprops=dict(arrowstyle="->", color="#4b5563"), zorder=3, bbox=dict(facecolor="white", edgecolor="none", pad=1)) 1731 ax.set_xlabel("image side length (pixels)") 1732 ax.set_ylabel("tokens per image") 1733 ax.set_title("Double the side, quadruple the tokens") 1734 ax.legend(frameon=False) 1735 figs["image_tokens"] = fig 1736 1737 # --- 3. Stage-1 alignment: training only the projector ---------------------- 1738 model = build_toy_vlm() 1739 images, labels = toy_images(20) 1740 held_out = toy_images(20, seed=99) 1741 before = caption_accuracy(model, *held_out) 1742 history = align_projector(model, images, labels) 1743 after = caption_accuracy(model, *held_out) 1744 fig, (a1, a2) = plt.subplots(1, 2, figsize=(9, 3.3)) 1745 a1.plot(history["loss"], color=BLUE) 1746 a1.axhline(np.log(len(TEXT_VOCAB)), color=MUTED, ls="--") 1747 a1.text(len(history["loss"]) * 0.4, np.log(len(TEXT_VOCAB)) - 0.2, "blind guess over 12 words", color="#4b5563") 1748 a1.set_xlabel("training step") 1749 a1.set_ylabel("caption cross-entropy") 1750 a1.set_title("Only the projector learns") 1751 a2.plot(history["accuracy"], color=GREEN, label="training images") 1752 a2.axhline(0.25, color=MUTED, ls="--", label="chance (4 classes)") 1753 a2.scatter([0, len(history["accuracy"]) - 1], [before, after], color=RED, zorder=3, label="new images") 1754 a2.set_ylim(0, 1.05) 1755 a2.set_xlabel("training step") 1756 a2.set_ylabel("right caption word ranked first") 1757 a2.set_title(f"Caption accuracy: {before:.0%} → {after:.0%} on new images") 1758 a2.legend(frameon=False, loc="lower right") 1759 fig.tight_layout() 1760 figs["alignment"] = fig 1761 1762 # --- 4. Waveform, spectrogram, log-mel spectrogram -------------------------- 1763 x = demo_signal() 1764 window, hop = 256, 64 1765 spec = stft(x, window, hop) 1766 mel = log_mel_spectrogram(x, SAMPLE_RATE, window, hop, n_mels=40) 1767 seconds = len(x) / SAMPLE_RATE 1768 fig, (a1, a2, a3) = plt.subplots(3, 1, figsize=(7.5, 7.2)) 1769 t_ms = np.arange(160) / SAMPLE_RATE * 1000 1770 a1.plot(t_ms, x[:160], color=BLUE, lw=1) 1771 a1.set_xlabel("time (milliseconds): the first 20 ms only") 1772 a1.set_ylabel("pressure") 1773 a1.set_title("Waveform: 8,000 numbers a second, pitch hidden in the wiggles") 1774 a2.imshow(20 * np.log10(spec.T + 1e-6), origin="lower", aspect="auto", cmap="magma", 1775 extent=[0, seconds, 0, SAMPLE_RATE / 2], vmin=-40) 1776 a2.set_ylabel("frequency (Hz)") 1777 a2.set_xlabel("time (seconds)") 1778 a2.set_title(f"Spectrogram: {spec.shape[0]} frames × {spec.shape[1]} frequency bins") 1779 a2.grid(False) 1780 a3.imshow(mel.T, origin="lower", aspect="auto", cmap="magma", extent=[0, seconds, 0, 40], vmin=mel.max() - 5) 1781 a3.set_ylabel("mel band") 1782 a3.set_xlabel("time (seconds)") 1783 a3.set_title(f"Log-mel spectrogram: {mel.shape[0]} frames × {mel.shape[1]} bands") 1784 a3.grid(False) 1785 fig.tight_layout() 1786 figs["spectrogram"] = fig 1787 1788 # --- 5. The mel scale and its filters ---------------------------------------- 1789 fig, (a1, a2) = plt.subplots(1, 2, figsize=(9, 3.3)) 1790 hz = np.linspace(0, 8000, 400) 1791 a1.plot(hz, hz_to_mel(hz), color=PURPLE) 1792 a1.plot(hz, hz, color=MUTED, ls="--", label="if mel were hertz") 1793 a1.scatter([1000], [1000], color=RED, zorder=3) 1794 a1.annotate("1000 Hz = 1000 mel", xy=(1000, 1000), xytext=(2200, 400), arrowprops=dict(arrowstyle="->", color="#4b5563")) 1795 a1.set_xlabel("frequency (Hz)") 1796 a1.set_ylabel("mel") 1797 a1.set_title("Mel: even steps low, squeezed high") 1798 a1.legend(frameon=False) 1799 bank = mel_filterbank(10, 512, 16_000) 1800 freqs = np.arange(bank.shape[1]) * 16_000 / 512 1801 for row in bank: 1802 a2.plot(freqs, row) 1803 a2.set_xlabel("frequency (Hz)") 1804 a2.set_ylabel("weight") 1805 a2.set_title("10 mel filters: narrow low, wide high") 1806 fig.tight_layout() 1807 figs["mel"] = fig 1808 1809 # --- 6. Codebook size vs reconstruction error, and what it looks like ----------- 1810 rows = codebook_sweep() 1811 patches = np.concatenate([image_to_patches(im, 4) for im in toy_images(30)[0]]) 1812 books = learn_residual_codebooks(patches, k=8, stages=4) 1813 new = np.concatenate([image_to_patches(im, 4) for im in toy_images(30, seed=99)[0]]) 1814 stage_err = [float(np.mean((new - residual_quantize(new, books[:s])[1]) ** 2)) for s in range(1, 5)] 1815 fig, ax = plt.subplots(figsize=(6.4, 3.6)) 1816 bits = [r["bits"] for r in rows] 1817 ax.plot(bits, [r["random"] for r in rows], "o-", color=RED, label="random codebook") 1818 ax.plot(bits, [r["learned"] for r in rows], "o-", color=BLUE, label="learned codebook (k-means)") 1819 ax.plot([3 * s for s in range(1, 5)], stage_err, "s--", color=GREEN, label="residual: 1 to 4 stages of 8 entries") 1820 ax.axhline(0.09, color=MUTED, ls=":") 1821 ax.text(0.1, 0.078, "clean pattern, noise dropped (0.3² = 0.09)", color="#4b5563", zorder=3, bbox=dict(facecolor="white", edgecolor="none", pad=1)) 1822 ax.set_xlabel("bits per patch (log₂ of codebook size, summed over stages)") 1823 ax.set_ylabel("mean squared error per pixel") 1824 ax.set_title("A learned codebook, and a second one for the leftovers") 1825 ax.set_yscale("log") 1826 ax.legend(frameon=False) 1827 figs["codebook"] = fig 1828 1829 # --- 7. How fast each modality spends a context window ------------------------ 1830 durations = np.logspace(0, np.log10(7200), 60) 1831 fig, ax = plt.subplots(figsize=(7, 4)) 1832 colors = [MUTED, GREEN, BLUE, AMBER, RED] 1833 for (label, tps), color in zip(TOKENS_PER_SECOND.items(), colors): 1834 ax.loglog(durations, durations * tps, color=color, label=label) 1835 for budget, name in ((128_000, "128k-token window"), (1_000_000, "1M-token window")): 1836 ax.axhline(budget, color="#4b5563", ls="--", lw=1) 1837 ax.text(1.2, budget * 1.25, name, color="#4b5563") 1838 ax.set_xlabel("length of the recording (seconds; 60 = a minute, 3600 = an hour)") 1839 ax.set_ylabel("tokens") 1840 ax.set_title("How fast each kind of input fills a context window") 1841 ax.legend(frameon=False, fontsize=8, loc="lower right") 1842 figs["token_budget"] = fig 1843 1844 return figs 1845 1846 1847# --------------------------------------------------------------------------- 1848# 7. Narrated walkthrough 1849# --------------------------------------------------------------------------- 1850 1851 1852def demo() -> None: 1853 banner("1. The one idea: every modality becomes a row of vectors") 1854 worked = worked_example_patches() 1855 say("A 4×4 picture with brightnesses 0 to 15, cut into four 2×2 patches and flattened:") 1856 matrix("patches (one row per patch)", worked["patches"]) 1857 say("Multiply by W_E (column 1 adds the top row of a patch, column 2 the bottom row), then add (row, column) positions:") 1858 table(["patch", "pixels", "x·W_E", "+ position", "token"], 1859 [(name, p.tolist(), q.tolist(), pos.tolist(), t.tolist()) for name, p, q, pos, t in 1860 zip(["top left", "top right", "bottom left", "bottom right"], worked["patches"], worked["projected"], WORKED_POSITIONS, worked["tokens"])]) 1861 takeaway("A picture is now four tokens of two numbers each: exactly the kind of input a transformer reads.") 1862 1863 banner("2. How many tokens is an image?") 1864 table(["image", "patch", "merge", "tokens"], 1865 [(f"{s}×{s}", p, m, count_image_tokens(s, s, p, m)) for s, p, m in ((224, 16, 1), (224, 14, 1), (336, 14, 1), (1008, 14, 2))]) 1866 say("Tokens grow with the square of the side: twice the resolution, four times the tokens.") 1867 encoder = VisionEncoder(image_size=32, patch=8, channels=1, d_model=24, n_layers=2, n_heads=4) 1868 say(f"A from-scratch ViT reads the 32×32 toy picture and returns {encoder(toy_picture()).shape}: 16 patches, 24 numbers each.") 1869 1870 banner("3. Plugging vision into a language model") 1871 model = build_toy_vlm() 1872 image = toy_images(1)[0][3] 1873 ids = np.array([TEXT_VOCAB.index(w) for w in ["what", "is", "this", "<image>"]]) 1874 sequence, is_image = model.splice(ids, image) 1875 say(f"Prompt ids {ids.tolist()} ('what is this <image>'). The image placeholder expands into " 1876 f"{model.vision.n_patches} projected vectors, so the language model reads {len(sequence)} rows of width {sequence.shape[1]}.") 1877 say(f"Which rows are image tokens: {is_image.astype(int).tolist()}. Logits come out as {model(ids, image).shape}: one score per word per position.") 1878 held_out = toy_images(20, seed=99) 1879 before = caption_accuracy(model, *held_out) 1880 history = align_projector(model, *toy_images(20)) 1881 after = caption_accuracy(model, *held_out) 1882 say(f"Stage 1 (alignment): train only the projector so each image names its pattern. Loss {history['loss'][0]:.2f} → " 1883 f"{history['loss'][-1]:.2f}; on 80 new images the right word ranks first {before:.0%} → {after:.0%} of the time.") 1884 takeaway("The vision encoder and the language model never changed: a small translator between them did all the learning.") 1885 1886 banner("4. Audio: a waveform becomes a spectrogram becomes tokens") 1887 wave = [1, 0, -1, 0, 1, 0, -1, 0] 1888 say(f"8 samples of a wave that cycles twice: {wave}. How much of each frequency: {np.round(dft_magnitudes(wave), 3).tolist()}.") 1889 x = demo_signal() 1890 spec = stft(x, 256, 64) 1891 say(f"One second of a rising whistle over a 1000 Hz hum at {SAMPLE_RATE} samples a second is {len(x)} numbers. " 1892 f"Windows of 256 every 64 samples give a spectrogram of {spec.shape} (frames, frequencies).") 1893 peaks = spec.argmax(axis=1) * SAMPLE_RATE / 256 1894 say(f"Loudest frequency in the first, middle and last frames: {peaks[0]:.0f}, {peaks[len(peaks) // 2]:.0f}, {peaks[-1]:.0f} Hz: the whistle climbing.") 1895 table(["hertz", "mel"], [(f, float(hz_to_mel(f))) for f in (100, 700, 1000, 4000, 8000)], floatfmt=".1f") 1896 say(f"A speech encoder with 10 ms frames and one stride-2 layer sees {audio_tokens(1)} tokens a second, {audio_tokens(30)} for 30 seconds.") 1897 1898 banner("5. Discrete tokens: snapping vectors to a codebook") 1899 codebook = np.array([[0.0, 0.0], [1.0, 0.0], [0.0, 1.0]]) 1900 z = np.array([[0.9, 0.2], [0.1, 0.8], [0.1, -0.1]]) 1901 say(f"Codebook {codebook.tolist()}. Vectors {z.tolist()} snap to ids {quantize(z, codebook).tolist()}.") 1902 table(["codebook size", "bits", "learned error", "random error"], [(r["k"], r["bits"], r["learned"], r["random"]) for r in codebook_sweep()], floatfmt=".3f") 1903 takeaway("Once a patch or a slice of sound is a codebook number, a language model can predict it exactly as it predicts a word.") 1904 1905 banner("6. Video, and what it costs") 1906 table(["clip", "sampled fps", "tubelet", "tokens"], 1907 [("10 s", fps, t, video_tokens(10, fps, 256, t)) for fps, t in ((30, 1), (2, 2), (1, 1))]) 1908 say(f"Frames kept from 300 frames at 30 fps, sampled at 1 fps: {sample_frames(300, 30, 1).tolist()}.") 1909 table(["input", "tokens per second", "minutes in 128k tokens"], 1910 [(k, v, seconds_that_fit(128_000, v) / 60) for k, v in TOKENS_PER_SECOND.items()], floatfmt=".1f") 1911 takeaway("Text is by far the densest way to hold information in a context window; pictures, sound and video pay per pixel and per second.") 1912 1913 1914if __name__ == "__main__": 1915 demo()
1215def image_to_patches(image: np.ndarray, patch: int) -> np.ndarray:
1216    """Cut an (H, W) or (H, W, C) image into square patches, one flattened row each.
1217
1218    Returns (number of patches, patch·patch·C), row by row from the top left.
1219    The cutting itself is `primer.ml.cnn_rnn.patchify`; this adds the check
1220    that the patch size divides the image, because a ragged edge would give
1221    a last patch with pixels missing.
1222    """
1223    image = np.asarray(image)
1224    if image.ndim == 2:
1225        image = image[:, :, None]  # grayscale: one colour channel
1226    h, w, _ = image.shape
1227    if h % patch or w % patch:
1228        raise ValueError(f"a {patch}-pixel patch does not divide a {h}×{w} image; resize or pad it first")
1229    return patchify(image, patch)
Cut an (H, W) or (H, W, C) image into square patches, one flattened row each.
Returns (number of patches, patch·patch·C), row by row from the top left.
The cutting itself is primer.ml.cnn_rnn.patchify; this adds the check
that the patch size divides the image, because a ragged edge would give
a last patch with pixels missing.
1232def count_image_tokens(height: int, width: int, patch: int, merge: int = 1) -> int:
1233    """Tokens for one image: (H/P)·(W/P) patches, divided by merge² if neighbours are pooled.
1234
1235    Many vision-language models merge each merge×merge block of neighbouring
1236    patch vectors into one token before the language model sees them, which
1237    cuts the count by merge².
1238    """
1239    if height % patch or width % patch:
1240        raise ValueError("resize the image to a multiple of the patch size first")
1241    grid_h, grid_w = height // patch, width // patch
1242    return (grid_h * grid_w) // (merge * merge)
Tokens for one image: (H/P)·(W/P) patches, divided by merge² if neighbours are pooled.
Many vision-language models merge each merge×merge block of neighbouring patch vectors into one token before the language model sees them, which cuts the count by merge².
1253def worked_example_patches() -> dict[str, np.ndarray]:
1254    """The 4×4 image cut into four 2×2 patches, projected, then given positions.
1255
1256    | patch        | pixels       | x·W_E    | + position | token    |
1257    |--------------|--------------|----------|------------|----------|
1258    | top left     | 0, 1, 4, 5   | (1, 9)   | (0, 0)     | (1, 9)   |
1259    | top right    | 2, 3, 6, 7   | (5, 13)  | (0, 1)     | (5, 14)  |
1260    | bottom left  | 8, 9, 12, 13 | (17, 25) | (1, 0)     | (18, 25) |
1261    | bottom right | 10, 11, 14, 15 | (21, 29) | (1, 1)   | (22, 30) |
1262    """
1263    patches = image_to_patches(WORKED_IMAGE, patch=2)  # (4, 4): 4 patches of 4 pixels
1264    projected = patches @ WORKED_W_E  # (4, 2): each patch squeezed to 2 numbers
1265    return dict(patches=patches, projected=projected, tokens=projected + WORKED_POSITIONS)
The 4×4 image cut into four 2×2 patches, projected, then given positions.
| patch | pixels | x·W_E | + position | token |
|---|---|---|---|---|
| top left | 0, 1, 4, 5 | (1, 9) | (0, 0) | (1, 9) |
| top right | 2, 3, 6, 7 | (5, 13) | (0, 1) | (5, 14) |
| bottom left | 8, 9, 12, 13 | (17, 25) | (1, 0) | (18, 25) |
| bottom right | 10, 11, 14, 15 | (21, 29) | (1, 1) | (22, 30) |
1268class VisionEncoder:
1269    """A Vision Transformer, forward pass only: patches -> vectors -> encoder blocks.
1270
1271    ```text
1272    image (H, W, C) -> patches (N, P·P·C) -> ·W_E + b_E (N, d) -> + positions (N, d)
1273                    -> n_layers × TransformerBlock(causal=False) -> LayerNorm (N, d)
1274    ```
1275
1276    The blocks are `primer.ml.transformer.TransformerBlock` with the causal
1277    mask switched off: a picture has no "future", so every patch may attend
1278    to every other. Weights are random; this shows the machinery.
1279    """
1280
1281    def __init__(self, image_size: int, patch: int, channels: int, d_model: int, n_layers: int, n_heads: int, seed: int = 0):
1282        rng = np.random.default_rng(seed)
1283        self.patch = patch
1284        self.n_patches = count_image_tokens(image_size, image_size, patch)
1285        patch_dim = patch * patch * channels
1286        # Scaled init keeps each token's numbers near unit size whatever the patch size.
1287        self.W_E = rng.normal(0, 1 / np.sqrt(patch_dim), (patch_dim, d_model))
1288        self.b_E = np.zeros(d_model)
1289        # Learned positions, one vector per patch slot, as ViT does (std 0.02 as in GPT-2).
1290        self.pos = rng.normal(0, 0.02, (self.n_patches, d_model))
1291        self.blocks = [TransformerBlock(d_model, n_heads, causal=False, seed=seed + 10 * i + 1) for i in range(n_layers)]
1292
1293    def embed(self, image: np.ndarray) -> np.ndarray:
1294        """(N, d): each patch projected to model width, plus its position vector."""
1295        return image_to_patches(image, self.patch) @ self.W_E + self.b_E + self.pos
1296
1297    def __call__(self, image: np.ndarray) -> np.ndarray:
1298        """(N, d): one context-aware vector per patch, the image's tokens."""
1299        x = self.embed(image)
1300        for block in self.blocks:
1301            x = block(x)
1302        return layer_norm(x)
A Vision Transformer, forward pass only: patches -> vectors -> encoder blocks.
image (H, W, C) -> patches (N, P·P·C) -> ·W_E + b_E (N, d) -> + positions (N, d)
                -> n_layers × TransformerBlock(causal=False) -> LayerNorm (N, d)
The blocks are primer.ml.transformer.TransformerBlock with the causal
mask switched off: a picture has no "future", so every patch may attend
to every other. Weights are random; this shows the machinery.
1281    def __init__(self, image_size: int, patch: int, channels: int, d_model: int, n_layers: int, n_heads: int, seed: int = 0):
1282        rng = np.random.default_rng(seed)
1283        self.patch = patch
1284        self.n_patches = count_image_tokens(image_size, image_size, patch)
1285        patch_dim = patch * patch * channels
1286        # Scaled init keeps each token's numbers near unit size whatever the patch size.
1287        self.W_E = rng.normal(0, 1 / np.sqrt(patch_dim), (patch_dim, d_model))
1288        self.b_E = np.zeros(d_model)
1289        # Learned positions, one vector per patch slot, as ViT does (std 0.02 as in GPT-2).
1290        self.pos = rng.normal(0, 0.02, (self.n_patches, d_model))
1291        self.blocks = [TransformerBlock(d_model, n_heads, causal=False, seed=seed + 10 * i + 1) for i in range(n_layers)]
1310class Projector:
1311    """Maps vision vectors into the language model's embedding space.
1312
1313    `hidden=None` is a single linear layer, v·W + b. With `hidden` set it is
1314    a two-layer MLP, GELU(v·W1 + b1)·W2 + b2: the same shape as a
1315    transformer's feed-forward network (`primer.ml.transformer.FeedForward`),
1316    with a different width on each side.
1317    """
1318
1319    def __init__(self, d_in: int, d_out: int, hidden: int | None = None, seed: int = 0):
1320        rng = np.random.default_rng(seed)
1321        self.hidden = hidden
1322        if hidden is None:
1323            self.W = rng.normal(0, 1 / np.sqrt(d_in), (d_in, d_out))
1324            self.b = np.zeros(d_out)
1325        else:
1326            self.W1 = rng.normal(0, 1 / np.sqrt(d_in), (d_in, hidden))
1327            self.b1 = np.zeros(hidden)
1328            self.W2 = rng.normal(0, 1 / np.sqrt(hidden), (hidden, d_out))
1329            self.b2 = np.zeros(d_out)
1330
1331    def __call__(self, v: np.ndarray) -> np.ndarray:
1332        # (N, d_in) -> (N, d_out): each image token translated on its own.
1333        if self.hidden is None:
1334            return v @ self.W + self.b
1335        return gelu(v @ self.W1 + self.b1) @ self.W2 + self.b2
Maps vision vectors into the language model's embedding space.
hidden=None is a single linear layer, v·W + b. With hidden set it is
a two-layer MLP, GELU(v·W1 + b1)·W2 + b2: the same shape as a
transformer's feed-forward network (primer.ml.transformer.FeedForward),
with a different width on each side.
1319    def __init__(self, d_in: int, d_out: int, hidden: int | None = None, seed: int = 0):
1320        rng = np.random.default_rng(seed)
1321        self.hidden = hidden
1322        if hidden is None:
1323            self.W = rng.normal(0, 1 / np.sqrt(d_in), (d_in, d_out))
1324            self.b = np.zeros(d_out)
1325        else:
1326            self.W1 = rng.normal(0, 1 / np.sqrt(d_in), (d_in, hidden))
1327            self.b1 = np.zeros(hidden)
1328            self.W2 = rng.normal(0, 1 / np.sqrt(hidden), (hidden, d_out))
1329            self.b2 = np.zeros(d_out)
1343def worked_example_projection() -> np.ndarray:
1344    """(1, 2)·W_P = (1·1 + 2·0, 1·0 + 2·1, 1·1 + 2·1) = (1, 2, 3)."""
1345    return WORKED_V @ WORKED_W_P
(1, 2)·W_P = (1·1 + 2·0, 1·0 + 2·1, 1·1 + 2·1) = (1, 2, 3).
1355class VisionLanguageModel:
1356    """Vision encoder -> projector -> image tokens spliced into a decoder language model.
1357
1358    The language model is `primer.ml.transformer.TinyGPT`. Instead of looking
1359    up every position in its token table, the image placeholder is replaced
1360    by the projected image tokens; everything after that is TinyGPT's own
1361    forward pass.
1362    """
1363
1364    def __init__(self, vision: VisionEncoder, projector: Projector, lm: TinyGPT):
1365        self.vision, self.projector, self.lm = vision, projector, lm
1366
1367    def splice(self, ids: np.ndarray, image: np.ndarray) -> tuple[np.ndarray, np.ndarray]:
1368        """(L, d_lm) input vectors with the image tokens where `IMAGE` was, and an is-image flag per row."""
1369        image_tokens = self.projector(self.vision(image))  # (N, d_lm)
1370        rows, flags = [], []
1371        for token_id in ids:
1372            if token_id == IMAGE:
1373                rows.append(image_tokens)
1374                flags += [True] * len(image_tokens)
1375            else:
1376                rows.append(self.lm.wte[token_id][None, :])  # a text token: its row of the table
1377                flags.append(False)
1378        return np.concatenate(rows), np.array(flags)
1379
1380    def __call__(self, ids: np.ndarray, image: np.ndarray) -> np.ndarray:
1381        """(L, vocab) logits: row i scores every possible next token after position i."""
1382        x, _ = self.splice(ids, image)
1383        x = x + self.lm.wpe[: len(x)]  # positions count image tokens too
1384        for block in self.lm.blocks:
1385            x = block(x)
1386        return layer_norm(x, self.lm.lnf_g, self.lm.lnf_b) @ self.lm.wte.T
Vision encoder -> projector -> image tokens spliced into a decoder language model.
The language model is primer.ml.transformer.TinyGPT. Instead of looking
up every position in its token table, the image placeholder is replaced
by the projected image tokens; everything after that is TinyGPT's own
forward pass.
1367    def splice(self, ids: np.ndarray, image: np.ndarray) -> tuple[np.ndarray, np.ndarray]:
1368        """(L, d_lm) input vectors with the image tokens where `IMAGE` was, and an is-image flag per row."""
1369        image_tokens = self.projector(self.vision(image))  # (N, d_lm)
1370        rows, flags = [], []
1371        for token_id in ids:
1372            if token_id == IMAGE:
1373                rows.append(image_tokens)
1374                flags += [True] * len(image_tokens)
1375            else:
1376                rows.append(self.lm.wte[token_id][None, :])  # a text token: its row of the table
1377                flags.append(False)
1378        return np.concatenate(rows), np.array(flags)
(L, d_lm) input vectors with the image tokens where IMAGE was, and an is-image flag per row.
1389def build_toy_vlm(seed: int = 0) -> VisionLanguageModel:
1390    """An 8×8 grayscale ViT (4 patches, width 16), a linear projector, and a width-24 TinyGPT."""
1391    vision = VisionEncoder(image_size=8, patch=4, channels=1, d_model=16, n_layers=2, n_heads=2, seed=seed)
1392    projector = Projector(16, 24, seed=seed + 1)
1393    lm = TinyGPT(vocab_size=len(TEXT_VOCAB), d_model=24, n_layers=2, n_heads=2, max_len=32, seed=seed + 2)
1394    return VisionLanguageModel(vision, projector, lm)
An 8×8 grayscale ViT (4 patches, width 16), a linear projector, and a width-24 TinyGPT.
1397def toy_images(n_per_class: int, size: int = 8, seed: int = 0) -> tuple[np.ndarray, np.ndarray]:
1398    """Four kinds of 8×8 grayscale picture (horizontal, vertical, diagonal, checkered), with noise.
1399
1400    Each image gets its own contrast, brightness and pixel noise, so no two
1401    are identical. Returns (images (4n, size, size), labels (4n,)).
1402    """
1403    rng = np.random.default_rng(seed)
1404    r, c = np.mgrid[0:size, 0:size]
1405    # 2-pixel-wide bands, so every 4×4 patch holds a full light-and-dark cycle of its pattern.
1406    patterns = [(r // 2) % 2, (c // 2) % 2, ((r + c) // 2) % 2, (r // 2 + c // 2) % 2]
1407    images, labels = [], []
1408    for label, pattern in enumerate(patterns):
1409        for _ in range(n_per_class):
1410            contrast, brightness = rng.uniform(0.6, 1.4), rng.uniform(-0.3, 0.3)
1411            images.append(contrast * pattern + brightness + 0.3 * rng.standard_normal((size, size)))
1412            labels.append(label)
1413    return np.array(images, dtype=float), np.array(labels)
Four kinds of 8×8 grayscale picture (horizontal, vertical, diagonal, checkered), with noise.
Each image gets its own contrast, brightness and pixel noise, so no two are identical. Returns (images (4n, size, size), labels (4n,)).
1421def caption_accuracy(model: VisionLanguageModel, images: np.ndarray, labels: np.ndarray) -> float:
1422    """Share of images whose projected tokens score their own class word highest in the whole vocabulary."""
1423    h = model.projector(_pooled_features(model, images))  # (B, d_lm)
1424    predicted = (h @ model.lm.wte.T).argmax(axis=1)  # scored against every word, as the output layer does
1425    return float(np.mean(predicted == CLASS_WORD_IDS[labels]))
Share of images whose projected tokens score their own class word highest in the whole vocabulary.
1428def align_projector(model: VisionLanguageModel, images: np.ndarray, labels: np.ndarray, steps: int = 300, lr: float = 2.0) -> dict[str, list[float]]:
1429    """Stage 1 of training: fit only the (linear) projector so each image says its caption word.
1430
1431    The loss is cross-entropy on the caption word, scored by the language
1432    model's own output layer (its tied token table). The vision encoder and
1433    the language model are frozen: only `projector.W` and `projector.b` move.
1434    A real model sends the image tokens through every language-model layer
1435    and back-propagates through them; this toy scores the pooled image
1436    vector against the token table directly, the last step of that same path.
1437    """
1438    v = _pooled_features(model, images)  # (B, d_vision), fixed while training
1439    wte = model.lm.wte  # (vocab, d_lm), frozen
1440    target = CLASS_WORD_IDS[labels]
1441    history: dict[str, list[float]] = {"loss": [], "accuracy": []}
1442    for _ in range(steps):
1443        h = model.projector(v)  # (B, d_lm)
1444        p = softmax(h @ wte.T)  # (B, vocab)
1445        history["loss"].append(float(-np.mean(np.log(p[np.arange(len(v)), target]))))
1446        history["accuracy"].append(float(np.mean(p.argmax(axis=1) == target)))
1447        # Gradient of mean cross-entropy: (p - one_hot) flows back through the frozen table.
1448        d_logits = p.copy()
1449        d_logits[np.arange(len(v)), target] -= 1
1450        d_h = d_logits @ wte / len(v)  # (B, d_lm)
1451        model.projector.W -= lr * v.T @ d_h
1452        model.projector.b -= lr * d_h.sum(axis=0)
1453    return history
Stage 1 of training: fit only the (linear) projector so each image says its caption word.
The loss is cross-entropy on the caption word, scored by the language
model's own output layer (its tied token table). The vision encoder and
the language model are frozen: only projector.W and projector.b move.
A real model sends the image tokens through every language-model layer
and back-propagates through them; this toy scores the pooled image
vector against the token table directly, the last step of that same path.
1461def tone(freq: float, seconds: float, sample_rate: int) -> np.ndarray:
1462    """A pure sine wave: the waveform of a single steady pitch."""
1463    t = np.arange(int(seconds * sample_rate)) / sample_rate
1464    return np.sin(2 * np.pi * freq * t)
A pure sine wave: the waveform of a single steady pitch.
1467def chirp(f_start: float, f_end: float, seconds: float, sample_rate: int) -> np.ndarray:
1468    """A sine whose pitch rises steadily from f_start to f_end, like a whistle sliding up."""
1469    t = np.arange(int(seconds * sample_rate)) / sample_rate
1470    # Phase is the running total of frequency: f(t) = f_start + (f_end - f_start)·t/T.
1471    return np.sin(2 * np.pi * (f_start * t + (f_end - f_start) * t**2 / (2 * seconds)))
A sine whose pitch rises steadily from f_start to f_end, like a whistle sliding up.
1482def dft_magnitudes(x) -> np.ndarray:
1483    """|X_k| for k = 0..n-1: how much of the wave that cycles k times the signal contains.
1484
1485    Written as the definition, with no fast Fourier transform: correlate the
1486    signal with a cosine and a sine of each frequency, and take the length
1487    of the pair.
1488    """
1489    x = np.asarray(x, dtype=float)
1490    cos, sin = _dft_basis(len(x), len(x))
1491    return np.sqrt((x @ cos) ** 2 + (x @ sin) ** 2)
|X_k| for k = 0..n-1: how much of the wave that cycles k times the signal contains.
Written as the definition, with no fast Fourier transform: correlate the signal with a cosine and a sine of each frequency, and take the length of the pair.
1494def frame_count(n_samples: int, window: int, hop: int) -> int:
1495    """Whole windows that fit: 1 + ⌊(L - N) / H⌋."""
1496    return 1 + (n_samples - window) // hop
Whole windows that fit: 1 + ⌊(L - N) / H⌋.
1499def hann(n: int) -> np.ndarray:
1500    """A window that rises from 0 to 1 and back, so each slice fades in and out instead of starting with a click."""
1501    return 0.5 - 0.5 * np.cos(2 * np.pi * np.arange(n) / (n - 1))
A window that rises from 0 to 1 and back, so each slice fades in and out instead of starting with a click.
1504def stft(x: np.ndarray, window: int, hop: int) -> np.ndarray:
1505    """Short-time Fourier transform magnitudes: (frames, window//2 + 1).
1506
1507    Slide a window of `window` samples along the signal in steps of `hop`,
1508    fade each slice with a Hann window, and measure every frequency in it.
1509    Only bins 0..window/2 are kept: for a real signal the rest mirror them.
1510    """
1511    t = frame_count(len(x), window, hop)
1512    starts = np.arange(t)[:, None] * hop
1513    frames = x[starts + np.arange(window)[None, :]] * hann(window)  # (T, window)
1514    cos, sin = _dft_basis(window, window // 2 + 1)
1515    return np.sqrt((frames @ cos) ** 2 + (frames @ sin) ** 2)
Short-time Fourier transform magnitudes: (frames, window//2 + 1).
Slide a window of window samples along the signal in steps of hop,
fade each slice with a Hann window, and measure every frequency in it.
Only bins 0..window/2 are kept: for a real signal the rest mirror them.
1518def hz_to_mel(f):
1519    """mel(f) = 2595·log10(1 + f/700): roughly even steps below 700 Hz, ratios above."""
1520    return 2595 * np.log10(1 + np.asarray(f, dtype=float) / 700)
mel(f) = 2595·log10(1 + f/700): roughly even steps below 700 Hz, ratios above.
1523def mel_to_hz(m):
1524    """The inverse of `hz_to_mel`."""
1525    return 700 * (10 ** (np.asarray(m, dtype=float) / 2595) - 1)
The inverse of hz_to_mel.
1528def mel_filterbank(n_mels: int, n_fft: int, sample_rate: int) -> np.ndarray:
1529    """(n_mels, n_fft//2 + 1) triangular filters, evenly spaced in mel, so wider in hertz as pitch rises.
1530
1531    Filter m rises from 0 at mel point m to 1 at point m+1 and falls back to
1532    0 at point m+2. Multiplying a spectrogram by this matrix's transpose
1533    adds up each band's energy: many fine bins become a few bands.
1534    """
1535    edges = mel_to_hz(np.linspace(0, hz_to_mel(sample_rate / 2), n_mels + 2))  # n_mels + 2 edges in Hz
1536    freqs = np.arange(n_fft // 2 + 1) * sample_rate / n_fft  # the frequency of each spectrogram bin
1537    lo, centre, hi = edges[:-2, None], edges[1:-1, None], edges[2:, None]
1538    rising = (freqs - lo) / (centre - lo)
1539    falling = (hi - freqs) / (hi - centre)
1540    return np.maximum(0, np.minimum(rising, falling))
(n_mels, n_fft//2 + 1) triangular filters, evenly spaced in mel, so wider in hertz as pitch rises.
Filter m rises from 0 at mel point m to 1 at point m+1 and falls back to 0 at point m+2. Multiplying a spectrogram by this matrix's transpose adds up each band's energy: many fine bins become a few bands.
1543def log_mel_spectrogram(x: np.ndarray, sample_rate: int, window: int, hop: int, n_mels: int) -> np.ndarray:
1544    """(frames, n_mels): power per mel band, on a log scale because loudness is heard by ratio too."""
1545    power = stft(x, window, hop) ** 2
1546    return np.log10(power @ mel_filterbank(n_mels, window, sample_rate).T + 1e-10)
(frames, n_mels): power per mel band, on a log scale because loudness is heard by ratio too.
1549def audio_tokens(seconds: float, hop_ms: float = 10, downsample: int = 2) -> int:
1550    """Encoder positions for a clip: one spectrogram frame per hop, halved by a stride-2 convolution."""
1551    return int(round(seconds * 1000 / hop_ms)) // downsample
Encoder positions for a clip: one spectrogram frame per hop, halved by a stride-2 convolution.
1559def quantize(Z: np.ndarray, codebook: np.ndarray) -> np.ndarray:
1560    """(n,) ids: for each row of Z, the number of the nearest codebook entry."""
1561    # ‖z - c‖² for every pair, (n, K), without a Python loop.
1562    d2 = (Z**2).sum(axis=1)[:, None] - 2 * Z @ codebook.T + (codebook**2).sum(axis=1)[None, :]
1563    return d2.argmin(axis=1)
(n,) ids: for each row of Z, the number of the nearest codebook entry.
1566def dequantize(ids: np.ndarray, codebook: np.ndarray) -> np.ndarray:
1567    """(n, d): look each id up in the codebook. What a decoder receives back."""
1568    return codebook[ids]
(n, d): look each id up in the codebook. What a decoder receives back.
1571def quantization_error(Z: np.ndarray, codebook: np.ndarray) -> float:
1572    """Mean squared difference between each vector and the codebook entry it snaps to."""
1573    return float(np.mean((Z - dequantize(quantize(Z, codebook), codebook)) ** 2))
Mean squared difference between each vector and the codebook entry it snaps to.
1576def kmeans_codebook(Z: np.ndarray, k: int, iters: int = 20, seed: int = 0) -> np.ndarray:
1577    """Learn k codebook entries with k-means: snap every vector, move each entry to its vectors' mean.
1578
1579    VQ-VAE learns its codebook inside a network, but the update it converges
1580    to is this one (see `primer.ml.embeddings.clustering` for k-means).
1581    """
1582    rng = np.random.default_rng(seed)
1583    codebook = Z[rng.choice(len(Z), size=k, replace=False)].copy()  # start from k real vectors
1584    for _ in range(iters):
1585        ids = quantize(Z, codebook)
1586        for j in range(k):
1587            members = Z[ids == j]
1588            if len(members):  # an entry nobody chose keeps its place rather than becoming NaN
1589                codebook[j] = members.mean(axis=0)
1590    return codebook
Learn k codebook entries with k-means: snap every vector, move each entry to its vectors' mean.
VQ-VAE learns its codebook inside a network, but the update it converges
to is this one (see primer.ml.embeddings.clustering for k-means).
1593def learn_residual_codebooks(Z: np.ndarray, k: int, stages: int, seed: int = 0) -> list[np.ndarray]:
1594    """Residual vector quantization: each new codebook is learned on what the previous ones missed."""
1595    books, residual = [], Z.copy()
1596    for s in range(stages):
1597        book = kmeans_codebook(residual, k, seed=seed + s)
1598        residual = residual - dequantize(quantize(residual, book), book)
1599        books.append(book)
1600    return books
Residual vector quantization: each new codebook is learned on what the previous ones missed.
1603def residual_quantize(Z: np.ndarray, codebooks: list[np.ndarray]) -> tuple[np.ndarray, np.ndarray]:
1604    """(ids (stages, n), reconstruction (n, d)): one id per stage per vector; the sum of their entries rebuilds it."""
1605    ids, recon, residual = [], np.zeros_like(Z, dtype=float), Z.astype(float)
1606    for book in codebooks:
1607        stage_ids = quantize(residual, book)
1608        recon = recon + book[stage_ids]
1609        residual = residual - book[stage_ids]
1610        ids.append(stage_ids)
1611    return np.array(ids), recon
(ids (stages, n), reconstruction (n, d)): one id per stage per vector; the sum of their entries rebuilds it.
1619def video_tokens(seconds: float, sample_fps: float, tokens_per_frame: int, tubelet: int = 1) -> int:
1620    """(seconds · sampled frames per second / frames per tubelet) · tokens per frame."""
1621    frames = int(round(seconds * sample_fps))
1622    return (frames // tubelet) * tokens_per_frame
(seconds · sampled frames per second / frames per tubelet) · tokens per frame.
1625def sample_frames(n_frames: int, video_fps: float, target_fps: float) -> np.ndarray:
1626    """Indices of the frames kept when sampling a video at `target_fps`: evenly spaced, starting at 0."""
1627    step = video_fps / target_fps
1628    return np.floor(np.arange(0, n_frames, step)).astype(int)
Indices of the frames kept when sampling a video at target_fps: evenly spaced, starting at 0.
1631def seconds_that_fit(context_tokens: int, tokens_per_second: float) -> float:
1632    """How many seconds of a stream fit in a context window, ignoring the prompt and the answer."""
1633    return context_tokens / tokens_per_second
How many seconds of a stream fit in a context window, ignoring the prompt and the answer.
1653def demo_signal(seconds: float = 1.0) -> np.ndarray:
1654    """A whistle sliding up from 200 Hz to 3000 Hz over a steady, quieter 1000 Hz hum."""
1655    return chirp(200, 3000, seconds, SAMPLE_RATE) + 0.5 * tone(1000, seconds, SAMPLE_RATE)
A whistle sliding up from 200 Hz to 3000 Hz over a steady, quieter 1000 Hz hum.
1658def toy_picture(size: int = 32) -> np.ndarray:
1659    """A 32×32 grayscale scene to cut into patches: a sun above a striped field."""
1660    r, c = np.mgrid[0:size, 0:size]
1661    sky = 0.25 + 0.3 * (r < size // 2)
1662    sun = ((r - 9) ** 2 + (c - 22) ** 2 < 25) * 0.6
1663    field = (r >= size // 2) * (0.3 + 0.4 * ((c // 3) % 2))
1664    return np.clip(sky * (r < size // 2) + sun + field, 0, 1)
A 32×32 grayscale scene to cut into patches: a sun above a striped field.
1667def codebook_sweep(sizes=(1, 2, 4, 8, 16, 32, 64), seed: int = 0) -> list[dict]:
1668    """Quantization error on new toy-image patches, for learned and random codebooks of each size.
1669
1670    The codebook is learned on one set of images and scored on another, so a
1671    large codebook cannot look good by memorising the noise it was fitted to.
1672    """
1673    patches = np.concatenate([image_to_patches(im, 4) for im in toy_images(30)[0]])
1674    new = np.concatenate([image_to_patches(im, 4) for im in toy_images(30, seed=99)[0]])
1675    rng = np.random.default_rng(seed)
1676    lo, hi = patches.min(), patches.max()
1677    rows = []
1678    for k in sizes:
1679        random = rng.uniform(lo, hi, (k, patches.shape[1]))
1680        rows.append(dict(k=k, bits=float(np.log2(k)), learned=quantization_error(new, kmeans_codebook(patches, k, seed=seed)),
1681                         random=quantization_error(new, random)))
1682    return rows
Quantization error on new toy-image patches, for learned and random codebooks of each size.
The codebook is learned on one set of images and scored on another, so a large codebook cannot look good by memorising the noise it was fitted to.
1690def figures() -> dict:
1691    """Plot this lesson's data. matplotlib is imported here, and only here,
1692    so the lesson itself needs nothing beyond NumPy."""
1693    import matplotlib
1694
1695    matplotlib.use("Agg")
1696    import matplotlib.pyplot as plt
1697
1698    BLUE, RED, GREEN, AMBER, PURPLE, MUTED = "#2563eb", "#dc2626", "#059669", "#d97706", "#7c3aed", "#9ca3af"
1699    figs = {}
1700
1701    # --- 1. An image cut into patches, and the token matrix it becomes --------
1702    picture = toy_picture()
1703    patches = image_to_patches(picture, 8)
1704    fig, (a1, a2) = plt.subplots(1, 2, figsize=(9, 3.8), gridspec_kw=dict(width_ratios=[1, 1.6]))
1705    a1.imshow(picture, cmap="gray", vmin=0, vmax=1)
1706    for edge in range(0, 33, 8):
1707        a1.axhline(edge - 0.5, color=AMBER, lw=1.5)
1708        a1.axvline(edge - 0.5, color=AMBER, lw=1.5)
1709    for i in range(16):
1710        a1.text((i % 4) * 8 + 3.5, (i // 4) * 8 + 3.5, str(i), color="white", ha="center", va="center", fontweight="bold",
1711                bbox=dict(boxstyle="round,pad=0.15", fc="#1f2937", ec="none", alpha=0.75))
1712    a1.set_xticks([])
1713    a1.set_yticks([])
1714    a1.grid(False)
1715    a1.set_title("32×32 image, 8-pixel patches")
1716    a2.imshow(patches, cmap="gray", vmin=0, vmax=1, aspect="auto")
1717    a2.set_yticks(range(16))
1718    a2.set_ylabel("token (patch number)")
1719    a2.set_xlabel("the patch's 64 pixels, read row by row")
1720    a2.grid(False)
1721    a2.set_title("…becomes 16 tokens of 64 numbers")
1722    fig.tight_layout()
1723    figs["patches"] = fig
1724
1725    # --- 2. Tokens per image as resolution grows --------------------------------
1726    sides = np.arange(112, 1345, 112)
1727    fig, ax = plt.subplots(figsize=(6.4, 3.6))
1728    for patch, merge, color, label in ((14, 1, RED, "14-pixel patches"), (16, 1, BLUE, "16-pixel patches"),
1729                                       (14, 2, GREEN, "14-pixel patches, 2×2 merged")):
1730        ax.plot(sides, [count_image_tokens(s, s, patch, merge) for s in sides], "o-", color=color, label=label, ms=4)
1731    ax.annotate("336 px → 576 tokens", xy=(336, 576), xytext=(130, 5200), arrowprops=dict(arrowstyle="->", color="#4b5563"), zorder=3, bbox=dict(facecolor="white", edgecolor="none", pad=1))
1732    ax.set_xlabel("image side length (pixels)")
1733    ax.set_ylabel("tokens per image")
1734    ax.set_title("Double the side, quadruple the tokens")
1735    ax.legend(frameon=False)
1736    figs["image_tokens"] = fig
1737
1738    # --- 3. Stage-1 alignment: training only the projector ----------------------
1739    model = build_toy_vlm()
1740    images, labels = toy_images(20)
1741    held_out = toy_images(20, seed=99)
1742    before = caption_accuracy(model, *held_out)
1743    history = align_projector(model, images, labels)
1744    after = caption_accuracy(model, *held_out)
1745    fig, (a1, a2) = plt.subplots(1, 2, figsize=(9, 3.3))
1746    a1.plot(history["loss"], color=BLUE)
1747    a1.axhline(np.log(len(TEXT_VOCAB)), color=MUTED, ls="--")
1748    a1.text(len(history["loss"]) * 0.4, np.log(len(TEXT_VOCAB)) - 0.2, "blind guess over 12 words", color="#4b5563")
1749    a1.set_xlabel("training step")
1750    a1.set_ylabel("caption cross-entropy")
1751    a1.set_title("Only the projector learns")
1752    a2.plot(history["accuracy"], color=GREEN, label="training images")
1753    a2.axhline(0.25, color=MUTED, ls="--", label="chance (4 classes)")
1754    a2.scatter([0, len(history["accuracy"]) - 1], [before, after], color=RED, zorder=3, label="new images")
1755    a2.set_ylim(0, 1.05)
1756    a2.set_xlabel("training step")
1757    a2.set_ylabel("right caption word ranked first")
1758    a2.set_title(f"Caption accuracy: {before:.0%} → {after:.0%} on new images")
1759    a2.legend(frameon=False, loc="lower right")
1760    fig.tight_layout()
1761    figs["alignment"] = fig
1762
1763    # --- 4. Waveform, spectrogram, log-mel spectrogram --------------------------
1764    x = demo_signal()
1765    window, hop = 256, 64
1766    spec = stft(x, window, hop)
1767    mel = log_mel_spectrogram(x, SAMPLE_RATE, window, hop, n_mels=40)
1768    seconds = len(x) / SAMPLE_RATE
1769    fig, (a1, a2, a3) = plt.subplots(3, 1, figsize=(7.5, 7.2))
1770    t_ms = np.arange(160) / SAMPLE_RATE * 1000
1771    a1.plot(t_ms, x[:160], color=BLUE, lw=1)
1772    a1.set_xlabel("time (milliseconds): the first 20 ms only")
1773    a1.set_ylabel("pressure")
1774    a1.set_title("Waveform: 8,000 numbers a second, pitch hidden in the wiggles")
1775    a2.imshow(20 * np.log10(spec.T + 1e-6), origin="lower", aspect="auto", cmap="magma",
1776              extent=[0, seconds, 0, SAMPLE_RATE / 2], vmin=-40)
1777    a2.set_ylabel("frequency (Hz)")
1778    a2.set_xlabel("time (seconds)")
1779    a2.set_title(f"Spectrogram: {spec.shape[0]} frames × {spec.shape[1]} frequency bins")
1780    a2.grid(False)
1781    a3.imshow(mel.T, origin="lower", aspect="auto", cmap="magma", extent=[0, seconds, 0, 40], vmin=mel.max() - 5)
1782    a3.set_ylabel("mel band")
1783    a3.set_xlabel("time (seconds)")
1784    a3.set_title(f"Log-mel spectrogram: {mel.shape[0]} frames × {mel.shape[1]} bands")
1785    a3.grid(False)
1786    fig.tight_layout()
1787    figs["spectrogram"] = fig
1788
1789    # --- 5. The mel scale and its filters ----------------------------------------
1790    fig, (a1, a2) = plt.subplots(1, 2, figsize=(9, 3.3))
1791    hz = np.linspace(0, 8000, 400)
1792    a1.plot(hz, hz_to_mel(hz), color=PURPLE)
1793    a1.plot(hz, hz, color=MUTED, ls="--", label="if mel were hertz")
1794    a1.scatter([1000], [1000], color=RED, zorder=3)
1795    a1.annotate("1000 Hz = 1000 mel", xy=(1000, 1000), xytext=(2200, 400), arrowprops=dict(arrowstyle="->", color="#4b5563"))
1796    a1.set_xlabel("frequency (Hz)")
1797    a1.set_ylabel("mel")
1798    a1.set_title("Mel: even steps low, squeezed high")
1799    a1.legend(frameon=False)
1800    bank = mel_filterbank(10, 512, 16_000)
1801    freqs = np.arange(bank.shape[1]) * 16_000 / 512
1802    for row in bank:
1803        a2.plot(freqs, row)
1804    a2.set_xlabel("frequency (Hz)")
1805    a2.set_ylabel("weight")
1806    a2.set_title("10 mel filters: narrow low, wide high")
1807    fig.tight_layout()
1808    figs["mel"] = fig
1809
1810    # --- 6. Codebook size vs reconstruction error, and what it looks like -----------
1811    rows = codebook_sweep()
1812    patches = np.concatenate([image_to_patches(im, 4) for im in toy_images(30)[0]])
1813    books = learn_residual_codebooks(patches, k=8, stages=4)
1814    new = np.concatenate([image_to_patches(im, 4) for im in toy_images(30, seed=99)[0]])
1815    stage_err = [float(np.mean((new - residual_quantize(new, books[:s])[1]) ** 2)) for s in range(1, 5)]
1816    fig, ax = plt.subplots(figsize=(6.4, 3.6))
1817    bits = [r["bits"] for r in rows]
1818    ax.plot(bits, [r["random"] for r in rows], "o-", color=RED, label="random codebook")
1819    ax.plot(bits, [r["learned"] for r in rows], "o-", color=BLUE, label="learned codebook (k-means)")
1820    ax.plot([3 * s for s in range(1, 5)], stage_err, "s--", color=GREEN, label="residual: 1 to 4 stages of 8 entries")
1821    ax.axhline(0.09, color=MUTED, ls=":")
1822    ax.text(0.1, 0.078, "clean pattern, noise dropped (0.3² = 0.09)", color="#4b5563", zorder=3, bbox=dict(facecolor="white", edgecolor="none", pad=1))
1823    ax.set_xlabel("bits per patch  (log₂ of codebook size, summed over stages)")
1824    ax.set_ylabel("mean squared error per pixel")
1825    ax.set_title("A learned codebook, and a second one for the leftovers")
1826    ax.set_yscale("log")
1827    ax.legend(frameon=False)
1828    figs["codebook"] = fig
1829
1830    # --- 7. How fast each modality spends a context window ------------------------
1831    durations = np.logspace(0, np.log10(7200), 60)
1832    fig, ax = plt.subplots(figsize=(7, 4))
1833    colors = [MUTED, GREEN, BLUE, AMBER, RED]
1834    for (label, tps), color in zip(TOKENS_PER_SECOND.items(), colors):
1835        ax.loglog(durations, durations * tps, color=color, label=label)
1836    for budget, name in ((128_000, "128k-token window"), (1_000_000, "1M-token window")):
1837        ax.axhline(budget, color="#4b5563", ls="--", lw=1)
1838        ax.text(1.2, budget * 1.25, name, color="#4b5563")
1839    ax.set_xlabel("length of the recording (seconds; 60 = a minute, 3600 = an hour)")
1840    ax.set_ylabel("tokens")
1841    ax.set_title("How fast each kind of input fills a context window")
1842    ax.legend(frameon=False, fontsize=8, loc="lower right")
1843    figs["token_budget"] = fig
1844
1845    return figs
Plot this lesson's data. matplotlib is imported here, and only here, so the lesson itself needs nothing beyond NumPy.
1853def demo() -> None:
1854    banner("1. The one idea: every modality becomes a row of vectors")
1855    worked = worked_example_patches()
1856    say("A 4×4 picture with brightnesses 0 to 15, cut into four 2×2 patches and flattened:")
1857    matrix("patches (one row per patch)", worked["patches"])
1858    say("Multiply by W_E (column 1 adds the top row of a patch, column 2 the bottom row), then add (row, column) positions:")
1859    table(["patch", "pixels", "x·W_E", "+ position", "token"],
1860          [(name, p.tolist(), q.tolist(), pos.tolist(), t.tolist()) for name, p, q, pos, t in
1861           zip(["top left", "top right", "bottom left", "bottom right"], worked["patches"], worked["projected"], WORKED_POSITIONS, worked["tokens"])])
1862    takeaway("A picture is now four tokens of two numbers each: exactly the kind of input a transformer reads.")
1863
1864    banner("2. How many tokens is an image?")
1865    table(["image", "patch", "merge", "tokens"],
1866          [(f"{s}×{s}", p, m, count_image_tokens(s, s, p, m)) for s, p, m in ((224, 16, 1), (224, 14, 1), (336, 14, 1), (1008, 14, 2))])
1867    say("Tokens grow with the square of the side: twice the resolution, four times the tokens.")
1868    encoder = VisionEncoder(image_size=32, patch=8, channels=1, d_model=24, n_layers=2, n_heads=4)
1869    say(f"A from-scratch ViT reads the 32×32 toy picture and returns {encoder(toy_picture()).shape}: 16 patches, 24 numbers each.")
1870
1871    banner("3. Plugging vision into a language model")
1872    model = build_toy_vlm()
1873    image = toy_images(1)[0][3]
1874    ids = np.array([TEXT_VOCAB.index(w) for w in ["what", "is", "this", "<image>"]])
1875    sequence, is_image = model.splice(ids, image)
1876    say(f"Prompt ids {ids.tolist()} ('what is this <image>'). The image placeholder expands into "
1877        f"{model.vision.n_patches} projected vectors, so the language model reads {len(sequence)} rows of width {sequence.shape[1]}.")
1878    say(f"Which rows are image tokens: {is_image.astype(int).tolist()}. Logits come out as {model(ids, image).shape}: one score per word per position.")
1879    held_out = toy_images(20, seed=99)
1880    before = caption_accuracy(model, *held_out)
1881    history = align_projector(model, *toy_images(20))
1882    after = caption_accuracy(model, *held_out)
1883    say(f"Stage 1 (alignment): train only the projector so each image names its pattern. Loss {history['loss'][0]:.2f} → "
1884        f"{history['loss'][-1]:.2f}; on 80 new images the right word ranks first {before:.0%} → {after:.0%} of the time.")
1885    takeaway("The vision encoder and the language model never changed: a small translator between them did all the learning.")
1886
1887    banner("4. Audio: a waveform becomes a spectrogram becomes tokens")
1888    wave = [1, 0, -1, 0, 1, 0, -1, 0]
1889    say(f"8 samples of a wave that cycles twice: {wave}. How much of each frequency: {np.round(dft_magnitudes(wave), 3).tolist()}.")
1890    x = demo_signal()
1891    spec = stft(x, 256, 64)
1892    say(f"One second of a rising whistle over a 1000 Hz hum at {SAMPLE_RATE} samples a second is {len(x)} numbers. "
1893        f"Windows of 256 every 64 samples give a spectrogram of {spec.shape} (frames, frequencies).")
1894    peaks = spec.argmax(axis=1) * SAMPLE_RATE / 256
1895    say(f"Loudest frequency in the first, middle and last frames: {peaks[0]:.0f}, {peaks[len(peaks) // 2]:.0f}, {peaks[-1]:.0f} Hz: the whistle climbing.")
1896    table(["hertz", "mel"], [(f, float(hz_to_mel(f))) for f in (100, 700, 1000, 4000, 8000)], floatfmt=".1f")
1897    say(f"A speech encoder with 10 ms frames and one stride-2 layer sees {audio_tokens(1)} tokens a second, {audio_tokens(30)} for 30 seconds.")
1898
1899    banner("5. Discrete tokens: snapping vectors to a codebook")
1900    codebook = np.array([[0.0, 0.0], [1.0, 0.0], [0.0, 1.0]])
1901    z = np.array([[0.9, 0.2], [0.1, 0.8], [0.1, -0.1]])
1902    say(f"Codebook {codebook.tolist()}. Vectors {z.tolist()} snap to ids {quantize(z, codebook).tolist()}.")
1903    table(["codebook size", "bits", "learned error", "random error"], [(r["k"], r["bits"], r["learned"], r["random"]) for r in codebook_sweep()], floatfmt=".3f")
1904    takeaway("Once a patch or a slice of sound is a codebook number, a language model can predict it exactly as it predicts a word.")
1905
1906    banner("6. Video, and what it costs")
1907    table(["clip", "sampled fps", "tubelet", "tokens"],
1908          [("10 s", fps, t, video_tokens(10, fps, 256, t)) for fps, t in ((30, 1), (2, 2), (1, 1))])
1909    say(f"Frames kept from 300 frames at 30 fps, sampled at 1 fps: {sample_frames(300, 30, 1).tolist()}.")
1910    table(["input", "tokens per second", "minutes in 128k tokens"],
1911          [(k, v, seconds_that_fit(128_000, v) / 60) for k, v in TOKENS_PER_SECOND.items()], floatfmt=".1f")
1912    takeaway("Text is by far the densest way to hold information in a context window; pictures, sound and video pay per pixel and per second.")