primer.ml.classical
Trees and boosting: the other workhorse
Run: python -m primer.ml.classical
New to the notation? primer.notation explains every symbol used here from
zero. This lesson builds on overfitting from primer.ml.regularization and
uses the small network from primer.ml.neural_net as its sparring partner.
Level 1: The practitioner's guide
In one sentence. On a table of data, where each column means something on its own, an ensemble of decision trees (a random forest or gradient boosting) is usually the model to beat, trains in seconds, needs no feature scaling, and should be the first thing you try before any neural network.
When you need it. Whenever one input is a row: a customer, a payment, a day, a shipment, with columns in their own units (years, dollars, counts, a region code). Loan approval, fraud flags, churn, demand forecasting, ad ranking on tabular features: these are tree problems. The tell is that a domain expert could write some of the rules by hand ("four or more late payments"), because a tree asks exactly that kind of question. This lesson's loan table shows the gap: gradient boosting scores 96.0% and a random forest 95.75% on the raw table, while a small neural network on the same raw columns scores 77.75%, which is the score for always predicting "fine". Rescaling every column lifts the net to 86.25%; hand-engineering the features (log income, one column per region) lifts it to 92.25%, where it ties a single depth-5 tree and still trails both ensembles. You do not need trees when the input is an image, an audio clip or a text, where the meaning lives in the arrangement of thousands of raw values; that is what convolutions and attention learn, and where a pretrained network brings knowledge a tree starts without.
Your options. From the most readable to the most accurate on a table, then the cases where the table is not the whole story:
| Option | What it does | What it guarantees | What it costs | Where it lives |
|---|---|---|---|---|
| One shallow decision tree | Asks yes/no questions about one column at a time, chosen greedily by impurity | A model you can print and read as if/else rules | Accuracy: a depth-5 tree scores 92.25% where the ensembles score 96% | scikit-learn's decision trees; rules a compliance team can audit |
| Random forest | Grows hundreds of deep trees on bootstrap samples with random feature subsets and averages them | Forgiving defaults; more trees never overfit, only cost time; a free out-of-bag error estimate | Not readable; a plateau set by how correlated the trees are | The standard first model on a new table |
| Gradient-boosted trees | Adds small trees in sequence, each fitted to what the model still gets wrong, shrunk by a learning rate | The best accuracy on most tables of thousands to millions of rows | Two knobs to tune (depth, learning rate) and a stopping round chosen on validation data; more rounds do overfit | XGBoost, LightGBM, CatBoost |
| A neural network on the table | Learns its own features from combinations of columns | Smooth trends, extrapolation, end-to-end training with other neural parts | Scaling and feature engineering just to get started; more data to pin down its weights; on this lesson's table it still trails | When the table is huge or mixed with text and images |
| Trees on neural embeddings | A network turns text or images into vectors, which become extra columns for a boosted-tree model | The table's structure and the perceptual data's meaning in one model | Two models to maintain | Common in production ranking and risk systems |
| A neural network on perceptual or sequential data | Convolutions, attention, pretrained weights | The only option that works: a tree cannot read a photo one pixel at a time | Everything the rest of this primer covers | Images, audio, text |
How to choose. The first question is the shape of one input, not what is fashionable.
- A row of a table, thousands to millions of rows: gradient-boosted trees, or a random forest if you want something that works untuned. Make any other model beat them on your validation data.
- The model must be explained to a person, line by line: one shallow tree, and accept the accuracy it costs. A forest's importances are a summary, not an explanation.
- Values outside the training range matter (prices next year, loads at a new scale): trees predict flat beyond the edge of their data; this lesson's four-house model prices a house of size 40 the same as size 4. Use a model with a slope, or add a trend feature.
- Pixels, audio samples, words: a neural network, usually pretrained.
- A table that also carries free text or images: embed those with a network and hand the vectors to the trees.
- Whatever you pick, tune the tree's depth and the boosting learning rate on validation data, and pick the number of boosting rounds by early stopping. Those two knobs are most of the tuning that matters.
What it costs. Training a forest or a boosted model on a table of modest size takes seconds on a laptop, with no GPU, no scaling and no feature engineering: the trees read dollars, years and region codes as they come. A forest grows its trees independently, so it parallelises across cores and machines; boosting is sequential, and a smaller learning rate buys accuracy with rounds. In this lesson's sweep, a learning rate of 1 reaches its best validation error (0.122) at round 4, 0.3 reaches 0.112 at round 9, and 0.1 reaches the lowest, 0.110, at round 31. A forest's accuracy climbs over the first ten or twenty trees and then flattens; past the plateau, every extra tree is only prediction time. The cost that surprises people is on the neural side: the net needed rescaled inputs and hand-made features to reach a score a single tree matched, and Grinsztajn, Oyallon and Varoquaux (2022) found tuned tree ensembles still ahead of tuned deep learning across 45 tabular datasets of about 10,000 rows.
What breaks.
- A tree grown to purity. No depth limit gives 100% on training data and the worst validation score in this lesson's sweep (82%, against 89.5% at depth 2). Limit the depth or the leaf size, or use an ensemble.
- Too many boosting rounds. Every learning rate's validation curve bottoms out and climbs; 200 rounds memorise 80 points. Stop early on validation data.
- A forest that has stopped improving. The floor is the correlation between trees: with correlation 0.3, going from 10 trees to 1,000 moves the variance from 0.37 to 0.30. Lower the correlation (fewer features per split) rather than adding trees.
- Trusting impurity importance. It is measured on training data and favours columns with many distinct values: here a column of pure noise gets 11% of the credit. Permutation importance on held-out data gives it 0.25 points. Correlated columns split the credit between them, and neither kind measures cause.
- Extrapolation. Leaves hold averages of training values, so a tree never predicts outside the range it saw.
- A network on raw columns. Incomes in the tens of thousands swamp every other column and saturate the neurons; the net learns nothing. Scale first, or use trees.
- Diagonal boundaries. A tree cuts parallel to the axes and can only approximate a slope with a staircase; if the rule is a ratio of two columns, give it that ratio as a feature.
In the wild. XGBoost (Chen and Guestrin, 2016), LightGBM and CatBoost
are the boosting libraries behind most winning tabular models, adding a
second-order step per leaf, penalties on tree size, histogram-based split
search and native missing values to the loop this lesson builds.
scikit-learn's decision trees, random forests and permutation importance
are the reference implementations for the rest, with its user guides in
Further reading. The recipe is Breiman's: bagging (1996) and random forests
(2001), which also introduced out-of-bag error and permutation importance;
the boosting loop is Friedman's gradient boosting machine (2001); and the
tree itself is CART (Breiman, Friedman, Olshen and Stone, 1984). Strobl et
al. (2007) documented the bias in impurity importance that this lesson
reproduces with its noise column. In primer.ml.interpretability the
question of what a model relies on returns for neural networks, where no
tree can be printed.
Go deeper. Level 2 grows a tree by hand on eight emails, scores every candidate question with Gini impurity and entropy, sweeps depth to watch overfitting appear, builds a random forest from bootstrap samples and derives the correlation floor on its variance, runs gradient boosting on four houses one round at a time and shows why the residual is a gradient, then stages the loan-table showdown and both kinds of feature importance. If you only needed to know which model to reach for on a table, you are done.
Level 2: How it works, from scratch
Most of this primer is about neural networks, because language models are neural networks. But open the models that decide whether a loan is approved, whether a card payment looks like fraud, which ad to show, or how many umbrellas a shop should stock, and very often you find no neural network at all. You find hundreds of small decision trees, added together.
Those problems share a shape: a table. Each row is a customer, a payment or a day; each column is a fact measured in its own units (age in years, income in dollars, number of late payments, a region code). On tables of modest size, ensembles of trees have stayed the model to beat, and they train in seconds on a laptop. This lesson builds them from scratch, so you can see why they work and, just as usefully, recognise when a neural network is the wrong tool.
The plan: one tree (how it chooses its questions), why a single tree
overfits, how a random forest fixes that by averaging many trees, how
gradient boosting fixes it differently by adding trees one after another,
and finally a head-to-head against a small neural network from
primer.ml.neural_net on a loan table.
A decision tree is a game of twenty questions
Everyday picture. A nurse at an emergency desk runs a flowchart: "Is the patient breathing normally? No: resuscitation room. Yes: is there chest pain? Yes: see a doctor now. No: take a seat." Each question looks at one fact and sends the patient left or right, and the last box gives the answer. A decision tree is exactly that flowchart, except the questions are chosen by the computer from past examples.
Tiny example. Eight emails, each described by two facts: how many links it contains, and whether it comes from a sender you have written to before.
| links | known sender | spam? | |
|---|---|---|---|
| 1 | 0 | yes | no |
| 2 | 1 | yes | no |
| 3 | 4 | yes | no |
| 4 | 0 | no | no |
| 5 | 3 | no | yes |
| 6 | 5 | no | yes |
| 7 | 6 | no | yes |
| 8 | 1 | no | yes |
The tree this lesson grows from those eight rows:
flowchart TD
  Q1{"known sender?"} -->|yes| L1["not spam<br/>(emails 1, 2, 3)"]
  Q1 -->|no| Q2{"more than 0 links?"}
  Q2 -->|no| L2["not spam<br/>(email 4)"]
  Q2 -->|yes| L3["spam<br/>(emails 5, 6, 7, 8)"]
Reading it: start at the top diamond with a new email and answer each question until you land in a box. Diamonds are questions (the tree's internal nodes); boxes are answers (its leaves), and each leaf lists the training emails that ended up there. Two questions sort all eight correctly. Notice what the tree did not ask: "more than 2 links?" looks reasonable, but it was worse. The next two sections show how the tree decides that.
In code: spam_emails returns the table above; DecisionTree grows the tree, and DecisionTree.rules prints it as nested if/else lines.
Measuring a mess: Gini impurity
Everyday picture. You are sorting laundry into piles. A pile of only socks is pure: pull out any two items and they match. A pile that is half socks, half shirts is as mixed-up as two kinds of item can be. A good sorting question is one that leaves piles as pure as possible.
Tiny example. Before any question, the eight emails are 4 spam and 4 not: a 50/50 pile. Pull out two emails at random (putting the first one back) and they disagree half the time. The pile of unknown senders is 1 "not spam" and 4 spam: purer, so two random picks disagree less often.
Gini impurity is exactly that chance of disagreement:
Level 3: the formula and its symbols
$$ G = 1 - \sum_{k=1}^{K} p_k^{2} $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $G$ | the Gini impurity of one pile of examples: 0 when pure, larger when mixed | 0.5 for the eight emails |
| $K$ | how many different labels there are | 2 (spam, not spam) |
| $k$ | a counter that walks over the labels | 1 = not spam, 2 = spam |
| $p_k$ | the share of the pile carrying label $k$ | $p_1 = 4/8$, $p_2 = 4/8$ |
| $p_k^{2}$ | the chance two random picks both have label $k$ | $0.5^2 = 0.25$ |
| $\sum_{k=1}^{K}$ | "add up over every label": the chance two picks match | $0.25 + 0.25 = 0.5$ |
| $1 - \ldots$ | turns "chance they match" into "chance they disagree" | $1 - 0.5$ |
In words: "the impurity of a pile is one minus the sum of the squared shares of each label: the chance that two examples drawn at random carry different labels."
With the numbers: all eight emails: $1 - (0.5^2 + 0.5^2) = 1 - 0.5 = 0.5$. The unknown-sender pile, 1 of 5 not spam and 4 of 5 spam: $1 - (0.2^2 + 0.8^2) = 1 - (0.04 + 0.64) = 0.32$. A pure pile: $1 - 1^2 = 0$.
Level 3: in Python
In Python:
# four spam (1) and four not spam (0)
labels = [1, 1, 1, 1, 0, 0, 0, 0]
# p_k: the share of each label
p = [labels.count(k) / len(labels) for k in (0, 1)]
p  # → [0.5, 0.5]
# G = 1 - Σ p_k²
1 - sum(p_k ** 2 for p_k in p)  # → 0.5
# the unknown-sender pile: 1 not spam, 4 spam
p = [1 / 5, 4 / 5]
round(1 - sum(p_k ** 2 for p_k in p), 2)  # → 0.32
Why it matters: the tree needs a single number to compare questions with, and it must be cheap, because a real tree scores millions of candidate questions. Gini needs only counts, one multiply per label, and no logarithm.
In code: gini computes $G$ for any list of labels.
Entropy: the same idea, counted in yes/no questions
Everyday picture. Entropy asks: if I had to guess an email's label by asking yes/no questions, how many would I need on average? A 50/50 pile needs one full question. A pure pile needs none, because you already know.
Tiny example. For the eight emails, one question ("is it spam?") settles it: entropy 1 bit. For the unknown-sender pile, 4 of 5 are spam, so you are usually right before asking and the average cost is about 0.72 of a question.
Level 3: the formula and its symbols
$$ H = -\sum_{k=1}^{K} p_k \log_2 p_k $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $H$ | the entropy of one pile, in bits (yes/no questions) | 1 for the eight emails |
| $p_k$ | the share of the pile carrying label $k$, as above | 0.2 and 0.8 |
| $\log_2 p_k$ | the logarithm base 2: the power you raise 2 to in order to get $p_k$. It is negative for shares below 1 | $\log_2 0.5 = -1$, $\log_2 0.2 = -2.32$ |
| $-\sum$ | add up over the labels, then flip the sign so the total is positive |
In words: "entropy is the average, over the labels, of how surprising each label is, weighted by how often it appears." A label with share 0.5 costs $-\log_2 0.5 = 1$ bit of surprise.
With the numbers: eight emails: $-(0.5 \cdot (-1) + 0.5 \cdot (-1)) = 1$ bit. Unknown-sender pile: $-(0.2 \cdot \log_2 0.2 + 0.8 \cdot \log_2 0.8) = -(0.2 \cdot (-2.32) + 0.8 \cdot (-0.32)) = 0.722$ bits.
Level 3: in Python
In Python:
import math
# H = -Σ p_k log2 p_k
p = [0.5, 0.5]
-sum(p_k * math.log2(p_k) for p_k in p)  # → 1.0
p = [1 / 5, 4 / 5]
round(-sum(p_k * math.log2(p_k) for p_k in p), 3)  # → 0.722
Gini and entropy almost always pick the same question; Gini is a little
cheaper. The drop in entropy a question produces is called information
gain, the name the early ID3 algorithm used. See primer.notation for
logarithms from scratch and primer.ml.losses for entropy's close cousin,
cross-entropy.
In code: entropy computes $H$ in bits; DecisionTree takes criterion="entropy" to split by it instead of Gini.
Choosing the best question
Everyday picture. A question splits one pile into two. Judge it by how messy the two new piles are, but weigh each by its size: a tiny pure pile of one email is worth less than a big pure pile of five.
Tiny example. "Known sender?" makes a pile of 3 (all not spam, Gini 0) and a pile of 5 (1 not spam, 4 spam, Gini 0.32). "More than 2 links?" makes a pile of 4 (3 not spam, 1 spam) and another pile of 4 (1 not spam, 3 spam), Gini 0.375 each.
Level 3: the formula and its symbols
$$ G_{\text{split}} = \frac{n_L}{n}\, G(L) + \frac{n_R}{n}\, G(R) $$
Symbols
| Symbol | Meaning here | For "known sender?" |
|---|---|---|
| $L$, $R$ | the left pile (answer yes) and the right pile (answer no) | known / unknown senders |
| $n_L$, $n_R$ | how many examples land in each pile | 3 and 5 |
| $n$ | how many examples reached this node, $n_L + n_R$ | 8 |
| $G(L)$, $G(R)$ | the Gini impurity of each pile (the formula above) | 0 and 0.32 |
| $\frac{n_L}{n}$ | the left pile's share of the examples: its weight | 3/8 |
| $G_{\text{split}}$ | the impurity left after asking: lower is better | 0.2 |
In words: "the mess left by a question is the average of the two piles' impurities, each weighted by the share of examples in it."
With the numbers: known sender: $\frac{3}{8} \cdot 0 + \frac{5}{8} \cdot 0.32 = 0.2$. More than 2 links: $\frac{4}{8} \cdot 0.375 + \frac{4}{8} \cdot 0.375 = 0.375$. The tree asks "known sender?" because 0.2 < 0.375. The impurity decrease (the gain) is $0.5 - 0.2 = 0.3$.
Level 3: in Python
In Python:
# known senders: 3 emails, all not spam
n_left, g_left = 3, 0.0
# unknown senders: 1 not spam, 4 spam
n_right, g_right = 5, 0.32
n = n_left + n_right
# G_split = (n_L/n)·G(L) + (n_R/n)·G(R)
round(n_left / n * g_left + n_right / n * g_right, 3)  # → 0.2
# the impurity the question removed
round(0.5 - 0.2, 3)  # → 0.3
Where do candidate questions come from? For a number such as "links", only thresholds between neighbouring values in the data can change which emails go where. The links column holds 0, 1, 3, 4, 5 and 6, so there are five thresholds worth trying (halfway points 0.5, 2, 3.5, 4.5, 5.5), plus one for the yes/no column. The tree scores all six and keeps the lowest.
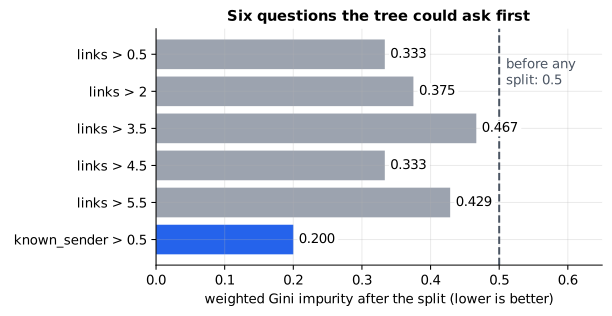
Reading it: each bar is one question the tree could ask first, and its length is the weighted Gini impurity left afterwards. The dashed line is the impurity before asking anything (0.5). Every question helps a little, since every bar ends left of the line, but "known_sender > 0.5" (blue) leaves the least mess by a clear margin, so it becomes the root of the tree. Two links thresholds tie at 0.333: the greedy search would take the first if known sender did not exist.
In code: split_impurity is $G_{\text{split}}$; candidate_splits scores every question in the figure; best_split does the same search fast, by sorting each feature once and keeping running label counts, and returns a Split.
Why it matters: this greedy search is the whole learning algorithm. There is no gradient and no learning rate: the tree tries every feature and every threshold and takes the best. That is why trees handle columns in any units, as the last section shows.
Growing the tree: ask, split, repeat
Everyday picture. Sorting a big box of photos: first by year, then each year's pile by who is in them, then each of those by place, until every pile is tidy or too small to bother with.
Tiny example. After "known sender?", the left pile (emails 1, 2, 3) is already pure: it becomes a leaf. The right pile (4, 5, 6, 7, 8) is not, so the tree searches again inside that pile only. There, "more than 0 links?" separates email 4 from the four spam emails perfectly. Both new piles are pure, so growth stops at depth 2.
flowchart TD
  S["node: the examples that reached here"] --> P{"pure, too small,<br/>or at the depth limit?"}
  P -->|yes| LEAF["make a leaf:<br/>predict the majority label<br/>(or the average number)"]
  P -->|no| SEARCH["try every feature and every threshold;<br/>keep the lowest weighted impurity"]
  SEARCH --> SPLIT["send examples left (feature ≤ threshold)<br/>or right (feature > threshold)"]
  SPLIT --> LEFT["grow the left child"] & RIGHT["grow the right child"]
  LEFT -.-> S
  RIGHT -.-> S
Reading it: the same recipe runs at every node, which is why the code is a function that calls itself (recursion). The dotted arrows are those calls: each child is a fresh node holding only its share of the examples. The diamond is where growth stops; everything else is the search from the previous section. To predict, a new example simply follows the questions from the root down to a leaf.
Each question looks at a single feature and compares it with a threshold, so every question cuts the input space with a straight line parallel to an axis. A tree therefore carves the plane into rectangles:
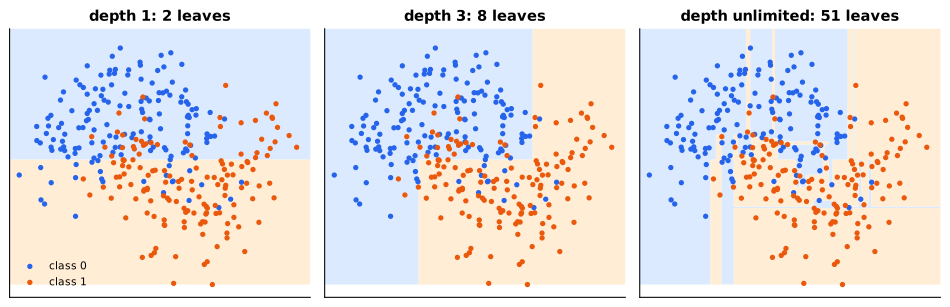
Reading it: the dots are 300 training points of two interleaved
half-moons with noise (primer.ml.neural_net.make_moons); the shaded
background is what the tree would predict at each spot. At depth 1 there is
one question, so one straight horizontal cut. At depth 3 there are 8 leaves, and the
boundary is a staircase of vertical and horizontal edges that roughly
follows the moons. With no limit, the tree keeps cutting until every leaf is
pure: 51 boxes, including thin strips that reach into the other class's
territory to capture a few noisy points.
Every edge is axis-aligned: trees cannot draw a diagonal, only approximate
one with steps.
A regression tree, predicting a number instead of a label, is the same recipe with two swaps: the impurity is the variance of the numbers in a pile (how spread out they are), and a leaf predicts their average. Gradient boosting, below, is built from those.
In code: DecisionTree grows by the recipe in the diagram (a depth limit and a minimum leaf size are its stopping rules, and the "squared" criterion makes it a regression tree), and DecisionTree.predict routes each row down to its leaf.
Overfitting: a question for every example
Everyday picture. Ask a friend to write rules for which of their emails are spam, and forbid them from stopping until every past email is sorted correctly. They will end up with rules like "an email from Pat at 9:14 on a Tuesday with 3 links is spam": perfect on the past, useless for the future.
Tiny example. On the noisy moons, a tree with no depth limit grows 51 leaves and gets 100% of its 300 training points right. On 200 fresh points it gets 82%. A tree stopped at depth 2 has 4 leaves, gets 88% on training and 89.5% on the fresh points: it learned the shape rather than the noise.
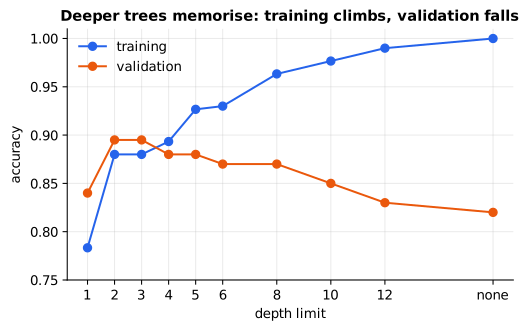
Reading it: the horizontal axis is the depth limit, from one question to
no limit at all. The blue training curve only ever rises, because every
extra level can only fit the training points better. The orange validation
curve peaks early, at depth 2 to 3, then slides down as the tree starts
building boxes around individual noisy points. The widening gap between
the two curves is overfitting, exactly as in primer.ml.regularization.
A single tree is the textbook high-variance model: change a few training points and the top question can flip, and everything below it changes with it. There are two ways out. Keep trees small (limit the depth, require a minimum number of examples per leaf, or grow fully then prune back the branches that do not help on validation data). Or keep trees big and combine many of them, which is what the rest of this lesson does.
In code: depth_sweep grows one tree per depth limit on moons_split data and measures both accuracies.
Why it matters: depth is the tree's capacity knob. Every tree library exposes it (along with a minimum leaf size), and choosing it on validation data is the first thing to tune.
Random forests: many noisy trees, one steady vote
Everyday picture. At a county fair, hundreds of people guess the weight of an ox. Individual guesses are wildly off in both directions, but the average of all of them lands remarkably close, because the errors point in different directions and cancel. A random forest does this with trees: grow many deep trees that each make different mistakes, then average them. The trick is making the mistakes different, since averaging copies of the same tree changes nothing.
Two sources of difference, both from Leo Breiman:
- Bagging (bootstrap aggregating): each tree trains on its own bootstrap sample, a resample of the training rows drawn with replacement.
- Random feature subsets: at every node, a tree may only consider a random handful of the features (commonly the square root of their number), so different trees are forced to find different questions.
flowchart LR
  D["training table<br/>(n rows)"] --> B1["bootstrap sample 1<br/>n rows drawn with replacement"] & B2["bootstrap sample 2"] & B3["..."] & BB["bootstrap sample B"]
  B1 --> T1["deep tree 1<br/>random features at each node"]
  B2 --> T2["deep tree 2"]
  B3 --> T3["..."]
  BB --> TB["deep tree B"]
  T1 & T2 & T3 & TB --> AVG["average their class shares<br/>(or their numbers)"]
  AVG --> OUT["prediction"]
Reading it: the table fans out into B different resamples, each resample grows its own full-depth tree, and the trees' answers are averaged at the end. Nothing flows between trees, so they can be grown in parallel on separate machines. Diversity enters twice: once in which rows each tree sees (the bootstrap boxes) and once in which features each node may use (inside the tree boxes).
Bagging: drawing names from a hat, and putting them back
Tiny example. Put the eight email numbers in a hat. Draw one, write it down, put it back, and repeat eight times. One draw might give 3, 1, 3, 7, 5, 1, 8, 2: emails 1 and 3 twice, and emails 4 and 6 not at all. Each tree sees a slightly different dataset, with some rows counted double and about a third missing.
How big is "about a third"? A particular email is missed on one draw with chance $1 - \frac{1}{n}$, and missed on all $n$ draws with:
Level 3: the formula and its symbols
$$ P(\text{left out}) = \left(1 - \frac{1}{n}\right)^{n} \;\longrightarrow\; \frac{1}{e} \approx 0.368 $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $n$ | the number of rows, and also the number of draws | 8 |
| $\frac{1}{n}$ | the chance one draw picks this particular row | 1/8 |
| $1 - \frac{1}{n}$ | the chance one draw misses it | 7/8 |
| $(\ldots)^{n}$ | missing it on every one of the $n$ independent draws: multiply the chances | $(7/8)^8$ |
| $\longrightarrow$ | "gets closer and closer to, as $n$ grows" | |
| $e$ | Euler's number, ≈ 2.718 (see primer.notation) |
$1/e = 0.368$ |
In words: "the chance a row never makes it into a bootstrap sample is the chance of missing it once, multiplied by itself once per draw; for big datasets that settles at about 37%."
With the numbers: $(7/8)^8 = 0.3436$ for the eight emails; for 100,000 rows, $(1 - 1/100000)^{100000} = 0.3679$, already equal to $1/e$ to four places.
Level 3: in Python
In Python:
import math
n = 8
# (1 - 1/n)^n: missed on every one of the n draws
round((1 - 1 / n) ** n, 4)  # → 0.3436
round((1 - 1 / 100_000) ** 100_000, 4)  # → 0.3679
round(1 / math.e, 4)  # → 0.3679
The rows a tree never saw are its out-of-bag rows: a free validation set for that tree, which random forests use to estimate their own accuracy without holding data back.
In code: bootstrap_sample draws the n row indices; out_of_bag_fraction is the formula; RandomForest gives every tree its own sample and its own feature subsets.
Why averaging helps, and what limits it
Tiny example. Three trees give a point spam probabilities of 0.9, 0.2 and 0.7. The forest says 0.6. If each tree's error is a coin flip that cancels out on average, three trees already wobble less than one; a hundred wobble far less. But if every tree makes the same mistake, averaging keeps it.
Level 3: the formula and its symbols
$$ \operatorname{Var}!\left(\frac{1}{B}\sum_{b=1}^{B} T_b\right) = \rho\,\sigma^{2} + \frac{1-\rho}{B}\,\sigma^{2} $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $B$ | the number of trees | 10 |
| $T_b$ | tree number $b$'s prediction for one input | 0.9, 0.2, 0.7, … |
| $\frac{1}{B}\sum_{b=1}^{B} T_b$ | the forest's prediction: the average of all trees | 0.6 |
| $\operatorname{Var}$ | variance: how much a prediction would swing if the training data were redrawn | |
| $\sigma^{2}$ | the variance of one tree on its own | 1 (a unit, for comparison) |
| $\rho$ | the correlation between two trees' errors: 0 if they err independently, 1 if they always err together (Greek letter rho) | 0.3 |
In words: "the forest's wobble has two parts: a part shared by all trees, which no amount of averaging removes, and a private part, which shrinks as you add trees."
With the numbers: with $\rho = 0.3$ and $\sigma^2 = 1$: ten trees give $0.3 + 0.7/10 = 0.37$; a thousand trees give $0.3 + 0.7/1000 = 0.3007$. Going from 10 to 1,000 trees barely helps; lowering $\rho$ would. With fully independent trees ($\rho = 0$), ten trees would cut the variance to 0.1.
Level 3: in Python
In Python:
sigma2, rho = 1.0, 0.3
# ρσ² + (1 - ρ)σ²/B
round(rho * sigma2 + (1 - rho) * sigma2 / 10, 4)  # → 0.37
round(rho * sigma2 + (1 - rho) * sigma2 / 1000, 4)  # → 0.3007
# independent trees: the variance falls as 1/B
round(0.0 * sigma2 + (1 - 0.0) * sigma2 / 10, 4)  # → 0.1
That is why a forest adds random feature subsets on top of bagging: bagging alone leaves every tree free to pick the same strong feature at the top, so the trees stay correlated. Forcing each node to choose from a random subset pushes $\rho$ down, which is the only way to push the floor down. Each tree gets a little worse; the average gets better.
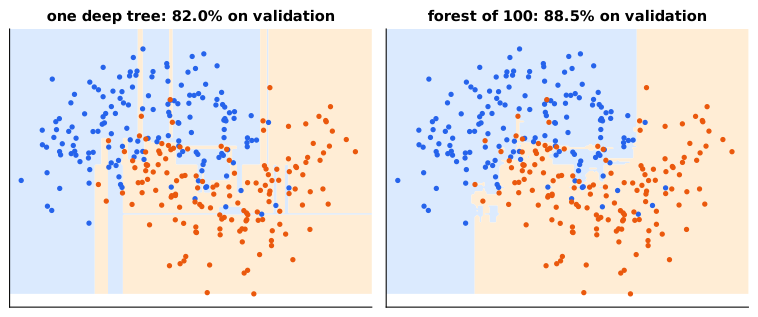
Reading it: both panels show the same 300 training points and the predicted class at every spot. On the left, a single unlimited tree fences off little islands around individual noisy points. On the right, a hundred unlimited trees vote: an island appears only where most trees agree, so the one-off islands mostly vanish and the boundary follows the two moons more smoothly. Each tree in the forest is just as overfitted as the one on the left; their average is not.
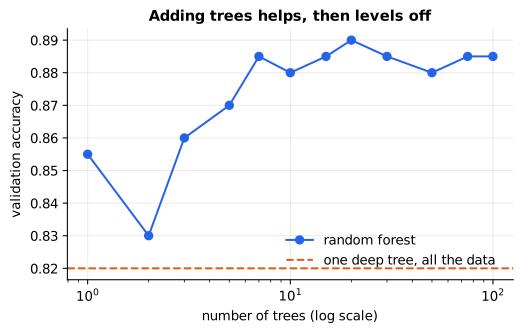
Reading it: the horizontal axis is how many trees are averaged, on a log scale; the vertical axis is accuracy on the 200 validation points. The dashed line is a single deep tree grown on all the data. The first points are jumpy (two fully grown trees that disagree give a 50/50 tie, which is why two trees dip below one), but the curve climbs over the first ten or twenty trees and then flattens: the private part of the variance is gone, and what remains is the shared part the formula predicts. Unlike depth, adding trees does not overfit; past the plateau it only costs time.
In code: averaged_variance is the formula; forest_curve grows one forest and scores its first k trees for each k; RandomForest.predict_proba averages the trees' class shares.
Why it matters: a random forest is the most forgiving model in machine learning. Its defaults (a few hundred unpruned trees, square root of the features per node) work well on most tables with no tuning at all, which is why it is the standard first model on new tabular data.
Gradient boosting: each tree fixes the last one's mistakes
Everyday picture. Golf. Your first shot from the tee gets you near the green. Your second shot does not start over from the tee: it aims at what is left, the gap between the ball and the hole. Each shot is small and corrects what remains. Gradient boosting builds a model the same way: start with a crude guess, then add small trees one at a time, each trained only on what the model so far still gets wrong.
Where a forest grows big trees side by side and averages them, boosting grows small trees in sequence and adds them up. The forest fights variance; boosting fights bias (being systematically off), a little at a time.
flowchart LR
  F0["F₀: start with the average"] --> R["residuals:<br/>what is still wrong<br/>r = y − F"]
  R --> H["fit a small tree hₘ<br/>to the residuals"]
  H --> U["Fₘ = Fₘ₋₁ + η · hₘ<br/>take a small step"]
  U -->|"next round"| R
  U --> OUT["after M rounds:<br/>F₀ + η·(h₁ + h₂ + … + h_M)"]
Reading it: the loop in the middle is the whole algorithm. Each round measures what is still wrong (the residuals), trains a small tree to predict those, and adds a shrunken copy of that tree to the model. The model is never retrained from scratch; it only grows by addition. The final model is the starting guess plus every tree's contribution, which is why a boosted model is literally a sum of trees.
Tiny example. Four houses of size 1, 2, 3 and 4 sold for 1, 2, 6 and 7 (hundreds of thousands, say). Boost with stumps (trees with a single question) and learning rate $\eta = 0.5$:
| size | price $y$ | $F_0$ | residual $y - F_0$ | stump $h_1$ | $F_1 = F_0 + 0.5\,h_1$ | new residual |
|---|---|---|---|---|---|---|
| 1 | 1 | 4 | −3 | −2.5 | 2.75 | −1.75 |
| 2 | 2 | 4 | −2 | −2.5 | 2.75 | −0.75 |
| 3 | 6 | 4 | 2 | 2.5 | 5.25 | 0.75 |
| 4 | 7 | 4 | 3 | 2.5 | 5.25 | 1.75 |
$F_0 = 4$ is the average price, the best single guess. The stump's best question on the residuals is "size ≤ 2.5?", and each leaf predicts its average residual: −2.5 for the small houses, +2.5 for the big ones. Adding half of that moves every guess toward its price. The mean squared error falls from 6.5 to 1.8125 in one round, and a second round brings it to 0.64.
Residuals are the negative gradient
Why is this called gradient boosting? Because "fit what is still wrong"
is a special case of gradient descent (primer.ml.optimizers), taken in the
space of predictions instead of weights.
Level 3: the formula and its symbols
$$ L(y, F) = \tfrac{1}{2}\,(y - F)^{2} \qquad\Longrightarrow\qquad r = -\frac{\partial L}{\partial F} = y - F $$
Symbols
| Symbol | Meaning here | For house 4 |
|---|---|---|
| $y$ | the true value | 7 |
| $F$ | the model's current prediction | $F_0 = 4$ |
| $L(y, F)$ | the loss: half the squared miss (the ½ only tidies the slope) | $\frac{1}{2}(7 - 4)^2 = 4.5$ |
| $\frac{\partial L}{\partial F}$ | the derivative: how fast the loss changes as the prediction $F$ is nudged up | $4 - 7 = -3$ |
| $-\frac{\partial L}{\partial F}$ | the direction that lowers the loss fastest, called the negative gradient | 3 |
| $r$ | the residual: what each tree is trained to predict | 3 |
| $\Longrightarrow$ | "which gives" |
In words: "for squared error, the direction that most quickly reduces the loss at each example is simply the true value minus the prediction: the residual."
With the numbers: house 4 has $y = 7$ and $F = 4$. Nudge $F$ up to 4.001 and the loss falls from 4.5 to about 4.497, a slope of −3; the negative gradient is +3, which is exactly $7 - 4$.
Level 3: in Python
In Python:
y, F, eps = 7.0, 4.0, 1e-6
# ∂L/∂F, measured by nudging F both ways
slope = (0.5 * (y - (F + eps)) ** 2 - 0.5 * (y - (F - eps)) ** 2) / (2 * eps)
round(slope, 6)  # → -3.0
# r = -∂L/∂F is the plain residual y - F
round(-slope, 6), y - F  # → (3.0, 3.0)
The payoff of the gradient view: swap in any loss with a slope and the same
loop still works. For yes/no labels with the log loss (primer.ml.losses),
$F$ is a score in log-odds and the negative gradient is $y - \sigma(F)$, the
label minus the predicted probability ($\sigma$ is the sigmoid, which
squashes a score into 0 to 1). Each tree then fits "how surprised were we
by each example".
In code: GradientBoosting.negative_gradient returns $y - F$ for loss="squared" and $y - \sigma(F)$ for loss="log".
The update, and the learning rate
Level 3: the formula and its symbols
$$ F_m(x) = F_{m-1}(x) + \eta\, h_m(x) $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $x$ | one input (a house's size) | size 4 |
| $m$ | the round number, 1, 2, …, $M$ | 1 |
| $F_{m-1}(x)$ | the model's prediction before this round | $F_0(4) = 4$ |
| $h_m(x)$ | this round's small tree, trained on the residuals | $h_1(4) = 2.5$ |
| $\eta$ | the learning rate (Greek letter eta), also called shrinkage: the fraction of each tree's correction actually applied | 0.5 |
| $F_m(x)$ | the prediction after this round | 5.25 |
In words: "after each round, the new prediction is the old prediction plus a shrunken copy of the tree that was trained to fix it."
With the numbers: big houses: $4 + 0.5 \times 2.5 = 5.25$; small houses: $4 + 0.5 \times (-2.5) = 2.75$. Mean squared error before: $(9 + 4 + 4 + 9)/4 = 6.5$; after: $(1.75^2 + 0.75^2 + 0.75^2 + 1.75^2)/4 = 1.8125$.
Level 3: in Python
In Python:
prices = [1, 2, 6, 7]
eta = 0.5
# F_0: the average price
F0 = sum(prices) / len(prices)
F0  # → 4.0
residuals = [y - F0 for y in prices]
residuals  # → [-3.0, -2.0, 2.0, 3.0]
# h_1: the stump predicts each side's average residual
small, big = (residuals[0] + residuals[1]) / 2, (residuals[2] + residuals[3]) / 2
h1 = [small, small, big, big]
h1  # → [-2.5, -2.5, 2.5, 2.5]
# F_1 = F_0 + η h_1
F1 = [F0 + eta * h for h in h1]
F1  # → [2.75, 2.75, 5.25, 5.25]
# mean squared error before and after the round
sum((y - F0) ** 2 for y in prices) / 4  # → 6.5
sum((y - f) ** 2 for y, f in zip(prices, F1)) / 4  # → 1.8125
Why not take the whole correction ($\eta = 1$)? Each tree is fitted to the training data, noise included. Taking the whole step lets the first few trees commit hard to whatever they saw; taking small steps means many trees must agree before the model moves far, which averages away some of the noise. The price is more rounds.
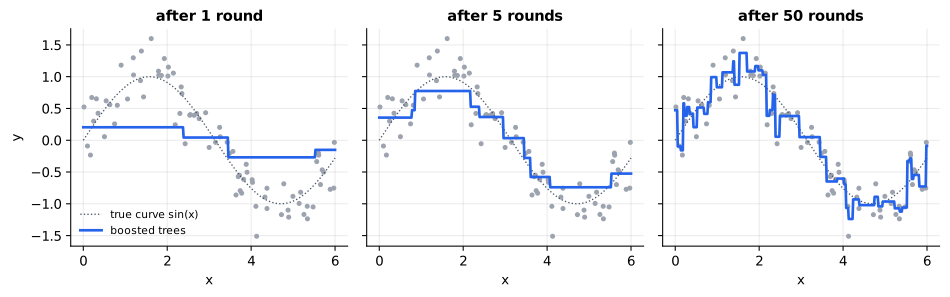
Reading it: grey dots are 80 noisy samples of the dotted sine curve, and the blue line is the boosted model's prediction everywhere between 0 and 6. After 1 round the model is the average plus 0.3 of one small tree: a line with just two flat steps. After 5 rounds it has the rough shape. After 50 it follows the curve closely and has begun to jump for individual noisy points, the first sign of the overfitting the next figure measures. Every version is made of flat steps, because every tree predicts a constant in each leaf; the curve is built from many small staircases added together.
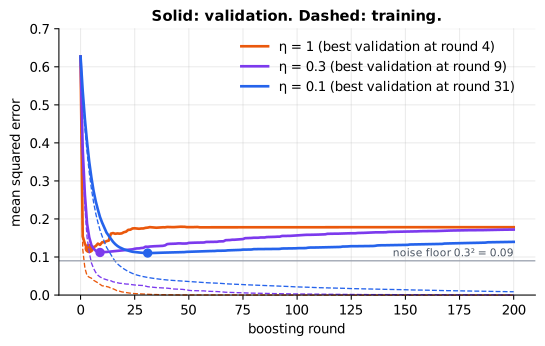
Reading it: dashed lines are training error and solid lines are error on
400 fresh points, per round, for three learning rates. Every training curve
falls toward zero, since 200 rounds of trees can memorise 80 points. Each
validation curve has a best round (the dot) and then rises, because later
trees are fitting noise. With $\eta = 1$ the best comes at round 4 (0.122)
and is poor; with $\eta = 0.1$ it comes at round 31 and is the lowest
(0.110), close to the noise floor of 0.09 that no model can beat. Smaller
steps generalize better but need more rounds, and every learning rate needs
a stopping point chosen on validation data: early stopping, as in
primer.ml.regularization.
In code: GradientBoosting runs the loop and records the training loss after each round; GradientBoosting.staged_loss scores held-out data after each round; boosting_worked_example is the four-house table; boosting_curves sweeps the learning rate on sine_data.
Why it matters: gradient-boosted trees (through libraries such as XGBoost, LightGBM and CatBoost) are the most common winning model on tabular data in practice. They add refinements this lesson leaves out, such as a second-order (Newton) step for each leaf's value, penalties on tree size, fast histogram-based split search, and native handling of missing values, but the loop is the one above. The two knobs that matter most are the ones you have met: tree depth and the learning rate, with the number of rounds chosen by early stopping.
When trees win, and when neural networks do
Everyday picture. A spreadsheet and a photograph are both grids of numbers, but they carry meaning differently. In a spreadsheet each column means something on its own: "income is under 30,000" is a sentence a loan officer would write. In a photo, "pixel (212, 40) is brighter than 0.7" means nothing; the meaning is in how thousands of pixels are arranged. A tree asks questions of one column at a time, which is perfect for the spreadsheet and hopeless for the photo. A neural network builds its own features out of combinations of inputs, which is what the photo needs.
Tiny example. A toy loan table: 800 training rows and 400 validation rows, five columns in their natural units: age in years, income in dollars (spanning a factor of 100), a count of late payments, a region code 0 to 5 (where region 4 is not "twice region 2"), and one column of pure random noise. The label follows rules of the kind a lender writes (four or more late payments; under 30,000 and under 30 years old; two late payments in certain regions or on a very low income), with 5% of labels flipped at random.
| model | what it was given | validation accuracy |
|---|---|---|
| always predict "fine" | nothing | 77.75% |
| single tree, depth 5 | the raw table | 92.25% |
| random forest, 50 trees | the raw table | 95.75% |
| gradient boosting, 100 depth-3 trees | the raw table | 96.00% |
| small neural net (32 hidden units) | the raw table | 77.75% |
| same net | every column rescaled to mean 0, spread 1 | 86.25% |
| same net | rescaled, plus log income and one column per region | 92.25% |
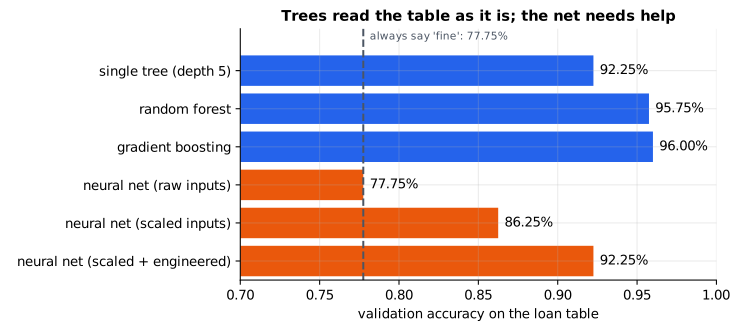
Reading it: blue bars are tree models, orange bars are the same small neural network given three versions of the same table, and the dashed line is the score for ignoring the inputs and always predicting "fine". The trees read the table exactly as it came. The net on raw inputs sits on the dashed line: incomes around 50,000 swamp every other column and saturate its neurons, so it learns nothing. Rescaling rescues it partly; hand-made features (the logarithm of income, a yes/no column per region) rescue it more. Even then it only ties a single depth-5 tree, and the ensembles stay ahead.
flowchart TD
  START{"what does one input look like?"} -->|"a row of a table:<br/>each column means<br/>something alone"| SIZE{"how much data?"}
  START -->|"pixels, audio samples,<br/>words, sequences"| NN["neural network<br/>(often a pretrained one)"]
  SIZE -->|"thousands to millions of rows"| GBT["gradient-boosted trees<br/>or a random forest first"]
  SIZE -->|"huge, or mixed with<br/>text or images"| MIX["neural network, or trees<br/>on top of neural embeddings"]
  GBT --> CHECK["compare against a neural net<br/>only if the gap matters"]
Reading it: the first question is about the shape of one input, not
about fashion. Tables go down the left; perceptual and sequential data go
right. On the left, the size of the data decides: at typical business
scale, start with trees. The bottom-right branch is common in practice: a
neural network turns text or images into embeddings
(primer.ml.embeddings.word2vec), and those numbers become extra columns
for a boosted-tree model.
Why trees fit tables so well, each point visible in this lesson's code:
- Units don't matter. A tree only asks "is this bigger than that?", so any order-keeping change to a column (dollars to thousands, a logarithm, a square) leaves every prediction unchanged. A neural net multiplies and adds columns, so their scales collide.
- Thresholds are native. Rules like "four or more late payments" are one question to a tree; a net must approximate the sharp edge with smooth curves.
- Irrelevant columns are mostly ignored, because a column that never wins a split is never used.
- Modest data is enough. A few hundred rows can grow a useful tree; a net with thousands of weights needs far more to pin them down.
Where neural networks win, and trees cannot follow:
- Perceptual and sequential data: images, audio, text. The useful
features are built from arrangements of raw values, which is what
convolutions (
primer.ml.cnn_rnn) and attention (primer.ml.transformer) learn. - Huge data and pretraining. A net's capacity keeps paying off as data grows, and a pretrained model brings knowledge from billions of examples. A tree starts from nothing every time.
- Smooth trends and extrapolation. A tree's leaves hold averages of training values, so it can never predict outside the range it saw. The four-house model predicts the same price for a house of size 40 as for size 4.
- End-to-end training with other neural parts, since a tree has no gradient to pass along.
In a careful benchmark on 45 tabular datasets of about 10,000 rows each (Grinsztajn, Oyallon and Varoquaux, 2022), tuned tree-based models remained ahead of tuned deep learning models. Their analysis names three reasons that match this lesson: trees shrug off uninformative columns, they respect each column's own axis, and they fit irregular, step-like functions easily. Research on neural networks for tables is active and the gap may narrow; the practical rule is to start with boosted trees on a table and make any other model beat them on your validation data.
In code: make_tabular builds the loan table; tabular_showdown trains every model in the table above (the net is primer.ml.neural_net.MLP); engineer_features is the hand-made preparation the net needed.
Feature importance, and its limits
Everyday picture. After a football season you want to know which players mattered. One way: count how often each player touched the ball in training. Another: bench each player for a real match and see how much the score suffers. The first is quick but credits whoever is busy; the second measures what the team actually depends on.
Trees offer the first kind for free. Impurity importance adds up, for each feature, the impurity its splits removed (weighted by how many examples reached each split), measured on the training data. Permutation importance is the second kind: take held-out data, shuffle one column so it no longer lines up with the labels, and measure how much accuracy drops.
Tiny example. The 30-tree forest scores 96.0% on the 400 validation rows. Shuffle the late-payments column and it scores 77.5%: a drop of 18.5 points, so the model leans on that column heavily. Shuffle the noise column and it scores 95.75%, a drop of 0.25 points (one row in 400).
Level 3: the formula and its symbols
$$ I_j = \text{acc}(X_{\text{val}}) - \text{acc}\big(X_{\text{val}} \text{ with column } j \text{ shuffled}\big) $$
Symbols
| Symbol | Meaning here | For late payments |
|---|---|---|
| $j$ | the feature (column) being tested | late_payments |
| $X_{\text{val}}$ | held-out rows the model never trained on | 400 rows |
| $\text{acc}(\ldots)$ | the share of those rows the model gets right | 0.96 |
| shuffled | the column's values randomly reordered: same values, links to the labels broken | 0.775 |
| $I_j$ | the permutation importance of feature $j$: accuracy lost without it | 0.185 |
In words: "a feature's importance is how much accuracy the model loses on fresh data when that feature is scrambled."
With the numbers: late payments $0.96 - 0.775 = 0.185$; noise $0.96 - 0.9575 = 0.0025$.
Level 3: in Python
In Python:
# validation rows answered correctly, out of 400
correct_of_400 = {"intact": 384, "late_payments shuffled": 310, "noise shuffled": 383}
acc = {k: v / 400 for k, v in correct_of_400.items()}
# I_j = acc(X_val) - acc(X_val with column j shuffled)
round(acc["intact"] - acc["late_payments shuffled"], 4)  # → 0.185
round(acc["intact"] - acc["noise shuffled"], 4)  # → 0.0025
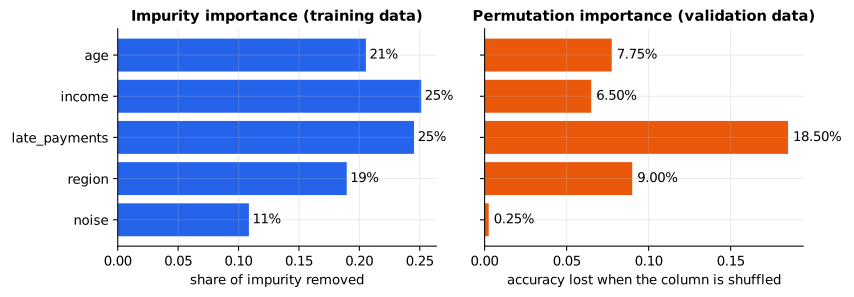
Reading it: the left panel is impurity importance from training, as shares that add to 100%; the right is permutation importance on validation data, in accuracy lost. Both agree the real columns matter. They disagree about noise: on the left it gets 11% of the credit, because deep trees can always find some threshold on a continuous random column that tidies up a few training rows. On the right, scrambling it costs almost nothing, because none of those splits help on new data.
The limits worth remembering:
- Impurity importance favours columns with many distinct values (continuous numbers, IDs), since they offer more thresholds to overfit with. Measure on held-out data instead.
- Correlated columns split the credit. If income appears twice (in dollars and in thousands), each copy looks half as important, and shuffling one does little because the other covers for it.
- Importance is not cause. It says what this model relies on to predict, not what would change the outcome in the world.
A single shallow tree is the one truly readable model here: print
DecisionTree.rules and you are reading the entire model. A forest of
hundreds of deep trees is not readable, and importances are a summary of it,
not an explanation.
In code: permutation_importance shuffles one column at a time on held-out data; DecisionTree.feature_importances and RandomForest.feature_importances are the impurity kind.
In 20 seconds
- A decision tree asks yes/no questions about one column at a time, choosing each question greedily to leave the purest piles (lowest weighted Gini impurity or entropy), until a stopping rule says stop.
- Deep trees overfit: a question for every example gives 100% on training data and poor results on new data. Depth is the capacity knob.
- Random forests average many deep trees, each grown on a bootstrap sample with random feature subsets. Averaging removes the variance the trees don't share; decorrelating them lowers the part they do.
- Gradient boosting adds small trees one at a time, each fit to the residuals (the negative gradient of the loss), shrunk by a learning rate, with the number of rounds set by early stopping.
- On tables, trees usually win: no scaling, native thresholds, modest data. Neural networks win on images, audio, text and huge datasets.
Self-test questions
Why is Gini impurity 0.5 for a pile that is half spam and half not? It is the chance that two emails drawn at random (with replacement) carry different labels: $1 - (0.5^2 + 0.5^2) = 0.5$. For two labels that is the most mixed a pile can be.
Why weight each child pile by its size when scoring a split? Otherwise a question that peels off one example into a tiny pure pile would look as good as one that sorts half the data cleanly. Weighting by size measures how much of the data the question actually tidied.
Why does a tree need no feature scaling, when a neural network does? A tree only compares one column against a threshold, so any change that keeps the order of values (rescaling, logarithms) produces the same splits and the same predictions. A network multiplies and adds columns together, so a column measured in tens of thousands drowns the others and saturates its neurons.
A tree scores 100% on training data and 80% on validation. What happened, and what are two fixes? It overfitted: it kept splitting until each leaf fenced off individual noisy examples. Limit its depth (or require a minimum number of examples per leaf, or prune), or replace it with a random forest that averages many such trees.
Why does a random forest use random feature subsets, not just bootstrap samples? The forest's variance is $\rho\sigma^2 + (1 - \rho)\sigma^2/B$. More trees only shrink the second term; the floor is set by the correlation $\rho$ between trees. With bagging alone every tree tends to pick the same strong feature first and they stay correlated. Random subsets force different trees down different paths, lowering $\rho$.
Does adding more trees overfit a random forest? Does adding more rounds overfit gradient boosting? More trees in a forest does not: accuracy rises and then levels off, only costing time. More rounds of boosting does: each round fits the training residuals more closely, so validation error reaches a minimum and then climbs. Boosting needs early stopping; forests don't.
Why is the residual the right target for each boosting tree? For squared-error loss $\frac{1}{2}(y - F)^2$, the negative derivative with respect to the prediction $F$ is $y - F$, the residual. Fitting a tree to it and taking a step is gradient descent on the predictions. With another loss, the tree fits that loss's negative gradient instead, such as $y - p$ for log loss.
What does a smaller learning rate buy in gradient boosting, and what does it cost? Each tree contributes only a fraction of its correction, so no single noisy tree can move the model far and many trees must agree. That usually generalizes better (0.110 against 0.122 in this lesson's sweep). It costs more rounds, so more training and prediction time.
Why can't a boosted-tree model predict a house price above the highest price it trained on? Every leaf predicts an average of training values, and the model is a sum of such leaves anchored at the training mean. Beyond the edge of the training data every question gives the same answer as at the edge, so the prediction stays flat.
What is wrong with trusting impurity-based feature importance? It is measured on training data, where splits on noise still tidy up piles. It favours columns with many distinct values and splits credit between correlated columns. Permutation importance on held-out data is more honest, and neither measures cause and effect.
When would you choose a neural network over gradient-boosted trees? When one input is an image, audio clip, text or other sequence whose meaning lies in the arrangement of raw values; when the data is huge or a pretrained model can be reused; when predictions must extrapolate smoothly; or when the model must be trained end to end with other neural parts.
The papers behind this lesson
- Breiman, Friedman, Olshen and Stone, Classification and Regression Trees (1984): https://doi.org/10.1201/9781315139470. The CART book: binary trees split by Gini impurity, regression trees with averaged leaves, and cost-complexity pruning, the recipe this lesson's tree follows.
- Quinlan, Induction of Decision Trees, Machine Learning 1 (1986): https://doi.org/10.1007/BF00116251. ID3, which grows trees by choosing the split with the largest information gain (drop in entropy).
- Breiman, Bagging Predictors, Machine Learning 24 (1996): https://doi.org/10.1007/BF00058655. Showed that averaging models trained on bootstrap samples reduces the error of unstable learners such as trees.
- Breiman, Random Forests, Machine Learning 45 (2001): https://doi.org/10.1023/A:1010933404324. Added random feature subsets at each split, out-of-bag error estimates, and permutation importance. Annotated companion
- Friedman, Greedy Function Approximation: A Gradient Boosting Machine, Annals of Statistics 29 (2001): https://doi.org/10.1214/aos/1013203451. Framed boosting as gradient descent in function space, fitting each tree to the negative gradient of any differentiable loss, with shrinkage. Annotated companion
- Chen and Guestrin, XGBoost: A Scalable Tree Boosting System (2016): https://arxiv.org/abs/1603.02754. A regularized, second-order boosting objective with fast, sparsity-aware split finding, which made boosted trees the default on tabular problems. Annotated companion
- Grinsztajn, Oyallon and Varoquaux, Why do tree-based models still outperform deep learning on tabular data? (2022): https://arxiv.org/abs/2207.08815. A benchmark on 45 medium-sized tabular datasets where tuned tree ensembles beat tuned neural networks, and an analysis of why.
Further reading
- scikit-learn user guide, Decision Trees: https://scikit-learn.org/stable/modules/tree.html
- scikit-learn user guide, Ensembles: gradient boosting, random forests, bagging: https://scikit-learn.org/stable/modules/ensemble.html
- scikit-learn user guide, Permutation feature importance: https://scikit-learn.org/stable/modules/permutation_importance.html
- XGBoost documentation, Introduction to Boosted Trees: https://xgboost.readthedocs.io/en/stable/tutorials/model.html
- Hastie, Tibshirani and Friedman, The Elements of Statistical Learning (free PDF from the authors; chapters 9, 10 and 15 cover trees, boosting and random forests): https://hastie.su.domains/ElemStatLearn/
- Strobl et al., Bias in random forest variable importance measures (2007): https://doi.org/10.1186/1471-2105-8-25
- Grinsztajn et al., Why do tree-based models still outperform deep learning on tabular data? (2022): https://arxiv.org/abs/2207.08815
1r""" 2# Trees and boosting: the other workhorse 3 4Run: `python -m primer.ml.classical` 5 6New to the notation? `primer.notation` explains every symbol used here from 7zero. This lesson builds on overfitting from `primer.ml.regularization` and 8uses the small network from `primer.ml.neural_net` as its sparring partner. 9 10## Level 1: The practitioner's guide 11 12**In one sentence.** On a table of data, where each column means something 13on its own, an ensemble of decision trees (a random forest or gradient 14boosting) is usually the model to beat, trains in seconds, needs no feature 15scaling, and should be the first thing you try before any neural network. 16 17**When you need it.** Whenever one input is a row: a customer, a payment, a 18day, a shipment, with columns in their own units (years, dollars, counts, a 19region code). Loan approval, fraud flags, churn, demand forecasting, ad 20ranking on tabular features: these are tree problems. The tell is that a 21domain expert could write some of the rules by hand ("four or more late 22payments"), because a tree asks exactly that kind of question. This 23lesson's loan table shows the gap: gradient boosting scores 96.0% and a 24random forest 95.75% on the raw table, while a small neural network on the 25same raw columns scores 77.75%, which is the score for always predicting 26"fine". Rescaling every column lifts the net to 86.25%; hand-engineering 27the features (log income, one column per region) lifts it to 92.25%, where 28it ties a single depth-5 tree and still trails both ensembles. You do not 29need trees when the input is an image, an audio clip or a text, where the 30meaning lives in the arrangement of thousands of raw values; that is what 31convolutions and attention learn, and where a pretrained network brings 32knowledge a tree starts without. 33 34**Your options.** From the most readable to the most accurate on a table, 35then the cases where the table is not the whole story: 36 37| Option | What it does | What it guarantees | What it costs | Where it lives | 38|---|---|---|---|---| 39| One shallow decision tree | Asks yes/no questions about one column at a time, chosen greedily by impurity | A model you can print and read as if/else rules | Accuracy: a depth-5 tree scores 92.25% where the ensembles score 96% | scikit-learn's decision trees; rules a compliance team can audit | 40| Random forest | Grows hundreds of deep trees on bootstrap samples with random feature subsets and averages them | Forgiving defaults; more trees never overfit, only cost time; a free out-of-bag error estimate | Not readable; a plateau set by how correlated the trees are | The standard first model on a new table | 41| Gradient-boosted trees | Adds small trees in sequence, each fitted to what the model still gets wrong, shrunk by a learning rate | The best accuracy on most tables of thousands to millions of rows | Two knobs to tune (depth, learning rate) and a stopping round chosen on validation data; more rounds do overfit | XGBoost, LightGBM, CatBoost | 42| A neural network on the table | Learns its own features from combinations of columns | Smooth trends, extrapolation, end-to-end training with other neural parts | Scaling and feature engineering just to get started; more data to pin down its weights; on this lesson's table it still trails | When the table is huge or mixed with text and images | 43| Trees on neural embeddings | A network turns text or images into vectors, which become extra columns for a boosted-tree model | The table's structure and the perceptual data's meaning in one model | Two models to maintain | Common in production ranking and risk systems | 44| A neural network on perceptual or sequential data | Convolutions, attention, pretrained weights | The only option that works: a tree cannot read a photo one pixel at a time | Everything the rest of this primer covers | Images, audio, text | 45 46**How to choose.** The first question is the shape of one input, not what 47is fashionable. 48 49- A row of a table, thousands to millions of rows: gradient-boosted trees, 50 or a random forest if you want something that works untuned. Make any 51 other model beat them on your validation data. 52- The model must be explained to a person, line by line: one shallow tree, 53 and accept the accuracy it costs. A forest's importances are a summary, 54 not an explanation. 55- Values outside the training range matter (prices next year, loads at a 56 new scale): trees predict flat beyond the edge of their data; this 57 lesson's four-house model prices a house of size 40 the same as size 4. 58 Use a model with a slope, or add a trend feature. 59- Pixels, audio samples, words: a neural network, usually pretrained. 60- A table that also carries free text or images: embed those with a 61 network and hand the vectors to the trees. 62- Whatever you pick, tune the tree's depth and the boosting learning rate 63 on validation data, and pick the number of boosting rounds by early 64 stopping. Those two knobs are most of the tuning that matters. 65 66**What it costs.** Training a forest or a boosted model on a table of 67modest size takes seconds on a laptop, with no GPU, no scaling and no 68feature engineering: the trees read dollars, years and region codes as they 69come. A forest grows its trees independently, so it parallelises across 70cores and machines; boosting is sequential, and a smaller learning rate 71buys accuracy with rounds. In this lesson's sweep, a learning rate of 1 72reaches its best validation error (0.122) at round 4, 0.3 reaches 0.112 at 73round 9, and 0.1 reaches the lowest, 0.110, at round 31. A forest's 74accuracy climbs over the first ten or twenty trees and then flattens; past 75the plateau, every extra tree is only prediction time. The cost that 76surprises people is on the neural side: the net needed rescaled inputs and 77hand-made features to reach a score a single tree matched, and Grinsztajn, 78Oyallon and Varoquaux (2022) found tuned tree ensembles still ahead of 79tuned deep learning across 45 tabular datasets of about 10,000 rows. 80 81**What breaks.** 82 83- **A tree grown to purity.** No depth limit gives 100% on training data and 84 the worst validation score in this lesson's sweep (82%, against 89.5% at 85 depth 2). Limit the depth or the leaf size, or use an ensemble. 86- **Too many boosting rounds.** Every learning rate's validation curve 87 bottoms out and climbs; 200 rounds memorise 80 points. Stop early on 88 validation data. 89- **A forest that has stopped improving.** The floor is the correlation 90 between trees: with correlation 0.3, going from 10 trees to 1,000 moves 91 the variance from 0.37 to 0.30. Lower the correlation (fewer features per 92 split) rather than adding trees. 93- **Trusting impurity importance.** It is measured on training data and 94 favours columns with many distinct values: here a column of pure noise 95 gets 11% of the credit. Permutation importance on held-out data gives it 96 0.25 points. Correlated columns split the credit between them, and 97 neither kind measures cause. 98- **Extrapolation.** Leaves hold averages of training values, so a tree 99 never predicts outside the range it saw. 100- **A network on raw columns.** Incomes in the tens of thousands swamp every 101 other column and saturate the neurons; the net learns nothing. Scale 102 first, or use trees. 103- **Diagonal boundaries.** A tree cuts parallel to the axes and can only 104 approximate a slope with a staircase; if the rule is a ratio of two 105 columns, give it that ratio as a feature. 106 107**In the wild.** XGBoost (Chen and Guestrin, 2016), LightGBM and CatBoost 108are the boosting libraries behind most winning tabular models, adding a 109second-order step per leaf, penalties on tree size, histogram-based split 110search and native missing values to the loop this lesson builds. 111scikit-learn's decision trees, random forests and permutation importance 112are the reference implementations for the rest, with its user guides in 113Further reading. The recipe is Breiman's: bagging (1996) and random forests 114(2001), which also introduced out-of-bag error and permutation importance; 115the boosting loop is Friedman's gradient boosting machine (2001); and the 116tree itself is CART (Breiman, Friedman, Olshen and Stone, 1984). Strobl et 117al. (2007) documented the bias in impurity importance that this lesson 118reproduces with its noise column. In `primer.ml.interpretability` the 119question of what a model relies on returns for neural networks, where no 120tree can be printed. 121 122**Go deeper.** Level 2 grows a tree by hand on eight emails, scores every 123candidate question with Gini impurity and entropy, sweeps depth to watch 124overfitting appear, builds a random forest from bootstrap samples and 125derives the correlation floor on its variance, runs gradient boosting on 126four houses one round at a time and shows why the residual is a gradient, 127then stages the loan-table showdown and both kinds of feature importance. 128If you only needed to know which model to reach for on a table, you are 129done. 130 131## Level 2: How it works, from scratch 132 133Most of this primer is about neural networks, because language models are 134neural networks. But open the models that decide whether a loan is approved, 135whether a card payment looks like fraud, which ad to show, or how many 136umbrellas a shop should stock, and very often you find no neural network at 137all. You find hundreds of small **decision trees**, added together. 138 139Those problems share a shape: a **table**. Each row is a customer, a payment 140or a day; each column is a fact measured in its own units (age in years, 141income in dollars, number of late payments, a region code). On tables of 142modest size, ensembles of trees have stayed the model to beat, and they 143train in seconds on a laptop. This lesson builds them from scratch, so you 144can see why they work and, just as usefully, recognise when a neural network 145is the wrong tool. 146 147The plan: one tree (how it chooses its questions), why a single tree 148overfits, how a **random forest** fixes that by averaging many trees, how 149**gradient boosting** fixes it differently by adding trees one after another, 150and finally a head-to-head against a small neural network from 151`primer.ml.neural_net` on a loan table. 152 153## A decision tree is a game of twenty questions 154 155**Everyday picture.** A nurse at an emergency desk runs a flowchart: "Is the 156patient breathing normally? No: resuscitation room. Yes: is there chest 157pain? Yes: see a doctor now. No: take a seat." Each question looks at *one* 158fact and sends the patient left or right, and the last box gives the answer. 159A decision tree is exactly that flowchart, except the questions are chosen 160by the computer from past examples. 161 162**Tiny example.** Eight emails, each described by two facts: how many links 163it contains, and whether it comes from a sender you have written to before. 164 165| email | links | known sender | spam? | 166|---|---|---|---| 167| 1 | 0 | yes | no | 168| 2 | 1 | yes | no | 169| 3 | 4 | yes | no | 170| 4 | 0 | no | no | 171| 5 | 3 | no | yes | 172| 6 | 5 | no | yes | 173| 7 | 6 | no | yes | 174| 8 | 1 | no | yes | 175 176The tree this lesson grows from those eight rows: 177 178```mermaid 179flowchart TD 180 Q1{"known sender?"} -->|yes| L1["not spam<br/>(emails 1, 2, 3)"] 181 Q1 -->|no| Q2{"more than 0 links?"} 182 Q2 -->|no| L2["not spam<br/>(email 4)"] 183 Q2 -->|yes| L3["spam<br/>(emails 5, 6, 7, 8)"] 184``` 185 186**Reading it:** start at the top diamond with a new email and answer each 187question until you land in a box. Diamonds are questions (the tree's 188**internal nodes**); boxes are answers (its **leaves**), and each leaf lists 189the training emails that ended up there. Two questions sort all eight 190correctly. Notice what the tree did *not* ask: "more than 2 links?" looks 191reasonable, but it was worse. The next two sections show how the tree 192decides that. 193 194**In code:** `spam_emails` returns the table above; `DecisionTree` grows the tree, and `DecisionTree.rules` prints it as nested if/else lines. 195 196## Measuring a mess: Gini impurity 197 198**Everyday picture.** You are sorting laundry into piles. A pile of only 199socks is *pure*: pull out any two items and they match. A pile that is half 200socks, half shirts is as mixed-up as two kinds of item can be. A good 201sorting question is one that leaves piles as pure as possible. 202 203**Tiny example.** Before any question, the eight emails are 4 spam and 4 204not: a 50/50 pile. Pull out two emails at random (putting the first one 205back) and they disagree half the time. The pile of unknown senders is 1 206"not spam" and 4 spam: purer, so two random picks disagree less often. 207 208**Gini impurity** is exactly that chance of disagreement: 209 210$$ 211G = 1 - \sum_{k=1}^{K} p_k^{2} 212$$ 213 214**Symbols** 215 216| Symbol | Meaning here | In the example | 217|---|---|---| 218| $G$ | the Gini impurity of one pile of examples: 0 when pure, larger when mixed | 0.5 for the eight emails | 219| $K$ | how many different labels there are | 2 (spam, not spam) | 220| $k$ | a counter that walks over the labels | 1 = not spam, 2 = spam | 221| $p_k$ | the share of the pile carrying label $k$ | $p_1 = 4/8$, $p_2 = 4/8$ | 222| $p_k^{2}$ | the chance two random picks *both* have label $k$ | $0.5^2 = 0.25$ | 223| $\sum_{k=1}^{K}$ | "add up over every label": the chance two picks match | $0.25 + 0.25 = 0.5$ | 224| $1 - \ldots$ | turns "chance they match" into "chance they disagree" | $1 - 0.5$ | 225 226**In words:** "the impurity of a pile is one minus the sum of the squared 227shares of each label: the chance that two examples drawn at random carry 228different labels." 229 230**With the numbers:** all eight emails: $1 - (0.5^2 + 0.5^2) = 1 - 0.5 = 2310.5$. The unknown-sender pile, 1 of 5 not spam and 4 of 5 spam: 232$1 - (0.2^2 + 0.8^2) = 1 - (0.04 + 0.64) = 0.32$. A pure pile: $1 - 1^2 = 0$. 233 234**In Python:** 235 236```python 237# four spam (1) and four not spam (0) 238labels = [1, 1, 1, 1, 0, 0, 0, 0] 239# p_k: the share of each label 240p = [labels.count(k) / len(labels) for k in (0, 1)] 241p # → [0.5, 0.5] 242# G = 1 - Σ p_k² 2431 - sum(p_k ** 2 for p_k in p) # → 0.5 244# the unknown-sender pile: 1 not spam, 4 spam 245p = [1 / 5, 4 / 5] 246round(1 - sum(p_k ** 2 for p_k in p), 2) # → 0.32 247``` 248 249**Why it matters:** the tree needs a single number to compare questions 250with, and it must be cheap, because a real tree scores millions of candidate 251questions. Gini needs only counts, one multiply per label, and no logarithm. 252 253**In code:** `gini` computes $G$ for any list of labels. 254 255### Entropy: the same idea, counted in yes/no questions 256 257**Everyday picture.** Entropy asks: if I had to guess an email's label by 258asking yes/no questions, how many would I need on average? A 50/50 pile 259needs one full question. A pure pile needs none, because you already know. 260 261**Tiny example.** For the eight emails, one question ("is it spam?") 262settles it: entropy 1 bit. For the unknown-sender pile, 4 of 5 are spam, so 263you are usually right before asking and the average cost is about 0.72 of a 264question. 265 266$$ 267H = -\sum_{k=1}^{K} p_k \log_2 p_k 268$$ 269 270**Symbols** 271 272| Symbol | Meaning here | In the example | 273|---|---|---| 274| $H$ | the entropy of one pile, in **bits** (yes/no questions) | 1 for the eight emails | 275| $p_k$ | the share of the pile carrying label $k$, as above | 0.2 and 0.8 | 276| $\log_2 p_k$ | the **logarithm** base 2: the power you raise 2 to in order to get $p_k$. It is negative for shares below 1 | $\log_2 0.5 = -1$, $\log_2 0.2 = -2.32$ | 277| $-\sum$ | add up over the labels, then flip the sign so the total is positive | | 278 279**In words:** "entropy is the average, over the labels, of how surprising 280each label is, weighted by how often it appears." A label with share 0.5 281costs $-\log_2 0.5 = 1$ bit of surprise. 282 283**With the numbers:** eight emails: $-(0.5 \cdot (-1) + 0.5 \cdot (-1)) = 1$ 284bit. Unknown-sender pile: $-(0.2 \cdot \log_2 0.2 + 0.8 \cdot \log_2 0.8) = 285-(0.2 \cdot (-2.32) + 0.8 \cdot (-0.32)) = 0.722$ bits. 286 287**In Python:** 288 289```python 290import math 291# H = -Σ p_k log2 p_k 292p = [0.5, 0.5] 293-sum(p_k * math.log2(p_k) for p_k in p) # → 1.0 294p = [1 / 5, 4 / 5] 295round(-sum(p_k * math.log2(p_k) for p_k in p), 3) # → 0.722 296``` 297 298Gini and entropy almost always pick the same question; Gini is a little 299cheaper. The drop in entropy a question produces is called **information 300gain**, the name the early ID3 algorithm used. See `primer.notation` for 301logarithms from scratch and `primer.ml.losses` for entropy's close cousin, 302cross-entropy. 303 304**In code:** `entropy` computes $H$ in bits; `DecisionTree` takes `criterion="entropy"` to split by it instead of Gini. 305 306## Choosing the best question 307 308**Everyday picture.** A question splits one pile into two. Judge it by how 309messy the two new piles are, but weigh each by its size: a tiny pure pile of 310one email is worth less than a big pure pile of five. 311 312**Tiny example.** "Known sender?" makes a pile of 3 (all not spam, Gini 0) 313and a pile of 5 (1 not spam, 4 spam, Gini 0.32). "More than 2 links?" makes 314a pile of 4 (3 not spam, 1 spam) and another pile of 4 (1 not spam, 3 spam), 315Gini 0.375 each. 316 317$$ 318G_{\text{split}} = \frac{n_L}{n}\, G(L) + \frac{n_R}{n}\, G(R) 319$$ 320 321**Symbols** 322 323| Symbol | Meaning here | For "known sender?" | 324|---|---|---| 325| $L$, $R$ | the left pile (answer yes) and the right pile (answer no) | known / unknown senders | 326| $n_L$, $n_R$ | how many examples land in each pile | 3 and 5 | 327| $n$ | how many examples reached this node, $n_L + n_R$ | 8 | 328| $G(L)$, $G(R)$ | the Gini impurity of each pile (the formula above) | 0 and 0.32 | 329| $\frac{n_L}{n}$ | the left pile's share of the examples: its weight | 3/8 | 330| $G_{\text{split}}$ | the impurity left after asking: lower is better | 0.2 | 331 332**In words:** "the mess left by a question is the average of the two piles' 333impurities, each weighted by the share of examples in it." 334 335**With the numbers:** known sender: $\frac{3}{8} \cdot 0 + \frac{5}{8} \cdot 3360.32 = 0.2$. More than 2 links: $\frac{4}{8} \cdot 0.375 + \frac{4}{8} 337\cdot 0.375 = 0.375$. The tree asks "known sender?" because 0.2 < 0.375. 338The **impurity decrease** (the gain) is $0.5 - 0.2 = 0.3$. 339 340**In Python:** 341 342```python 343# known senders: 3 emails, all not spam 344n_left, g_left = 3, 0.0 345# unknown senders: 1 not spam, 4 spam 346n_right, g_right = 5, 0.32 347n = n_left + n_right 348# G_split = (n_L/n)·G(L) + (n_R/n)·G(R) 349round(n_left / n * g_left + n_right / n * g_right, 3) # → 0.2 350# the impurity the question removed 351round(0.5 - 0.2, 3) # → 0.3 352``` 353 354Where do candidate questions come from? For a number such as "links", only 355thresholds *between* neighbouring values in the data can change which 356emails go where. The links column holds 0, 1, 3, 4, 5 and 6, so there are 357five thresholds worth trying (halfway points 0.5, 2, 3.5, 4.5, 5.5), plus 358one for the yes/no column. The tree scores all six and keeps the lowest. 359 360 361 362**Reading it:** each bar is one question the tree could ask first, and its 363length is the weighted Gini impurity left afterwards. The dashed line is the 364impurity before asking anything (0.5). Every question helps a little, since 365every bar ends left of the line, but "known_sender > 0.5" (blue) leaves the 366least mess by a clear margin, so it becomes the root of the tree. Two links 367thresholds tie at 0.333: the greedy search would take the first if known 368sender did not exist. 369 370**In code:** `split_impurity` is $G_{\text{split}}$; `candidate_splits` scores every question in the figure; `best_split` does the same search fast, by sorting each feature once and keeping running label counts, and returns a `Split`. 371 372**Why it matters:** this greedy search is the whole learning algorithm. There 373is no gradient and no learning rate: the tree tries every feature and every 374threshold and takes the best. That is why trees handle columns in any units, 375as the last section shows. 376 377## Growing the tree: ask, split, repeat 378 379**Everyday picture.** Sorting a big box of photos: first by year, then each 380year's pile by who is in them, then each of those by place, until every pile 381is tidy or too small to bother with. 382 383**Tiny example.** After "known sender?", the left pile (emails 1, 2, 3) is 384already pure: it becomes a leaf. The right pile (4, 5, 6, 7, 8) is not, so 385the tree searches again *inside that pile only*. There, "more than 0 links?" 386separates email 4 from the four spam emails perfectly. Both new piles are 387pure, so growth stops at depth 2. 388 389```mermaid 390flowchart TD 391 S["node: the examples that reached here"] --> P{"pure, too small,<br/>or at the depth limit?"} 392 P -->|yes| LEAF["make a leaf:<br/>predict the majority label<br/>(or the average number)"] 393 P -->|no| SEARCH["try every feature and every threshold;<br/>keep the lowest weighted impurity"] 394 SEARCH --> SPLIT["send examples left (feature ≤ threshold)<br/>or right (feature > threshold)"] 395 SPLIT --> LEFT["grow the left child"] & RIGHT["grow the right child"] 396 LEFT -.-> S 397 RIGHT -.-> S 398``` 399 400**Reading it:** the same recipe runs at every node, which is why the code is 401a function that calls itself (recursion). The dotted arrows are those 402calls: each child is a fresh node holding only its share of the examples. 403The diamond is where growth stops; everything else is the search from the 404previous section. To predict, a new example simply follows the questions 405from the root down to a leaf. 406 407Each question looks at a single feature and compares it with a threshold, 408so every question cuts the input space with a straight line parallel to an 409axis. A tree therefore carves the plane into rectangles: 410 411 412 413**Reading it:** the dots are 300 training points of two interleaved 414half-moons with noise (`primer.ml.neural_net.make_moons`); the shaded 415background is what the tree would predict at each spot. At depth 1 there is 416one question, so one straight horizontal cut. At depth 3 there are 8 leaves, and the 417boundary is a staircase of vertical and horizontal edges that roughly 418follows the moons. With no limit, the tree keeps cutting until every leaf is 419pure: 51 boxes, including thin strips that reach into the other class's 420territory to capture a few noisy points. 421Every edge is axis-aligned: trees cannot draw a diagonal, only approximate 422one with steps. 423 424A regression tree, predicting a number instead of a label, is the same 425recipe with two swaps: the impurity is the **variance** of the numbers in a 426pile (how spread out they are), and a leaf predicts their average. Gradient 427boosting, below, is built from those. 428 429**In code:** `DecisionTree` grows by the recipe in the diagram (a depth limit and a minimum leaf size are its stopping rules, and the "squared" criterion makes it a regression tree), and `DecisionTree.predict` routes each row down to its leaf. 430 431## Overfitting: a question for every example 432 433**Everyday picture.** Ask a friend to write rules for which of their emails 434are spam, and forbid them from stopping until every past email is sorted 435correctly. They will end up with rules like "an email from Pat at 9:14 on a 436Tuesday with 3 links is spam": perfect on the past, useless for the future. 437 438**Tiny example.** On the noisy moons, a tree with no depth limit grows 51 439leaves and gets 100% of its 300 training points right. On 200 fresh points 440it gets 82%. A tree stopped at depth 2 has 4 leaves, gets 88% on training 441and 89.5% on the fresh points: it learned the shape rather than the noise. 442 443 444 445**Reading it:** the horizontal axis is the depth limit, from one question to 446no limit at all. The blue training curve only ever rises, because every 447extra level can only fit the training points better. The orange validation 448curve peaks early, at depth 2 to 3, then slides down as the tree starts 449building boxes around individual noisy points. The widening gap between 450the two curves is overfitting, exactly as in `primer.ml.regularization`. 451 452A single tree is the textbook **high-variance** model: change a few training 453points and the top question can flip, and everything below it changes with 454it. There are two ways out. Keep trees small (limit the depth, require a 455minimum number of examples per leaf, or grow fully then **prune** back the 456branches that do not help on validation data). Or keep trees big and combine 457many of them, which is what the rest of this lesson does. 458 459**In code:** `depth_sweep` grows one tree per depth limit on `moons_split` data and measures both accuracies. 460 461**Why it matters:** depth is the tree's capacity knob. Every tree library 462exposes it (along with a minimum leaf size), and choosing it on validation 463data is the first thing to tune. 464 465## Random forests: many noisy trees, one steady vote 466 467**Everyday picture.** At a county fair, hundreds of people guess the weight 468of an ox. Individual guesses are wildly off in both directions, but the 469average of all of them lands remarkably close, because the errors point in 470different directions and cancel. A **random forest** does this with trees: 471grow many deep trees that each make *different* mistakes, then average 472them. The trick is making the mistakes different, since averaging copies of 473the same tree changes nothing. 474 475Two sources of difference, both from Leo Breiman: 476 4771. **Bagging** (bootstrap aggregating): each tree trains on its own 478 **bootstrap sample**, a resample of the training rows drawn *with 479 replacement*. 4802. **Random feature subsets**: at every node, a tree may only consider a 481 random handful of the features (commonly the square root of their 482 number), so different trees are forced to find different questions. 483 484```mermaid 485flowchart LR 486 D["training table<br/>(n rows)"] --> B1["bootstrap sample 1<br/>n rows drawn with replacement"] & B2["bootstrap sample 2"] & B3["..."] & BB["bootstrap sample B"] 487 B1 --> T1["deep tree 1<br/>random features at each node"] 488 B2 --> T2["deep tree 2"] 489 B3 --> T3["..."] 490 BB --> TB["deep tree B"] 491 T1 & T2 & T3 & TB --> AVG["average their class shares<br/>(or their numbers)"] 492 AVG --> OUT["prediction"] 493``` 494 495**Reading it:** the table fans out into B different resamples, each resample 496grows its own full-depth tree, and the trees' answers are averaged at the 497end. Nothing flows between trees, so they can be grown in parallel on 498separate machines. Diversity enters twice: once in which rows each tree 499sees (the bootstrap boxes) and once in which features each node may use 500(inside the tree boxes). 501 502### Bagging: drawing names from a hat, and putting them back 503 504**Tiny example.** Put the eight email numbers in a hat. Draw one, write it 505down, *put it back*, and repeat eight times. One draw might give 3, 1, 3, 7, 5065, 1, 8, 2: emails 1 and 3 twice, and emails 4 and 6 not at all. Each tree 507sees a slightly different dataset, with some rows counted double and about 508a third missing. 509 510How big is "about a third"? A particular email is missed on one draw with 511chance $1 - \frac{1}{n}$, and missed on all $n$ draws with: 512 513$$ 514P(\text{left out}) = \left(1 - \frac{1}{n}\right)^{n} \;\longrightarrow\; \frac{1}{e} \approx 0.368 515$$ 516 517**Symbols** 518 519| Symbol | Meaning here | In the example | 520|---|---|---| 521| $n$ | the number of rows, and also the number of draws | 8 | 522| $\frac{1}{n}$ | the chance one draw picks this particular row | 1/8 | 523| $1 - \frac{1}{n}$ | the chance one draw misses it | 7/8 | 524| $(\ldots)^{n}$ | missing it on every one of the $n$ independent draws: multiply the chances | $(7/8)^8$ | 525| $\longrightarrow$ | "gets closer and closer to, as $n$ grows" | | 526| $e$ | Euler's number, ≈ 2.718 (see `primer.notation`) | $1/e = 0.368$ | 527 528**In words:** "the chance a row never makes it into a bootstrap sample is 529the chance of missing it once, multiplied by itself once per draw; for big 530datasets that settles at about 37%." 531 532**With the numbers:** $(7/8)^8 = 0.3436$ for the eight emails; for 100,000 533rows, $(1 - 1/100000)^{100000} = 0.3679$, already equal to $1/e$ to four 534places. 535 536**In Python:** 537 538```python 539import math 540n = 8 541# (1 - 1/n)^n: missed on every one of the n draws 542round((1 - 1 / n) ** n, 4) # → 0.3436 543round((1 - 1 / 100_000) ** 100_000, 4) # → 0.3679 544round(1 / math.e, 4) # → 0.3679 545``` 546 547The rows a tree never saw are its **out-of-bag** rows: a free validation set 548for that tree, which random forests use to estimate their own accuracy 549without holding data back. 550 551**In code:** `bootstrap_sample` draws the n row indices; `out_of_bag_fraction` is the formula; `RandomForest` gives every tree its own sample and its own feature subsets. 552 553### Why averaging helps, and what limits it 554 555**Tiny example.** Three trees give a point spam probabilities of 0.9, 0.2 556and 0.7. The forest says 0.6. If each tree's error is a coin flip that 557cancels out on average, three trees already wobble less than one; a hundred 558wobble far less. But if every tree makes the *same* mistake, averaging keeps 559it. 560 561$$ 562\operatorname{Var}\!\left(\frac{1}{B}\sum_{b=1}^{B} T_b\right) = \rho\,\sigma^{2} + \frac{1-\rho}{B}\,\sigma^{2} 563$$ 564 565**Symbols** 566 567| Symbol | Meaning here | In the example | 568|---|---|---| 569| $B$ | the number of trees | 10 | 570| $T_b$ | tree number $b$'s prediction for one input | 0.9, 0.2, 0.7, … | 571| $\frac{1}{B}\sum_{b=1}^{B} T_b$ | the forest's prediction: the average of all trees | 0.6 | 572| $\operatorname{Var}$ | **variance**: how much a prediction would swing if the training data were redrawn | | 573| $\sigma^{2}$ | the variance of one tree on its own | 1 (a unit, for comparison) | 574| $\rho$ | the **correlation** between two trees' errors: 0 if they err independently, 1 if they always err together (Greek letter rho) | 0.3 | 575 576**In words:** "the forest's wobble has two parts: a part shared by all trees, 577which no amount of averaging removes, and a private part, which shrinks as 578you add trees." 579 580**With the numbers:** with $\rho = 0.3$ and $\sigma^2 = 1$: ten trees give 581$0.3 + 0.7/10 = 0.37$; a thousand trees give $0.3 + 0.7/1000 = 0.3007$. 582Going from 10 to 1,000 trees barely helps; lowering $\rho$ would. With fully 583independent trees ($\rho = 0$), ten trees would cut the variance to 0.1. 584 585**In Python:** 586 587```python 588sigma2, rho = 1.0, 0.3 589# ρσ² + (1 - ρ)σ²/B 590round(rho * sigma2 + (1 - rho) * sigma2 / 10, 4) # → 0.37 591round(rho * sigma2 + (1 - rho) * sigma2 / 1000, 4) # → 0.3007 592# independent trees: the variance falls as 1/B 593round(0.0 * sigma2 + (1 - 0.0) * sigma2 / 10, 4) # → 0.1 594``` 595 596That is why a forest adds random feature subsets on top of bagging: bagging 597alone leaves every tree free to pick the same strong feature at the top, so 598the trees stay correlated. Forcing each node to choose from a random subset 599pushes $\rho$ down, which is the only way to push the floor down. Each tree 600gets a little worse; the average gets better. 601 602 603 604**Reading it:** both panels show the same 300 training points and the 605predicted class at every spot. On the left, a single unlimited tree fences 606off little islands around individual noisy points. On the right, a hundred 607unlimited trees vote: an island appears only where most trees agree, so the 608one-off islands mostly vanish and the boundary follows the two moons more 609smoothly. Each tree in the forest is just as overfitted as the one on the 610left; their average is not. 611 612 613 614**Reading it:** the horizontal axis is how many trees are averaged, on a log 615scale; the vertical axis is accuracy on the 200 validation points. The 616dashed line is a single deep tree grown on all the data. The first points 617are jumpy (two fully grown trees that disagree give a 50/50 tie, which is 618why two trees dip below one), but the curve climbs over the first ten or 619twenty trees and then flattens: the private 620part of the variance is gone, and what remains is the shared part the 621formula predicts. Unlike depth, adding trees does not overfit; past the 622plateau it only costs time. 623 624**In code:** `averaged_variance` is the formula; `forest_curve` grows one forest and scores its first k trees for each k; `RandomForest.predict_proba` averages the trees' class shares. 625 626**Why it matters:** a random forest is the most forgiving model in machine 627learning. Its defaults (a few hundred unpruned trees, square root of the 628features per node) work well on most tables with no tuning at all, which is 629why it is the standard first model on new tabular data. 630 631## Gradient boosting: each tree fixes the last one's mistakes 632 633**Everyday picture.** Golf. Your first shot from the tee gets you near the 634green. Your second shot does not start over from the tee: it aims at what is 635*left*, the gap between the ball and the hole. Each shot is small and 636corrects what remains. **Gradient boosting** builds a model the same way: 637start with a crude guess, then add small trees one at a time, each trained 638only on what the model so far still gets wrong. 639 640Where a forest grows big trees side by side and averages them, boosting 641grows small trees in sequence and adds them up. The forest fights variance; 642boosting fights **bias** (being systematically off), a little at a time. 643 644```mermaid 645flowchart LR 646 F0["F₀: start with the average"] --> R["residuals:<br/>what is still wrong<br/>r = y − F"] 647 R --> H["fit a small tree hₘ<br/>to the residuals"] 648 H --> U["Fₘ = Fₘ₋₁ + η · hₘ<br/>take a small step"] 649 U -->|"next round"| R 650 U --> OUT["after M rounds:<br/>F₀ + η·(h₁ + h₂ + … + h_M)"] 651``` 652 653**Reading it:** the loop in the middle is the whole algorithm. Each round 654measures what is still wrong (the residuals), trains a small tree to predict 655*those*, and adds a shrunken copy of that tree to the model. The model is 656never retrained from scratch; it only grows by addition. The final model is 657the starting guess plus every tree's contribution, which is why a boosted 658model is literally a sum of trees. 659 660**Tiny example.** Four houses of size 1, 2, 3 and 4 sold for 1, 2, 6 and 7 661(hundreds of thousands, say). Boost with **stumps** (trees with a single 662question) and learning rate $\eta = 0.5$: 663 664| size | price $y$ | $F_0$ | residual $y - F_0$ | stump $h_1$ | $F_1 = F_0 + 0.5\,h_1$ | new residual | 665|---|---|---|---|---|---|---| 666| 1 | 1 | 4 | −3 | −2.5 | 2.75 | −1.75 | 667| 2 | 2 | 4 | −2 | −2.5 | 2.75 | −0.75 | 668| 3 | 6 | 4 | 2 | 2.5 | 5.25 | 0.75 | 669| 4 | 7 | 4 | 3 | 2.5 | 5.25 | 1.75 | 670 671$F_0 = 4$ is the average price, the best single guess. The stump's best 672question on the residuals is "size ≤ 2.5?", and each leaf predicts its 673average residual: −2.5 for the small houses, +2.5 for the big ones. Adding 674half of that moves every guess toward its price. The mean squared error 675falls from 6.5 to 1.8125 in one round, and a second round brings it to 6760.64. 677 678### Residuals are the negative gradient 679 680Why is this called *gradient* boosting? Because "fit what is still wrong" 681is a special case of gradient descent (`primer.ml.optimizers`), taken in the 682space of predictions instead of weights. 683 684$$ 685L(y, F) = \tfrac{1}{2}\,(y - F)^{2} 686\qquad\Longrightarrow\qquad 687r = -\frac{\partial L}{\partial F} = y - F 688$$ 689 690**Symbols** 691 692| Symbol | Meaning here | For house 4 | 693|---|---|---| 694| $y$ | the true value | 7 | 695| $F$ | the model's current prediction | $F_0 = 4$ | 696| $L(y, F)$ | the **loss**: half the squared miss (the ½ only tidies the slope) | $\frac{1}{2}(7 - 4)^2 = 4.5$ | 697| $\frac{\partial L}{\partial F}$ | the **derivative**: how fast the loss changes as the prediction $F$ is nudged up | $4 - 7 = -3$ | 698| $-\frac{\partial L}{\partial F}$ | the direction that lowers the loss fastest, called the **negative gradient** | 3 | 699| $r$ | the **residual**: what each tree is trained to predict | 3 | 700| $\Longrightarrow$ | "which gives" | | 701 702**In words:** "for squared error, the direction that most quickly reduces 703the loss at each example is simply the true value minus the prediction: the 704residual." 705 706**With the numbers:** house 4 has $y = 7$ and $F = 4$. Nudge $F$ up to 4.001 707and the loss falls from 4.5 to about 4.497, a slope of −3; the negative 708gradient is +3, which is exactly $7 - 4$. 709 710**In Python:** 711 712```python 713y, F, eps = 7.0, 4.0, 1e-6 714# ∂L/∂F, measured by nudging F both ways 715slope = (0.5 * (y - (F + eps)) ** 2 - 0.5 * (y - (F - eps)) ** 2) / (2 * eps) 716round(slope, 6) # → -3.0 717# r = -∂L/∂F is the plain residual y - F 718round(-slope, 6), y - F # → (3.0, 3.0) 719``` 720 721The payoff of the gradient view: swap in any loss with a slope and the same 722loop still works. For yes/no labels with the log loss (`primer.ml.losses`), 723$F$ is a score in log-odds and the negative gradient is $y - \sigma(F)$, the 724label minus the predicted probability ($\sigma$ is the **sigmoid**, which 725squashes a score into 0 to 1). Each tree then fits "how surprised were we 726by each example". 727 728**In code:** `GradientBoosting.negative_gradient` returns $y - F$ for `loss="squared"` and $y - \sigma(F)$ for `loss="log"`. 729 730### The update, and the learning rate 731 732$$ 733F_m(x) = F_{m-1}(x) + \eta\, h_m(x) 734$$ 735 736**Symbols** 737 738| Symbol | Meaning here | In the example | 739|---|---|---| 740| $x$ | one input (a house's size) | size 4 | 741| $m$ | the round number, 1, 2, …, $M$ | 1 | 742| $F_{m-1}(x)$ | the model's prediction before this round | $F_0(4) = 4$ | 743| $h_m(x)$ | this round's small tree, trained on the residuals | $h_1(4) = 2.5$ | 744| $\eta$ | the **learning rate** (Greek letter eta), also called **shrinkage**: the fraction of each tree's correction actually applied | 0.5 | 745| $F_m(x)$ | the prediction after this round | 5.25 | 746 747**In words:** "after each round, the new prediction is the old prediction 748plus a shrunken copy of the tree that was trained to fix it." 749 750**With the numbers:** big houses: $4 + 0.5 \times 2.5 = 5.25$; small houses: 751$4 + 0.5 \times (-2.5) = 2.75$. Mean squared error before: 752$(9 + 4 + 4 + 9)/4 = 6.5$; after: $(1.75^2 + 0.75^2 + 0.75^2 + 7531.75^2)/4 = 1.8125$. 754 755**In Python:** 756 757```python 758prices = [1, 2, 6, 7] 759eta = 0.5 760# F_0: the average price 761F0 = sum(prices) / len(prices) 762F0 # → 4.0 763residuals = [y - F0 for y in prices] 764residuals # → [-3.0, -2.0, 2.0, 3.0] 765# h_1: the stump predicts each side's average residual 766small, big = (residuals[0] + residuals[1]) / 2, (residuals[2] + residuals[3]) / 2 767h1 = [small, small, big, big] 768h1 # → [-2.5, -2.5, 2.5, 2.5] 769# F_1 = F_0 + η h_1 770F1 = [F0 + eta * h for h in h1] 771F1 # → [2.75, 2.75, 5.25, 5.25] 772# mean squared error before and after the round 773sum((y - F0) ** 2 for y in prices) / 4 # → 6.5 774sum((y - f) ** 2 for y, f in zip(prices, F1)) / 4 # → 1.8125 775``` 776 777Why not take the whole correction ($\eta = 1$)? Each tree is fitted to the 778training data, noise included. Taking the whole step lets the first few 779trees commit hard to whatever they saw; taking small steps means many trees 780must agree before the model moves far, which averages away some of the 781noise. The price is more rounds. 782 783 784 785**Reading it:** grey dots are 80 noisy samples of the dotted sine curve, and 786the blue line is the boosted model's prediction everywhere between 0 and 6. 787After 1 round the model is the average plus 0.3 of one small tree: a 788line with just two flat steps. After 5 rounds it has the rough shape. 789After 50 it follows the curve closely and has begun to jump for individual 790noisy points, the first sign of the overfitting the next figure measures. 791Every version is made of flat steps, because 792every tree predicts a constant in each leaf; the curve is built from many 793small staircases added together. 794 795 796 797**Reading it:** dashed lines are training error and solid lines are error on 798400 fresh points, per round, for three learning rates. Every training curve 799falls toward zero, since 200 rounds of trees can memorise 80 points. Each 800validation curve has a best round (the dot) and then rises, because later 801trees are fitting noise. With $\eta = 1$ the best comes at round 4 (0.122) 802and is poor; with $\eta = 0.1$ it comes at round 31 and is the lowest 803(0.110), close to the noise floor of 0.09 that no model can beat. Smaller 804steps generalize better but need more rounds, and every learning rate needs 805a stopping point chosen on validation data: early stopping, as in 806`primer.ml.regularization`. 807 808**In code:** `GradientBoosting` runs the loop and records the training loss after each round; `GradientBoosting.staged_loss` scores held-out data after each round; `boosting_worked_example` is the four-house table; `boosting_curves` sweeps the learning rate on `sine_data`. 809 810**Why it matters:** gradient-boosted trees (through libraries such as 811XGBoost, LightGBM and CatBoost) are the most common winning model on tabular 812data in practice. They add refinements this lesson leaves out, such as a 813second-order (Newton) step for each leaf's value, penalties on tree size, 814fast histogram-based split search, and native handling of missing values, 815but the loop is the one above. The two knobs that matter most are the ones 816you have met: tree depth and the learning rate, with the number of rounds 817chosen by early stopping. 818 819## When trees win, and when neural networks do 820 821**Everyday picture.** A spreadsheet and a photograph are both grids of 822numbers, but they carry meaning differently. In a spreadsheet each column 823means something on its own: "income is under 30,000" is a sentence a loan 824officer would write. In a photo, "pixel (212, 40) is brighter than 0.7" 825means nothing; the meaning is in how thousands of pixels are arranged. A 826tree asks questions of one column at a time, which is perfect for the 827spreadsheet and hopeless for the photo. A neural network builds its own 828features out of combinations of inputs, which is what the photo needs. 829 830**Tiny example.** A toy loan table: 800 training rows and 400 validation 831rows, five columns in their natural units: age in years, income in dollars 832(spanning a factor of 100), a count of late payments, a region code 0 to 5 833(where region 4 is not "twice region 2"), and one column of pure random 834noise. The label follows rules of the kind a lender writes (four or more 835late payments; under 30,000 and under 30 years old; two late payments in 836certain regions or on a very low income), with 5% of labels flipped at 837random. 838 839| model | what it was given | validation accuracy | 840|---|---|---| 841| always predict "fine" | nothing | 77.75% | 842| single tree, depth 5 | the raw table | 92.25% | 843| random forest, 50 trees | the raw table | 95.75% | 844| gradient boosting, 100 depth-3 trees | the raw table | 96.00% | 845| small neural net (32 hidden units) | the raw table | 77.75% | 846| same net | every column rescaled to mean 0, spread 1 | 86.25% | 847| same net | rescaled, plus log income and one column per region | 92.25% | 848 849 850 851**Reading it:** blue bars are tree models, orange bars are the same small 852neural network given three versions of the same table, and the dashed line 853is the score for ignoring the inputs and always predicting "fine". The 854trees read the table exactly as it came. The net on raw inputs sits on the 855dashed line: incomes around 50,000 swamp every other column and saturate 856its neurons, so it learns nothing. Rescaling rescues it partly; hand-made 857features (the logarithm of income, a yes/no column per region) rescue it 858more. Even then it only ties a single depth-5 tree, and the ensembles stay 859ahead. 860 861```mermaid 862flowchart TD 863 START{"what does one input look like?"} -->|"a row of a table:<br/>each column means<br/>something alone"| SIZE{"how much data?"} 864 START -->|"pixels, audio samples,<br/>words, sequences"| NN["neural network<br/>(often a pretrained one)"] 865 SIZE -->|"thousands to millions of rows"| GBT["gradient-boosted trees<br/>or a random forest first"] 866 SIZE -->|"huge, or mixed with<br/>text or images"| MIX["neural network, or trees<br/>on top of neural embeddings"] 867 GBT --> CHECK["compare against a neural net<br/>only if the gap matters"] 868``` 869 870**Reading it:** the first question is about the *shape* of one input, not 871about fashion. Tables go down the left; perceptual and sequential data go 872right. On the left, the size of the data decides: at typical business 873scale, start with trees. The bottom-right branch is common in practice: a 874neural network turns text or images into **embeddings** 875(`primer.ml.embeddings.word2vec`), and those numbers become extra columns 876for a boosted-tree model. 877 878Why trees fit tables so well, each point visible in this lesson's code: 879 880- **Units don't matter.** A tree only asks "is this bigger than that?", so 881 any order-keeping change to a column (dollars to thousands, a logarithm, 882 a square) leaves every prediction unchanged. A neural net multiplies and 883 adds columns, so their scales collide. 884- **Thresholds are native.** Rules like "four or more late payments" are 885 one question to a tree; a net must approximate the sharp edge with smooth 886 curves. 887- **Irrelevant columns are mostly ignored**, because a column that never 888 wins a split is never used. 889- **Modest data is enough.** A few hundred rows can grow a useful tree; a 890 net with thousands of weights needs far more to pin them down. 891 892Where neural networks win, and trees cannot follow: 893 894- **Perceptual and sequential data**: images, audio, text. The useful 895 features are built from arrangements of raw values, which is what 896 convolutions (`primer.ml.cnn_rnn`) and attention (`primer.ml.transformer`) 897 learn. 898- **Huge data and pretraining.** A net's capacity keeps paying off as data 899 grows, and a pretrained model brings knowledge from billions of examples. 900 A tree starts from nothing every time. 901- **Smooth trends and extrapolation.** A tree's leaves hold averages of 902 training values, so it can never predict outside the range it saw. The 903 four-house model predicts the same price for a house of size 40 as for 904 size 4. 905- **End-to-end training** with other neural parts, since a tree has no 906 gradient to pass along. 907 908In a careful benchmark on 45 tabular datasets of about 10,000 rows each 909(Grinsztajn, Oyallon and Varoquaux, 2022), tuned tree-based models remained 910ahead of tuned deep learning models. Their analysis names three reasons that 911match this lesson: trees shrug off uninformative columns, they respect each 912column's own axis, and they fit irregular, step-like functions easily. 913Research on neural networks 914for tables is active and the gap may narrow; the practical rule is to start 915with boosted trees on a table and make any other model beat them on your 916validation data. 917 918**In code:** `make_tabular` builds the loan table; `tabular_showdown` trains every model in the table above (the net is `primer.ml.neural_net.MLP`); `engineer_features` is the hand-made preparation the net needed. 919 920### Feature importance, and its limits 921 922**Everyday picture.** After a football season you want to know which 923players mattered. One way: count how often each player touched the ball in 924training. Another: bench each player for a real match and see how much the 925score suffers. The first is quick but credits whoever is busy; the second 926measures what the team actually depends on. 927 928Trees offer the first kind for free. **Impurity importance** adds up, for 929each feature, the impurity its splits removed (weighted by how many examples 930reached each split), measured on the training data. **Permutation 931importance** is the second kind: take held-out data, shuffle one column so 932it no longer lines up with the labels, and measure how much accuracy drops. 933 934**Tiny example.** The 30-tree forest scores 96.0% on the 400 validation 935rows. Shuffle the late-payments column and it scores 77.5%: a drop of 18.5 936points, so the model leans on that column heavily. Shuffle the noise column 937and it scores 95.75%, a drop of 0.25 points (one row in 400). 938 939$$ 940I_j = \text{acc}(X_{\text{val}}) - \text{acc}\big(X_{\text{val}} \text{ with column } j \text{ shuffled}\big) 941$$ 942 943**Symbols** 944 945| Symbol | Meaning here | For late payments | 946|---|---|---| 947| $j$ | the feature (column) being tested | late_payments | 948| $X_{\text{val}}$ | held-out rows the model never trained on | 400 rows | 949| $\text{acc}(\ldots)$ | the share of those rows the model gets right | 0.96 | 950| shuffled | the column's values randomly reordered: same values, links to the labels broken | 0.775 | 951| $I_j$ | the permutation importance of feature $j$: accuracy lost without it | 0.185 | 952 953**In words:** "a feature's importance is how much accuracy the model loses 954on fresh data when that feature is scrambled." 955 956**With the numbers:** late payments $0.96 - 0.775 = 0.185$; noise 957$0.96 - 0.9575 = 0.0025$. 958 959**In Python:** 960 961```python 962# validation rows answered correctly, out of 400 963correct_of_400 = {"intact": 384, "late_payments shuffled": 310, "noise shuffled": 383} 964acc = {k: v / 400 for k, v in correct_of_400.items()} 965# I_j = acc(X_val) - acc(X_val with column j shuffled) 966round(acc["intact"] - acc["late_payments shuffled"], 4) # → 0.185 967round(acc["intact"] - acc["noise shuffled"], 4) # → 0.0025 968``` 969 970 971 972**Reading it:** the left panel is impurity importance from training, as 973shares that add to 100%; the right is permutation importance on validation 974data, in accuracy lost. Both agree the real columns matter. They disagree 975about noise: on the left it gets 11% of the credit, because deep trees can 976always find some threshold on a continuous random column that tidies up a 977few training rows. On the right, scrambling it costs almost nothing, 978because none of those splits help on new data. 979 980The limits worth remembering: 981 982- **Impurity importance favours columns with many distinct values** 983 (continuous numbers, IDs), since they offer more thresholds to overfit 984 with. Measure on held-out data instead. 985- **Correlated columns split the credit.** If income appears twice (in 986 dollars and in thousands), each copy looks half as important, and 987 shuffling one does little because the other covers for it. 988- **Importance is not cause.** It says what *this model* relies on to 989 predict, not what would change the outcome in the world. 990 991A single shallow tree is the one truly readable model here: print 992`DecisionTree.rules` and you are reading the entire model. A forest of 993hundreds of deep trees is not readable, and importances are a summary of it, 994not an explanation. 995 996**In code:** `permutation_importance` shuffles one column at a time on held-out data; `DecisionTree.feature_importances` and `RandomForest.feature_importances` are the impurity kind. 997 998## In 20 seconds 999 1000- **A decision tree** asks yes/no questions about one column at a time, 1001 choosing each question greedily to leave the purest piles (lowest 1002 weighted Gini impurity or entropy), until a stopping rule says stop. 1003- **Deep trees overfit**: a question for every example gives 100% on 1004 training data and poor results on new data. Depth is the capacity knob. 1005- **Random forests** average many deep trees, each grown on a bootstrap 1006 sample with random feature subsets. Averaging removes the variance the 1007 trees don't share; decorrelating them lowers the part they do. 1008- **Gradient boosting** adds small trees one at a time, each fit to the 1009 residuals (the negative gradient of the loss), shrunk by a learning rate, 1010 with the number of rounds set by early stopping. 1011- **On tables, trees usually win**: no scaling, native thresholds, modest 1012 data. Neural networks win on images, audio, text and huge datasets. 1013 1014## Self-test questions 1015 1016**Why is Gini impurity 0.5 for a pile that is half spam and half not?** 1017It is the chance that two emails drawn at random (with replacement) carry 1018different labels: $1 - (0.5^2 + 0.5^2) = 0.5$. For two labels that is the 1019most mixed a pile can be. 1020 1021**Why weight each child pile by its size when scoring a split?** 1022Otherwise a question that peels off one example into a tiny pure pile 1023would look as good as one that sorts half the data cleanly. Weighting by 1024size measures how much of the data the question actually tidied. 1025 1026**Why does a tree need no feature scaling, when a neural network does?** 1027A tree only compares one column against a threshold, so any change that 1028keeps the order of values (rescaling, logarithms) produces the same splits 1029and the same predictions. A network multiplies and adds columns together, 1030so a column measured in tens of thousands drowns the others and saturates 1031its neurons. 1032 1033**A tree scores 100% on training data and 80% on validation. What happened, 1034and what are two fixes?** 1035It overfitted: it kept splitting until each leaf fenced off individual 1036noisy examples. Limit its depth (or require a minimum number of examples per 1037leaf, or prune), or replace it with a random forest that averages many such 1038trees. 1039 1040**Why does a random forest use random feature subsets, not just bootstrap 1041samples?** 1042The forest's variance is $\rho\sigma^2 + (1 - \rho)\sigma^2/B$. More trees 1043only shrink the second term; the floor is set by the correlation $\rho$ 1044between trees. With bagging alone every tree tends to pick the same strong 1045feature first and they stay correlated. Random subsets force different 1046trees down different paths, lowering $\rho$. 1047 1048**Does adding more trees overfit a random forest? Does adding more rounds 1049overfit gradient boosting?** 1050More trees in a forest does not: accuracy rises and then levels off, only 1051costing time. More rounds of boosting does: each round fits the training 1052residuals more closely, so validation error reaches a minimum and then 1053climbs. Boosting needs early stopping; forests don't. 1054 1055**Why is the residual the right target for each boosting tree?** 1056For squared-error loss $\frac{1}{2}(y - F)^2$, the negative derivative with 1057respect to the prediction $F$ is $y - F$, the residual. Fitting a tree to it 1058and taking a step is gradient descent on the predictions. With another 1059loss, the tree fits that loss's negative gradient instead, such as $y - p$ 1060for log loss. 1061 1062**What does a smaller learning rate buy in gradient boosting, and what does 1063it cost?** 1064Each tree contributes only a fraction of its correction, so no single noisy 1065tree can move the model far and many trees must agree. That usually 1066generalizes better (0.110 against 0.122 in this lesson's sweep). It costs 1067more rounds, so more training and prediction time. 1068 1069**Why can't a boosted-tree model predict a house price above the highest 1070price it trained on?** 1071Every leaf predicts an average of training values, and the model is a sum of 1072such leaves anchored at the training mean. Beyond the edge of the training 1073data every question gives the same answer as at the edge, so the prediction 1074stays flat. 1075 1076**What is wrong with trusting impurity-based feature importance?** 1077It is measured on training data, where splits on noise still tidy up piles. 1078It favours columns with many distinct values and splits credit between 1079correlated columns. Permutation importance on held-out data is more honest, 1080and neither measures cause and effect. 1081 1082**When would you choose a neural network over gradient-boosted trees?** 1083When one input is an image, audio clip, text or other sequence whose 1084meaning lies in the arrangement of raw values; when the data is huge or a 1085pretrained model can be reused; when predictions must extrapolate smoothly; 1086or when the model must be trained end to end with other neural parts. 1087 1088## The papers behind this lesson 1089 1090- **Breiman, Friedman, Olshen and Stone, *Classification and Regression 1091 Trees* (1984)**: https://doi.org/10.1201/9781315139470. The CART book: 1092 binary trees split by Gini impurity, regression trees with averaged 1093 leaves, and cost-complexity pruning, the recipe this lesson's tree 1094 follows. 1095- **Quinlan, *Induction of Decision Trees*, Machine Learning 1 (1986)**: 1096 https://doi.org/10.1007/BF00116251. ID3, which grows trees by choosing 1097 the split with the largest information gain (drop in entropy). 1098- **Breiman, *Bagging Predictors*, Machine Learning 24 (1996)**: 1099 https://doi.org/10.1007/BF00058655. Showed that averaging models trained 1100 on bootstrap samples reduces the error of unstable learners such as 1101 trees. 1102- **Breiman, *Random Forests*, Machine Learning 45 (2001)**: 1103 https://doi.org/10.1023/A:1010933404324. Added random feature subsets at 1104 each split, out-of-bag error estimates, and permutation importance. 1105 [Annotated companion](../../papers/random-forests.html) 1106- **Friedman, *Greedy Function Approximation: A Gradient Boosting Machine*, 1107 Annals of Statistics 29 (2001)**: https://doi.org/10.1214/aos/1013203451. 1108 Framed boosting as gradient descent in function space, fitting each tree 1109 to the negative gradient of any differentiable loss, with shrinkage. 1110 [Annotated companion](../../papers/gradient-boosting-machine.html) 1111- **Chen and Guestrin, *XGBoost: A Scalable Tree Boosting System* (2016)**: 1112 https://arxiv.org/abs/1603.02754. A regularized, second-order boosting 1113 objective with fast, sparsity-aware split finding, which made boosted 1114 trees the default on tabular problems. 1115 [Annotated companion](../../papers/xgboost.html) 1116- **Grinsztajn, Oyallon and Varoquaux, *Why do tree-based models still 1117 outperform deep learning on tabular data?* (2022)**: 1118 https://arxiv.org/abs/2207.08815. A benchmark on 45 medium-sized tabular 1119 datasets where tuned tree ensembles beat tuned neural networks, and an 1120 analysis of why. 1121 1122## Further reading 1123 1124- scikit-learn user guide, *Decision Trees*: https://scikit-learn.org/stable/modules/tree.html 1125- scikit-learn user guide, *Ensembles: gradient boosting, random forests, bagging*: https://scikit-learn.org/stable/modules/ensemble.html 1126- scikit-learn user guide, *Permutation feature importance*: https://scikit-learn.org/stable/modules/permutation_importance.html 1127- XGBoost documentation, *Introduction to Boosted Trees*: https://xgboost.readthedocs.io/en/stable/tutorials/model.html 1128- Hastie, Tibshirani and Friedman, *The Elements of Statistical Learning* (free PDF from the authors; chapters 9, 10 and 15 cover trees, boosting and random forests): https://hastie.su.domains/ElemStatLearn/ 1129- Strobl et al., *Bias in random forest variable importance measures* (2007): https://doi.org/10.1186/1471-2105-8-25 1130- Grinsztajn et al., *Why do tree-based models still outperform deep learning on tabular data?* (2022): https://arxiv.org/abs/2207.08815 1131""" 1132 1133from __future__ import annotations 1134 1135import functools 1136import math 1137from dataclasses import dataclass, field 1138 1139import numpy as np 1140 1141from primer._show import banner, say, table, takeaway 1142 1143# --------------------------------------------------------------------------- 1144# 1. Impurity: how mixed-up is a pile of labels? 1145# --------------------------------------------------------------------------- 1146 1147 1148def _class_shares(y: np.ndarray) -> np.ndarray: 1149 # Shares of each label present; absent labels contribute nothing to either measure. 1150 _, counts = np.unique(y, return_counts=True) 1151 return counts / counts.sum() 1152 1153 1154def gini(y: np.ndarray) -> float: 1155 """Gini impurity, 1 - Σ p_k²: the chance two labels drawn at random (with replacement) disagree.""" 1156 if len(y) == 0: 1157 return 0.0 1158 p = _class_shares(y) 1159 return float(1.0 - np.sum(p**2)) 1160 1161 1162def entropy(y: np.ndarray) -> float: 1163 """Entropy in bits, -Σ p_k log2 p_k: how many yes/no questions a label still costs on average.""" 1164 if len(y) == 0: 1165 return 0.0 1166 p = _class_shares(y) 1167 return float(-np.sum(p * np.log2(p))) 1168 1169 1170def split_impurity(y_left: np.ndarray, y_right: np.ndarray, impurity=gini) -> float: 1171 """Impurity after a split: each side's impurity, weighted by its share of the examples.""" 1172 n = len(y_left) + len(y_right) 1173 return len(y_left) / n * impurity(y_left) + len(y_right) / n * impurity(y_right) 1174 1175 1176# --------------------------------------------------------------------------- 1177# 2. Choosing a split: try every feature and every threshold 1178# --------------------------------------------------------------------------- 1179 1180 1181@dataclass(frozen=True) 1182class Split: 1183 """The best question found for a node: "is feature <= threshold?", and the impurity it leaves.""" 1184 1185 feature: int 1186 threshold: float 1187 impurity: float 1188 1189 1190def _side_impurities(counts: np.ndarray, n_side: np.ndarray, criterion: str) -> np.ndarray: 1191 """Impurity of one side for every candidate threshold at once. counts: (candidates, classes).""" 1192 p = counts / n_side[:, None] 1193 if criterion == "gini": 1194 return 1.0 - np.sum(p**2, axis=1) 1195 # 0·log 0 counts as 0: an absent class adds no uncertainty. 1196 with np.errstate(divide="ignore", invalid="ignore"): 1197 return -np.sum(np.where(p > 0, p * np.log2(p), 0.0), axis=1) 1198 1199 1200def best_split( 1201 X: np.ndarray, 1202 y: np.ndarray, 1203 criterion: str = "gini", 1204 features: np.ndarray | None = None, 1205 min_samples_leaf: int = 1, 1206) -> Split | None: 1207 """The feature and threshold whose split leaves the lowest weighted impurity, or None. 1208 1209 `criterion` is "gini" or "entropy" for class labels (integers 0..K-1), or 1210 "squared" for numbers (impurity = variance, as in a regression tree). 1211 Sorting each feature once turns "try every threshold" into running totals, 1212 so a node costs O(n log n) per feature instead of O(n²). 1213 """ 1214 n = len(y) 1215 if n < 2 * min_samples_leaf: 1216 return None 1217 if criterion == "squared": 1218 parent = float(np.var(y)) 1219 else: 1220 parent = gini(y) if criterion == "gini" else entropy(y) 1221 if parent <= 1e-12: # already pure: nothing left to separate 1222 return None 1223 features = np.arange(X.shape[1]) if features is None else features 1224 best: Split | None = None 1225 n_left = np.arange(1, n) # candidate i puts the first i sorted examples on the left 1226 n_right = n - n_left 1227 for f in features: 1228 order = np.argsort(X[:, f], kind="stable") 1229 xs, ys = X[order, f], y[order] 1230 # A threshold can only sit between two different values; equal values must stay together. 1231 valid = (xs[1:] > xs[:-1]) & (n_left >= min_samples_leaf) & (n_right >= min_samples_leaf) 1232 if not valid.any(): 1233 continue 1234 if criterion == "squared": 1235 # Sum of squared errors from running sums: Σy² - (Σy)²/n on each side. 1236 s, s2 = np.cumsum(ys)[:-1], np.cumsum(ys**2)[:-1] 1237 tot, tot2 = ys.sum(), (ys**2).sum() 1238 sse = (s2 - s**2 / n_left) + ((tot2 - s2) - (tot - s) ** 2 / n_right) 1239 weighted = sse / n 1240 else: 1241 onehot = np.eye(int(y.max()) + 1)[ys] # (n, classes) 1242 left = np.cumsum(onehot, axis=0)[:-1] # class counts left of each candidate 1243 right = onehot.sum(axis=0) - left 1244 weighted = (n_left * _side_impurities(left, n_left, criterion) + n_right * _side_impurities(right, n_right, criterion)) / n 1245 weighted = np.where(valid, weighted, np.inf) 1246 i = int(np.argmin(weighted)) 1247 # Strictly lower wins, so ties go to the earliest feature: the tree is reproducible. 1248 if best is None or weighted[i] < best.impurity - 1e-12: 1249 best = Split(int(f), float((xs[i] + xs[i + 1]) / 2), float(weighted[i])) 1250 return best 1251 1252 1253def candidate_splits(X: np.ndarray, y: np.ndarray) -> list[Split]: 1254 """Every question worth asking at one node, with the Gini impurity it would leave. 1255 1256 Thresholds sit halfway between neighbouring distinct values of a 1257 feature; anywhere else in the gap gives the same split. 1258 """ 1259 out = [] 1260 for f in range(X.shape[1]): 1261 values = np.unique(X[:, f]) 1262 for t in (values[1:] + values[:-1]) / 2: 1263 left = X[:, f] <= t 1264 out.append(Split(f, float(t), split_impurity(y[left], y[~left]))) 1265 return out 1266 1267# --------------------------------------------------------------------------- 1268# 3. The tree: ask, split, repeat 1269# --------------------------------------------------------------------------- 1270 1271 1272@dataclass 1273class Node: 1274 """One box of the flowchart. A leaf has no question and carries the prediction in `value`.""" 1275 1276 value: np.ndarray # class shares (classification) or [mean] (regression) 1277 n_samples: int 1278 impurity: float 1279 feature: int | None = None 1280 threshold: float | None = None 1281 left: "Node | None" = None 1282 right: "Node | None" = None 1283 1284 @property 1285 def is_leaf(self) -> bool: 1286 return self.feature is None 1287 1288 1289@dataclass 1290class DecisionTree: 1291 """A CART-style decision tree, grown greedily from the top. 1292 1293 criterion: "gini" or "entropy" to classify integer labels, "squared" to 1294 predict numbers. max_depth None grows until every leaf is pure. 1295 max_features limits how many randomly chosen features each node may try 1296 ("sqrt" or an int); that is the random forest's extra ingredient. 1297 """ 1298 1299 max_depth: int | None = None 1300 criterion: str = "gini" 1301 min_samples_leaf: int = 1 1302 max_features: int | str | None = None 1303 seed: int = 0 1304 root: Node | None = field(default=None, init=False) 1305 1306 def fit(self, X: np.ndarray, y: np.ndarray, n_classes: int | None = None) -> "DecisionTree": 1307 X = np.asarray(X, dtype=float) 1308 self.regression = self.criterion == "squared" 1309 y = np.asarray(y, dtype=float if self.regression else int) 1310 # A bootstrap sample can miss a class; the forest passes the true count so shares line up. 1311 self.n_classes = None if self.regression else (n_classes or int(y.max()) + 1) 1312 self.n_features = X.shape[1] 1313 self._importance = np.zeros(self.n_features) 1314 self._rng = np.random.default_rng(self.seed) 1315 self._n_total = len(y) 1316 self.root = self._grow(X, y, depth=0) 1317 return self 1318 1319 def _leaf_value(self, y: np.ndarray) -> np.ndarray: 1320 if self.regression: 1321 return np.array([y.mean()]) 1322 return np.bincount(y, minlength=self.n_classes) / len(y) 1323 1324 def _impurity(self, y: np.ndarray) -> float: 1325 if self.regression: 1326 return float(np.var(y)) 1327 return gini(y) if self.criterion == "gini" else entropy(y) 1328 1329 def _features_to_try(self) -> np.ndarray: 1330 d = self.n_features 1331 k = {None: d, "sqrt": max(1, int(math.sqrt(d)))}.get(self.max_features, self.max_features) 1332 if k >= d: 1333 return np.arange(d) 1334 # A fresh random subset at every node keeps the trees of a forest different from each other. 1335 return np.sort(self._rng.choice(d, size=k, replace=False)) 1336 1337 def _grow(self, X: np.ndarray, y: np.ndarray, depth: int) -> Node: 1338 node = Node(self._leaf_value(y), len(y), self._impurity(y)) 1339 if self.max_depth is not None and depth >= self.max_depth: 1340 return node 1341 split = best_split(X, y, self.criterion, self._features_to_try(), self.min_samples_leaf) 1342 if split is None: 1343 return node 1344 go_left = X[:, split.feature] <= split.threshold 1345 # Credit the feature with the impurity it removed, weighted by how many examples reached here. 1346 self._importance[split.feature] += len(y) / self._n_total * (node.impurity - split.impurity) 1347 node.feature, node.threshold = split.feature, split.threshold 1348 node.left = self._grow(X[go_left], y[go_left], depth + 1) 1349 node.right = self._grow(X[~go_left], y[~go_left], depth + 1) 1350 return node 1351 1352 def _values(self, X: np.ndarray) -> np.ndarray: 1353 """Route every row to its leaf and return the leaf values, (n, classes) or (n, 1).""" 1354 X = np.asarray(X, dtype=float) 1355 out = np.empty((len(X), len(self.root.value))) 1356 1357 def route(node: Node, rows: np.ndarray) -> None: 1358 if node.is_leaf: 1359 out[rows] = node.value 1360 return 1361 go_left = X[rows, node.feature] <= node.threshold 1362 route(node.left, rows[go_left]) 1363 route(node.right, rows[~go_left]) 1364 1365 route(self.root, np.arange(len(X))) 1366 return out 1367 1368 def predict_proba(self, X: np.ndarray) -> np.ndarray: 1369 """Class shares of the leaf each row lands in, (n, classes).""" 1370 return self._values(X) 1371 1372 def predict(self, X: np.ndarray) -> np.ndarray: 1373 """The leaf's mean for regression, or the leaf's majority class.""" 1374 values = self._values(X) 1375 return values[:, 0] if self.regression else values.argmax(axis=1) 1376 1377 @property 1378 def depth(self) -> int: 1379 def d(node: Node) -> int: 1380 return 0 if node.is_leaf else 1 + max(d(node.left), d(node.right)) 1381 1382 return d(self.root) 1383 1384 @property 1385 def n_leaves(self) -> int: 1386 def count(node: Node) -> int: 1387 return 1 if node.is_leaf else count(node.left) + count(node.right) 1388 1389 return count(self.root) 1390 1391 @property 1392 def feature_importances(self) -> np.ndarray: 1393 """Impurity removed by each feature's splits, as shares that sum to 1.""" 1394 total = self._importance.sum() 1395 return self._importance / total if total > 0 else self._importance 1396 1397 def rules(self, names: list[str] | None = None, classes: list[str] | None = None) -> list[str]: 1398 """The tree as nested if/else lines: the whole model, readable by a person.""" 1399 names = names or [f"x{i}" for i in range(self.n_features)] 1400 lines: list[str] = [] 1401 1402 def leaf_text(node: Node) -> str: 1403 if self.regression: 1404 return f"predict {node.value[0]:.3g}" 1405 k = int(node.value.argmax()) 1406 label = classes[k] if classes else str(k) 1407 noun = "example" if node.n_samples == 1 else "examples" 1408 return f"predict {label} ({node.n_samples} {noun}, {node.value[k]:.0%} agree)" 1409 1410 def walk(node: Node, indent: str) -> None: 1411 if node.is_leaf: 1412 lines.append(indent + leaf_text(node)) 1413 return 1414 lines.append(f"{indent}if {names[node.feature]} <= {node.threshold:g}:") 1415 walk(node.left, indent + " ") 1416 lines.append(f"{indent}else: # {names[node.feature]} > {node.threshold:g}") 1417 walk(node.right, indent + " ") 1418 1419 walk(self.root, "") 1420 return lines 1421 1422 1423# --------------------------------------------------------------------------- 1424# 4. Worked examples and toy data 1425# --------------------------------------------------------------------------- 1426 1427SPAM_FEATURES = ["links", "known_sender"] 1428 1429 1430def spam_emails() -> tuple[np.ndarray, np.ndarray, list[str]]: 1431 """The eight emails of the worked example: (links, known sender?) and 1 = spam. 1432 1433 | email | links | known sender | spam? | 1434 |---|---|---|---| 1435 | 1 | 0 | yes | no | 1436 | 2 | 1 | yes | no | 1437 | 3 | 4 | yes | no | 1438 | 4 | 0 | no | no | 1439 | 5 | 3 | no | yes | 1440 | 6 | 5 | no | yes | 1441 | 7 | 6 | no | yes | 1442 | 8 | 1 | no | yes | 1443 """ 1444 X = np.array([[0, 1], [1, 1], [4, 1], [0, 0], [3, 0], [5, 0], [6, 0], [1, 0]], dtype=float) 1445 y = np.array([0, 0, 0, 0, 1, 1, 1, 1]) 1446 return X, y, list(SPAM_FEATURES) 1447 1448 1449def moons_split(n: int = 500, noise: float = 0.35, n_train: int = 300, seed: int = 1): 1450 """Noisy two-moons points (`primer.ml.neural_net.make_moons`), cut into training and validation sets.""" 1451 from primer.ml.neural_net import make_moons 1452 1453 X, y = make_moons(n=n, noise=noise, seed=seed) 1454 # make_moons lists one moon, then the other; shuffle so both sets hold both classes. 1455 order = np.random.default_rng(seed).permutation(n) 1456 X, y = X[order], y[order].astype(int) 1457 return X[:n_train], y[:n_train], X[n_train:], y[n_train:] 1458 1459 1460def _accuracy(model, X: np.ndarray, y: np.ndarray) -> float: 1461 return float(np.mean(model.predict(X) == y)) 1462 1463 1464def depth_sweep(depths=(1, 2, 3, 4, 5, 6, 8, 10, 12, None)) -> list[dict]: 1465 """Train and validation accuracy of one tree per depth limit on the noisy moons.""" 1466 X, y, X_val, y_val = moons_split() 1467 rows = [] 1468 for depth in depths: 1469 tree = DecisionTree(max_depth=depth).fit(X, y) 1470 rows.append(dict(depth=depth, train_accuracy=_accuracy(tree, X, y), val_accuracy=_accuracy(tree, X_val, y_val), leaves=tree.n_leaves)) 1471 return rows 1472 1473 1474# --------------------------------------------------------------------------- 1475# 5. Random forests: bagging plus random feature subsets 1476# --------------------------------------------------------------------------- 1477 1478 1479def bootstrap_sample(n: int, rng: np.random.Generator) -> np.ndarray: 1480 """n row indices drawn with replacement: some rows twice or more, about a third not at all.""" 1481 return rng.integers(0, n, size=n) 1482 1483 1484def out_of_bag_fraction(n: int) -> float: 1485 """(1 - 1/n)^n: the chance a given row is never drawn in n draws. Tends to 1/e ≈ 0.368.""" 1486 return (1 - 1 / n) ** n 1487 1488 1489def averaged_variance(sigma2: float, rho: float, n_trees: int) -> float: 1490 """Variance of the average of n_trees predictions, each with variance sigma2 and pairwise correlation rho. 1491 1492 ρσ² + (1 - ρ)σ²/B: more trees shrink only the second term, so the 1493 correlation between trees sets the floor. Random feature subsets exist 1494 to push ρ down. 1495 """ 1496 return rho * sigma2 + (1 - rho) * sigma2 / n_trees 1497 1498 1499@dataclass 1500class RandomForest: 1501 """Many deep trees, each grown on its own bootstrap sample and trying only 1502 a random subset of features at every node; their class shares are averaged.""" 1503 1504 n_trees: int = 100 1505 max_depth: int | None = None 1506 max_features: int | str | None = "sqrt" 1507 seed: int = 0 1508 trees: list[DecisionTree] = field(default_factory=list, init=False) 1509 1510 def fit(self, X: np.ndarray, y: np.ndarray) -> "RandomForest": 1511 X, y = np.asarray(X, dtype=float), np.asarray(y, dtype=int) 1512 rng = np.random.default_rng(self.seed) 1513 n_classes = int(y.max()) + 1 1514 self.trees = [] 1515 for _ in range(self.n_trees): 1516 rows = bootstrap_sample(len(y), rng) 1517 # Each tree gets its own seed, so its feature subsets differ from its neighbours'. 1518 tree = DecisionTree(max_depth=self.max_depth, max_features=self.max_features, seed=int(rng.integers(2**31))) 1519 self.trees.append(tree.fit(X[rows], y[rows], n_classes=n_classes)) 1520 return self 1521 1522 def predict_proba(self, X: np.ndarray) -> np.ndarray: 1523 return np.mean([t.predict_proba(X) for t in self.trees], axis=0) 1524 1525 def predict(self, X: np.ndarray) -> np.ndarray: 1526 return self.predict_proba(X).argmax(axis=1) 1527 1528 @property 1529 def feature_importances(self) -> np.ndarray: 1530 """Each tree's impurity importance, averaged over the forest.""" 1531 return np.mean([t.feature_importances for t in self.trees], axis=0) 1532 1533 1534def forest_curve(n_trees=(1, 2, 3, 5, 10, 20, 50, 100), seed: int = 0) -> list[dict]: 1535 """Validation accuracy of a forest on the noisy moons as trees are added. 1536 1537 One forest of max(n_trees) is grown; the first k trees' average gives the 1538 k-tree forest, exactly as if it had been grown alone. 1539 """ 1540 X, y, X_val, y_val = moons_split() 1541 forest = RandomForest(n_trees=max(n_trees), seed=seed).fit(X, y) 1542 probas = np.cumsum([t.predict_proba(X_val) for t in forest.trees], axis=0) 1543 single = DecisionTree().fit(X, y) 1544 return [ 1545 dict(n_trees=k, val_accuracy=float(np.mean(probas[k - 1].argmax(axis=1) == y_val)), single_tree=_accuracy(single, X_val, y_val)) 1546 for k in n_trees 1547 ] 1548 1549 1550# --------------------------------------------------------------------------- 1551# 6. Gradient boosting: each small tree fixes what the others still get wrong 1552# --------------------------------------------------------------------------- 1553 1554 1555def _sigmoid(z: np.ndarray) -> np.ndarray: 1556 return 1 / (1 + np.exp(-z)) 1557 1558 1559@dataclass 1560class GradientBoosting: 1561 """F_m = F_{m-1} + η·h_m, where each h_m is a small regression tree fit to 1562 the negative gradient of the loss (the residuals, for squared loss). 1563 1564 loss="squared" predicts numbers; loss="log" classifies 0/1 labels, with F 1565 as log-odds. `train_loss` holds the training loss before any tree and 1566 after each round: mean squared error, or cross-entropy for "log". 1567 """ 1568 1569 n_rounds: int = 100 1570 learning_rate: float = 0.1 1571 max_depth: int = 2 1572 loss: str = "squared" 1573 trees: list[DecisionTree] = field(default_factory=list, init=False) 1574 train_loss: list[float] = field(default_factory=list, init=False) 1575 1576 @staticmethod 1577 def negative_gradient(y: np.ndarray, F: np.ndarray, loss: str) -> np.ndarray: 1578 """-∂L/∂F for each example: the direction that most quickly reduces its loss. 1579 1580 Squared loss ½(y - F)² gives y - F, the plain residual. Log loss 1581 gives y - sigmoid(F): the label minus the predicted probability. 1582 """ 1583 return y - F if loss == "squared" else y - _sigmoid(F) 1584 1585 def _loss(self, y: np.ndarray, F: np.ndarray) -> float: 1586 if self.loss == "squared": 1587 return float(np.mean((y - F) ** 2)) 1588 p = np.clip(_sigmoid(F), 1e-12, 1 - 1e-12) 1589 return float(-np.mean(y * np.log(p) + (1 - y) * np.log(1 - p))) 1590 1591 def fit(self, X: np.ndarray, y: np.ndarray) -> "GradientBoosting": 1592 X, y = np.asarray(X, dtype=float), np.asarray(y, dtype=float) 1593 # F_0: the best single constant. The mean for squared loss; the log-odds of the base rate for log loss. 1594 mean = y.mean() 1595 self.f0 = mean if self.loss == "squared" else math.log(mean / (1 - mean)) 1596 F = np.full(len(y), self.f0) 1597 self.trees, self.train_loss = [], [self._loss(y, F)] 1598 for _ in range(self.n_rounds): 1599 residual = self.negative_gradient(y, F, self.loss) 1600 tree = DecisionTree(max_depth=self.max_depth, criterion="squared").fit(X, residual) 1601 # Take only a fraction η of the step: many small corrections generalize better than a few big ones. 1602 F = F + self.learning_rate * tree.predict(X) 1603 self.trees.append(tree) 1604 self.train_loss.append(self._loss(y, F)) 1605 return self 1606 1607 def staged_scores(self, X: np.ndarray) -> np.ndarray: 1608 """F_0, F_1, ..., F_M for every row: (rounds + 1, n).""" 1609 steps = [np.full(len(X), self.f0)] + [self.learning_rate * t.predict(X) for t in self.trees] 1610 return np.cumsum(steps, axis=0) 1611 1612 def staged_loss(self, X: np.ndarray, y: np.ndarray) -> list[float]: 1613 """The loss on (X, y) before any tree and after each round: the validation curve.""" 1614 return [self._loss(np.asarray(y, dtype=float), F) for F in self.staged_scores(X)] 1615 1616 def predict(self, X: np.ndarray) -> np.ndarray: 1617 F = self.staged_scores(X)[-1] 1618 return F if self.loss == "squared" else (F > 0).astype(int) 1619 1620 1621def boosting_worked_example(learning_rate: float = 0.5) -> dict: 1622 """Four houses (size 1..4, price 1, 2, 6, 7) and one round of boosting with a one-question tree.""" 1623 X, y = np.array([[1.0], [2.0], [3.0], [4.0]]), np.array([1.0, 2.0, 6.0, 7.0]) 1624 model = GradientBoosting(n_rounds=1, learning_rate=learning_rate, max_depth=1).fit(X, y) 1625 F0 = np.full(4, model.f0) 1626 residuals = GradientBoosting.negative_gradient(y, F0, "squared") 1627 return dict( 1628 F0=model.f0, 1629 residuals=residuals.tolist(), 1630 stump=model.trees[0].predict(X).tolist(), 1631 F1=model.predict(X).tolist(), 1632 mse=model.train_loss, 1633 ) 1634 1635 1636def sine_data(n: int, noise: float = 0.3, seed: int = 0) -> tuple[np.ndarray, np.ndarray]: 1637 """n points of y = sin(x) + noise for x in [0, 6]: a curve for regression trees to approximate.""" 1638 rng = np.random.default_rng(seed) 1639 x = rng.uniform(0, 6, n) 1640 return x[:, None], np.sin(x) + rng.normal(0, noise, n) 1641 1642 1643def boosting_curves(learning_rates=(1.0, 0.3, 0.1), n_rounds: int = 200, max_depth: int = 2) -> list[dict]: 1644 """Training and validation mean squared error per round on 80 noisy sine points, for each learning rate.""" 1645 X, y = sine_data(80, seed=0) 1646 X_val, y_val = sine_data(400, seed=1) 1647 rows = [] 1648 for lr in learning_rates: 1649 model = GradientBoosting(n_rounds=n_rounds, learning_rate=lr, max_depth=max_depth).fit(X, y) 1650 val = model.staged_loss(X_val, y_val) 1651 rows.append(dict(learning_rate=lr, train_loss=model.train_loss, val_loss=val, best_round=int(np.argmin(val)))) 1652 return rows 1653 1654 1655# --------------------------------------------------------------------------- 1656# 7. When trees win: a tabular showdown 1657# --------------------------------------------------------------------------- 1658 1659TABULAR_FEATURES = ["age", "income", "late_payments", "region", "noise"] 1660 1661 1662def make_tabular(n: int = 1200, n_train: int = 800, seed: int = 0): 1663 """A toy loan table with the mix real spreadsheets have. 1664 1665 age in years, income in dollars (spanning 100×), a count of late 1666 payments, a region code 0..5 whose numbers mean nothing in order, and a 1667 column of pure noise. The label (1 = the loan went bad) follows 1668 threshold rules of the kind a lender writes, with 5% of labels flipped. 1669 Returns X_train, y_train, X_val, y_val, feature names. 1670 """ 1671 rng = np.random.default_rng(seed) 1672 age = rng.uniform(18, 80, n) 1673 income = np.exp(rng.normal(np.log(50_000), 0.7, n)) 1674 late = rng.poisson(1.2, n) 1675 region = rng.integers(0, 6, n) 1676 noise = rng.normal(0, 1, n) 1677 bad = (late >= 4) | ((income < 30_000) & (age < 30)) | (np.isin(region, [1, 4]) & (late >= 2)) | ((income < 20_000) & (late >= 2)) 1678 flip = rng.random(n) < 0.05 1679 y = (bad ^ flip).astype(int) 1680 X = np.c_[age, income, late, region, noise] 1681 return X[:n_train], y[:n_train], X[n_train:], y[n_train:], list(TABULAR_FEATURES) 1682 1683 1684def permutation_importance(model, X: np.ndarray, y: np.ndarray, seed: int = 0) -> np.ndarray: 1685 """Accuracy lost on held-out data when one column is shuffled, per feature. 1686 1687 Shuffling breaks the link between that column and the label while 1688 keeping its values, so the drop measures how much the model relies on it 1689 for data it did not train on. 1690 """ 1691 rng = np.random.default_rng(seed) 1692 base = _accuracy(model, X, y) 1693 drops = [] 1694 for f in range(X.shape[1]): 1695 shuffled = X.copy() 1696 shuffled[:, f] = rng.permutation(shuffled[:, f]) 1697 drops.append(base - _accuracy(model, shuffled, y)) 1698 return np.array(drops) 1699 1700 1701def engineer_features(X: np.ndarray) -> np.ndarray: 1702 """What a neural network needs done by hand before it can read the loan table. 1703 1704 Income becomes its logarithm, so a raise from 20k to 40k counts as much 1705 as one from 100k to 200k. The region code becomes six yes/no columns, 1706 because region 4 is not "twice region 2". Columns: age, log income, late 1707 payments, region_0..region_5, noise. 1708 """ 1709 region = np.eye(6)[X[:, 3].astype(int)] 1710 return np.c_[X[:, 0], np.log(X[:, 1]), X[:, 2], region, X[:, 4]] 1711 1712 1713def _standardize(X: np.ndarray, X_ref: np.ndarray) -> np.ndarray: 1714 # Scale with the training set's statistics only: using validation data here would leak it. 1715 return (X - X_ref.mean(axis=0)) / X_ref.std(axis=0) 1716 1717 1718@functools.lru_cache(maxsize=4) 1719def _showdown(seed: int) -> tuple[tuple[str, float], ...]: 1720 from primer.ml.neural_net import MLP, train 1721 1722 X, y, X_val, y_val, _ = make_tabular(seed=seed) 1723 scores = { 1724 "single tree (depth 5)": _accuracy(DecisionTree(max_depth=5).fit(X, y), X_val, y_val), 1725 "random forest": _accuracy(RandomForest(n_trees=50, seed=seed).fit(X, y), X_val, y_val), 1726 "gradient boosting": _accuracy(GradientBoosting(n_rounds=100, learning_rate=0.3, max_depth=3, loss="log").fit(X, y), X_val, y_val), 1727 } 1728 E, E_val = engineer_features(X), engineer_features(X_val) 1729 inputs = { 1730 "neural net (raw inputs)": (X, X_val), 1731 "neural net (scaled inputs)": (_standardize(X, X), _standardize(X_val, X)), 1732 "neural net (scaled + engineered)": (_standardize(E, E), _standardize(E_val, E)), 1733 } 1734 for label, (A, A_val) in inputs.items(): 1735 net = MLP(n_in=A.shape[1], n_hidden=32, seed=seed) 1736 with np.errstate(over="ignore"): # raw incomes of 50,000 overflow exp inside the sigmoid; that is the point 1737 train(net, A, y.astype(float), epochs=150, batch_size=32, lr=0.1, seed=seed) 1738 scores[label] = net.accuracy(A_val, y_val.astype(float)) 1739 return tuple(scores.items()) 1740 1741 1742def tabular_showdown(seed: int = 0) -> dict[str, float]: 1743 """Validation accuracy on `make_tabular` for a tree, two tree ensembles and a small MLP 1744 (`primer.ml.neural_net.MLP`) fed raw, scaled, and scaled plus engineered inputs. 1745 1746 Trees get the table exactly as it is. Every model is trained once per 1747 seed and remembered, because several callers ask for the same scores. 1748 """ 1749 return dict(_showdown(seed)) 1750 1751 1752 1753# --------------------------------------------------------------------------- 1754# 8. Figures (rendered into the HTML docs by `make figures`) 1755# --------------------------------------------------------------------------- 1756 1757 1758def figures() -> dict: 1759 """Plot this lesson's data. matplotlib is imported here, and only here, 1760 so the lesson itself needs nothing beyond NumPy.""" 1761 import matplotlib 1762 1763 matplotlib.use("Agg") 1764 import matplotlib.pyplot as plt 1765 from matplotlib.colors import ListedColormap 1766 1767 BLUE, ORANGE, MUTED, DARK = "#2563eb", "#ea580c", "#9ca3af", "#4b5563" 1768 REGIONS = ListedColormap(["#dbeafe", "#ffedd5"]) 1769 figs = {} 1770 X, y, X_val, y_val = moons_split() 1771 xx, yy = np.meshgrid(np.linspace(-1.8, 2.8, 220), np.linspace(-1.5, 1.9, 170)) 1772 grid = np.c_[xx.ravel(), yy.ravel()] 1773 1774 def regions(ax, model, title): 1775 ax.contourf(xx, yy, model.predict(grid).reshape(xx.shape), levels=[-0.5, 0.5, 1.5], cmap=REGIONS) 1776 ax.scatter(*X[y == 0].T, s=9, color=BLUE, label="class 0") 1777 ax.scatter(*X[y == 1].T, s=9, color=ORANGE, label="class 1") 1778 ax.set_title(title) 1779 ax.set_xticks([]) 1780 ax.set_yticks([]) 1781 ax.grid(False) 1782 1783 # --- 1. Every candidate question on the eight emails ------------------- 1784 Xs, ys, names = spam_emails() 1785 cands = candidate_splits(Xs, ys) 1786 labels = [f"{names[c.feature]} > {c.threshold:g}" for c in cands] 1787 scores = [c.impurity for c in cands] 1788 fig, ax = plt.subplots(figsize=(6, 3.2)) 1789 colors = [BLUE if s == min(scores) else MUTED for s in scores] 1790 ax.barh(labels, scores, color=colors) 1791 ax.axvline(gini(ys), color=DARK, ls="--") 1792 ax.text(gini(ys) + 0.01, 0.5, "before any\nsplit: 0.5", va="center", color=DARK) 1793 for i, s in enumerate(scores): 1794 ax.text(s + 0.008, i, f"{s:.3f}", va="center", zorder=3, bbox=dict(facecolor="white", edgecolor="none", pad=1)) 1795 ax.invert_yaxis() 1796 ax.set_xlim(0, 0.65) 1797 ax.set_xlabel("weighted Gini impurity after the split (lower is better)") 1798 ax.set_title("Six questions the tree could ask first") 1799 figs["spam_splits"] = fig 1800 1801 # --- 2. Axis-aligned decision regions as depth grows -------------------- 1802 fig, axes = plt.subplots(1, 3, figsize=(10, 3.3)) 1803 for ax, depth in zip(axes, (1, 3, None)): 1804 tree = DecisionTree(max_depth=depth).fit(X, y) 1805 regions(ax, tree, f"depth {depth or 'unlimited'}: {tree.n_leaves} leaves") 1806 axes[0].legend(frameon=False, loc="lower left", fontsize=8) 1807 fig.tight_layout() 1808 figs["regions"] = fig 1809 1810 # --- 3. Depth vs train/validation accuracy ------------------------------ 1811 rows = depth_sweep() 1812 xs = [r["depth"] or 16 for r in rows] 1813 fig, ax = plt.subplots(figsize=(6, 3.4)) 1814 ax.plot(xs, [r["train_accuracy"] for r in rows], "o-", color=BLUE, label="training") 1815 ax.plot(xs, [r["val_accuracy"] for r in rows], "o-", color=ORANGE, label="validation") 1816 ax.set_xticks(xs, [str(r["depth"] or "none") for r in rows]) 1817 ax.set_xlabel("depth limit") 1818 ax.set_ylabel("accuracy") 1819 ax.set_ylim(0.75, 1.01) 1820 ax.set_title("Deeper trees memorise: training climbs, validation falls") 1821 ax.legend(frameon=False) 1822 figs["depth_sweep"] = fig 1823 1824 # --- 4. One deep tree vs a forest --------------------------------------- 1825 fig, axes = plt.subplots(1, 2, figsize=(8, 3.4)) 1826 single = DecisionTree().fit(X, y) 1827 forest = RandomForest(n_trees=100).fit(X, y) 1828 regions(axes[0], single, f"one deep tree: {_accuracy(single, X_val, y_val):.1%} on validation") 1829 regions(axes[1], forest, f"forest of 100: {_accuracy(forest, X_val, y_val):.1%} on validation") 1830 fig.tight_layout() 1831 figs["forest_regions"] = fig 1832 1833 # --- 5. Validation accuracy vs number of trees -------------------------- 1834 curve = forest_curve(n_trees=(1, 2, 3, 5, 7, 10, 15, 20, 30, 50, 75, 100)) 1835 fig, ax = plt.subplots(figsize=(6, 3.4)) 1836 ax.plot([r["n_trees"] for r in curve], [r["val_accuracy"] for r in curve], "o-", color=BLUE, label="random forest") 1837 ax.axhline(curve[0]["single_tree"], color=ORANGE, ls="--", label="one deep tree, all the data") 1838 ax.set_xscale("log") 1839 ax.set_xlabel("number of trees (log scale)") 1840 ax.set_ylabel("validation accuracy") 1841 ax.set_title("Adding trees helps, then levels off") 1842 ax.legend(frameon=False, loc="lower right") 1843 figs["forest_curve"] = fig 1844 1845 # --- 6. Boosting builds a curve from steps ------------------------------ 1846 Xr, yr = sine_data(80, seed=0) 1847 line = np.linspace(0, 6, 400)[:, None] 1848 model = GradientBoosting(n_rounds=50, learning_rate=0.3, max_depth=2).fit(Xr, yr) 1849 staged = model.staged_scores(line) 1850 fig, axes = plt.subplots(1, 3, figsize=(10, 3.2), sharey=True) 1851 for ax, m in zip(axes, (1, 5, 50)): 1852 ax.scatter(Xr[:, 0], yr, s=8, color=MUTED) 1853 ax.plot(line[:, 0], np.sin(line[:, 0]), color=DARK, lw=1, ls=":", label="true curve sin(x)") 1854 ax.plot(line[:, 0], staged[m], color=BLUE, lw=2, label="boosted trees") 1855 ax.set_title(f"after {m} round{'s' if m > 1 else ''}") 1856 ax.set_xlabel("x") 1857 axes[0].set_ylabel("y") 1858 axes[0].legend(frameon=False, loc="lower left", fontsize=8) 1859 fig.tight_layout() 1860 figs["boosting_steps"] = fig 1861 1862 # --- 7. Training and validation loss per round, by learning rate -------- 1863 fig, ax = plt.subplots(figsize=(6.4, 3.6)) 1864 for row, color in zip(boosting_curves(), (ORANGE, "#7c3aed", BLUE)): 1865 lr = row["learning_rate"] 1866 ax.plot(row["train_loss"], color=color, lw=1, ls="--") 1867 ax.plot(row["val_loss"], color=color, lw=2, label=f"η = {lr:g} (best validation at round {row['best_round']})") 1868 ax.plot(row["best_round"], min(row["val_loss"]), "o", color=color) 1869 ax.axhline(0.09, color=MUTED, lw=1) 1870 ax.text(200, 0.095, "noise floor 0.3² = 0.09", ha="right", va="bottom", color=DARK, fontsize=8) 1871 ax.set_ylim(0, 0.7) 1872 ax.set_xlabel("boosting round") 1873 ax.set_ylabel("mean squared error") 1874 ax.set_title("Solid: validation. Dashed: training.") 1875 ax.legend(frameon=False) 1876 figs["boosting_curves"] = fig 1877 1878 # --- 8. The tabular showdown -------------------------------------------- 1879 scores = tabular_showdown() 1880 _, _, _, y_tab, _ = make_tabular() 1881 fig, ax = plt.subplots(figsize=(6.4, 3.4)) 1882 names_ = list(scores) 1883 colors = [BLUE if not k.startswith("neural") else ORANGE for k in names_] 1884 ax.barh(names_, [scores[k] for k in names_], color=colors) 1885 majority = max(y_tab.mean(), 1 - y_tab.mean()) 1886 ax.axvline(majority, color=DARK, ls="--") 1887 ax.text(majority + 0.004, -0.75, f"always say 'fine': {majority:.2%}", va="bottom", color=DARK, fontsize=8) 1888 for i, k in enumerate(names_): 1889 ax.text(scores[k] + 0.004, i, f"{scores[k]:.2%}", va="center") 1890 ax.set_ylim(len(names_) - 0.5, -1.1) 1891 ax.set_xlim(0.7, 1.0) 1892 ax.set_xlabel("validation accuracy on the loan table") 1893 ax.set_title("Trees read the table as it is; the net needs help") 1894 figs["showdown"] = fig 1895 1896 # --- 9. Impurity importance vs permutation importance ------------------- 1897 Xt, yt, Xtv, ytv, tab_names = make_tabular() 1898 forest = RandomForest(n_trees=30).fit(Xt, yt) 1899 imp, perm = forest.feature_importances, permutation_importance(forest, Xtv, ytv) 1900 fig, (a1, a2) = plt.subplots(1, 2, figsize=(9, 3.2), sharey=True) 1901 a1.barh(tab_names, imp, color=BLUE) 1902 a2.barh(tab_names, perm, color=ORANGE) 1903 for a, vals, fmt in ((a1, imp, "{:.0%}"), (a2, perm, "{:.2%}")): 1904 for i, v in enumerate(vals): 1905 a.text(v + 0.003, i, fmt.format(v), va="center") 1906 a1.invert_yaxis() 1907 a1.set_title("Impurity importance (training data)") 1908 a1.set_xlabel("share of impurity removed") 1909 a2.set_title("Permutation importance (validation data)") 1910 a2.set_xlabel("accuracy lost when the column is shuffled") 1911 fig.tight_layout() 1912 figs["importance"] = fig 1913 1914 return figs 1915 1916 1917# --------------------------------------------------------------------------- 1918# 9. Narrated walkthrough 1919# --------------------------------------------------------------------------- 1920 1921 1922def demo() -> None: 1923 banner("1. Sorting eight emails: which question first?") 1924 X, y, names = spam_emails() 1925 say( 1926 f""" 1927 Eight emails, four spam and four not. Before any question the pile has 1928 Gini impurity {gini(y):.2f}: two labels drawn at random disagree half 1929 the time. The tree tries every question it could ask: 1930 """ 1931 ) 1932 table(["question", "weighted Gini after"], [(f"{names[c.feature]} > {c.threshold:g}", c.impurity) for c in candidate_splits(X, y)], floatfmt=".3f") 1933 takeaway("'Known sender?' leaves the least mess (0.2), so it becomes the first question.") 1934 1935 banner("2. The grown tree, as rules a person can read") 1936 tree = DecisionTree(max_depth=2).fit(X, y) 1937 print("\n".join(tree.rules(names, ["ham", "spam"]))) 1938 print() 1939 say("Two questions sort all eight emails. The whole model is those five lines.") 1940 1941 banner("3. Overfitting: depth against training and validation accuracy") 1942 table( 1943 ["depth limit", "leaves", "train acc", "val acc"], 1944 [(r["depth"] or "none", r["leaves"], r["train_accuracy"], r["val_accuracy"]) for r in depth_sweep()], 1945 floatfmt=".3f", 1946 ) 1947 takeaway("With no limit the tree scores 100% on training data and worst on validation: it memorised the noise.") 1948 1949 banner("4. Random forests: bootstrap samples, random features, one vote") 1950 say( 1951 f""" 1952 A bootstrap sample of n rows leaves each row out with chance 1953 (1 - 1/n)^n: {out_of_bag_fraction(8):.4f} for n = 8, approaching 1/e = 1954 {1 / math.e:.4f}. Averaging B trees with correlation 0.3 leaves variance 1955 {averaged_variance(1.0, 0.3, 10):.2f} at B = 10 and 1956 {averaged_variance(1.0, 0.3, 1000):.4f} at B = 1000: the correlation is the floor. 1957 """ 1958 ) 1959 table(["trees", "val acc", "one deep tree"], [(r["n_trees"], r["val_accuracy"], r["single_tree"]) for r in forest_curve()], floatfmt=".3f") 1960 takeaway("Many deep, decorrelated trees averaged together keep their low bias and lose much of their variance.") 1961 1962 banner("5. Gradient boosting by hand: four houses, one round") 1963 ex = boosting_worked_example() 1964 table( 1965 ["size", "price y", "F0", "residual", "stump h1", "F1 = F0 + 0.5·h1"], 1966 [(s, p, ex["F0"], r, h, f) for s, p, r, h, f in zip((1, 2, 3, 4), (1, 2, 6, 7), ex["residuals"], ex["stump"], ex["F1"])], 1967 floatfmt=".2f", 1968 ) 1969 say(f"Mean squared error falls from {ex['mse'][0]} to {ex['mse'][1]} in one round.") 1970 for row in boosting_curves(): 1971 say( 1972 f""" 1973 Learning rate {row['learning_rate']:g}: best validation MSE 1974 {min(row['val_loss']):.3f} at round {row['best_round']}; by round 200 it 1975 is {row['val_loss'][-1]:.3f} while training MSE is {row['train_loss'][-1]:.3f}. 1976 """ 1977 ) 1978 takeaway("Each tree fits what is still wrong. Smaller steps take longer and generalize better; too many rounds memorise.") 1979 1980 banner("6. When trees win: a loan table") 1981 scores = tabular_showdown() 1982 table(["model", "val accuracy"], list(scores.items()), floatfmt=".4f") 1983 say( 1984 """ 1985 The trees took the table as it came: dollars, years, counts and region 1986 codes. The neural net learned nothing from raw inputs (it matches 1987 always predicting 'fine'), improved once scaled, and improved again 1988 once income was logged and regions one-hot encoded, and still trailed. 1989 """ 1990 ) 1991 Xt, yt, Xv, yv, tab_names = make_tabular() 1992 forest = RandomForest(n_trees=30).fit(Xt, yt) 1993 table( 1994 ["feature", "impurity importance", "permutation importance"], 1995 list(zip(tab_names, forest.feature_importances, permutation_importance(forest, Xv, yv))), 1996 floatfmt=".3f", 1997 ) 1998 takeaway( 1999 "Impurity importance gives the pure-noise column real credit; shuffling it on held-out data shows the model " 2000 "barely relies on it. Check importances on data the model has not seen." 2001 ) 2002 2003 2004if __name__ == "__main__": 2005 demo()
1155def gini(y: np.ndarray) -> float:
1156    """Gini impurity, 1 - Σ p_k²: the chance two labels drawn at random (with replacement) disagree."""
1157    if len(y) == 0:
1158        return 0.0
1159    p = _class_shares(y)
1160    return float(1.0 - np.sum(p**2))
Gini impurity, 1 - Σ p_k²: the chance two labels drawn at random (with replacement) disagree.
1163def entropy(y: np.ndarray) -> float:
1164    """Entropy in bits, -Σ p_k log2 p_k: how many yes/no questions a label still costs on average."""
1165    if len(y) == 0:
1166        return 0.0
1167    p = _class_shares(y)
1168    return float(-np.sum(p * np.log2(p)))
Entropy in bits, -Σ p_k log2 p_k: how many yes/no questions a label still costs on average.
1171def split_impurity(y_left: np.ndarray, y_right: np.ndarray, impurity=gini) -> float:
1172    """Impurity after a split: each side's impurity, weighted by its share of the examples."""
1173    n = len(y_left) + len(y_right)
1174    return len(y_left) / n * impurity(y_left) + len(y_right) / n * impurity(y_right)
Impurity after a split: each side's impurity, weighted by its share of the examples.
1182@dataclass(frozen=True)
1183class Split:
1184    """The best question found for a node: "is feature <= threshold?", and the impurity it leaves."""
1185
1186    feature: int
1187    threshold: float
1188    impurity: float
The best question found for a node: "is feature <= threshold?", and the impurity it leaves.
1201def best_split(
1202    X: np.ndarray,
1203    y: np.ndarray,
1204    criterion: str = "gini",
1205    features: np.ndarray | None = None,
1206    min_samples_leaf: int = 1,
1207) -> Split | None:
1208    """The feature and threshold whose split leaves the lowest weighted impurity, or None.
1209
1210    `criterion` is "gini" or "entropy" for class labels (integers 0..K-1), or
1211    "squared" for numbers (impurity = variance, as in a regression tree).
1212    Sorting each feature once turns "try every threshold" into running totals,
1213    so a node costs O(n log n) per feature instead of O(n²).
1214    """
1215    n = len(y)
1216    if n < 2 * min_samples_leaf:
1217        return None
1218    if criterion == "squared":
1219        parent = float(np.var(y))
1220    else:
1221        parent = gini(y) if criterion == "gini" else entropy(y)
1222    if parent <= 1e-12:  # already pure: nothing left to separate
1223        return None
1224    features = np.arange(X.shape[1]) if features is None else features
1225    best: Split | None = None
1226    n_left = np.arange(1, n)  # candidate i puts the first i sorted examples on the left
1227    n_right = n - n_left
1228    for f in features:
1229        order = np.argsort(X[:, f], kind="stable")
1230        xs, ys = X[order, f], y[order]
1231        # A threshold can only sit between two different values; equal values must stay together.
1232        valid = (xs[1:] > xs[:-1]) & (n_left >= min_samples_leaf) & (n_right >= min_samples_leaf)
1233        if not valid.any():
1234            continue
1235        if criterion == "squared":
1236            # Sum of squared errors from running sums: Σy² - (Σy)²/n on each side.
1237            s, s2 = np.cumsum(ys)[:-1], np.cumsum(ys**2)[:-1]
1238            tot, tot2 = ys.sum(), (ys**2).sum()
1239            sse = (s2 - s**2 / n_left) + ((tot2 - s2) - (tot - s) ** 2 / n_right)
1240            weighted = sse / n
1241        else:
1242            onehot = np.eye(int(y.max()) + 1)[ys]  # (n, classes)
1243            left = np.cumsum(onehot, axis=0)[:-1]  # class counts left of each candidate
1244            right = onehot.sum(axis=0) - left
1245            weighted = (n_left * _side_impurities(left, n_left, criterion) + n_right * _side_impurities(right, n_right, criterion)) / n
1246        weighted = np.where(valid, weighted, np.inf)
1247        i = int(np.argmin(weighted))
1248        # Strictly lower wins, so ties go to the earliest feature: the tree is reproducible.
1249        if best is None or weighted[i] < best.impurity - 1e-12:
1250            best = Split(int(f), float((xs[i] + xs[i + 1]) / 2), float(weighted[i]))
1251    return best
The feature and threshold whose split leaves the lowest weighted impurity, or None.
criterion is "gini" or "entropy" for class labels (integers 0..K-1), or
"squared" for numbers (impurity = variance, as in a regression tree).
Sorting each feature once turns "try every threshold" into running totals,
so a node costs O(n log n) per feature instead of O(n²).
1254def candidate_splits(X: np.ndarray, y: np.ndarray) -> list[Split]:
1255    """Every question worth asking at one node, with the Gini impurity it would leave.
1256
1257    Thresholds sit halfway between neighbouring distinct values of a
1258    feature; anywhere else in the gap gives the same split.
1259    """
1260    out = []
1261    for f in range(X.shape[1]):
1262        values = np.unique(X[:, f])
1263        for t in (values[1:] + values[:-1]) / 2:
1264            left = X[:, f] <= t
1265            out.append(Split(f, float(t), split_impurity(y[left], y[~left])))
1266    return out
Every question worth asking at one node, with the Gini impurity it would leave.
Thresholds sit halfway between neighbouring distinct values of a feature; anywhere else in the gap gives the same split.
1273@dataclass
1274class Node:
1275    """One box of the flowchart. A leaf has no question and carries the prediction in `value`."""
1276
1277    value: np.ndarray  # class shares (classification) or [mean] (regression)
1278    n_samples: int
1279    impurity: float
1280    feature: int | None = None
1281    threshold: float | None = None
1282    left: "Node | None" = None
1283    right: "Node | None" = None
1284
1285    @property
1286    def is_leaf(self) -> bool:
1287        return self.feature is None
One box of the flowchart. A leaf has no question and carries the prediction in value.
1290@dataclass
1291class DecisionTree:
1292    """A CART-style decision tree, grown greedily from the top.
1293
1294    criterion: "gini" or "entropy" to classify integer labels, "squared" to
1295    predict numbers. max_depth None grows until every leaf is pure.
1296    max_features limits how many randomly chosen features each node may try
1297    ("sqrt" or an int); that is the random forest's extra ingredient.
1298    """
1299
1300    max_depth: int | None = None
1301    criterion: str = "gini"
1302    min_samples_leaf: int = 1
1303    max_features: int | str | None = None
1304    seed: int = 0
1305    root: Node | None = field(default=None, init=False)
1306
1307    def fit(self, X: np.ndarray, y: np.ndarray, n_classes: int | None = None) -> "DecisionTree":
1308        X = np.asarray(X, dtype=float)
1309        self.regression = self.criterion == "squared"
1310        y = np.asarray(y, dtype=float if self.regression else int)
1311        # A bootstrap sample can miss a class; the forest passes the true count so shares line up.
1312        self.n_classes = None if self.regression else (n_classes or int(y.max()) + 1)
1313        self.n_features = X.shape[1]
1314        self._importance = np.zeros(self.n_features)
1315        self._rng = np.random.default_rng(self.seed)
1316        self._n_total = len(y)
1317        self.root = self._grow(X, y, depth=0)
1318        return self
1319
1320    def _leaf_value(self, y: np.ndarray) -> np.ndarray:
1321        if self.regression:
1322            return np.array([y.mean()])
1323        return np.bincount(y, minlength=self.n_classes) / len(y)
1324
1325    def _impurity(self, y: np.ndarray) -> float:
1326        if self.regression:
1327            return float(np.var(y))
1328        return gini(y) if self.criterion == "gini" else entropy(y)
1329
1330    def _features_to_try(self) -> np.ndarray:
1331        d = self.n_features
1332        k = {None: d, "sqrt": max(1, int(math.sqrt(d)))}.get(self.max_features, self.max_features)
1333        if k >= d:
1334            return np.arange(d)
1335        # A fresh random subset at every node keeps the trees of a forest different from each other.
1336        return np.sort(self._rng.choice(d, size=k, replace=False))
1337
1338    def _grow(self, X: np.ndarray, y: np.ndarray, depth: int) -> Node:
1339        node = Node(self._leaf_value(y), len(y), self._impurity(y))
1340        if self.max_depth is not None and depth >= self.max_depth:
1341            return node
1342        split = best_split(X, y, self.criterion, self._features_to_try(), self.min_samples_leaf)
1343        if split is None:
1344            return node
1345        go_left = X[:, split.feature] <= split.threshold
1346        # Credit the feature with the impurity it removed, weighted by how many examples reached here.
1347        self._importance[split.feature] += len(y) / self._n_total * (node.impurity - split.impurity)
1348        node.feature, node.threshold = split.feature, split.threshold
1349        node.left = self._grow(X[go_left], y[go_left], depth + 1)
1350        node.right = self._grow(X[~go_left], y[~go_left], depth + 1)
1351        return node
1352
1353    def _values(self, X: np.ndarray) -> np.ndarray:
1354        """Route every row to its leaf and return the leaf values, (n, classes) or (n, 1)."""
1355        X = np.asarray(X, dtype=float)
1356        out = np.empty((len(X), len(self.root.value)))
1357
1358        def route(node: Node, rows: np.ndarray) -> None:
1359            if node.is_leaf:
1360                out[rows] = node.value
1361                return
1362            go_left = X[rows, node.feature] <= node.threshold
1363            route(node.left, rows[go_left])
1364            route(node.right, rows[~go_left])
1365
1366        route(self.root, np.arange(len(X)))
1367        return out
1368
1369    def predict_proba(self, X: np.ndarray) -> np.ndarray:
1370        """Class shares of the leaf each row lands in, (n, classes)."""
1371        return self._values(X)
1372
1373    def predict(self, X: np.ndarray) -> np.ndarray:
1374        """The leaf's mean for regression, or the leaf's majority class."""
1375        values = self._values(X)
1376        return values[:, 0] if self.regression else values.argmax(axis=1)
1377
1378    @property
1379    def depth(self) -> int:
1380        def d(node: Node) -> int:
1381            return 0 if node.is_leaf else 1 + max(d(node.left), d(node.right))
1382
1383        return d(self.root)
1384
1385    @property
1386    def n_leaves(self) -> int:
1387        def count(node: Node) -> int:
1388            return 1 if node.is_leaf else count(node.left) + count(node.right)
1389
1390        return count(self.root)
1391
1392    @property
1393    def feature_importances(self) -> np.ndarray:
1394        """Impurity removed by each feature's splits, as shares that sum to 1."""
1395        total = self._importance.sum()
1396        return self._importance / total if total > 0 else self._importance
1397
1398    def rules(self, names: list[str] | None = None, classes: list[str] | None = None) -> list[str]:
1399        """The tree as nested if/else lines: the whole model, readable by a person."""
1400        names = names or [f"x{i}" for i in range(self.n_features)]
1401        lines: list[str] = []
1402
1403        def leaf_text(node: Node) -> str:
1404            if self.regression:
1405                return f"predict {node.value[0]:.3g}"
1406            k = int(node.value.argmax())
1407            label = classes[k] if classes else str(k)
1408            noun = "example" if node.n_samples == 1 else "examples"
1409            return f"predict {label}  ({node.n_samples} {noun}, {node.value[k]:.0%} agree)"
1410
1411        def walk(node: Node, indent: str) -> None:
1412            if node.is_leaf:
1413                lines.append(indent + leaf_text(node))
1414                return
1415            lines.append(f"{indent}if {names[node.feature]} <= {node.threshold:g}:")
1416            walk(node.left, indent + "    ")
1417            lines.append(f"{indent}else:  # {names[node.feature]} > {node.threshold:g}")
1418            walk(node.right, indent + "    ")
1419
1420        walk(self.root, "")
1421        return lines
A CART-style decision tree, grown greedily from the top.
criterion: "gini" or "entropy" to classify integer labels, "squared" to predict numbers. max_depth None grows until every leaf is pure. max_features limits how many randomly chosen features each node may try ("sqrt" or an int); that is the random forest's extra ingredient.
1307    def fit(self, X: np.ndarray, y: np.ndarray, n_classes: int | None = None) -> "DecisionTree":
1308        X = np.asarray(X, dtype=float)
1309        self.regression = self.criterion == "squared"
1310        y = np.asarray(y, dtype=float if self.regression else int)
1311        # A bootstrap sample can miss a class; the forest passes the true count so shares line up.
1312        self.n_classes = None if self.regression else (n_classes or int(y.max()) + 1)
1313        self.n_features = X.shape[1]
1314        self._importance = np.zeros(self.n_features)
1315        self._rng = np.random.default_rng(self.seed)
1316        self._n_total = len(y)
1317        self.root = self._grow(X, y, depth=0)
1318        return self
1369    def predict_proba(self, X: np.ndarray) -> np.ndarray:
1370        """Class shares of the leaf each row lands in, (n, classes)."""
1371        return self._values(X)
Class shares of the leaf each row lands in, (n, classes).
1373    def predict(self, X: np.ndarray) -> np.ndarray:
1374        """The leaf's mean for regression, or the leaf's majority class."""
1375        values = self._values(X)
1376        return values[:, 0] if self.regression else values.argmax(axis=1)
The leaf's mean for regression, or the leaf's majority class.
1392    @property
1393    def feature_importances(self) -> np.ndarray:
1394        """Impurity removed by each feature's splits, as shares that sum to 1."""
1395        total = self._importance.sum()
1396        return self._importance / total if total > 0 else self._importance
Impurity removed by each feature's splits, as shares that sum to 1.
1398    def rules(self, names: list[str] | None = None, classes: list[str] | None = None) -> list[str]:
1399        """The tree as nested if/else lines: the whole model, readable by a person."""
1400        names = names or [f"x{i}" for i in range(self.n_features)]
1401        lines: list[str] = []
1402
1403        def leaf_text(node: Node) -> str:
1404            if self.regression:
1405                return f"predict {node.value[0]:.3g}"
1406            k = int(node.value.argmax())
1407            label = classes[k] if classes else str(k)
1408            noun = "example" if node.n_samples == 1 else "examples"
1409            return f"predict {label}  ({node.n_samples} {noun}, {node.value[k]:.0%} agree)"
1410
1411        def walk(node: Node, indent: str) -> None:
1412            if node.is_leaf:
1413                lines.append(indent + leaf_text(node))
1414                return
1415            lines.append(f"{indent}if {names[node.feature]} <= {node.threshold:g}:")
1416            walk(node.left, indent + "    ")
1417            lines.append(f"{indent}else:  # {names[node.feature]} > {node.threshold:g}")
1418            walk(node.right, indent + "    ")
1419
1420        walk(self.root, "")
1421        return lines
The tree as nested if/else lines: the whole model, readable by a person.
1431def spam_emails() -> tuple[np.ndarray, np.ndarray, list[str]]:
1432    """The eight emails of the worked example: (links, known sender?) and 1 = spam.
1433
1434    | email | links | known sender | spam? |
1435    |---|---|---|---|
1436    | 1 | 0 | yes | no |
1437    | 2 | 1 | yes | no |
1438    | 3 | 4 | yes | no |
1439    | 4 | 0 | no  | no |
1440    | 5 | 3 | no  | yes |
1441    | 6 | 5 | no  | yes |
1442    | 7 | 6 | no  | yes |
1443    | 8 | 1 | no  | yes |
1444    """
1445    X = np.array([[0, 1], [1, 1], [4, 1], [0, 0], [3, 0], [5, 0], [6, 0], [1, 0]], dtype=float)
1446    y = np.array([0, 0, 0, 0, 1, 1, 1, 1])
1447    return X, y, list(SPAM_FEATURES)
The eight emails of the worked example: (links, known sender?) and 1 = spam.
| links | known sender | spam? | |
|---|---|---|---|
| 1 | 0 | yes | no |
| 2 | 1 | yes | no |
| 3 | 4 | yes | no |
| 4 | 0 | no | no |
| 5 | 3 | no | yes |
| 6 | 5 | no | yes |
| 7 | 6 | no | yes |
| 8 | 1 | no | yes |
1450def moons_split(n: int = 500, noise: float = 0.35, n_train: int = 300, seed: int = 1):
1451    """Noisy two-moons points (`primer.ml.neural_net.make_moons`), cut into training and validation sets."""
1452    from primer.ml.neural_net import make_moons
1453
1454    X, y = make_moons(n=n, noise=noise, seed=seed)
1455    # make_moons lists one moon, then the other; shuffle so both sets hold both classes.
1456    order = np.random.default_rng(seed).permutation(n)
1457    X, y = X[order], y[order].astype(int)
1458    return X[:n_train], y[:n_train], X[n_train:], y[n_train:]
Noisy two-moons points (primer.ml.neural_net.make_moons), cut into training and validation sets.
1465def depth_sweep(depths=(1, 2, 3, 4, 5, 6, 8, 10, 12, None)) -> list[dict]:
1466    """Train and validation accuracy of one tree per depth limit on the noisy moons."""
1467    X, y, X_val, y_val = moons_split()
1468    rows = []
1469    for depth in depths:
1470        tree = DecisionTree(max_depth=depth).fit(X, y)
1471        rows.append(dict(depth=depth, train_accuracy=_accuracy(tree, X, y), val_accuracy=_accuracy(tree, X_val, y_val), leaves=tree.n_leaves))
1472    return rows
Train and validation accuracy of one tree per depth limit on the noisy moons.
1480def bootstrap_sample(n: int, rng: np.random.Generator) -> np.ndarray:
1481    """n row indices drawn with replacement: some rows twice or more, about a third not at all."""
1482    return rng.integers(0, n, size=n)
n row indices drawn with replacement: some rows twice or more, about a third not at all.
1485def out_of_bag_fraction(n: int) -> float:
1486    """(1 - 1/n)^n: the chance a given row is never drawn in n draws. Tends to 1/e ≈ 0.368."""
1487    return (1 - 1 / n) ** n
(1 - 1/n)^n: the chance a given row is never drawn in n draws. Tends to 1/e ≈ 0.368.
1490def averaged_variance(sigma2: float, rho: float, n_trees: int) -> float:
1491    """Variance of the average of n_trees predictions, each with variance sigma2 and pairwise correlation rho.
1492
1493    ρσ² + (1 - ρ)σ²/B: more trees shrink only the second term, so the
1494    correlation between trees sets the floor. Random feature subsets exist
1495    to push ρ down.
1496    """
1497    return rho * sigma2 + (1 - rho) * sigma2 / n_trees
Variance of the average of n_trees predictions, each with variance sigma2 and pairwise correlation rho.
ρσ² + (1 - ρ)σ²/B: more trees shrink only the second term, so the correlation between trees sets the floor. Random feature subsets exist to push ρ down.
1500@dataclass
1501class RandomForest:
1502    """Many deep trees, each grown on its own bootstrap sample and trying only
1503    a random subset of features at every node; their class shares are averaged."""
1504
1505    n_trees: int = 100
1506    max_depth: int | None = None
1507    max_features: int | str | None = "sqrt"
1508    seed: int = 0
1509    trees: list[DecisionTree] = field(default_factory=list, init=False)
1510
1511    def fit(self, X: np.ndarray, y: np.ndarray) -> "RandomForest":
1512        X, y = np.asarray(X, dtype=float), np.asarray(y, dtype=int)
1513        rng = np.random.default_rng(self.seed)
1514        n_classes = int(y.max()) + 1
1515        self.trees = []
1516        for _ in range(self.n_trees):
1517            rows = bootstrap_sample(len(y), rng)
1518            # Each tree gets its own seed, so its feature subsets differ from its neighbours'.
1519            tree = DecisionTree(max_depth=self.max_depth, max_features=self.max_features, seed=int(rng.integers(2**31)))
1520            self.trees.append(tree.fit(X[rows], y[rows], n_classes=n_classes))
1521        return self
1522
1523    def predict_proba(self, X: np.ndarray) -> np.ndarray:
1524        return np.mean([t.predict_proba(X) for t in self.trees], axis=0)
1525
1526    def predict(self, X: np.ndarray) -> np.ndarray:
1527        return self.predict_proba(X).argmax(axis=1)
1528
1529    @property
1530    def feature_importances(self) -> np.ndarray:
1531        """Each tree's impurity importance, averaged over the forest."""
1532        return np.mean([t.feature_importances for t in self.trees], axis=0)
Many deep trees, each grown on its own bootstrap sample and trying only a random subset of features at every node; their class shares are averaged.
1511    def fit(self, X: np.ndarray, y: np.ndarray) -> "RandomForest":
1512        X, y = np.asarray(X, dtype=float), np.asarray(y, dtype=int)
1513        rng = np.random.default_rng(self.seed)
1514        n_classes = int(y.max()) + 1
1515        self.trees = []
1516        for _ in range(self.n_trees):
1517            rows = bootstrap_sample(len(y), rng)
1518            # Each tree gets its own seed, so its feature subsets differ from its neighbours'.
1519            tree = DecisionTree(max_depth=self.max_depth, max_features=self.max_features, seed=int(rng.integers(2**31)))
1520            self.trees.append(tree.fit(X[rows], y[rows], n_classes=n_classes))
1521        return self
1535def forest_curve(n_trees=(1, 2, 3, 5, 10, 20, 50, 100), seed: int = 0) -> list[dict]:
1536    """Validation accuracy of a forest on the noisy moons as trees are added.
1537
1538    One forest of max(n_trees) is grown; the first k trees' average gives the
1539    k-tree forest, exactly as if it had been grown alone.
1540    """
1541    X, y, X_val, y_val = moons_split()
1542    forest = RandomForest(n_trees=max(n_trees), seed=seed).fit(X, y)
1543    probas = np.cumsum([t.predict_proba(X_val) for t in forest.trees], axis=0)
1544    single = DecisionTree().fit(X, y)
1545    return [
1546        dict(n_trees=k, val_accuracy=float(np.mean(probas[k - 1].argmax(axis=1) == y_val)), single_tree=_accuracy(single, X_val, y_val))
1547        for k in n_trees
1548    ]
Validation accuracy of a forest on the noisy moons as trees are added.
One forest of max(n_trees) is grown; the first k trees' average gives the k-tree forest, exactly as if it had been grown alone.
1560@dataclass
1561class GradientBoosting:
1562    """F_m = F_{m-1} + η·h_m, where each h_m is a small regression tree fit to
1563    the negative gradient of the loss (the residuals, for squared loss).
1564
1565    loss="squared" predicts numbers; loss="log" classifies 0/1 labels, with F
1566    as log-odds. `train_loss` holds the training loss before any tree and
1567    after each round: mean squared error, or cross-entropy for "log".
1568    """
1569
1570    n_rounds: int = 100
1571    learning_rate: float = 0.1
1572    max_depth: int = 2
1573    loss: str = "squared"
1574    trees: list[DecisionTree] = field(default_factory=list, init=False)
1575    train_loss: list[float] = field(default_factory=list, init=False)
1576
1577    @staticmethod
1578    def negative_gradient(y: np.ndarray, F: np.ndarray, loss: str) -> np.ndarray:
1579        """-∂L/∂F for each example: the direction that most quickly reduces its loss.
1580
1581        Squared loss ½(y - F)² gives y - F, the plain residual. Log loss
1582        gives y - sigmoid(F): the label minus the predicted probability.
1583        """
1584        return y - F if loss == "squared" else y - _sigmoid(F)
1585
1586    def _loss(self, y: np.ndarray, F: np.ndarray) -> float:
1587        if self.loss == "squared":
1588            return float(np.mean((y - F) ** 2))
1589        p = np.clip(_sigmoid(F), 1e-12, 1 - 1e-12)
1590        return float(-np.mean(y * np.log(p) + (1 - y) * np.log(1 - p)))
1591
1592    def fit(self, X: np.ndarray, y: np.ndarray) -> "GradientBoosting":
1593        X, y = np.asarray(X, dtype=float), np.asarray(y, dtype=float)
1594        # F_0: the best single constant. The mean for squared loss; the log-odds of the base rate for log loss.
1595        mean = y.mean()
1596        self.f0 = mean if self.loss == "squared" else math.log(mean / (1 - mean))
1597        F = np.full(len(y), self.f0)
1598        self.trees, self.train_loss = [], [self._loss(y, F)]
1599        for _ in range(self.n_rounds):
1600            residual = self.negative_gradient(y, F, self.loss)
1601            tree = DecisionTree(max_depth=self.max_depth, criterion="squared").fit(X, residual)
1602            # Take only a fraction η of the step: many small corrections generalize better than a few big ones.
1603            F = F + self.learning_rate * tree.predict(X)
1604            self.trees.append(tree)
1605            self.train_loss.append(self._loss(y, F))
1606        return self
1607
1608    def staged_scores(self, X: np.ndarray) -> np.ndarray:
1609        """F_0, F_1, ..., F_M for every row: (rounds + 1, n)."""
1610        steps = [np.full(len(X), self.f0)] + [self.learning_rate * t.predict(X) for t in self.trees]
1611        return np.cumsum(steps, axis=0)
1612
1613    def staged_loss(self, X: np.ndarray, y: np.ndarray) -> list[float]:
1614        """The loss on (X, y) before any tree and after each round: the validation curve."""
1615        return [self._loss(np.asarray(y, dtype=float), F) for F in self.staged_scores(X)]
1616
1617    def predict(self, X: np.ndarray) -> np.ndarray:
1618        F = self.staged_scores(X)[-1]
1619        return F if self.loss == "squared" else (F > 0).astype(int)
F_m = F_{m-1} + η·h_m, where each h_m is a small regression tree fit to the negative gradient of the loss (the residuals, for squared loss).
loss="squared" predicts numbers; loss="log" classifies 0/1 labels, with F
as log-odds. train_loss holds the training loss before any tree and
after each round: mean squared error, or cross-entropy for "log".
1577    @staticmethod
1578    def negative_gradient(y: np.ndarray, F: np.ndarray, loss: str) -> np.ndarray:
1579        """-∂L/∂F for each example: the direction that most quickly reduces its loss.
1580
1581        Squared loss ½(y - F)² gives y - F, the plain residual. Log loss
1582        gives y - sigmoid(F): the label minus the predicted probability.
1583        """
1584        return y - F if loss == "squared" else y - _sigmoid(F)
-∂L/∂F for each example: the direction that most quickly reduces its loss.
Squared loss ½(y - F)² gives y - F, the plain residual. Log loss gives y - sigmoid(F): the label minus the predicted probability.
1592    def fit(self, X: np.ndarray, y: np.ndarray) -> "GradientBoosting":
1593        X, y = np.asarray(X, dtype=float), np.asarray(y, dtype=float)
1594        # F_0: the best single constant. The mean for squared loss; the log-odds of the base rate for log loss.
1595        mean = y.mean()
1596        self.f0 = mean if self.loss == "squared" else math.log(mean / (1 - mean))
1597        F = np.full(len(y), self.f0)
1598        self.trees, self.train_loss = [], [self._loss(y, F)]
1599        for _ in range(self.n_rounds):
1600            residual = self.negative_gradient(y, F, self.loss)
1601            tree = DecisionTree(max_depth=self.max_depth, criterion="squared").fit(X, residual)
1602            # Take only a fraction η of the step: many small corrections generalize better than a few big ones.
1603            F = F + self.learning_rate * tree.predict(X)
1604            self.trees.append(tree)
1605            self.train_loss.append(self._loss(y, F))
1606        return self
1608    def staged_scores(self, X: np.ndarray) -> np.ndarray:
1609        """F_0, F_1, ..., F_M for every row: (rounds + 1, n)."""
1610        steps = [np.full(len(X), self.f0)] + [self.learning_rate * t.predict(X) for t in self.trees]
1611        return np.cumsum(steps, axis=0)
F_0, F_1, ..., F_M for every row: (rounds + 1, n).
1613    def staged_loss(self, X: np.ndarray, y: np.ndarray) -> list[float]:
1614        """The loss on (X, y) before any tree and after each round: the validation curve."""
1615        return [self._loss(np.asarray(y, dtype=float), F) for F in self.staged_scores(X)]
The loss on (X, y) before any tree and after each round: the validation curve.
1622def boosting_worked_example(learning_rate: float = 0.5) -> dict:
1623    """Four houses (size 1..4, price 1, 2, 6, 7) and one round of boosting with a one-question tree."""
1624    X, y = np.array([[1.0], [2.0], [3.0], [4.0]]), np.array([1.0, 2.0, 6.0, 7.0])
1625    model = GradientBoosting(n_rounds=1, learning_rate=learning_rate, max_depth=1).fit(X, y)
1626    F0 = np.full(4, model.f0)
1627    residuals = GradientBoosting.negative_gradient(y, F0, "squared")
1628    return dict(
1629        F0=model.f0,
1630        residuals=residuals.tolist(),
1631        stump=model.trees[0].predict(X).tolist(),
1632        F1=model.predict(X).tolist(),
1633        mse=model.train_loss,
1634    )
Four houses (size 1..4, price 1, 2, 6, 7) and one round of boosting with a one-question tree.
1637def sine_data(n: int, noise: float = 0.3, seed: int = 0) -> tuple[np.ndarray, np.ndarray]:
1638    """n points of y = sin(x) + noise for x in [0, 6]: a curve for regression trees to approximate."""
1639    rng = np.random.default_rng(seed)
1640    x = rng.uniform(0, 6, n)
1641    return x[:, None], np.sin(x) + rng.normal(0, noise, n)
n points of y = sin(x) + noise for x in [0, 6]: a curve for regression trees to approximate.
1644def boosting_curves(learning_rates=(1.0, 0.3, 0.1), n_rounds: int = 200, max_depth: int = 2) -> list[dict]:
1645    """Training and validation mean squared error per round on 80 noisy sine points, for each learning rate."""
1646    X, y = sine_data(80, seed=0)
1647    X_val, y_val = sine_data(400, seed=1)
1648    rows = []
1649    for lr in learning_rates:
1650        model = GradientBoosting(n_rounds=n_rounds, learning_rate=lr, max_depth=max_depth).fit(X, y)
1651        val = model.staged_loss(X_val, y_val)
1652        rows.append(dict(learning_rate=lr, train_loss=model.train_loss, val_loss=val, best_round=int(np.argmin(val))))
1653    return rows
Training and validation mean squared error per round on 80 noisy sine points, for each learning rate.
1663def make_tabular(n: int = 1200, n_train: int = 800, seed: int = 0):
1664    """A toy loan table with the mix real spreadsheets have.
1665
1666    age in years, income in dollars (spanning 100×), a count of late
1667    payments, a region code 0..5 whose numbers mean nothing in order, and a
1668    column of pure noise. The label (1 = the loan went bad) follows
1669    threshold rules of the kind a lender writes, with 5% of labels flipped.
1670    Returns X_train, y_train, X_val, y_val, feature names.
1671    """
1672    rng = np.random.default_rng(seed)
1673    age = rng.uniform(18, 80, n)
1674    income = np.exp(rng.normal(np.log(50_000), 0.7, n))
1675    late = rng.poisson(1.2, n)
1676    region = rng.integers(0, 6, n)
1677    noise = rng.normal(0, 1, n)
1678    bad = (late >= 4) | ((income < 30_000) & (age < 30)) | (np.isin(region, [1, 4]) & (late >= 2)) | ((income < 20_000) & (late >= 2))
1679    flip = rng.random(n) < 0.05
1680    y = (bad ^ flip).astype(int)
1681    X = np.c_[age, income, late, region, noise]
1682    return X[:n_train], y[:n_train], X[n_train:], y[n_train:], list(TABULAR_FEATURES)
A toy loan table with the mix real spreadsheets have.
age in years, income in dollars (spanning 100×), a count of late payments, a region code 0..5 whose numbers mean nothing in order, and a column of pure noise. The label (1 = the loan went bad) follows threshold rules of the kind a lender writes, with 5% of labels flipped. Returns X_train, y_train, X_val, y_val, feature names.
1685def permutation_importance(model, X: np.ndarray, y: np.ndarray, seed: int = 0) -> np.ndarray:
1686    """Accuracy lost on held-out data when one column is shuffled, per feature.
1687
1688    Shuffling breaks the link between that column and the label while
1689    keeping its values, so the drop measures how much the model relies on it
1690    for data it did not train on.
1691    """
1692    rng = np.random.default_rng(seed)
1693    base = _accuracy(model, X, y)
1694    drops = []
1695    for f in range(X.shape[1]):
1696        shuffled = X.copy()
1697        shuffled[:, f] = rng.permutation(shuffled[:, f])
1698        drops.append(base - _accuracy(model, shuffled, y))
1699    return np.array(drops)
Accuracy lost on held-out data when one column is shuffled, per feature.
Shuffling breaks the link between that column and the label while keeping its values, so the drop measures how much the model relies on it for data it did not train on.
1702def engineer_features(X: np.ndarray) -> np.ndarray:
1703    """What a neural network needs done by hand before it can read the loan table.
1704
1705    Income becomes its logarithm, so a raise from 20k to 40k counts as much
1706    as one from 100k to 200k. The region code becomes six yes/no columns,
1707    because region 4 is not "twice region 2". Columns: age, log income, late
1708    payments, region_0..region_5, noise.
1709    """
1710    region = np.eye(6)[X[:, 3].astype(int)]
1711    return np.c_[X[:, 0], np.log(X[:, 1]), X[:, 2], region, X[:, 4]]
What a neural network needs done by hand before it can read the loan table.
Income becomes its logarithm, so a raise from 20k to 40k counts as much as one from 100k to 200k. The region code becomes six yes/no columns, because region 4 is not "twice region 2". Columns: age, log income, late payments, region_0..region_5, noise.
1743def tabular_showdown(seed: int = 0) -> dict[str, float]:
1744    """Validation accuracy on `make_tabular` for a tree, two tree ensembles and a small MLP
1745    (`primer.ml.neural_net.MLP`) fed raw, scaled, and scaled plus engineered inputs.
1746
1747    Trees get the table exactly as it is. Every model is trained once per
1748    seed and remembered, because several callers ask for the same scores.
1749    """
1750    return dict(_showdown(seed))
Validation accuracy on make_tabular for a tree, two tree ensembles and a small MLP
(primer.ml.neural_net.MLP) fed raw, scaled, and scaled plus engineered inputs.
Trees get the table exactly as it is. Every model is trained once per seed and remembered, because several callers ask for the same scores.
1759def figures() -> dict:
1760    """Plot this lesson's data. matplotlib is imported here, and only here,
1761    so the lesson itself needs nothing beyond NumPy."""
1762    import matplotlib
1763
1764    matplotlib.use("Agg")
1765    import matplotlib.pyplot as plt
1766    from matplotlib.colors import ListedColormap
1767
1768    BLUE, ORANGE, MUTED, DARK = "#2563eb", "#ea580c", "#9ca3af", "#4b5563"
1769    REGIONS = ListedColormap(["#dbeafe", "#ffedd5"])
1770    figs = {}
1771    X, y, X_val, y_val = moons_split()
1772    xx, yy = np.meshgrid(np.linspace(-1.8, 2.8, 220), np.linspace(-1.5, 1.9, 170))
1773    grid = np.c_[xx.ravel(), yy.ravel()]
1774
1775    def regions(ax, model, title):
1776        ax.contourf(xx, yy, model.predict(grid).reshape(xx.shape), levels=[-0.5, 0.5, 1.5], cmap=REGIONS)
1777        ax.scatter(*X[y == 0].T, s=9, color=BLUE, label="class 0")
1778        ax.scatter(*X[y == 1].T, s=9, color=ORANGE, label="class 1")
1779        ax.set_title(title)
1780        ax.set_xticks([])
1781        ax.set_yticks([])
1782        ax.grid(False)
1783
1784    # --- 1. Every candidate question on the eight emails -------------------
1785    Xs, ys, names = spam_emails()
1786    cands = candidate_splits(Xs, ys)
1787    labels = [f"{names[c.feature]} > {c.threshold:g}" for c in cands]
1788    scores = [c.impurity for c in cands]
1789    fig, ax = plt.subplots(figsize=(6, 3.2))
1790    colors = [BLUE if s == min(scores) else MUTED for s in scores]
1791    ax.barh(labels, scores, color=colors)
1792    ax.axvline(gini(ys), color=DARK, ls="--")
1793    ax.text(gini(ys) + 0.01, 0.5, "before any\nsplit: 0.5", va="center", color=DARK)
1794    for i, s in enumerate(scores):
1795        ax.text(s + 0.008, i, f"{s:.3f}", va="center", zorder=3, bbox=dict(facecolor="white", edgecolor="none", pad=1))
1796    ax.invert_yaxis()
1797    ax.set_xlim(0, 0.65)
1798    ax.set_xlabel("weighted Gini impurity after the split (lower is better)")
1799    ax.set_title("Six questions the tree could ask first")
1800    figs["spam_splits"] = fig
1801
1802    # --- 2. Axis-aligned decision regions as depth grows --------------------
1803    fig, axes = plt.subplots(1, 3, figsize=(10, 3.3))
1804    for ax, depth in zip(axes, (1, 3, None)):
1805        tree = DecisionTree(max_depth=depth).fit(X, y)
1806        regions(ax, tree, f"depth {depth or 'unlimited'}: {tree.n_leaves} leaves")
1807    axes[0].legend(frameon=False, loc="lower left", fontsize=8)
1808    fig.tight_layout()
1809    figs["regions"] = fig
1810
1811    # --- 3. Depth vs train/validation accuracy ------------------------------
1812    rows = depth_sweep()
1813    xs = [r["depth"] or 16 for r in rows]
1814    fig, ax = plt.subplots(figsize=(6, 3.4))
1815    ax.plot(xs, [r["train_accuracy"] for r in rows], "o-", color=BLUE, label="training")
1816    ax.plot(xs, [r["val_accuracy"] for r in rows], "o-", color=ORANGE, label="validation")
1817    ax.set_xticks(xs, [str(r["depth"] or "none") for r in rows])
1818    ax.set_xlabel("depth limit")
1819    ax.set_ylabel("accuracy")
1820    ax.set_ylim(0.75, 1.01)
1821    ax.set_title("Deeper trees memorise: training climbs, validation falls")
1822    ax.legend(frameon=False)
1823    figs["depth_sweep"] = fig
1824
1825    # --- 4. One deep tree vs a forest ---------------------------------------
1826    fig, axes = plt.subplots(1, 2, figsize=(8, 3.4))
1827    single = DecisionTree().fit(X, y)
1828    forest = RandomForest(n_trees=100).fit(X, y)
1829    regions(axes[0], single, f"one deep tree: {_accuracy(single, X_val, y_val):.1%} on validation")
1830    regions(axes[1], forest, f"forest of 100: {_accuracy(forest, X_val, y_val):.1%} on validation")
1831    fig.tight_layout()
1832    figs["forest_regions"] = fig
1833
1834    # --- 5. Validation accuracy vs number of trees --------------------------
1835    curve = forest_curve(n_trees=(1, 2, 3, 5, 7, 10, 15, 20, 30, 50, 75, 100))
1836    fig, ax = plt.subplots(figsize=(6, 3.4))
1837    ax.plot([r["n_trees"] for r in curve], [r["val_accuracy"] for r in curve], "o-", color=BLUE, label="random forest")
1838    ax.axhline(curve[0]["single_tree"], color=ORANGE, ls="--", label="one deep tree, all the data")
1839    ax.set_xscale("log")
1840    ax.set_xlabel("number of trees (log scale)")
1841    ax.set_ylabel("validation accuracy")
1842    ax.set_title("Adding trees helps, then levels off")
1843    ax.legend(frameon=False, loc="lower right")
1844    figs["forest_curve"] = fig
1845
1846    # --- 6. Boosting builds a curve from steps ------------------------------
1847    Xr, yr = sine_data(80, seed=0)
1848    line = np.linspace(0, 6, 400)[:, None]
1849    model = GradientBoosting(n_rounds=50, learning_rate=0.3, max_depth=2).fit(Xr, yr)
1850    staged = model.staged_scores(line)
1851    fig, axes = plt.subplots(1, 3, figsize=(10, 3.2), sharey=True)
1852    for ax, m in zip(axes, (1, 5, 50)):
1853        ax.scatter(Xr[:, 0], yr, s=8, color=MUTED)
1854        ax.plot(line[:, 0], np.sin(line[:, 0]), color=DARK, lw=1, ls=":", label="true curve sin(x)")
1855        ax.plot(line[:, 0], staged[m], color=BLUE, lw=2, label="boosted trees")
1856        ax.set_title(f"after {m} round{'s' if m > 1 else ''}")
1857        ax.set_xlabel("x")
1858    axes[0].set_ylabel("y")
1859    axes[0].legend(frameon=False, loc="lower left", fontsize=8)
1860    fig.tight_layout()
1861    figs["boosting_steps"] = fig
1862
1863    # --- 7. Training and validation loss per round, by learning rate --------
1864    fig, ax = plt.subplots(figsize=(6.4, 3.6))
1865    for row, color in zip(boosting_curves(), (ORANGE, "#7c3aed", BLUE)):
1866        lr = row["learning_rate"]
1867        ax.plot(row["train_loss"], color=color, lw=1, ls="--")
1868        ax.plot(row["val_loss"], color=color, lw=2, label=f"η = {lr:g} (best validation at round {row['best_round']})")
1869        ax.plot(row["best_round"], min(row["val_loss"]), "o", color=color)
1870    ax.axhline(0.09, color=MUTED, lw=1)
1871    ax.text(200, 0.095, "noise floor 0.3² = 0.09", ha="right", va="bottom", color=DARK, fontsize=8)
1872    ax.set_ylim(0, 0.7)
1873    ax.set_xlabel("boosting round")
1874    ax.set_ylabel("mean squared error")
1875    ax.set_title("Solid: validation. Dashed: training.")
1876    ax.legend(frameon=False)
1877    figs["boosting_curves"] = fig
1878
1879    # --- 8. The tabular showdown --------------------------------------------
1880    scores = tabular_showdown()
1881    _, _, _, y_tab, _ = make_tabular()
1882    fig, ax = plt.subplots(figsize=(6.4, 3.4))
1883    names_ = list(scores)
1884    colors = [BLUE if not k.startswith("neural") else ORANGE for k in names_]
1885    ax.barh(names_, [scores[k] for k in names_], color=colors)
1886    majority = max(y_tab.mean(), 1 - y_tab.mean())
1887    ax.axvline(majority, color=DARK, ls="--")
1888    ax.text(majority + 0.004, -0.75, f"always say 'fine': {majority:.2%}", va="bottom", color=DARK, fontsize=8)
1889    for i, k in enumerate(names_):
1890        ax.text(scores[k] + 0.004, i, f"{scores[k]:.2%}", va="center")
1891    ax.set_ylim(len(names_) - 0.5, -1.1)
1892    ax.set_xlim(0.7, 1.0)
1893    ax.set_xlabel("validation accuracy on the loan table")
1894    ax.set_title("Trees read the table as it is; the net needs help")
1895    figs["showdown"] = fig
1896
1897    # --- 9. Impurity importance vs permutation importance -------------------
1898    Xt, yt, Xtv, ytv, tab_names = make_tabular()
1899    forest = RandomForest(n_trees=30).fit(Xt, yt)
1900    imp, perm = forest.feature_importances, permutation_importance(forest, Xtv, ytv)
1901    fig, (a1, a2) = plt.subplots(1, 2, figsize=(9, 3.2), sharey=True)
1902    a1.barh(tab_names, imp, color=BLUE)
1903    a2.barh(tab_names, perm, color=ORANGE)
1904    for a, vals, fmt in ((a1, imp, "{:.0%}"), (a2, perm, "{:.2%}")):
1905        for i, v in enumerate(vals):
1906            a.text(v + 0.003, i, fmt.format(v), va="center")
1907    a1.invert_yaxis()
1908    a1.set_title("Impurity importance (training data)")
1909    a1.set_xlabel("share of impurity removed")
1910    a2.set_title("Permutation importance (validation data)")
1911    a2.set_xlabel("accuracy lost when the column is shuffled")
1912    fig.tight_layout()
1913    figs["importance"] = fig
1914
1915    return figs
Plot this lesson's data. matplotlib is imported here, and only here, so the lesson itself needs nothing beyond NumPy.
1923def demo() -> None:
1924    banner("1. Sorting eight emails: which question first?")
1925    X, y, names = spam_emails()
1926    say(
1927        f"""
1928        Eight emails, four spam and four not. Before any question the pile has
1929        Gini impurity {gini(y):.2f}: two labels drawn at random disagree half
1930        the time. The tree tries every question it could ask:
1931        """
1932    )
1933    table(["question", "weighted Gini after"], [(f"{names[c.feature]} > {c.threshold:g}", c.impurity) for c in candidate_splits(X, y)], floatfmt=".3f")
1934    takeaway("'Known sender?' leaves the least mess (0.2), so it becomes the first question.")
1935
1936    banner("2. The grown tree, as rules a person can read")
1937    tree = DecisionTree(max_depth=2).fit(X, y)
1938    print("\n".join(tree.rules(names, ["ham", "spam"])))
1939    print()
1940    say("Two questions sort all eight emails. The whole model is those five lines.")
1941
1942    banner("3. Overfitting: depth against training and validation accuracy")
1943    table(
1944        ["depth limit", "leaves", "train acc", "val acc"],
1945        [(r["depth"] or "none", r["leaves"], r["train_accuracy"], r["val_accuracy"]) for r in depth_sweep()],
1946        floatfmt=".3f",
1947    )
1948    takeaway("With no limit the tree scores 100% on training data and worst on validation: it memorised the noise.")
1949
1950    banner("4. Random forests: bootstrap samples, random features, one vote")
1951    say(
1952        f"""
1953        A bootstrap sample of n rows leaves each row out with chance
1954        (1 - 1/n)^n: {out_of_bag_fraction(8):.4f} for n = 8, approaching 1/e =
1955        {1 / math.e:.4f}. Averaging B trees with correlation 0.3 leaves variance
1956        {averaged_variance(1.0, 0.3, 10):.2f} at B = 10 and
1957        {averaged_variance(1.0, 0.3, 1000):.4f} at B = 1000: the correlation is the floor.
1958        """
1959    )
1960    table(["trees", "val acc", "one deep tree"], [(r["n_trees"], r["val_accuracy"], r["single_tree"]) for r in forest_curve()], floatfmt=".3f")
1961    takeaway("Many deep, decorrelated trees averaged together keep their low bias and lose much of their variance.")
1962
1963    banner("5. Gradient boosting by hand: four houses, one round")
1964    ex = boosting_worked_example()
1965    table(
1966        ["size", "price y", "F0", "residual", "stump h1", "F1 = F0 + 0.5·h1"],
1967        [(s, p, ex["F0"], r, h, f) for s, p, r, h, f in zip((1, 2, 3, 4), (1, 2, 6, 7), ex["residuals"], ex["stump"], ex["F1"])],
1968        floatfmt=".2f",
1969    )
1970    say(f"Mean squared error falls from {ex['mse'][0]} to {ex['mse'][1]} in one round.")
1971    for row in boosting_curves():
1972        say(
1973            f"""
1974            Learning rate {row['learning_rate']:g}: best validation MSE
1975            {min(row['val_loss']):.3f} at round {row['best_round']}; by round 200 it
1976            is {row['val_loss'][-1]:.3f} while training MSE is {row['train_loss'][-1]:.3f}.
1977            """
1978        )
1979    takeaway("Each tree fits what is still wrong. Smaller steps take longer and generalize better; too many rounds memorise.")
1980
1981    banner("6. When trees win: a loan table")
1982    scores = tabular_showdown()
1983    table(["model", "val accuracy"], list(scores.items()), floatfmt=".4f")
1984    say(
1985        """
1986        The trees took the table as it came: dollars, years, counts and region
1987        codes. The neural net learned nothing from raw inputs (it matches
1988        always predicting 'fine'), improved once scaled, and improved again
1989        once income was logged and regions one-hot encoded, and still trailed.
1990        """
1991    )
1992    Xt, yt, Xv, yv, tab_names = make_tabular()
1993    forest = RandomForest(n_trees=30).fit(Xt, yt)
1994    table(
1995        ["feature", "impurity importance", "permutation importance"],
1996        list(zip(tab_names, forest.feature_importances, permutation_importance(forest, Xv, yv))),
1997        floatfmt=".3f",
1998    )
1999    takeaway(
2000        "Impurity importance gives the pure-noise column real credit; shuffling it on held-out data shows the model "
2001        "barely relies on it. Check importances on data the model has not seen."
2002    )