primer.ml.embeddings.ann
Vector search: finding the nearest neighbors without checking everyone
Run: python -m primer.ml.embeddings.ann
New to the notation? primer.notation explains every symbol used here from
zero (vectors, Σ, logarithms, big-O).
Level 1: The practitioner's guide
In one sentence. An approximate nearest neighbor (ANN) index finds the stored vectors most similar to a query without comparing it against every one, trading a small, measurable loss of accuracy for searches that stay fast and affordable as a collection grows to millions of vectors.
When you need it. Every search over embeddings ends the same way: the
question becomes a vector, and the answers are the stored vectors nearest to
it. The honest way to find them is a flat search, one comparison per
stored vector, and it is exact. It is also the ground truth every index is
judged against, and below about a million vectors it is often the right
choice: simple, exact, fast enough. You need an index when the collection
outgrows it. At 10 million vectors of 1,536 dimensions a flat search costs
about 15 billion multiply-adds per query, and the raw vectors alone take
about 61 GB of memory (this lesson's storage_estimate does the sum). The
tell: query latency grows in step with the number of documents, or the
vectors no longer fit in one machine's memory.
Your options. Four ideas cover almost every vector database in use, and a fifth takes them past the size of one machine's memory. From the simplest to the most scalable:
| Option | What it does | What it gives you | What it costs | Where it lives |
|---|---|---|---|---|
| Flat search | Compares the query with every stored vector | Exact results: recall 1.0, by definition | One comparison per stored vector per query; every vector in memory | NumPy, FAISS Flat, a pgvector column with no index |
| IVF (inverted file) | Sorts the vectors into clusters ahead of time; a query opens only the nprobe nearest clusters |
High recall at a fraction of the work, rising with nprobe until it equals a flat scan |
A k-means training step before the first insert, and retraining when the data drifts | FAISS IVF, pgvector ivfflat |
| PQ (product quantization) | Compresses each vector to a few bytes and scores by table lookup | A collection 8 to 64 times smaller in memory, and a good shortlist | Lossy scores: re-score the shortlist with exact vectors or recall suffers | FAISS IVF...,PQ, ScaNN |
| HNSW (layered graph) | Links each vector to a few neighbors on stacked layers; a query hops from coarse to fine | High recall at low latency, tuned per query with efSearch, with no training step |
Memory for every vector plus its links; slow builds at scale | hnswlib, FAISS HNSW, pgvector hnsw, Elasticsearch, Qdrant |
| Disk-resident graph | Keeps the graph and full vectors on an SSD and a compressed copy in memory | A billion vectors on one machine | SSD reads per query and a long build | DiskANN |
How to choose. Start from the size of the collection and the memory you have.
- Under about a million vectors: flat search. Measure it before you build anything; it may already be fast enough, and it is what you will compare every index against.
- Millions of vectors, memory to spare: HNSW. It is the default in most
vector databases because it gives high recall at low latency with no
training step. Set
Maround 16 (32 to 64 for high-dimensional data), build withefConstructionof 100 to 400, then tuneefSearchat query time. - Millions of vectors, memory tight: IVF with PQ codes, re-scoring a
shortlist with the exact vectors. Choose
nlistnear the square root of N (FAISS's guidelines say 4√N to 16√N below a million vectors, with 30 to 256 training vectors per cluster), then tunenprobe. - Billions of vectors: IVF-PQ, HNSW sharded across machines, or a disk-based graph. DiskANN indexes a billion points on one workstation with 64 GB of memory and an SSD.
- Whatever you pick, measure recall@k against a flat index on your own vectors while you turn the dial, then check the 95th-percentile latency. A benchmark on other data predicts little, because the shape of the data decides where the curve flattens.
What it costs. Three currencies: memory, build time and recall.
- Memory. Raw float32 vectors cost 4 bytes per dimension: about 3 GB for a
million 768-dimensional vectors, 3 TB for a billion. HNSW adds its links,
roughly
Mtimes 8 to 10 bytes per vector by hnswlib's estimate (1.69 MB against the flat index's 1.28 MB in this lesson's run on 5,000 vectors of 64 dimensions). PQ goes the other way: 96 one-byte codes for a 3,072-byte vector is a 32× saving, so a billion vectors fit in about 100 GB instead of 3 TB. - Build time. Flat builds instantly and IVF needs one k-means pass. HNSW inserts each vector by first searching for its neighbors, so a build is one search per vector: the slowest to build in this lesson's run, and pgvector documents the same trade (HNSW: a better speed-recall trade-off, slower builds, more memory; IVFFlat: the reverse).
- Recall. Every index has one dial, and the last few points of recall are
the expensive ones. In this lesson's run, HNSW at
efSearch10 reaches recall@10 of 0.49 while comparing 5.5% of the collection, and 0.99 at 160 while comparing 36%. IVF atnprobe1 gives 0.33, at 16 gives 0.96, and at 70 (every list) gives 1.0. PQ scores alone at 8 bytes per vector give 0.35; re-scoring the top 100 with exact vectors lifts that to 0.88. - Latency. This lesson's pure-Python timings are only relative; FAISS or hnswlib run the same searches around 100× faster. DiskANN reports more than 5,000 queries per second at under 3 ms mean latency on a billion points.
What breaks.
- Recall you never measured. An index that scored 0.99 on a benchmark can do worse on your vectors, because ANN accuracy depends on the data's structure. Keep a flat index of a sample and measure recall@k against it.
- A neighbor across a cluster boundary. IVF's blind spot: the true
nearest vector sits in a cell the query didn't open. Raise
nprobe, and retrain the centroids when the data changes a lot. - Ranking by compressed scores. PQ is excellent at shortlisting and poor at final ranking: at 8 bytes per vector it finds under half of the true top 10 on its own. Always re-score the shortlist with the exact vectors.
- Running out of memory. HNSW must hold every vector and every link in memory. When it no longer fits, move to IVF-PQ, shard across machines, or use a disk-based graph.
- A greedy walk stuck in a corner. A search that only hops to closer
neighbors stops at a point with none closer even when a closer one
exists; the beam (
efSearch) protects against that, and can never be set below k. - A filter applied after the search. Keep only the results a user may see after asking for the top 10, and you can be left with none. Qdrant's documentation describes extra graph edges from indexed metadata so filters apply during the search; where your database filters afterwards, ask for more candidates than you need.
In the wild. FAISS, Meta's library, ships every index in this lesson
and publishes guidelines that pick one by collection size. hnswlib is the
reference HNSW implementation from the paper's authors, and its parameter
guide is where this lesson's knob table comes from. Databases have absorbed
the same indexes: pgvector adds hnsw (defaults m 16, ef_construction
64, ef_search 40) and ivfflat indexes to PostgreSQL; Elasticsearch's
dense_vector fields index with HNSW (m 16, ef_construction 100) and
offer quantized variants; Qdrant builds every collection on a filterable
HNSW (m 16, ef_construct 100). Google's ScaNN pairs partitioning with
anisotropic quantization and re-scoring. DiskANN (Subramanya et al.,
NeurIPS 2019) put a billion points on one workstation by keeping the graph
on an SSD. ANN-Benchmarks publishes recall-versus-throughput curves across
these libraries. The papers behind this lesson (HNSW, product quantization
and the Faiss library) are listed at the end with their companions.
Go deeper. Level 2 builds each index by hand on eight points you can check with a pencil: the flat scan, IVF's centroids and cells, PQ's codebooks and lookup tables, and HNSW's layered graph with its greedy descent, beam search and the random draw that decides which vectors become highways. Then it measures all four on 5,000 vectors and draws the recall-versus-work curves. If you only needed to choose an index and set its dial, you are done.
Level 2: How it works, from scratch
Level 2 builds every index above from nothing, starting with a picture and eight points on a map.
The everyday picture. You've just moved to a new country and want the house nearest to a landmark. You could walk up to every house in the country and measure the distance. That's always right, but it takes forever. Or you could do what everyone actually does: take the highway to the right region, switch to main roads to the right town, then walk the side streets to the house. You check only a handful of places and still end up at (almost always) the right door.
That is the whole problem of this lesson. A search engine that works on
meaning stores every document as a vector (a list of numbers, see
primer.ml.embeddings.similarity) and turns the question into a vector too.
The best documents are the vectors nearest the question. With ten million
documents, "walk to every house" is too slow, so we build a map with
highways. Structures like that are called approximate nearest neighbor
(ANN) indexes. Approximate because, like the traveller, they very
occasionally stop at the second-nearest house instead of the nearest.
Four ideas cover almost every vector database in use:
| Index | Everyday picture | What you give up |
|---|---|---|
| Flat | Visit every house | Nothing; it's exact. Just slow at scale |
| IVF | A library sorts books into sections; you search only the few nearest sections | Books shelved in the section next door |
| PQ | Describe a face by picking the closest nose, eyes and mouth from a small catalogue | Fine detail: the description is lossy |
| HNSW | Highway, then main roads, then side streets | Memory for all the roads, and the occasional near-miss |
A few words used throughout, in plain terms:
- Similarity score. How alike two vectors are. Here we use the dot product (multiply the two lists position by position and add up). All vectors are rescaled to length 1 first (normalized), so the dot product equals the cosine similarity, which runs from −1 (opposite) to 1 (identical). Higher means closer.
- Top k. The k best matches, e.g. the top 10.
- Recall@k. Of the true top k (found by exhaustive search), the fraction
the index actually returned. Recall@10 = 0.9 means it found 9 of the true
- It's the standard measure of an ANN index's accuracy.
- Big-O, e.g. O(N). How the work grows with the data. O(N) means doubling the number of vectors N doubles the work; O(log N) means doubling N adds only one more step.
A tiny worked example: eight houses on a map
Every index in this lesson is shown first on the same eight points, drawn on a flat map so you can check each step with a pencil. The question (the query) sits at (5, 4). On a flat map "near" is ordinary distance; we keep it squared (dx² + dy²) so every number stays whole. Squaring doesn't change which point is nearest.
| Point | Position | Squared distance to the query (5, 4) |
|---|---|---|
| A | (0, 0) | 5² + 4² = 41 |
| B | (2, 1) | 3² + 3² = 18 |
| C | (4, 0) | 1² + 4² = 17 |
| D | (1, 3) | 4² + 1² = 17 |
| E | (3, 3) | 2² + 1² = 5 |
| F | (5, 2) | 0² + 2² = 4 |
| G | (2, 5) | 3² + 1² = 10 |
| H | (5, 5) | 0² + 1² = 1 ← the true nearest |
Checking all eight rows is flat search. It's exact, and it costs one distance per stored point.
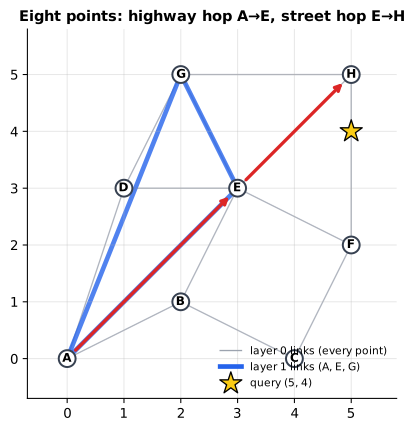
Reading it: the eight dots are the stored points and the yellow star is the query at (5, 4). Thin grey lines are the "streets" (layer 0: every point, linked to its neighbors); the thick blue lines are the "highway" (layer 1: only A, E and G). The red arrows are the HNSW search worked through below: one highway hop from A to E, then one street hop from E to H. It checked a few points near its route instead of reading the whole table.
1. Flat search: the exact baseline
flowchart LR
  Q[Query vector] --> D["Dot product with<br/>EVERY stored vector<br/>(N comparisons)"]
  D --> T[Keep the k highest]
  T --> R[Exact top k]
Reading it: there is only one path and no shortcuts. The middle box touches every stored vector, which is why the cost grows in step with N. It is always exactly right, so every other index is measured against it: its answer is the "truth" in recall@k.
Level 3: the formula and its symbols
$$ s(q, x) = q \cdot x = \sum_{i=1}^{d} q_i \, x_i $$
Symbols
| Symbol | Meaning here | Range |
|---|---|---|
| q | the query vector | d numbers, length 1 |
| x | one stored vector | d numbers, length 1 |
| d | number of dimensions (numbers per vector) | 2 in the toy; 384 to 3072 in practice |
| i | position in the vector, counted from 1 | 1 … d |
| q_i, x_i | the i-th number of q and of x | −1 … 1 |
| Σ | "add up the following for every i from 1 to d" | |
| s(q, x) | similarity score, the dot product | −1 … 1 for unit vectors |
In words: the score of a stored vector is what you get by multiplying it with the query number by number and adding the results.
On the example: with unit vectors q = (0.8, 0.6) and x = (0.6, 0.8): s = 0.8·0.6 + 0.6·0.8 = 0.48 + 0.48 = 0.96, very similar.
Level 3: in Python
In Python:
q = [0.8, 0.6]
x = [0.6, 0.8]
# s(q, x) = Σ q_i x_i
round(sum(q_i * x_i for q_i, x_i in zip(q, x)), 2)  # → 0.96
points = {"A": (0, 0), "B": (2, 1), "C": (4, 0), "D": (1, 3),
          "E": (3, 3), "F": (5, 2), "G": (2, 5), "H": (5, 5)}
query = (5, 4)
def sq_dist(p):
    return (p[0] - query[0]) ** 2 + (p[1] - query[1]) ** 2
# flat search on the map: check all eight
min(points, key=lambda name: sq_dist(points[name]))  # → 'H'
In code: FlatIndex.search scores the query against every stored vector
and keeps the best k with top_k; normalize rescales vectors to length 1
first, so the dot product is the cosine.
Why it matters: flat search costs N·d multiply-adds per query. At 10 million vectors of 1,536 dimensions that's about 15 billion, far too many for an interactive search, and the raw vectors alone take 10,000,000 × 1,536 × 4 bytes ≈ 61 GB of memory. Below about a million vectors, flat search is often the right answer: simple, exact, and fast enough.
In code: storage_estimate does that memory sum for any n and d.
2. IVF: search only the nearest sections of the library
The everyday picture. A library doesn't search every shelf for a book about sailing. It sorts books into sections ahead of time, and you go to "Sports" and maybe "Travel", the one or two most promising sections, and search only there. A sailing book shelved in the wrong section is missed unless you check that section too.
On the eight points. Split them into two groups (clusters) ahead of time: left = {A, B, C, D} and right = {E, F, G, H}. Each cluster is summarized by its centroid, the average position of its members: left = (1.75, 1), right = (3.75, 3.75). For the query (5, 4):
| Cluster | Centroid | Squared distance to (5, 4) |
|---|---|---|
| left | (1.75, 1) | 3.25² + 3² = 19.5625 |
| right | (3.75, 3.75) | 1.25² + 0.25² = 1.625 ← probe this one |
Scan only E, F, G, H: the nearest is H (distance 1). That's 2 centroid checks + 4 point checks = 6 instead of 8. With a million points in 1,000 clusters the saving is enormous.
flowchart TB
  subgraph BUILD["Ahead of time"]
    V[All vectors] --> KM["k-means: find nlist centroids"]
    KM --> L["Put each vector on the list<br/>of its nearest centroid"]
  end
  subgraph QUERY["At query time"]
    Q[Query] --> C["Compare with the nlist centroids"]
    C --> P["Pick the nprobe nearest"]
    P --> S["Scan only those lists"]
    S --> R[Top k]
  end
  L -.-> S
Reading it: the top box runs once, when the index is built: k-means
(a simple clustering method: guess centroids, assign every vector to its
nearest, move each centroid to the average of its members, repeat) sorts the
vectors into nlist lists. The bottom box runs per query and never touches
lists it didn't pick. The only dial is nprobe: how many lists to open.
The set of all points closer to one centroid than to any other is called that centroid's Voronoi cell: the "section" of the library. IVF's blind spot is a true neighbor sitting just across a cell boundary.
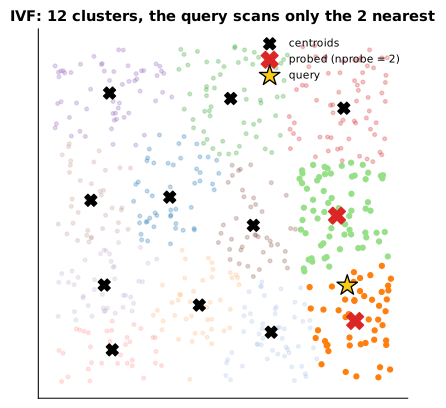
Reading it: 600 points, colored by which of 12 centroids (black X) they
belong to; each color patch is a Voronoi cell. The query (yellow star)
compares itself with the 12 centroids, then scans only the two nearest cells
(red X, bright points). The faded points are never looked at. A true neighbor
sitting just across a boundary, in a faded cell, would be missed, which is
exactly why raising nprobe raises recall.
Level 3: the formula and its symbols
$$ \text{comparisons per query} \approx n_{\text{list}} + N \cdot \frac{n_{\text{probe}}}{n_{\text{list}}} $$
Symbols
| Symbol | Meaning here | Typical range |
|---|---|---|
| N | number of stored vectors | thousands to billions |
| n_list | number of clusters (lists) | ≈ √N, e.g. 1,000 for 1M vectors |
| n_probe | clusters scanned per query, the recall dial | 1 … n_list |
| N · n_probe / n_list | vectors in the scanned lists, assuming equal-size clusters |
In words: you pay once to compare with every centroid, plus the share of the collection that lives in the clusters you open.
On the example: 2 + 8 · 1/2 = 6 comparisons (versus 8). At N = 1,000,000, n_list = 1,000, n_probe = 10: 1,000 + 10,000 = 11,000, about 1% of a flat scan.
Level 3: in Python
In Python:
left = [(0, 0), (2, 1), (4, 0), (1, 3)]
right = [(3, 3), (5, 2), (2, 5), (5, 5)]
def centroid(members):
    return tuple(sum(p[i] for p in members) / len(members) for i in range(2))
centroid(left), centroid(right)  # → ((1.75, 1.0), (3.75, 3.75))
# probe the nearer
[(c[0] - 5) ** 2 + (c[1] - 4) ** 2 for c in (centroid(left), centroid(right))]  # → [19.5625, 1.625]
def comparisons(N, n_list, n_probe):
    # n_list centroids + the vectors in the opened lists
    return n_list + N * n_probe // n_list
comparisons(8, 2, 1)  # → 6
comparisons(1_000_000, 1_000, 10)  # → 11000
In code: IVFIndex.train finds the centroids with kmeans,
IVFIndex.add files each vector on its nearest centroid's list, and
IVFIndex.search scans only the nprobe nearest lists. tiny_ivf_search
replays the eight-point example.
Why it matters: IVF is cheap to build and light on memory, and
nprobe = nlist gives you back an exact flat search, which is a handy
sanity check. Its accuracy depends on how well the clusters fit the data, so
retrain the centroids when the data changes a lot.
3. PQ: store each vector as a few catalogue numbers
The everyday picture. A police sketch artist doesn't record every pixel of a face. They pick the closest nose from a catalogue of 256 noses, the closest eyes from 256 eyes, the closest mouth, and so on. The whole face becomes a handful of catalogue numbers: tiny to store, close enough to recognize someone. That's product quantization (PQ). To quantize means to round a value to the nearest entry of a fixed set.
On a 4-number vector. Split x = (0.9, 0.1, −0.2, 0.8) into two halves. Each half is matched against a four-entry catalogue (a codebook), here the four compass directions: 0 = (1, 0), 1 = (0, 1), 2 = (−1, 0), 3 = (0, −1).
| Half | Values | Nearest catalogue entry | Code |
|---|---|---|---|
| 1 | (0.9, 0.1) | (1, 0) | 0 |
| 2 | (−0.2, 0.8) | (0, 1) | 1 |
The vector is now stored as two codes, [0, 1]. To score the query q = (1, 0, 0, 1) against any stored vector, first build one small table per half: the query's half dotted with each catalogue entry.
| entry 0 | entry 1 | entry 2 | entry 3 | |
|---|---|---|---|---|
| T₁ (q's half 1 = (1, 0)) | 1 | 0 | −1 | 0 |
| T₂ (q's half 2 = (0, 1)) | 0 | 1 | 0 | −1 |
The approximate score of codes [0, 1] is T₁[0] + T₂[1] = 1 + 1 = 2. The exact score is 0.9 + 0.8 = 1.7: close, not identical. That's the price of compression.
flowchart LR
  subgraph ENC["Encode (once per vector)"]
    X["x: d numbers"] --> SPLIT["split into m pieces"]
    SPLIT --> NN["each piece → nearest of<br/>256 codebook entries"]
    NN --> CODE["m one-byte codes"]
  end
  subgraph ADC["Score (per query)"]
    Q["query q"] --> TAB["m small tables:<br/>q's piece · every entry"]
    TAB --> SUM["score = sum of m<br/>table lookups"]
  end
  CODE --> SUM
Reading it: the left box shrinks every stored vector to m bytes, once. The right box is the trick: the query is not compressed. We precompute m tables of 256 numbers, and then scoring any stored vector is just m lookups and additions, with no multiplication at all. Keeping the query exact while the stored side is compressed is called asymmetric distance computation (ADC).
Level 3: the formula and its symbols
$$ \hat{s}(q, x) = \sum_{j=1}^{m} T_j\big[c_j(x)\big], \qquad T_j[c] = q^{(j)} \cdot C_j[c] $$
Symbols
| Symbol | Meaning here | Range |
|---|---|---|
| m | number of pieces each vector is split into | 2 in the toy; 8 to 96 in practice |
| j | which piece, counted from 1 | 1 … m |
| q^(j) | the j-th piece of the query (d/m numbers) | |
| C_j | the codebook for piece j: its catalogue of entries | 2^nbits entries, usually 256 |
| C_j[c] | entry number c of that catalogue | |
| c_j(x) | the code stored for piece j of x: which entry was nearest | 0 … 255 (one byte) |
| T_j[c] | precomputed table: q's piece j dotted with entry c | |
| ŝ(q, x) | approximate score ("s-hat": the hat means estimate) |
In words: the estimated score is the sum, over the pieces, of the table value for whichever catalogue entry that piece of the stored vector was rounded to.
On the example: ŝ = T₁[c₁] + T₂[c₂] = T₁[0] + T₂[1] = 1 + 1 = 2 (exact: 1.7).
Level 3: in Python
In Python:
# the compass codebook, used for both pieces
C = [(1, 0), (0, 1), (-1, 0), (0, -1)]
def dot(a, b):
    return sum(a_i * b_i for a_i, b_i in zip(a, b))
def sq_dist(a, b):
    return sum((a_i - b_i) ** 2 for a_i, b_i in zip(a, b))
x = [0.9, 0.1, -0.2, 0.8]
pieces = [x[0:2], x[2:4]]
# c_j(x)
codes = [min(range(4), key=lambda c: sq_dist(piece, C[c])) for piece in pieces]
codes  # → [0, 1]
q = [1, 0, 0, 1]
# T_j[c] = q^(j) · C_j[c]
T = [[dot(q_j, C[c]) for c in range(4)] for q_j in (q[0:2], q[2:4])]
T  # → [[1, 0, -1, 0], [0, 1, 0, -1]]
# ŝ = Σ_j T_j[c_j(x)]
sum(T[j][codes[j]] for j in range(2))  # → 2
# the exact score, for comparison
round(dot(q, x), 2)  # → 1.7
In code: ProductQuantizer learns the codebooks (ProductQuantizer.train),
rounds vectors to codes (ProductQuantizer.encode), builds the Tⱼ tables
(ProductQuantizer.lookup_table) and sums the lookups
(ProductQuantizer.adc_scores). tiny_pq_example replays the 4-number
example by hand-setting the compass codebooks.
Why it matters: a 768-dimension float32 vector is 3,072 bytes; with m = 96 it's 96 bytes, 32× smaller, so a billion vectors fit in about 100 GB instead of 3 TB. The lost accuracy is recovered by re-scoring: take the top few hundred by PQ score and recompute their exact scores from the full vectors kept on disk. Real systems combine PQ with IVF (IVF-PQ) and encode each vector's residual (its offset from its cluster centroid), which is smaller and so rounds more precisely.
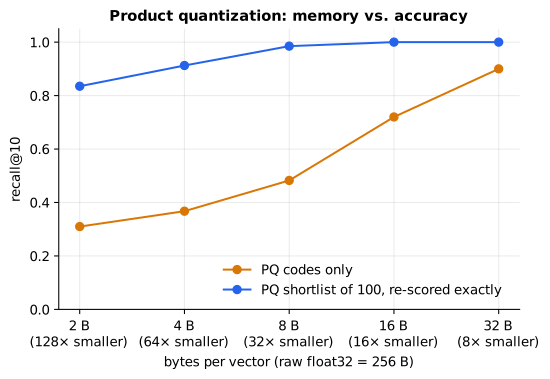
Reading it: left to right, each vector gets more bytes (less compression). The orange line uses PQ scores alone: at 8 bytes per vector (32× smaller than the raw 256 bytes) it finds under half of the true top 10. The blue line re-scores PQ's top 100 with the exact vectors and is near perfect from 8 bytes up. The lesson: PQ is excellent at shortlisting and poor at final ranking, so production systems always re-score.
In code: PQIndex scans every PQ code and can re-score its top
candidates with the exact vectors; IVFPQIndex combines IVF lists with
PQ-encoded residuals.
4. HNSW: highway, main roads, side streets
The everyday picture. Back to the traveller: highways to get close fast, main roads to get closer, side streets to find the door. HNSW (Hierarchical Navigable Small World) builds exactly that as a graph: a set of points (nodes) joined by links (edges). Every vector is a node on the bottom layer (the side streets). A random few are also placed on layer 1 (main roads), fewer still on layer 2 (highways), and so on.
On the eight points. Layer 1 holds only A, E and G. Layer 0 holds all eight, linked to nearby points (the thin lines in the figure above). A greedy search means "always move to whichever neighbor is closest to the target; stop when none is closer". Start at A:
| Step | Layer | At | Neighbors checked (squared distance) | Move? |
|---|---|---|---|---|
| 1 | 1 | A (41) | E (5), G (10) | → E |
| 2 | 1 | E (5) | A (41), G (10) | no closer neighbor: drop a layer, staying at E |
| 3 | 0 | E (5) | B (18), D (17), F (4), G (10), H (1) | → H |
| 4 | 0 | H (1) | E (5), F (4), G (10) | no closer neighbor: done. Answer: H |
flowchart TD
  subgraph L2["Top layer: few nodes, long jumps"]
    A2[A] --- D2[D]
  end
  subgraph L1["Middle layer: more nodes"]
    A1[A] --- B1[B] --- D1[D] --- E1[E]
  end
  subgraph L0["Bottom layer: every vector"]
    A0[A] --- B0[B] --- C0[C] --- D0[D] --- E0[E] --- F0[F]
  end
  D2 -.-> D1
  E1 -.-> E0
Reading it: three layers of the same kind of map, fewer nodes the higher you go. Solid lines are links within a layer; dotted arrows are "the same node, one layer down". A search enters at the top, crosses a lot of ground in a few long jumps (A to D), then follows a dotted arrow down and continues from the same node with finer steps, until the bottom layer, where every vector lives.
In code: tiny_hnsw_search replays the greedy walk from the table above
on the eight-point map and returns every stop; HNSWIndex is the full index
used on real vectors.
The search, step by step
flowchart TD
  S[Start at the entry point<br/>on the top layer] --> G{Is any neighbor<br/>closer to the query?}
  G -->|yes| H[Hop to the closest neighbor] --> G
  G -->|no| B{On the bottom layer?}
  B -->|no| DOWN[Drop one layer,<br/>same node] --> G
  B -->|yes| BEAM["Beam search: keep the best efSearch<br/>candidates, expand the most promising<br/>until nothing better turns up"]
  BEAM --> K[Return the top k]
Reading it: the loop at the top is greedy descent: hop while something
closer exists, else drop a layer. On the upper layers it keeps a single best
node. On the bottom layer it switches to a beam search, which keeps a
shortlist of the best efSearch nodes found so far, not just one, and keeps
exploring from the most promising. That wider net is what protects against
getting stuck at a point that is only locally the best. efSearch is the
dial you tune at query time.
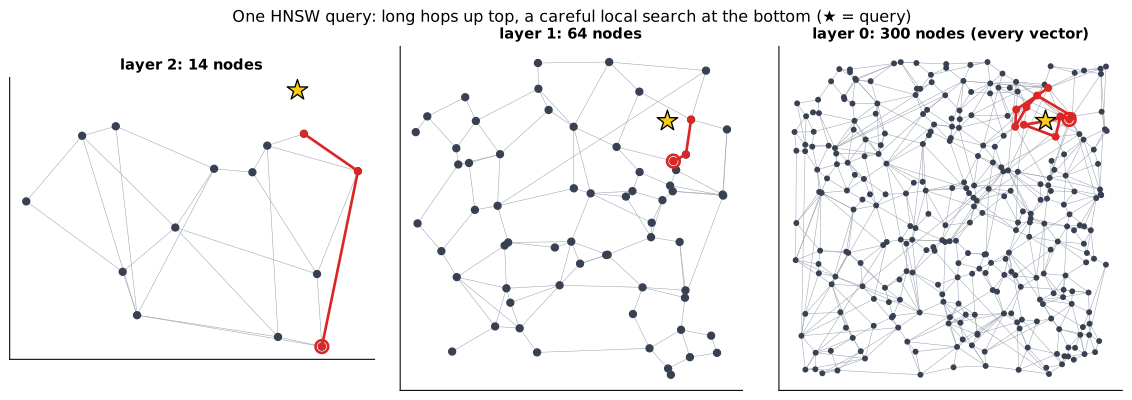
Reading it: this graph has four layers: 300 nodes at the bottom, then 64, then 14, and a single node on top, which is the entry point. The top layer has nothing to hop to, so the figure leaves it out and draws the other three, left to right: 14 nodes, 64, and the bottom with all 300. Grey lines are the graph's links. The red path is one real query (yellow star) run by the code below; the red circle marks where the search entered each layer. On the left it covers most of the map in a couple of long hops. By the bottom layer it is already next to the star, and it only explores a small neighborhood. Out of 300 points, it compared the query with 51, a few dozen.
Try it: the map below has 60 points on four layers. Pick a query and drag Step: watch the walk cross the map in long hops on the sparse upper layers, drop a layer whenever no neighbor is closer, and finish with a short local search on the bottom layer. Then choose query D with a beam of 1 (pure greedy): it stops at a point with no closer neighbor, yet brute force finds a closer one. Widen the beam to 4 and step through again.
In code: HNSWIndex.search runs the greedy descent and the bottom-layer
beam search; HNSWIndex.search_trace does the same and returns every node it
expanded, which is what this figure draws. small_hnsw_map builds the
60-point graph the widget searches, and viz_data hands it to the page.
How the layers are built
flowchart TD
  N[New vector] --> LV["Draw its top layer ℓ at random<br/>(most get 0, a few get more)"]
  LV --> DESC[Greedy descent from the entry point<br/>down to layer ℓ]
  DESC --> FIND["On each layer ≤ ℓ: beam search with<br/>efConstruction to find candidates"]
  FIND --> SEL["Keep up to M diverse neighbors<br/>(the heuristic below)"]
  SEL --> LINK[Link both ways]
  LINK --> PRUNE{Neighbor now has too many links?<br/>more than M, or 2·M on layer 0}
  PRUNE -->|yes| TRIM[Re-select its best-spread links]
  PRUNE -->|no| DONE[Next layer down]
  TRIM --> DONE
Reading it: inserting a vector is a search followed by wiring. The random
draw at the top decides how many layers the node lives on. The search part
is the same as a query, just with a wider beam (efConstruction) for a
better-quality result. The wiring part keeps each node's links to a fixed
budget, so the graph never gets too dense to walk quickly.
The diversity heuristic. When choosing a new node's M neighbors, go through the candidates from nearest to farthest and keep one only if it is closer to the new node than to every neighbor already kept. Otherwise a kept neighbor already "covers" that direction. Without this rule, in clustered data all M links would point into the same clump, and the graph could split into islands a greedy walk can't cross. With it, links fan out in different directions and long "bridges" between clusters survive.
The random layer draw is where the math comes in:
Level 3: the formula and its symbols
$$ \ell = \left\lfloor -\ln(U) \cdot m_L \right\rfloor, \qquad m_L = \frac{1}{\ln M}, \qquad P(\ell \ge l) = M^{-l} $$
Symbols
| Symbol | Meaning here | Range |
|---|---|---|
| ℓ | the top layer the new node will live on | 0, 1, 2, … |
| U | a random number drawn uniformly | 0 < U ≤ 1 |
| ln | natural logarithm: the power you raise e ≈ 2.718 to in order to get the number. ln(1) = 0; ln of a number below 1 is negative, so −ln(U) is positive | |
| ⌊ ⌋ | "floor": round down to a whole number | |
| M | the link budget per node (also sets how fast layers thin out) | 4 to 64; 16 is common |
| m_L | the level multiplier, 1/ln M | ≈ 0.36 for M = 16 |
| P(ℓ ≥ l) | the probability a node reaches layer l or higher | |
| efConstruction | beam width while building | 100 to 400 |
| efSearch | beam width while searching, the recall dial | ≥ k; 50 to 500 |
In words: draw a random number, take minus its logarithm, scale it by one over the log of M, and round down. That gives a node layer 1 or higher with probability 1/M, layer 2 or higher with probability 1/M², and so on.
On the example: M = 16, so m_L = 1/ln 16 = 1/2.773 = 0.361. A draw of U = 0.5 gives −ln 0.5 · 0.361 = 0.693 · 0.361 = 0.25 → floor → layer 0. A draw of U = 0.05 gives 2.996 · 0.361 = 1.08 → layer 1. Only 1/16 = 6.25% of nodes reach layer 1, and 1/256 ≈ 0.4% reach layer 2: each layer has about 1/M as many nodes as the one below, which is what makes the upper layers "highways".
Level 3: in Python
In Python:
import math
M = 16
# m_L = 1 / ln M
m_L = 1 / math.log(M)
round(m_L, 3)  # → 0.361
for U in (0.5, 0.05):
    # -ln(U) · m_L
    scaled = -math.log(U) * m_L
    # ... then round down to get ℓ
    print(U, round(scaled, 2), math.floor(scaled))  # → 0.5 0.25 0 0.05 1.08 1
# P(ℓ ≥ l) = M^(-l): 6.25% and about 0.4%
[M ** -l for l in (1, 2)]  # → [0.0625, 0.00390625]
| Knob | Set when | Higher means |
|---|---|---|
M |
build | more links per node: better recall, more memory, slower build. 16 is a common default; 32 to 64 for high-dimensional data |
efConstruction |
build | a better-quality graph, a slower build |
efSearch |
query time | a wider beam: better recall, slower queries |
In code: HNSWIndex.add inserts each vector this way: draw its layer,
beam-search each layer with efConstruction, keep up to M diverse neighbors
and link both ways. HNSWIndex.layer_sizes counts the nodes on each layer,
and HNSWIndex.memory_bytes adds up the vectors plus their links.
Why it matters: HNSW is the default index in most vector databases because it gives high recall at low latency with no training step. Its costs are memory (every vector plus its links must sit in RAM) and slow builds for very large collections. At billions of vectors, teams switch to IVF-PQ, shard HNSW across machines, or use disk-based graphs (DiskANN).
Turning the dial: recall vs. work
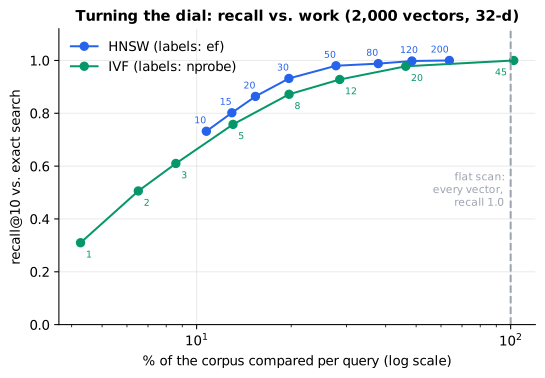
Reading it: each point is one setting of the dial (the small labels are efSearch for HNSW and nprobe for IVF). The x-axis is the share of the whole collection compared per query, on a log scale (each tick is 10× more work), and the dashed line at 100% is a flat scan. The y-axis is recall@10. Read it as a menu: the further up and to the left, the better. HNSW reaches about 0.95 recall while comparing around a fifth of these 2,000 vectors. On real collections of millions the share is far smaller, because the number of hops grows only slowly with N. Both curves rise steeply and then flatten, which is why the last few points of recall are the expensive ones.
Level 3: the formula and its symbols
$$ \text{recall@}k = \frac{\lvert \text{returned top } k \;\cap\; \text{true top } k \rvert}{k} $$
Symbols
| Symbol | Meaning here |
|---|---|
| k | how many results we ask for |
| true top k | the answer from an exact flat search |
| ∩ | "intersection": the items in both lists |
| | | | "the number of items in" |
In words: recall@k is the share of the true top k that the index actually returned.
On the example: if the true top 10 is documents 1 to 10 and the index returns 1 to 9 plus document 42, the overlap is 9, so recall@10 = 9/10 = 0.9.
Level 3: in Python
In Python:
# documents 1 to 10
true_top = set(range(1, 11))
# 1 to 9, plus document 42
returned = set(range(1, 10)) | {42}
k = 10
# |returned ∩ true| / k
len(returned & true_top) / k  # → 0.9
In code: recall_at_k computes this share; ground_truth runs the exact
flat search that supplies the true top k, and evaluate reports recall,
latency and distance computations per query for any index.
Why it matters: recall and latency are traded against each other on every index. The only reliable way to pick a setting is to measure recall@k against a flat index on your own vectors while you turn the dial, then check the 95th-percentile latency.
In 20 seconds
- Flat compares the query with everything: exact, O(N). It's the ground truth, and fine for small collections.
- IVF clusters ahead of time and searches the
nprobenearest clusters. - PQ compresses each vector to a few bytes and scores by table lookup; re-score a shortlist with exact vectors.
- HNSW is a layered graph: long jumps on top, a careful beam search at
the bottom.
efSearchtrades recall for latency;MandefConstructionset graph quality at build time. It's fast and accurate, but memory-hungry. - Always measure recall@k against a flat index on your own data while you turn the dial.
Self-test questions
On the eight-point map, query at (5, 4): walk the HNSW search. Start at A on layer 1 (squared distance 41). Its layer-1 neighbors are E (5) and G (10), so hop to E. No layer-1 neighbor of E is closer, so drop to layer 0 at E. There, H (1) is closer, so hop to H. None of H's neighbors beats 1, so the answer is H.
PQ stores x = (0.9, 0.1, −0.2, 0.8) with the four compass directions as each half's codebook. What are the codes, and what score does the query (1, 0, 0, 1) get? Codes [0, 1]. The lookup tables are [1, 0, −1, 0] and [0, 1, 0, −1], so the approximate score is 1 + 1 = 2, against an exact score of 0.9 + 0.8 = 1.7.
How does an HNSW search proceed, and which knobs change its speed and recall?
Enter at the top layer's entry point; greedily hop to whichever neighbor is
closest to the query until none is closer, then drop a layer at the same
node; at layer 0 run a beam search keeping efSearch candidates; return the
top k. Build-time knobs: M (links per node; memory and recall) and
efConstruction (graph quality; build time). Query-time knob: efSearch. Raise
it until recall@k against a flat index meets your target, then check p95
latency.
Why does HNSW need a "diversity" rule when choosing neighbors? If a node linked to its M nearest points, in clustered data all M would sit in one clump and the graph could split into islands that greedy search can't cross. Keeping a candidate only if it's closer to the new node than to any already-kept neighbor spreads links in different directions and keeps bridges between clusters.
Why do the upper layers of HNSW have so few nodes? Each node's top layer is drawn so that P(layer ≥ l) = M^−l. Each layer holds about 1/M of the one below, like express stops on a subway line, so a few long hops at the top cover the whole space.
IVF: what happens as nprobe goes from 1 to nlist?
Recall rises and the work grows roughly in proportion. At nprobe = nlist
it's an exact scan (plus the centroid comparisons).
How does PQ score a vector without decompressing it? It precomputes, for each of the m pieces, the query piece's dot product with all 256 codebook entries. A stored vector's score is then the sum of m table lookups, one per code. The query stays exact; only the stored side is approximate (asymmetric distance computation).
You have 1 billion 768-dimension vectors. Why not HNSW over raw float32? The raw vectors alone are 10⁹ × 768 × 4 bytes ≈ 3 TB of RAM, before the graph links. Use IVF-PQ (e.g. 64-byte codes ≈ 64 GB) with exact re-scoring of a shortlist, shard the index across machines, or use a disk-based graph index such as DiskANN.
Why can an index that scores 0.99 recall on a benchmark do worse on your data? ANN performance depends on the data's structure. Uniformly random high-dimensional vectors are the hardest case (all distances look alike), while real embeddings are clustered. A benchmark with different structure, dimension or size predicts little. Always measure on your own vectors.
The papers behind this lesson
- Malkov & Yashunin, Efficient and robust approximate nearest neighbor search using Hierarchical Navigable Small World graphs (2016). https://arxiv.org/abs/1603.09320. Introduced HNSW: the layered graph, the exponential layer draw with m_L = 1/ln M, and the diversity heuristic for choosing neighbors, which together gave logarithmic-feeling search with state-of-the-art recall. annotated companion
- Jégou, Douze & Schmid, Product Quantization for Nearest Neighbor Search (IEEE TPAMI, 2011). https://ieeexplore.ieee.org/document/5432202. Introduced product quantization, asymmetric distance computation and the IVF-ADC index (IVF with PQ-encoded residuals), the basis of billion-scale vector search.
- Douze et al., The Faiss library (2024). https://arxiv.org/abs/2401.08281. Describes the most widely used vector-search library and the design space of indexes (flat, IVF, PQ, HNSW and their combinations) this lesson walks through.
Further reading
- FAISS wiki (index types, guidelines for choosing an index): https://github.com/facebookresearch/faiss/wiki
- Douze et al., The Faiss library (2024): https://arxiv.org/abs/2401.08281
- hnswlib, the reference HNSW implementation, and its parameter guide: https://github.com/nmslib/hnswlib/blob/master/ALGO_PARAMS.md
- ANN-Benchmarks (recall vs. queries per second across libraries): https://ann-benchmarks.com/
- Pinecone's illustrated guides to HNSW, IVF and PQ: https://www.pinecone.io/learn/series/faiss/
1r""" 2# Vector search: finding the nearest neighbors without checking everyone 3 4Run: `python -m primer.ml.embeddings.ann` 5 6New to the notation? `primer.notation` explains every symbol used here from 7zero (vectors, Σ, logarithms, big-O). 8 9## Level 1: The practitioner's guide 10 11**In one sentence.** An approximate nearest neighbor (ANN) index finds the 12stored vectors most similar to a query without comparing it against every 13one, trading a small, measurable loss of accuracy for searches that stay 14fast and affordable as a collection grows to millions of vectors. 15 16**When you need it.** Every search over embeddings ends the same way: the 17question becomes a vector, and the answers are the stored vectors nearest to 18it. The honest way to find them is a **flat search**, one comparison per 19stored vector, and it is exact. It is also the ground truth every index is 20judged against, and below about a million vectors it is often the right 21choice: simple, exact, fast enough. You need an index when the collection 22outgrows it. At 10 million vectors of 1,536 dimensions a flat search costs 23about 15 billion multiply-adds per query, and the raw vectors alone take 24about 61 GB of memory (this lesson's `storage_estimate` does the sum). The 25tell: query latency grows in step with the number of documents, or the 26vectors no longer fit in one machine's memory. 27 28**Your options.** Four ideas cover almost every vector database in use, and 29a fifth takes them past the size of one machine's memory. From the simplest 30to the most scalable: 31 32| Option | What it does | What it gives you | What it costs | Where it lives | 33|---|---|---|---|---| 34| Flat search | Compares the query with every stored vector | Exact results: recall 1.0, by definition | One comparison per stored vector per query; every vector in memory | NumPy, FAISS `Flat`, a pgvector column with no index | 35| IVF (inverted file) | Sorts the vectors into clusters ahead of time; a query opens only the `nprobe` nearest clusters | High recall at a fraction of the work, rising with `nprobe` until it equals a flat scan | A k-means training step before the first insert, and retraining when the data drifts | FAISS `IVF`, pgvector `ivfflat` | 36| PQ (product quantization) | Compresses each vector to a few bytes and scores by table lookup | A collection 8 to 64 times smaller in memory, and a good shortlist | Lossy scores: re-score the shortlist with exact vectors or recall suffers | FAISS `IVF...,PQ`, ScaNN | 37| HNSW (layered graph) | Links each vector to a few neighbors on stacked layers; a query hops from coarse to fine | High recall at low latency, tuned per query with `efSearch`, with no training step | Memory for every vector plus its links; slow builds at scale | hnswlib, FAISS `HNSW`, pgvector `hnsw`, Elasticsearch, Qdrant | 38| Disk-resident graph | Keeps the graph and full vectors on an SSD and a compressed copy in memory | A billion vectors on one machine | SSD reads per query and a long build | DiskANN | 39 40**How to choose.** Start from the size of the collection and the memory you 41have. 42 43- Under about a million vectors: flat search. Measure it before you build 44 anything; it may already be fast enough, and it is what you will compare 45 every index against. 46- Millions of vectors, memory to spare: HNSW. It is the default in most 47 vector databases because it gives high recall at low latency with no 48 training step. Set `M` around 16 (32 to 64 for high-dimensional data), 49 build with `efConstruction` of 100 to 400, then tune `efSearch` at query 50 time. 51- Millions of vectors, memory tight: IVF with PQ codes, re-scoring a 52 shortlist with the exact vectors. Choose `nlist` near the square root of 53 N (FAISS's guidelines say 4√N to 16√N below a million vectors, with 30 to 54 256 training vectors per cluster), then tune `nprobe`. 55- Billions of vectors: IVF-PQ, HNSW sharded across machines, or a disk-based 56 graph. DiskANN indexes a billion points on one workstation with 64 GB of 57 memory and an SSD. 58- Whatever you pick, measure recall@k against a flat index on your own 59 vectors while you turn the dial, then check the 95th-percentile latency. 60 A benchmark on other data predicts little, because the shape of the data 61 decides where the curve flattens. 62 63**What it costs.** Three currencies: memory, build time and recall. 64 65- Memory. Raw float32 vectors cost 4 bytes per dimension: about 3 GB for a 66 million 768-dimensional vectors, 3 TB for a billion. HNSW adds its links, 67 roughly `M` times 8 to 10 bytes per vector by hnswlib's estimate (1.69 MB 68 against the flat index's 1.28 MB in this lesson's run on 5,000 vectors of 69 64 dimensions). PQ goes the other way: 96 one-byte codes for a 3,072-byte 70 vector is a 32× saving, so a billion vectors fit in about 100 GB instead 71 of 3 TB. 72- Build time. Flat builds instantly and IVF needs one k-means pass. HNSW 73 inserts each vector by first searching for its neighbors, so a build is 74 one search per vector: the slowest to build in this lesson's run, and 75 pgvector documents the same trade (HNSW: a better speed-recall trade-off, 76 slower builds, more memory; IVFFlat: the reverse). 77- Recall. Every index has one dial, and the last few points of recall are 78 the expensive ones. In this lesson's run, HNSW at `efSearch` 10 reaches 79 recall@10 of 0.49 while comparing 5.5% of the collection, and 0.99 at 160 80 while comparing 36%. IVF at `nprobe` 1 gives 0.33, at 16 gives 0.96, and 81 at 70 (every list) gives 1.0. PQ scores alone at 8 bytes per vector give 82 0.35; re-scoring the top 100 with exact vectors lifts that to 0.88. 83- Latency. This lesson's pure-Python timings are only relative; FAISS or 84 hnswlib run the same searches around 100× faster. DiskANN reports more 85 than 5,000 queries per second at under 3 ms mean latency on a billion 86 points. 87 88**What breaks.** 89 90- **Recall you never measured.** An index that scored 0.99 on a benchmark 91 can do worse on your vectors, because ANN accuracy depends on the data's 92 structure. Keep a flat index of a sample and measure recall@k against it. 93- **A neighbor across a cluster boundary.** IVF's blind spot: the true 94 nearest vector sits in a cell the query didn't open. Raise `nprobe`, and 95 retrain the centroids when the data changes a lot. 96- **Ranking by compressed scores.** PQ is excellent at shortlisting and poor 97 at final ranking: at 8 bytes per vector it finds under half of the true 98 top 10 on its own. Always re-score the shortlist with the exact vectors. 99- **Running out of memory.** HNSW must hold every vector and every link in 100 memory. When it no longer fits, move to IVF-PQ, shard across machines, or 101 use a disk-based graph. 102- **A greedy walk stuck in a corner.** A search that only hops to closer 103 neighbors stops at a point with none closer even when a closer one 104 exists; the beam (`efSearch`) protects against that, and can never be set 105 below k. 106- **A filter applied after the search.** Keep only the results a user may 107 see after asking for the top 10, and you can be left with none. Qdrant's 108 documentation describes extra graph edges from indexed metadata so filters 109 apply during the search; where your database filters afterwards, ask for 110 more candidates than you need. 111 112**In the wild.** FAISS, Meta's library, ships every index in this lesson 113and publishes guidelines that pick one by collection size. hnswlib is the 114reference HNSW implementation from the paper's authors, and its parameter 115guide is where this lesson's knob table comes from. Databases have absorbed 116the same indexes: pgvector adds `hnsw` (defaults `m` 16, `ef_construction` 11764, `ef_search` 40) and `ivfflat` indexes to PostgreSQL; Elasticsearch's 118`dense_vector` fields index with HNSW (`m` 16, `ef_construction` 100) and 119offer quantized variants; Qdrant builds every collection on a filterable 120HNSW (`m` 16, `ef_construct` 100). Google's ScaNN pairs partitioning with 121anisotropic quantization and re-scoring. DiskANN (Subramanya et al., 122NeurIPS 2019) put a billion points on one workstation by keeping the graph 123on an SSD. ANN-Benchmarks publishes recall-versus-throughput curves across 124these libraries. The papers behind this lesson (HNSW, product quantization 125and the Faiss library) are listed at the end with their companions. 126 127**Go deeper.** Level 2 builds each index by hand on eight points you can 128check with a pencil: the flat scan, IVF's centroids and cells, PQ's 129codebooks and lookup tables, and HNSW's layered graph with its greedy 130descent, beam search and the random draw that decides which vectors become 131highways. Then it measures all four on 5,000 vectors and draws the 132recall-versus-work curves. If you only needed to choose an index and set 133its dial, you are done. 134 135## Level 2: How it works, from scratch 136 137Level 2 builds every index above from nothing, starting with a picture and 138eight points on a map. 139 140**The everyday picture.** You've just moved to a new country and want the house nearest to a landmark. 141You could walk up to every house in the country and measure the distance. 142That's always right, but it takes forever. Or you could do what everyone 143actually does: take the **highway** to the right region, switch to **main 144roads** to the right town, then walk the **side streets** to the house. You 145check only a handful of places and still end up at (almost always) the right 146door. 147 148That is the whole problem of this lesson. A search engine that works on 149meaning stores every document as a **vector** (a list of numbers, see 150`primer.ml.embeddings.similarity`) and turns the question into a vector too. 151The best documents are the vectors *nearest* the question. With ten million 152documents, "walk to every house" is too slow, so we build a map with 153highways. Structures like that are called **approximate nearest neighbor 154(ANN) indexes**. *Approximate* because, like the traveller, they very 155occasionally stop at the second-nearest house instead of the nearest. 156 157Four ideas cover almost every vector database in use: 158 159| Index | Everyday picture | What you give up | 160|---|---|---| 161| **Flat** | Visit every house | Nothing; it's exact. Just slow at scale | 162| **IVF** | A library sorts books into sections; you search only the few nearest sections | Books shelved in the section next door | 163| **PQ** | Describe a face by picking the closest nose, eyes and mouth from a small catalogue | Fine detail: the description is lossy | 164| **HNSW** | Highway, then main roads, then side streets | Memory for all the roads, and the occasional near-miss | 165 166A few words used throughout, in plain terms: 167 168- **Similarity score.** How alike two vectors are. Here we use the **dot 169 product** (multiply the two lists position by position and add up). All 170 vectors are rescaled to length 1 first (**normalized**), so the dot 171 product equals the **cosine similarity**, which runs from −1 (opposite) to 172 1 (identical). Higher means closer. 173- **Top k.** The k best matches, e.g. the top 10. 174- **Recall@k.** Of the true top k (found by exhaustive search), the fraction 175 the index actually returned. Recall@10 = 0.9 means it found 9 of the true 176 10. It's the standard measure of an ANN index's accuracy. 177- **Big-O, e.g. O(N).** How the work grows with the data. O(N) means doubling 178 the number of vectors N doubles the work; O(log N) means doubling N adds 179 only one more step. 180 181## A tiny worked example: eight houses on a map 182 183Every index in this lesson is shown first on the same eight points, drawn on 184a flat map so you can check each step with a pencil. The question (the 185**query**) sits at (5, 4). On a flat map "near" is ordinary distance; we keep 186it **squared** (dx² + dy²) so every number stays whole. Squaring doesn't 187change which point is nearest. 188 189| Point | Position | Squared distance to the query (5, 4) | 190|---|---|---| 191| A | (0, 0) | 5² + 4² = **41** | 192| B | (2, 1) | 3² + 3² = **18** | 193| C | (4, 0) | 1² + 4² = **17** | 194| D | (1, 3) | 4² + 1² = **17** | 195| E | (3, 3) | 2² + 1² = **5** | 196| F | (5, 2) | 0² + 2² = **4** | 197| G | (2, 5) | 3² + 1² = **10** | 198| H | (5, 5) | 0² + 1² = **1** ← the true nearest | 199 200Checking all eight rows is **flat search**. It's exact, and it costs one 201distance per stored point. 202 203 204 205**Reading it:** the eight dots are the stored points and the yellow star is 206the query at (5, 4). Thin grey lines are the "streets" (layer 0: every point, 207linked to its neighbors); the thick blue lines are the "highway" (layer 1: 208only A, E and G). The red arrows are the HNSW search worked through below: 209one highway hop from A to E, then one street hop from E to H. It checked a 210few points near its route instead of reading the whole table. 211 212## 1. Flat search: the exact baseline 213 214```mermaid 215flowchart LR 216 Q[Query vector] --> D["Dot product with<br/>EVERY stored vector<br/>(N comparisons)"] 217 D --> T[Keep the k highest] 218 T --> R[Exact top k] 219``` 220 221**Reading it:** there is only one path and no shortcuts. The middle box 222touches every stored vector, which is why the cost grows in step with N. It 223is always exactly right, so every other index is measured against it: its 224answer is the "truth" in recall@k. 225 226$$ 227s(q, x) = q \cdot x = \sum_{i=1}^{d} q_i \, x_i 228$$ 229 230**Symbols** 231 232| Symbol | Meaning here | Range | 233|---|---|---| 234| q | the query vector | d numbers, length 1 | 235| x | one stored vector | d numbers, length 1 | 236| d | number of dimensions (numbers per vector) | 2 in the toy; 384 to 3072 in practice | 237| i | position in the vector, counted from 1 | 1 … d | 238| q_i, x_i | the i-th number of q and of x | −1 … 1 | 239| Σ | "add up the following for every i from 1 to d" | | 240| s(q, x) | similarity score, the dot product | −1 … 1 for unit vectors | 241 242**In words:** the score of a stored vector is what you get by multiplying it 243with the query number by number and adding the results. 244 245**On the example:** with unit vectors q = (0.8, 0.6) and x = (0.6, 0.8): 246s = 0.8·0.6 + 0.6·0.8 = 0.48 + 0.48 = **0.96**, very similar. 247 248**In Python:** 249 250```python 251q = [0.8, 0.6] 252x = [0.6, 0.8] 253# s(q, x) = Σ q_i x_i 254round(sum(q_i * x_i for q_i, x_i in zip(q, x)), 2) # → 0.96 255points = {"A": (0, 0), "B": (2, 1), "C": (4, 0), "D": (1, 3), 256 "E": (3, 3), "F": (5, 2), "G": (2, 5), "H": (5, 5)} 257query = (5, 4) 258def sq_dist(p): 259 return (p[0] - query[0]) ** 2 + (p[1] - query[1]) ** 2 260# flat search on the map: check all eight 261min(points, key=lambda name: sq_dist(points[name])) # → 'H' 262``` 263 264**In code:** `FlatIndex.search` scores the query against every stored vector 265and keeps the best k with `top_k`; `normalize` rescales vectors to length 1 266first, so the dot product is the cosine. 267 268**Why it matters:** flat search costs N·d multiply-adds per query. At 10 269million vectors of 1,536 dimensions that's about 15 billion, far too many 270for an interactive search, and the raw vectors alone take 27110,000,000 × 1,536 × 4 bytes ≈ **61 GB** of memory. Below about a million 272vectors, flat search is often the right answer: simple, exact, and fast 273enough. 274 275**In code:** `storage_estimate` does that memory sum for any n and d. 276 277## 2. IVF: search only the nearest sections of the library 278 279**The everyday picture.** A library doesn't search every shelf for a book 280about sailing. It sorts books into sections ahead of time, and you go to 281"Sports" and maybe "Travel", the one or two most promising sections, and 282search only there. A sailing book shelved in the wrong section is missed 283unless you check that section too. 284 285**On the eight points.** Split them into two groups (**clusters**) ahead of 286time: *left* = {A, B, C, D} and *right* = {E, F, G, H}. Each cluster is 287summarized by its **centroid**, the average position of its members: 288left = (1.75, 1), right = (3.75, 3.75). For the query (5, 4): 289 290| Cluster | Centroid | Squared distance to (5, 4) | 291|---|---|---| 292| left | (1.75, 1) | 3.25² + 3² = 19.5625 | 293| right | (3.75, 3.75) | 1.25² + 0.25² = **1.625** ← probe this one | 294 295Scan only E, F, G, H: the nearest is H (distance 1). That's 2 centroid 296checks + 4 point checks = 6 instead of 8. With a million points in 1,000 297clusters the saving is enormous. 298 299```mermaid 300flowchart TB 301 subgraph BUILD["Ahead of time"] 302 V[All vectors] --> KM["k-means: find nlist centroids"] 303 KM --> L["Put each vector on the list<br/>of its nearest centroid"] 304 end 305 subgraph QUERY["At query time"] 306 Q[Query] --> C["Compare with the nlist centroids"] 307 C --> P["Pick the nprobe nearest"] 308 P --> S["Scan only those lists"] 309 S --> R[Top k] 310 end 311 L -.-> S 312``` 313 314**Reading it:** the top box runs once, when the index is built: **k-means** 315(a simple clustering method: guess centroids, assign every vector to its 316nearest, move each centroid to the average of its members, repeat) sorts the 317vectors into `nlist` lists. The bottom box runs per query and never touches 318lists it didn't pick. The only dial is `nprobe`: how many lists to open. 319 320The set of all points closer to one centroid than to any other is called that 321centroid's **Voronoi cell**: the "section" of the library. IVF's blind spot 322is a true neighbor sitting just across a cell boundary. 323 324 325 326**Reading it:** 600 points, colored by which of 12 centroids (black X) they 327belong to; each color patch is a Voronoi cell. The query (yellow star) 328compares itself with the 12 centroids, then scans only the two nearest cells 329(red X, bright points). The faded points are never looked at. A true neighbor 330sitting just across a boundary, in a faded cell, would be missed, which is 331exactly why raising `nprobe` raises recall. 332 333$$ 334\text{comparisons per query} \approx n_{\text{list}} + N \cdot \frac{n_{\text{probe}}}{n_{\text{list}}} 335$$ 336 337**Symbols** 338 339| Symbol | Meaning here | Typical range | 340|---|---|---| 341| N | number of stored vectors | thousands to billions | 342| n_list | number of clusters (lists) | ≈ √N, e.g. 1,000 for 1M vectors | 343| n_probe | clusters scanned per query, the recall dial | 1 … n_list | 344| N · n_probe / n_list | vectors in the scanned lists, assuming equal-size clusters | | 345 346**In words:** you pay once to compare with every centroid, plus the share of 347the collection that lives in the clusters you open. 348 349**On the example:** 2 + 8 · 1/2 = **6** comparisons (versus 8). At 350N = 1,000,000, n_list = 1,000, n_probe = 10: 1,000 + 10,000 = **11,000**, 351about 1% of a flat scan. 352 353**In Python:** 354 355```python 356left = [(0, 0), (2, 1), (4, 0), (1, 3)] 357right = [(3, 3), (5, 2), (2, 5), (5, 5)] 358def centroid(members): 359 return tuple(sum(p[i] for p in members) / len(members) for i in range(2)) 360centroid(left), centroid(right) # → ((1.75, 1.0), (3.75, 3.75)) 361# probe the nearer 362[(c[0] - 5) ** 2 + (c[1] - 4) ** 2 for c in (centroid(left), centroid(right))] # → [19.5625, 1.625] 363def comparisons(N, n_list, n_probe): 364 # n_list centroids + the vectors in the opened lists 365 return n_list + N * n_probe // n_list 366comparisons(8, 2, 1) # → 6 367comparisons(1_000_000, 1_000, 10) # → 11000 368``` 369 370**In code:** `IVFIndex.train` finds the centroids with `kmeans`, 371`IVFIndex.add` files each vector on its nearest centroid's list, and 372`IVFIndex.search` scans only the nprobe nearest lists. `tiny_ivf_search` 373replays the eight-point example. 374 375**Why it matters:** IVF is cheap to build and light on memory, and 376`nprobe = nlist` gives you back an exact flat search, which is a handy 377sanity check. Its accuracy depends on how well the clusters fit the data, so 378retrain the centroids when the data changes a lot. 379 380## 3. PQ: store each vector as a few catalogue numbers 381 382**The everyday picture.** A police sketch artist doesn't record every pixel 383of a face. They pick the closest nose from a catalogue of 256 noses, the 384closest eyes from 256 eyes, the closest mouth, and so on. The whole face 385becomes a handful of catalogue numbers: tiny to store, close enough to 386recognize someone. That's **product quantization (PQ)**. To **quantize** 387means to round a value to the nearest entry of a fixed set. 388 389**On a 4-number vector.** Split x = (0.9, 0.1, −0.2, 0.8) into two halves. 390Each half is matched against a four-entry catalogue (a **codebook**), here 391the four compass directions: 0 = (1, 0), 1 = (0, 1), 2 = (−1, 0), 3923 = (0, −1). 393 394| Half | Values | Nearest catalogue entry | Code | 395|---|---|---|---| 396| 1 | (0.9, 0.1) | (1, 0) | **0** | 397| 2 | (−0.2, 0.8) | (0, 1) | **1** | 398 399The vector is now stored as two codes, [0, 1]. To score the query 400q = (1, 0, 0, 1) against *any* stored vector, first build one small table 401per half: the query's half dotted with each catalogue entry. 402 403| | entry 0 | entry 1 | entry 2 | entry 3 | 404|---|---|---|---|---| 405| T₁ (q's half 1 = (1, 0)) | 1 | 0 | −1 | 0 | 406| T₂ (q's half 2 = (0, 1)) | 0 | 1 | 0 | −1 | 407 408The approximate score of codes [0, 1] is T₁[0] + T₂[1] = 1 + 1 = **2**. The 409exact score is 0.9 + 0.8 = **1.7**: close, not identical. That's the price of 410compression. 411 412```mermaid 413flowchart LR 414 subgraph ENC["Encode (once per vector)"] 415 X["x: d numbers"] --> SPLIT["split into m pieces"] 416 SPLIT --> NN["each piece → nearest of<br/>256 codebook entries"] 417 NN --> CODE["m one-byte codes"] 418 end 419 subgraph ADC["Score (per query)"] 420 Q["query q"] --> TAB["m small tables:<br/>q's piece · every entry"] 421 TAB --> SUM["score = sum of m<br/>table lookups"] 422 end 423 CODE --> SUM 424``` 425 426**Reading it:** the left box shrinks every stored vector to m bytes, once. 427The right box is the trick: the query is *not* compressed. We precompute m 428tables of 256 numbers, and then scoring any stored vector is just m lookups 429and additions, with no multiplication at all. Keeping the query exact while 430the stored side is compressed is called **asymmetric distance computation 431(ADC)**. 432 433$$ 434\hat{s}(q, x) = \sum_{j=1}^{m} T_j\big[c_j(x)\big], \qquad T_j[c] = q^{(j)} \cdot C_j[c] 435$$ 436 437**Symbols** 438 439| Symbol | Meaning here | Range | 440|---|---|---| 441| m | number of pieces each vector is split into | 2 in the toy; 8 to 96 in practice | 442| j | which piece, counted from 1 | 1 … m | 443| q^(j) | the j-th piece of the query (d/m numbers) | | 444| C_j | the codebook for piece j: its catalogue of entries | 2^nbits entries, usually 256 | 445| C_j[c] | entry number c of that catalogue | | 446| c_j(x) | the code stored for piece j of x: which entry was nearest | 0 … 255 (one byte) | 447| T_j[c] | precomputed table: q's piece j dotted with entry c | | 448| ŝ(q, x) | approximate score ("s-hat": the hat means *estimate*) | | 449 450**In words:** the estimated score is the sum, over the pieces, of the table 451value for whichever catalogue entry that piece of the stored vector was 452rounded to. 453 454**On the example:** ŝ = T₁[c₁] + T₂[c₂] = T₁[0] + T₂[1] = 1 + 1 = **2** 455(exact: 1.7). 456 457**In Python:** 458 459```python 460# the compass codebook, used for both pieces 461C = [(1, 0), (0, 1), (-1, 0), (0, -1)] 462def dot(a, b): 463 return sum(a_i * b_i for a_i, b_i in zip(a, b)) 464def sq_dist(a, b): 465 return sum((a_i - b_i) ** 2 for a_i, b_i in zip(a, b)) 466x = [0.9, 0.1, -0.2, 0.8] 467pieces = [x[0:2], x[2:4]] 468# c_j(x) 469codes = [min(range(4), key=lambda c: sq_dist(piece, C[c])) for piece in pieces] 470codes # → [0, 1] 471q = [1, 0, 0, 1] 472# T_j[c] = q^(j) · C_j[c] 473T = [[dot(q_j, C[c]) for c in range(4)] for q_j in (q[0:2], q[2:4])] 474T # → [[1, 0, -1, 0], [0, 1, 0, -1]] 475# ŝ = Σ_j T_j[c_j(x)] 476sum(T[j][codes[j]] for j in range(2)) # → 2 477# the exact score, for comparison 478round(dot(q, x), 2) # → 1.7 479``` 480 481**In code:** `ProductQuantizer` learns the codebooks (`ProductQuantizer.train`), 482rounds vectors to codes (`ProductQuantizer.encode`), builds the Tⱼ tables 483(`ProductQuantizer.lookup_table`) and sums the lookups 484(`ProductQuantizer.adc_scores`). `tiny_pq_example` replays the 4-number 485example by hand-setting the compass codebooks. 486 487**Why it matters:** a 768-dimension float32 vector is 3,072 bytes; with 488m = 96 it's 96 bytes, 32× smaller, so a billion vectors fit in about 100 GB 489instead of 3 TB. The lost accuracy is recovered by **re-scoring**: take the 490top few hundred by PQ score and recompute their exact scores from the full 491vectors kept on disk. Real systems combine PQ with IVF (**IVF-PQ**) and 492encode each vector's *residual* (its offset from its cluster centroid), 493which is smaller and so rounds more precisely. 494 495 496 497**Reading it:** left to right, each vector gets more bytes (less 498compression). The orange line uses PQ scores alone: at 8 bytes per vector 499(32× smaller than the raw 256 bytes) it finds under half of the true top 10. 500The blue line re-scores PQ's top 100 with the exact vectors and is near 501perfect from 8 bytes up. The lesson: PQ is excellent at *shortlisting* and 502poor at *final ranking*, so production systems always re-score. 503 504**In code:** `PQIndex` scans every PQ code and can re-score its top 505candidates with the exact vectors; `IVFPQIndex` combines IVF lists with 506PQ-encoded residuals. 507 508## 4. HNSW: highway, main roads, side streets 509 510**The everyday picture.** Back to the traveller: highways to get close fast, 511main roads to get closer, side streets to find the door. **HNSW** 512(*Hierarchical Navigable Small World*) builds exactly that as a **graph**: a 513set of points (**nodes**) joined by links (**edges**). Every vector is a node 514on the bottom layer (the side streets). A random few are also placed on 515layer 1 (main roads), fewer still on layer 2 (highways), and so on. 516 517**On the eight points.** Layer 1 holds only A, E and G. Layer 0 holds all 518eight, linked to nearby points (the thin lines in the figure above). A 519**greedy search** means "always move to whichever neighbor is closest to the 520target; stop when none is closer". Start at A: 521 522| Step | Layer | At | Neighbors checked (squared distance) | Move? | 523|---|---|---|---|---| 524| 1 | 1 | A (41) | E (5), G (10) | → E | 525| 2 | 1 | E (5) | A (41), G (10) | no closer neighbor: drop a layer, staying at E | 526| 3 | 0 | E (5) | B (18), D (17), F (4), G (10), H (1) | → H | 527| 4 | 0 | H (1) | E (5), F (4), G (10) | no closer neighbor: done. **Answer: H** | 528 529```mermaid 530flowchart TD 531 subgraph L2["Top layer: few nodes, long jumps"] 532 A2[A] --- D2[D] 533 end 534 subgraph L1["Middle layer: more nodes"] 535 A1[A] --- B1[B] --- D1[D] --- E1[E] 536 end 537 subgraph L0["Bottom layer: every vector"] 538 A0[A] --- B0[B] --- C0[C] --- D0[D] --- E0[E] --- F0[F] 539 end 540 D2 -.-> D1 541 E1 -.-> E0 542``` 543 544**Reading it:** three layers of the same kind of map, fewer nodes the higher 545you go. Solid lines are links within a layer; dotted arrows are "the same 546node, one layer down". A search enters at the top, crosses a lot of ground 547in a few long jumps (A to D), then follows a dotted arrow down and continues 548from the same node with finer steps, until the bottom layer, where every 549vector lives. 550 551**In code:** `tiny_hnsw_search` replays the greedy walk from the table above 552on the eight-point map and returns every stop; `HNSWIndex` is the full index 553used on real vectors. 554 555### The search, step by step 556 557```mermaid 558flowchart TD 559 S[Start at the entry point<br/>on the top layer] --> G{Is any neighbor<br/>closer to the query?} 560 G -->|yes| H[Hop to the closest neighbor] --> G 561 G -->|no| B{On the bottom layer?} 562 B -->|no| DOWN[Drop one layer,<br/>same node] --> G 563 B -->|yes| BEAM["Beam search: keep the best efSearch<br/>candidates, expand the most promising<br/>until nothing better turns up"] 564 BEAM --> K[Return the top k] 565``` 566 567**Reading it:** the loop at the top is greedy descent: hop while something 568closer exists, else drop a layer. On the upper layers it keeps a single best 569node. On the bottom layer it switches to a **beam search**, which keeps a 570shortlist of the best `efSearch` nodes found so far, not just one, and keeps 571exploring from the most promising. That wider net is what protects against 572getting stuck at a point that is only *locally* the best. `efSearch` is the 573dial you tune at query time. 574 575 576 577**Reading it:** this graph has four layers: 300 nodes at the bottom, then 57864, then 14, and a single node on top, which is the entry point. The top 579layer has nothing to hop to, so the figure leaves it out and draws the other 580three, left to right: 14 nodes, 64, and the bottom with all 300. Grey lines 581are the graph's links. The red path is one real query (yellow star) run by 582the code below; the red circle marks where the search entered each layer. On 583the left it covers most of the map in a couple of long hops. By the bottom 584layer it is already next to the star, and it only explores a small 585neighborhood. Out of 300 points, it compared the query with 51, a few dozen. 586 587**Try it:** the map below has 60 points on four layers. Pick a query and 588drag Step: watch the walk cross the map in long hops on the sparse upper 589layers, drop a layer whenever no neighbor is closer, and finish with a short 590local search on the bottom layer. Then choose query D with a beam of 1 (pure 591greedy): it stops at a point with no closer neighbor, yet brute force finds a 592closer one. Widen the beam to 4 and step through again. 593 594<div class="viz" data-viz="hnsw-search" aria-label="HNSW search, step by step, on a 60-point map"></div> 595 596**In code:** `HNSWIndex.search` runs the greedy descent and the bottom-layer 597beam search; `HNSWIndex.search_trace` does the same and returns every node it 598expanded, which is what this figure draws. `small_hnsw_map` builds the 59960-point graph the widget searches, and `viz_data` hands it to the page. 600 601### How the layers are built 602 603```mermaid 604flowchart TD 605 N[New vector] --> LV["Draw its top layer ℓ at random<br/>(most get 0, a few get more)"] 606 LV --> DESC[Greedy descent from the entry point<br/>down to layer ℓ] 607 DESC --> FIND["On each layer ≤ ℓ: beam search with<br/>efConstruction to find candidates"] 608 FIND --> SEL["Keep up to M diverse neighbors<br/>(the heuristic below)"] 609 SEL --> LINK[Link both ways] 610 LINK --> PRUNE{Neighbor now has too many links?<br/>more than M, or 2·M on layer 0} 611 PRUNE -->|yes| TRIM[Re-select its best-spread links] 612 PRUNE -->|no| DONE[Next layer down] 613 TRIM --> DONE 614``` 615 616**Reading it:** inserting a vector is a search followed by wiring. The random 617draw at the top decides how many layers the node lives on. The search part 618is the same as a query, just with a wider beam (`efConstruction`) for a 619better-quality result. The wiring part keeps each node's links to a fixed 620budget, so the graph never gets too dense to walk quickly. 621 622**The diversity heuristic.** When choosing a new node's M neighbors, go 623through the candidates from nearest to farthest and keep one only if it is 624closer to the new node than to every neighbor already kept. Otherwise a kept 625neighbor already "covers" that direction. Without this rule, in clustered 626data all M links would point into the same clump, and the graph could split 627into islands a greedy walk can't cross. With it, links fan out in different 628directions and long "bridges" between clusters survive. 629 630The random layer draw is where the math comes in: 631 632$$ 633\ell = \left\lfloor -\ln(U) \cdot m_L \right\rfloor, \qquad m_L = \frac{1}{\ln M}, \qquad P(\ell \ge l) = M^{-l} 634$$ 635 636**Symbols** 637 638| Symbol | Meaning here | Range | 639|---|---|---| 640| ℓ | the top layer the new node will live on | 0, 1, 2, … | 641| U | a random number drawn uniformly | 0 < U ≤ 1 | 642| ln | natural logarithm: the power you raise e ≈ 2.718 to in order to get the number. ln(1) = 0; ln of a number below 1 is negative, so −ln(U) is positive | | 643| ⌊ ⌋ | "floor": round down to a whole number | | 644| M | the link budget per node (also sets how fast layers thin out) | 4 to 64; 16 is common | 645| m_L | the level multiplier, 1/ln M | ≈ 0.36 for M = 16 | 646| P(ℓ ≥ l) | the probability a node reaches layer l or higher | | 647| efConstruction | beam width while building | 100 to 400 | 648| efSearch | beam width while searching, the recall dial | ≥ k; 50 to 500 | 649 650**In words:** draw a random number, take minus its logarithm, scale it by 651one over the log of M, and round down. That gives a node layer 1 or higher 652with probability 1/M, layer 2 or higher with probability 1/M², and so on. 653 654**On the example:** M = 16, so m_L = 1/ln 16 = 1/2.773 = 0.361. A draw of 655U = 0.5 gives −ln 0.5 · 0.361 = 0.693 · 0.361 = 0.25 → floor → **layer 0**. 656A draw of U = 0.05 gives 2.996 · 0.361 = 1.08 → **layer 1**. Only 6571/16 = 6.25% of nodes reach layer 1, and 1/256 ≈ 0.4% reach layer 2: each 658layer has about 1/M as many nodes as the one below, which is what makes the 659upper layers "highways". 660 661**In Python:** 662 663```python 664import math 665M = 16 666# m_L = 1 / ln M 667m_L = 1 / math.log(M) 668round(m_L, 3) # → 0.361 669for U in (0.5, 0.05): 670 # -ln(U) · m_L 671 scaled = -math.log(U) * m_L 672 # ... then round down to get ℓ 673 print(U, round(scaled, 2), math.floor(scaled)) # → 0.5 0.25 0 0.05 1.08 1 674# P(ℓ ≥ l) = M^(-l): 6.25% and about 0.4% 675[M ** -l for l in (1, 2)] # → [0.0625, 0.00390625] 676``` 677 678| Knob | Set when | Higher means | 679|---|---|---| 680| `M` | build | more links per node: better recall, more memory, slower build. 16 is a common default; 32 to 64 for high-dimensional data | 681| `efConstruction` | build | a better-quality graph, a slower build | 682| `efSearch` | **query time** | a wider beam: better recall, slower queries | 683 684**In code:** `HNSWIndex.add` inserts each vector this way: draw its layer, 685beam-search each layer with efConstruction, keep up to M diverse neighbors 686and link both ways. `HNSWIndex.layer_sizes` counts the nodes on each layer, 687and `HNSWIndex.memory_bytes` adds up the vectors plus their links. 688 689**Why it matters:** HNSW is the default index in most vector databases 690because it gives high recall at low latency with no training step. Its costs 691are memory (every vector *plus* its links must sit in RAM) and slow builds 692for very large collections. At billions of vectors, teams switch to IVF-PQ, 693shard HNSW across machines, or use disk-based graphs (DiskANN). 694 695## Turning the dial: recall vs. work 696 697 698 699**Reading it:** each point is one setting of the dial (the small labels are 700efSearch for HNSW and nprobe for IVF). The x-axis is the share of the whole 701collection compared per query, on a log scale (each tick is 10× more work), 702and the dashed line at 100% is a flat scan. The y-axis is recall@10. Read it 703as a menu: the further up and to the left, the better. HNSW reaches about 0.95 704recall while comparing around a fifth of these 2,000 vectors. On real 705collections of millions the share is far smaller, because the number of 706hops grows only slowly with N. Both curves rise steeply and 707then flatten, which is why the last few points of recall are the expensive 708ones. 709 710$$ 711\text{recall@}k = \frac{\lvert \text{returned top } k \;\cap\; \text{true top } k \rvert}{k} 712$$ 713 714**Symbols** 715 716| Symbol | Meaning here | 717|---|---| 718| k | how many results we ask for | 719| true top k | the answer from an exact flat search | 720| ∩ | "intersection": the items in both lists | 721| \| \| | "the number of items in" | 722 723**In words:** recall@k is the share of the true top k that the index 724actually returned. 725 726**On the example:** if the true top 10 is documents 1 to 10 and the index 727returns 1 to 9 plus document 42, the overlap is 9, so recall@10 = 9/10 = 728**0.9**. 729 730**In Python:** 731 732```python 733# documents 1 to 10 734true_top = set(range(1, 11)) 735# 1 to 9, plus document 42 736returned = set(range(1, 10)) | {42} 737k = 10 738# |returned ∩ true| / k 739len(returned & true_top) / k # → 0.9 740``` 741 742**In code:** `recall_at_k` computes this share; `ground_truth` runs the exact 743flat search that supplies the true top k, and `evaluate` reports recall, 744latency and distance computations per query for any index. 745 746**Why it matters:** recall and latency are traded against each other on 747every index. The only reliable way to pick a setting is to measure recall@k 748against a flat index *on your own vectors* while you turn the dial, then 749check the 95th-percentile latency. 750 751## In 20 seconds 752- **Flat** compares the query with everything: exact, O(N). It's the ground 753 truth, and fine for small collections. 754- **IVF** clusters ahead of time and searches the `nprobe` nearest clusters. 755- **PQ** compresses each vector to a few bytes and scores by table lookup; 756 re-score a shortlist with exact vectors. 757- **HNSW** is a layered graph: long jumps on top, a careful beam search at 758 the bottom. `efSearch` trades recall for latency; `M` and `efConstruction` 759 set graph quality at build time. It's fast and accurate, but memory-hungry. 760- Always measure **recall@k against a flat index** on your own data while you 761 turn the dial. 762 763## Self-test questions 764 765**On the eight-point map, query at (5, 4): walk the HNSW search.** 766Start at A on layer 1 (squared distance 41). Its layer-1 neighbors are E (5) 767and G (10), so hop to E. No layer-1 neighbor of E is closer, so drop to 768layer 0 at E. There, H (1) is closer, so hop to H. None of H's neighbors 769beats 1, so the answer is H. 770 771**PQ stores x = (0.9, 0.1, −0.2, 0.8) with the four compass directions as 772each half's codebook. What are the codes, and what score does the query 773(1, 0, 0, 1) get?** 774Codes [0, 1]. The lookup tables are [1, 0, −1, 0] and [0, 1, 0, −1], so the 775approximate score is 1 + 1 = 2, against an exact score of 0.9 + 0.8 = 1.7. 776 777**How does an HNSW search proceed, and which knobs change its speed and recall?** 778Enter at the top layer's entry point; greedily hop to whichever neighbor is 779closest to the query until none is closer, then drop a layer at the same 780node; at layer 0 run a beam search keeping `efSearch` candidates; return the 781top k. Build-time knobs: M (links per node; memory and recall) and 782efConstruction (graph quality; build time). Query-time knob: efSearch. Raise 783it until recall@k against a flat index meets your target, then check p95 784latency. 785 786**Why does HNSW need a "diversity" rule when choosing neighbors?** 787If a node linked to its M nearest points, in clustered data all M would sit 788in one clump and the graph could split into islands that greedy search can't 789cross. Keeping a candidate only if it's closer to the new node than to any 790already-kept neighbor spreads links in different directions and keeps 791bridges between clusters. 792 793**Why do the upper layers of HNSW have so few nodes?** 794Each node's top layer is drawn so that P(layer ≥ l) = M^−l. Each layer holds 795about 1/M of the one below, like express stops on a subway line, so a few 796long hops at the top cover the whole space. 797 798**IVF: what happens as `nprobe` goes from 1 to `nlist`?** 799Recall rises and the work grows roughly in proportion. At `nprobe = nlist` 800it's an exact scan (plus the centroid comparisons). 801 802**How does PQ score a vector without decompressing it?** 803It precomputes, for each of the m pieces, the query piece's dot product with 804all 256 codebook entries. A stored vector's score is then the sum of m table 805lookups, one per code. The query stays exact; only the stored side is 806approximate (asymmetric distance computation). 807 808**You have 1 billion 768-dimension vectors. Why not HNSW over raw float32?** 809The raw vectors alone are 10⁹ × 768 × 4 bytes ≈ 3 TB of RAM, before the 810graph links. Use IVF-PQ (e.g. 64-byte codes ≈ 64 GB) with exact re-scoring 811of a shortlist, shard the index across machines, or use a disk-based graph 812index such as DiskANN. 813 814**Why can an index that scores 0.99 recall on a benchmark do worse on your data?** 815ANN performance depends on the data's structure. Uniformly random 816high-dimensional vectors are the hardest case (all distances look alike), 817while real embeddings are clustered. A benchmark with different structure, 818dimension or size predicts little. Always measure on your own vectors. 819 820## The papers behind this lesson 821 822- **Malkov & Yashunin, *Efficient and robust approximate nearest neighbor 823 search using Hierarchical Navigable Small World graphs* (2016).** 824 https://arxiv.org/abs/1603.09320. Introduced HNSW: the layered graph, the 825 exponential layer draw with m_L = 1/ln M, and the diversity heuristic for 826 choosing neighbors, which together gave logarithmic-feeling search with 827 state-of-the-art recall. [annotated companion](../../../papers/hnsw.html) 828- **Jégou, Douze & Schmid, *Product Quantization for Nearest Neighbor 829 Search* (IEEE TPAMI, 2011).** https://ieeexplore.ieee.org/document/5432202. 830 Introduced product quantization, asymmetric distance computation and the 831 IVF-ADC index (IVF with PQ-encoded residuals), the basis of billion-scale 832 vector search. 833- **Douze et al., *The Faiss library* (2024).** https://arxiv.org/abs/2401.08281. 834 Describes the most widely used vector-search library and the design space 835 of indexes (flat, IVF, PQ, HNSW and their combinations) this lesson walks 836 through. 837 838## Further reading 839- FAISS wiki (index types, guidelines for choosing an index): https://github.com/facebookresearch/faiss/wiki 840- Douze et al., *The Faiss library* (2024): https://arxiv.org/abs/2401.08281 841- hnswlib, the reference HNSW implementation, and its parameter guide: https://github.com/nmslib/hnswlib/blob/master/ALGO_PARAMS.md 842- ANN-Benchmarks (recall vs. queries per second across libraries): https://ann-benchmarks.com/ 843- Pinecone's illustrated guides to HNSW, IVF and PQ: https://www.pinecone.io/learn/series/faiss/ 844""" 845 846from __future__ import annotations 847 848import heapq 849import math 850import time 851 852import numpy as np 853 854from primer._show import banner, say, table, takeaway 855 856# --------------------------------------------------------------------------- 857# 0. Shared helpers 858# --------------------------------------------------------------------------- 859 860 861def normalize(X: np.ndarray) -> np.ndarray: 862 """L2-normalize rows (or a single vector) so dot product = cosine similarity.""" 863 X = np.asarray(X, dtype=np.float32) 864 norms = np.linalg.norm(X, axis=-1, keepdims=True) 865 return X / np.where(norms == 0, 1, norms) 866 867 868def top_k(scores: np.ndarray, k: int) -> np.ndarray: 869 """Indices of the k highest scores, best first. 870 871 `argpartition` finds the top k in O(N) without fully sorting all N 872 scores; then we sort only those k. Real libraries use a small heap. 873 """ 874 k = min(k, len(scores)) 875 if k == 0: 876 return np.array([], dtype=int) 877 idx = np.argpartition(-scores, k - 1)[:k] 878 return idx[np.argsort(-scores[idx], kind="stable")] 879 880 881def kmeans(X: np.ndarray, k: int, iters: int = 20, seed: int = 0) -> tuple[np.ndarray, np.ndarray]: 882 """Plain Lloyd's k-means. Returns (centroids (k, d), assignment (N,)). 883 884 Used by IVF (coarse clusters) and PQ (per-sub-space codebooks). 885 1. Start from k random data points. 886 2. Assign every point to its nearest centroid. 887 3. Move each centroid to the mean of its points. Repeat. 888 Empty clusters are re-seeded from random points so k stays k. 889 """ 890 rng = np.random.default_rng(seed) 891 X = np.asarray(X, dtype=np.float32) 892 k = min(k, len(X)) 893 C = X[rng.choice(len(X), size=k, replace=False)].copy() 894 assign = np.zeros(len(X), dtype=int) 895 for _ in range(iters): 896 # Squared L2 distance via ||x||² - 2x·c + ||c||², all at once. 897 d2 = (X**2).sum(1, keepdims=True) - 2 * X @ C.T + (C**2).sum(1) 898 assign = d2.argmin(1) 899 for j in range(k): 900 members = X[assign == j] 901 C[j] = members.mean(0) if len(members) else X[rng.integers(len(X))] 902 return C, assign 903 904 905class _Index: 906 """Common bookkeeping: every index counts distance computations. 907 908 'Distance computations per query' is the hardware-independent cost 909 measure used in the ANN literature: it says how much of the database a 910 query actually touched. 911 """ 912 913 def __init__(self, dim: int): 914 self.dim = dim 915 self.ndist = 0 # running count of vector-vs-query comparisons 916 917 def __len__(self) -> int: # pragma: no cover - overridden 918 raise NotImplementedError 919 920 def memory_bytes(self) -> int: # pragma: no cover - overridden 921 raise NotImplementedError 922 923 924# --------------------------------------------------------------------------- 925# 0b. The eight-point map: every index, small enough to check by hand 926# --------------------------------------------------------------------------- 927# Eight "houses" on a grid. On a flat map we use ordinary distance, and we 928# keep it *squared* (dx² + dy²) so every number stays a whole number. Squaring 929# doesn't change which house is nearest. 930 931TOY_POINTS: dict[str, tuple[int, int]] = { 932 "A": (0, 0), "B": (2, 1), "C": (4, 0), "D": (1, 3), 933 "E": (3, 3), "F": (5, 2), "G": (2, 5), "H": (5, 5), 934} 935 936# A hand-built two-layer HNSW graph over the eight points. 937# Layer 1 (the "highway"): only A, E and G, all linked to each other. 938# Layer 0 (the "streets"): every point, linked to its nearby neighbours. 939TOY_LAYERS: dict[int, dict[str, list[str]]] = { 940 1: {"A": ["E", "G"], "E": ["A", "G"], "G": ["A", "E"]}, 941 0: { 942 "A": ["B", "D"], "B": ["A", "C", "E"], "C": ["B", "F"], "D": ["A", "E", "G"], 943 "E": ["B", "D", "F", "G", "H"], "F": ["C", "E", "H"], "G": ["D", "E", "H"], "H": ["E", "F", "G"], 944 }, 945} 946 947 948def _sqdist(p: tuple[float, float], q: tuple[float, float]) -> float: 949 return (p[0] - q[0]) ** 2 + (p[1] - q[1]) ** 2 950 951 952def tiny_hnsw_search(query: tuple[float, float], entry: str = "A") -> list[tuple[int, str, float]]: 953 """Greedy HNSW search on the eight-point map. Returns every stop as (layer, point, squared distance). 954 955 On each layer: look at the current point's neighbours; hop to the closest 956 one if it beats where you stand; stop when none does; then drop to the 957 layer below *at the same point*. (A real HNSW keeps a beam of `ef` 958 candidates at layer 0 rather than a single one; with ef = 1 it is exactly 959 this greedy walk.) 960 """ 961 here = entry 962 path: list[tuple[int, str, float]] = [] 963 for layer in sorted(TOY_LAYERS, reverse=True): 964 path.append((layer, here, _sqdist(TOY_POINTS[here], query))) 965 while True: 966 best = min(TOY_LAYERS[layer][here], key=lambda p: _sqdist(TOY_POINTS[p], query)) 967 if _sqdist(TOY_POINTS[best], query) >= _sqdist(TOY_POINTS[here], query): 968 break # no neighbour is closer: a local best on this layer 969 here = best 970 path.append((layer, here, _sqdist(TOY_POINTS[here], query))) 971 return path 972 973 974# Two hand-picked IVF clusters: the four lower-left points and the four upper-right ones. 975TOY_CLUSTERS: dict[str, list[str]] = {"left": ["A", "B", "C", "D"], "right": ["E", "F", "G", "H"]} 976 977 978def tiny_ivf_search(query: tuple[float, float], nprobe: int = 1) -> tuple[list[str], list[str], str]: 979 """IVF on the eight-point map: compare to the cluster centres, scan only the nearest `nprobe`. 980 981 Returns (probed clusters, points scanned, nearest point found). 982 """ 983 centroids = { 984 name: tuple(np.mean([TOY_POINTS[p] for p in members], axis=0)) for name, members in TOY_CLUSTERS.items() 985 } 986 probed = sorted(centroids, key=lambda c: _sqdist(centroids[c], query))[:nprobe] 987 scanned = [p for c in probed for p in TOY_CLUSTERS[c]] 988 best = min(scanned, key=lambda p: _sqdist(TOY_POINTS[p], query)) 989 return probed, scanned, best 990 991 992def tiny_pq_example() -> dict: 993 """Product quantization on one 4-number vector, small enough to do by hand. 994 995 Split x = (0.9, 0.1, -0.2, 0.8) into two halves. Each half is replaced by 996 the nearest of four "catalogue" entries (the four compass directions), 997 so the whole vector is stored as two small codes instead of four floats. 998 """ 999 pq = ProductQuantizer(dim=4, m=2, nbits=2) 1000 compass = np.array([[1, 0], [0, 1], [-1, 0], [0, -1]], dtype=np.float32) 1001 pq.codebooks = np.stack([compass, compass]) # hand-set instead of learned by k-means 1002 x = np.array([[0.9, 0.1, -0.2, 0.8]], dtype=np.float32) 1003 q = np.array([1, 0, 0, 1], dtype=np.float32) 1004 codes = pq.encode(x) 1005 table = pq.lookup_table(q) 1006 return dict( 1007 codes=codes[0].tolist(), 1008 decoded=pq.decode(codes)[0].tolist(), 1009 table=table.tolist(), 1010 approx_score=float(pq.adc_scores(table, codes)[0]), 1011 exact_score=float(x[0] @ q), 1012 ) 1013 1014 1015# --------------------------------------------------------------------------- 1016# 1. Flat: exact brute force (the ground truth) 1017# --------------------------------------------------------------------------- 1018 1019 1020class FlatIndex(_Index): 1021 """Exact search: score the query against every stored vector. 1022 1023 O(N·d) per query. Always the reference when measuring ANN recall. 1024 """ 1025 1026 def __init__(self, dim: int): 1027 super().__init__(dim) 1028 self.X = np.zeros((0, dim), dtype=np.float32) 1029 1030 def add(self, vectors: np.ndarray) -> None: 1031 self.X = np.vstack([self.X, np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim)]) 1032 1033 def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]: 1034 scores = self.X @ np.asarray(query, dtype=np.float32) # one dot product per stored vector 1035 self.ndist += len(self.X) 1036 ids = top_k(scores, k) 1037 return ids, scores[ids] 1038 1039 def __len__(self) -> int: 1040 return len(self.X) 1041 1042 def memory_bytes(self) -> int: 1043 return self.X.nbytes # N · d · 4 bytes of float32 1044 1045 1046# --------------------------------------------------------------------------- 1047# 2. IVF: cluster, then search only the nearest clusters 1048# --------------------------------------------------------------------------- 1049 1050 1051class IVFIndex(_Index): 1052 """Inverted-file index: k-means coarse quantizer + per-cluster lists. 1053 1054 Args: 1055 nlist: number of clusters. Rule of thumb ≈ sqrt(N). 1056 nprobe: clusters scanned per query, the recall/latency dial. 1057 """ 1058 1059 def __init__(self, dim: int, nlist: int = 64, nprobe: int = 4, seed: int = 0): 1060 super().__init__(dim) 1061 self.nlist, self.nprobe, self.seed = nlist, nprobe, seed 1062 self.centroids: np.ndarray | None = None 1063 self.lists: list[list[int]] = [] 1064 self.X = np.zeros((0, dim), dtype=np.float32) 1065 1066 def train(self, sample: np.ndarray) -> None: 1067 """Learn the clusters. Real systems train on a sample, then add everything.""" 1068 self.centroids, _ = kmeans(sample, self.nlist, seed=self.seed) 1069 self.lists = [[] for _ in range(len(self.centroids))] 1070 1071 def add(self, vectors: np.ndarray) -> None: 1072 vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim) 1073 if self.centroids is None: 1074 self.train(vectors) # convenience: train on the first batch 1075 start = len(self.X) 1076 self.X = np.vstack([self.X, vectors]) 1077 # Each vector goes on the list of its nearest centroid (by dot product, 1078 # since we search by dot product). 1079 for offset, c in enumerate((vectors @ self.centroids.T).argmax(1)): 1080 self.lists[c].append(start + offset) 1081 1082 def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]: 1083 q = np.asarray(query, dtype=np.float32) 1084 # Step 1: which clusters look closest? (nlist comparisons) 1085 centroid_scores = self.centroids @ q 1086 probe = top_k(centroid_scores, self.nprobe) 1087 # Step 2: scan only those clusters' members. 1088 cand = np.array([i for c in probe for i in self.lists[c]], dtype=int) 1089 self.ndist += len(self.centroids) + len(cand) 1090 if len(cand) == 0: 1091 return np.array([], dtype=int), np.array([]) 1092 scores = self.X[cand] @ q 1093 order = top_k(scores, k) 1094 return cand[order], scores[order] 1095 1096 def __len__(self) -> int: 1097 return len(self.X) 1098 1099 def memory_bytes(self) -> int: 1100 return self.X.nbytes + self.centroids.nbytes + 8 * len(self.X) # vectors + centroids + list ids 1101 1102 1103# --------------------------------------------------------------------------- 1104# 3. PQ: compress vectors to a few bytes, score by table lookup 1105# --------------------------------------------------------------------------- 1106 1107 1108class ProductQuantizer: 1109 """Splits d dims into m sub-spaces, each with a 2^nbits-entry codebook. 1110 1111 - `ProductQuantizer.encode`: vector -> m small integer codes (1 byte each at nbits=8). 1112 - `ProductQuantizer.decode`: codes -> the concatenation of the chosen centroids (lossy). 1113 - `ProductQuantizer.lookup_table`: for a query, table[j, c] = q_j · centroid_j[c], 1114 so the approximate dot product with any code is sum_j table[j, code_j]. 1115 """ 1116 1117 def __init__(self, dim: int, m: int = 8, nbits: int = 8, seed: int = 0): 1118 assert dim % m == 0, "dim must split evenly into m sub-vectors" 1119 self.dim, self.m, self.ksub, self.dsub, self.seed = dim, m, 2**nbits, dim // m, seed 1120 self.codebooks: np.ndarray | None = None # (m, ksub, dsub) 1121 1122 def _chunks(self, X: np.ndarray) -> np.ndarray: 1123 # (N, d) -> (N, m, dsub): the j-th slice is sub-vector j. 1124 return X.reshape(len(X), self.m, self.dsub) 1125 1126 def train(self, X: np.ndarray) -> None: 1127 chunks = self._chunks(np.asarray(X, dtype=np.float32)) 1128 books = [] 1129 for j in range(self.m): 1130 C, _ = kmeans(chunks[:, j, :], self.ksub, iters=15, seed=self.seed + j) 1131 if len(C) < self.ksub: # tiny training sets: pad by repeating 1132 C = np.vstack([C, C[np.arange(self.ksub - len(C)) % len(C)]]) 1133 books.append(C) 1134 self.codebooks = np.stack(books) 1135 1136 def encode(self, X: np.ndarray) -> np.ndarray: 1137 chunks = self._chunks(np.asarray(X, dtype=np.float32)) 1138 codes = np.empty((len(X), self.m), dtype=np.uint8 if self.ksub <= 256 else np.uint16) 1139 for j in range(self.m): 1140 C = self.codebooks[j] 1141 d2 = (chunks[:, j, :] ** 2).sum(1, keepdims=True) - 2 * chunks[:, j, :] @ C.T + (C**2).sum(1) 1142 codes[:, j] = d2.argmin(1) # nearest centroid in this sub-space 1143 return codes 1144 1145 def decode(self, codes: np.ndarray) -> np.ndarray: 1146 return np.concatenate([self.codebooks[j][codes[:, j]] for j in range(self.m)], axis=1) 1147 1148 def lookup_table(self, q: np.ndarray) -> np.ndarray: 1149 """(m, ksub) table of partial dot products: the heart of ADC.""" 1150 qc = np.asarray(q, dtype=np.float32).reshape(self.m, self.dsub) 1151 return np.einsum("jd,jkd->jk", qc, self.codebooks) 1152 1153 def adc_scores(self, table: np.ndarray, codes: np.ndarray) -> np.ndarray: 1154 """Asymmetric distance computation: m lookups + adds per stored vector.""" 1155 return table[np.arange(self.m), codes].sum(axis=1) 1156 1157 1158class PQIndex(_Index): 1159 """Flat scan over PQ codes. Tiny memory; approximate scores. 1160 1161 `rerank`: re-score this many top candidates with the exact vectors 1162 (if you kept them, e.g. on disk). 0 = pure PQ. 1163 """ 1164 1165 def __init__(self, dim: int, m: int = 8, nbits: int = 8, rerank: int = 0, seed: int = 0): 1166 super().__init__(dim) 1167 self.pq = ProductQuantizer(dim, m, nbits, seed) 1168 self.rerank = rerank 1169 self.codes = np.zeros((0, m), dtype=np.uint8) 1170 self.X = np.zeros((0, dim), dtype=np.float32) # only used for re-scoring 1171 1172 def add(self, vectors: np.ndarray) -> None: 1173 vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim) 1174 if self.pq.codebooks is None: 1175 self.pq.train(vectors) 1176 self.codes = np.vstack([self.codes, self.pq.encode(vectors)]) 1177 self.X = np.vstack([self.X, vectors]) 1178 1179 def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]: 1180 table = self.pq.lookup_table(query) 1181 approx = self.pq.adc_scores(table, self.codes) 1182 self.ndist += len(self.codes) # cheap lookups, but still touches all N 1183 if not self.rerank: 1184 ids = top_k(approx, k) 1185 return ids, approx[ids] 1186 shortlist = top_k(approx, max(k, self.rerank)) 1187 exact = self.X[shortlist] @ np.asarray(query, dtype=np.float32) 1188 self.ndist += len(shortlist) 1189 order = top_k(exact, k) 1190 return shortlist[order], exact[order] 1191 1192 def __len__(self) -> int: 1193 return len(self.codes) 1194 1195 def memory_bytes(self) -> int: 1196 # Only the codes (and codebooks) must live in RAM; re-scoring vectors 1197 # can stay on disk. That is the entire point of PQ. 1198 return self.codes.nbytes + self.pq.codebooks.nbytes 1199 1200 1201class IVFPQIndex(_Index): 1202 """IVF coarse clustering + PQ-encoded *residuals* (vector minus its centroid). 1203 1204 Score decomposes exactly as q·x = q·c + q·r, and PQ approximates q·r. 1205 Residuals are small and centered, so the same bytes buy more precision 1206 than encoding raw vectors. This is FAISS's `IndexIVFPQ`. 1207 """ 1208 1209 def __init__(self, dim: int, nlist: int = 64, nprobe: int = 4, m: int = 8, nbits: int = 8, rerank: int = 0, seed: int = 0): 1210 super().__init__(dim) 1211 self.nlist, self.nprobe, self.rerank, self.seed = nlist, nprobe, rerank, seed 1212 self.pq = ProductQuantizer(dim, m, nbits, seed) 1213 self.centroids: np.ndarray | None = None 1214 self.lists: list[list[int]] = [] 1215 self.assign = np.zeros(0, dtype=int) 1216 self.codes = np.zeros((0, m), dtype=np.uint8) 1217 self.X = np.zeros((0, dim), dtype=np.float32) 1218 1219 def add(self, vectors: np.ndarray) -> None: 1220 vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim) 1221 if self.centroids is None: 1222 self.centroids, _ = kmeans(vectors, self.nlist, seed=self.seed) 1223 self.lists = [[] for _ in range(len(self.centroids))] 1224 a = (vectors @ self.centroids.T).argmax(1) 1225 self.pq.train(vectors - self.centroids[a]) 1226 a = (vectors @ self.centroids.T).argmax(1) 1227 start = len(self.X) 1228 for offset, c in enumerate(a): 1229 self.lists[c].append(start + offset) 1230 self.assign = np.concatenate([self.assign, a]) 1231 self.codes = np.vstack([self.codes, self.pq.encode(vectors - self.centroids[a])]) 1232 self.X = np.vstack([self.X, vectors]) 1233 1234 def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]: 1235 q = np.asarray(query, dtype=np.float32) 1236 cscores = self.centroids @ q 1237 probe = top_k(cscores, self.nprobe) 1238 cand = np.array([i for c in probe for i in self.lists[c]], dtype=int) 1239 self.ndist += len(self.centroids) + len(cand) 1240 if len(cand) == 0: 1241 return np.array([], dtype=int), np.array([]) 1242 table = self.pq.lookup_table(q) # the residual table is query-only, shared by all lists 1243 approx = cscores[self.assign[cand]] + self.pq.adc_scores(table, self.codes[cand]) 1244 if not self.rerank: 1245 order = top_k(approx, k) 1246 return cand[order], approx[order] 1247 short = cand[top_k(approx, max(k, self.rerank))] 1248 exact = self.X[short] @ q 1249 self.ndist += len(short) 1250 order = top_k(exact, k) 1251 return short[order], exact[order] 1252 1253 def __len__(self) -> int: 1254 return len(self.codes) 1255 1256 def memory_bytes(self) -> int: 1257 return self.codes.nbytes + self.pq.codebooks.nbytes + self.centroids.nbytes + 8 * len(self.codes) 1258 1259 1260# --------------------------------------------------------------------------- 1261# 4. HNSW: hierarchical navigable small-world graph 1262# --------------------------------------------------------------------------- 1263 1264 1265class HNSWIndex(_Index): 1266 """HNSW graph index (Malkov & Yashunin, 2016), written for readability. 1267 1268 Similarity is the dot product (vectors assumed L2-normalized), so 1269 "closer" means "higher score" everywhere below. 1270 1271 Args: 1272 M: links per node on upper layers; layer 0 allows M0 = 2·M. 1273 ef_construction: beam width while inserting (graph quality). 1274 ef_search: beam width while querying (the recall/latency dial). 1275 """ 1276 1277 def __init__(self, dim: int, M: int = 16, ef_construction: int = 100, ef_search: int = 50, seed: int = 0): 1278 super().__init__(dim) 1279 self.M, self.M0 = M, 2 * M 1280 self.ef_construction, self.ef_search = ef_construction, ef_search 1281 # mL normalizes the level distribution: P(level >= l) = M^-l, so each 1282 # layer has ~1/M as many nodes as the one below (like a skip list). 1283 self.mL = 1.0 / math.log(M) 1284 self.rng = np.random.default_rng(seed) 1285 self._X = np.zeros((16, dim), dtype=np.float32) # grows by doubling 1286 self.n = 0 1287 # links[node][layer] -> list of neighbor ids on that layer. 1288 self.links: list[list[list[int]]] = [] 1289 self.levels: list[int] = [] 1290 self.entry: int | None = None 1291 self.max_level = -1 1292 1293 # -- small utilities -------------------------------------------------- 1294 1295 @property 1296 def X(self) -> np.ndarray: 1297 return self._X[: self.n] 1298 1299 def _sims(self, q: np.ndarray, ids: list[int]) -> np.ndarray: 1300 """Similarity of q to several nodes at once (and count the work).""" 1301 self.ndist += len(ids) 1302 return self._X[ids] @ q 1303 1304 def _random_level(self) -> int: 1305 # Exponentially decaying: floor(-ln U · mL). With M=16, ~94% of nodes 1306 # are level 0, ~6% reach level 1, ~0.4% level 2... 1307 return int(-math.log(1.0 - self.rng.random()) * self.mL) 1308 1309 # -- the core routine: beam search on one layer ----------------------- 1310 1311 def _search_layer( 1312 self, q: np.ndarray, entry_points: list[int], ef: int, layer: int, trace: list | None = None 1313 ) -> list[tuple[float, int]]: 1314 """Best-first beam search on a single layer. Returns [(sim, id)], best first. 1315 1316 Two heaps: 1317 * `candidates`: nodes still to expand, best first (a max-heap, stored 1318 as negated sims because heapq is a min-heap). 1319 * `results`: the best `ef` nodes seen, worst on top (a min-heap), so 1320 we can cheaply evict the worst when something better shows up. 1321 Stop when the best unexpanded candidate is worse than the worst 1322 result: nothing reachable from here can improve the beam. 1323 """ 1324 visited = set(entry_points) 1325 sims = self._sims(q, entry_points) 1326 candidates = [(-s, e) for s, e in zip(sims.tolist(), entry_points)] 1327 heapq.heapify(candidates) 1328 results = [(s, e) for s, e in zip(sims.tolist(), entry_points)] 1329 heapq.heapify(results) 1330 while len(results) > ef: 1331 heapq.heappop(results) 1332 1333 while candidates: 1334 neg_s, c = heapq.heappop(candidates) 1335 if -neg_s < results[0][0]: 1336 break # closest remaining candidate is worse than our worst result 1337 if trace is not None: 1338 trace.append((layer, c, -neg_s)) # record each node we expand, for figures 1339 fresh = [n for n in self.links[c][layer] if n not in visited] 1340 if not fresh: 1341 continue 1342 visited.update(fresh) 1343 for s, n in zip(self._sims(q, fresh).tolist(), fresh): 1344 if len(results) < ef or s > results[0][0]: 1345 heapq.heappush(candidates, (-s, n)) 1346 heapq.heappush(results, (s, n)) 1347 if len(results) > ef: 1348 heapq.heappop(results) 1349 return sorted(results, reverse=True) 1350 1351 def _select_neighbors(self, candidates: list[tuple[float, int]], M: int) -> list[int]: 1352 """HNSW's diversity heuristic (Algorithm 4 in the paper). 1353 1354 Walk candidates from closest to farthest. Keep candidate e only if it 1355 is closer to the base point than to every neighbor kept so far. 1356 Otherwise some kept neighbor already "covers" e's direction, and 1357 greedy search can reach e through it. The result: links that fan out 1358 in different directions, including long "bridges" between clusters. 1359 """ 1360 selected: list[int] = [] 1361 for s, e in candidates: 1362 if len(selected) >= M: 1363 break 1364 if not selected or float((self._X[selected] @ self._X[e]).max()) < s: 1365 selected.append(e) 1366 return selected 1367 1368 # -- build --------------------------------------------------------------- 1369 1370 def _insert(self, idx: int) -> None: 1371 q = self._X[idx] 1372 level = self._random_level() 1373 self.levels.append(level) 1374 self.links.append([[] for _ in range(level + 1)]) 1375 1376 if self.entry is None: # the very first node 1377 self.entry, self.max_level = idx, level 1378 return 1379 1380 # Phase 1: greedy descent (beam width 1) through layers above `level`. 1381 ep = [self.entry] 1382 for layer in range(self.max_level, level, -1): 1383 ep = [self._search_layer(q, ep, 1, layer)[0][1]] 1384 1385 # Phase 2: on every layer this node lives on, find neighbors and link. 1386 for layer in range(min(level, self.max_level), -1, -1): 1387 found = self._search_layer(q, ep, self.ef_construction, layer) 1388 neighbors = self._select_neighbors(found, self.M) 1389 self.links[idx][layer] = neighbors 1390 max_degree = self.M0 if layer == 0 else self.M 1391 for nb in neighbors: 1392 nb_links = self.links[nb][layer] 1393 nb_links.append(idx) # links are bidirectional 1394 if len(nb_links) > max_degree: 1395 # Too many links: re-select the best-spread subset for nb. 1396 sims = (self._X[nb_links] @ self._X[nb]).tolist() 1397 ranked = sorted(zip(sims, nb_links), reverse=True) 1398 self.links[nb][layer] = self._select_neighbors(ranked, max_degree) 1399 ep = [e for _, e in found] # next layer starts from everything we found 1400 1401 if level > self.max_level: # new tallest node becomes the entry point 1402 self.entry, self.max_level = idx, level 1403 1404 def add(self, vectors: np.ndarray) -> None: 1405 vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim) 1406 while self.n + len(vectors) > len(self._X): 1407 self._X = np.vstack([self._X, np.zeros_like(self._X)]) 1408 for v in vectors: 1409 self._X[self.n] = v 1410 self.n += 1 1411 self._insert(self.n - 1) 1412 1413 # -- query ----------------------------------------------------------------- 1414 1415 def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]: 1416 if self.entry is None: 1417 return np.array([], dtype=int), np.array([]) 1418 q = np.asarray(query, dtype=np.float32) 1419 ep = [self.entry] 1420 # Highways and main roads: greedy, one best node per layer. 1421 for layer in range(self.max_level, 0, -1): 1422 ep = [self._search_layer(q, ep, 1, layer)[0][1]] 1423 # Side streets: a wide beam at layer 0. ef must be at least k. 1424 found = self._search_layer(q, ep, max(self.ef_search, k), 0)[:k] 1425 return np.array([i for _, i in found], dtype=int), np.array([s for s, _ in found]) 1426 1427 def search_trace(self, query: np.ndarray, k: int = 10) -> list[tuple[int, int, float]]: 1428 """Same as `search`, but return every node expanded as (layer, id, sim). 1429 1430 Plotting this shows the idea in one picture: a few long hops on the 1431 top layers, then a careful local search at the bottom. 1432 """ 1433 q = np.asarray(query, dtype=np.float32) 1434 trace: list[tuple[int, int, float]] = [] 1435 ep = [self.entry] 1436 for layer in range(self.max_level, 0, -1): 1437 ep = [self._search_layer(q, ep, 1, layer, trace)[0][1]] 1438 self._search_layer(q, ep, max(self.ef_search, k), 0, trace) 1439 return trace 1440 1441 def __len__(self) -> int: 1442 return self.n 1443 1444 def layer_sizes(self) -> list[int]: 1445 """How many nodes live on each layer (bottom first). Shrinks ~M× per layer.""" 1446 return [sum(1 for lv in self.levels if lv >= layer) for layer in range(self.max_level + 1)] 1447 1448 def memory_bytes(self) -> int: 1449 n_links = sum(len(nbrs) for node in self.links for nbrs in node) 1450 return self.X.nbytes + 4 * n_links # vectors + 4-byte neighbor ids 1451 1452 1453# --------------------------------------------------------------------------- 1454# 5. Benchmarking: recall@k vs. flat, latency, work per query, memory 1455# --------------------------------------------------------------------------- 1456 1457 1458def clustered_vectors(n: int, dim: int, n_clusters: int = 50, spread: float = 0.35, seed: int = 0) -> np.ndarray: 1459 """Normalized vectors drawn around random cluster centers. 1460 1461 Real embeddings are clustered (topics, languages, document types), not 1462 uniform. Uniform random high-dimensional data is the hardest case for 1463 ANN, because all distances look alike (the curse of dimensionality). 1464 """ 1465 rng = np.random.default_rng(seed) 1466 centers = normalize(rng.standard_normal((n_clusters, dim))) 1467 which = rng.integers(n_clusters, size=n) 1468 return normalize(centers[which] + spread * rng.standard_normal((n, dim)) / np.sqrt(dim) * 3) 1469 1470 1471def planar_vectors(n: int, width: float = 0.6, seed: int = 0) -> tuple[np.ndarray, np.ndarray]: 1472 """Unit vectors in a small cap around the north pole, plus their 2-D (x, y). 1473 1474 For points (x, y, 1) normalized with x and y small, ranking by dot product 1475 matches ranking by ordinary distance in the (x, y) plane. That lets us 1476 *draw* what an index does to high-dimensional data. 1477 """ 1478 rng = np.random.default_rng(seed) 1479 xy = rng.uniform(-width / 2, width / 2, size=(n, 2)) 1480 return normalize(np.hstack([xy, np.ones((n, 1))])), xy 1481 1482 1483# Four places to drop a query on the small map, as (x, y). A and B sit where 1484# greedy search always succeeds; C and D sit behind a local dead end, where a 1485# beam of one stops short and a wider beam gets through. 1486HNSW_MAP_QUERIES = {"A": (-0.2, -0.2), "B": (0.2, 0.2), "C": (0.1, -0.1), "D": (-0.1, 0.2)} 1487 1488 1489def small_hnsw_map() -> tuple[HNSWIndex, np.ndarray, dict[str, np.ndarray]]: 1490 """A 60-point HNSW graph on the plane, small enough to draw every link. 1491 1492 Returns (index, xy of each point, {query name: float32 unit vector}). 1493 M = 4 keeps each point to a handful of links, so the picture stays 1494 legible; this seed happens to give four layers (60, 15, 3 and 2 nodes), 1495 so a search takes a real hop on every layer before the bottom. 1496 """ 1497 vectors, xy = planar_vectors(60, seed=0) 1498 index = HNSWIndex(3, M=4, ef_construction=20, ef_search=1, seed=7) 1499 index.add(vectors) 1500 queries = { 1501 name: normalize(np.array([[x, y, 1.0]]))[0].astype(np.float32) for name, (x, y) in HNSW_MAP_QUERIES.items() 1502 } 1503 return index, xy, queries 1504 1505 1506def recall_at_k(found: np.ndarray, truth: np.ndarray) -> float: 1507 """Fraction of the true top-k that the index returned.""" 1508 return len(set(found.tolist()) & set(truth.tolist())) / max(1, len(truth)) 1509 1510 1511def evaluate(index: _Index, queries: np.ndarray, truth: list[np.ndarray], k: int = 10) -> dict[str, float]: 1512 """Mean recall@k, mean latency (ms) and distance computations per query.""" 1513 index.ndist = 0 1514 t0 = time.perf_counter() 1515 recalls = [recall_at_k(index.search(q, k)[0], t) for q, t in zip(queries, truth)] 1516 ms = (time.perf_counter() - t0) * 1000 / len(queries) 1517 return dict(recall=float(np.mean(recalls)), ms=ms, ndist=index.ndist / len(queries)) 1518 1519 1520def ground_truth(X: np.ndarray, queries: np.ndarray, k: int = 10) -> list[np.ndarray]: 1521 flat = FlatIndex(X.shape[1]) 1522 flat.add(X) 1523 return [flat.search(q, k)[0] for q in queries] 1524 1525 1526def storage_estimate(n: int, dim: int, bytes_per_value: int = 4) -> float: 1527 """Raw vector storage in GB: n · dim · bytes. (10M × 1536 × 4 ≈ 61 GB.)""" 1528 return n * dim * bytes_per_value / 1e9 1529 1530 1531def viz_data() -> dict: 1532 """The graph the site's interactive HNSW widget searches, step by step.""" 1533 index, xy, queries = small_hnsw_map() 1534 # float() of a float32 is exact, so the widget searches the very numbers 1535 # the index stores and its sims agree with the lesson's to the last digit 1536 # that matters; the (x, y) positions are only for drawing, so they round. 1537 return { 1538 "hnsw-search": { 1539 "points": [[round(float(x), 4), round(float(y), 4)] for x, y in xy], 1540 "vectors": [[float(v) for v in row] for row in index.X], 1541 "links": index.links, 1542 "entry": index.entry, 1543 "max_level": index.max_level, 1544 "queries": [ 1545 {"name": name, "xy": list(HNSW_MAP_QUERIES[name]), "vector": [float(v) for v in q]} 1546 for name, q in queries.items() 1547 ], 1548 "ef_options": [1, 2, 4, 8], 1549 } 1550 } 1551 1552 1553# --------------------------------------------------------------------------- 1554# 6. Figures 1555# --------------------------------------------------------------------------- 1556 1557 1558def figures() -> dict: 1559 """Plot this lesson's data. matplotlib is imported here, and only here, 1560 so the lesson itself needs nothing beyond NumPy.""" 1561 import matplotlib 1562 1563 matplotlib.use("Agg") 1564 import matplotlib.pyplot as plt 1565 1566 HNSW_C, IVF_C, PQ_C, MUTED, HOT = "#2563eb", "#059669", "#d97706", "#9ca3af", "#dc2626" 1567 figs = {} 1568 1569 # --- 0. The eight-point map with both HNSW layers and the search path ---- 1570 fig, ax = plt.subplots(figsize=(5.2, 5)) 1571 for layer, width, color in [(0, 1, MUTED), (1, 3.5, HNSW_C)]: 1572 for a, nbrs in TOY_LAYERS[layer].items(): 1573 for b in nbrs: 1574 if a < b: 1575 (xa, ya), (xb, yb) = TOY_POINTS[a], TOY_POINTS[b] 1576 ax.plot([xa, xb], [ya, yb], color=color, lw=width, alpha=0.8, zorder=1, 1577 label=None) 1578 ax.plot([], [], color=MUTED, lw=1, label="layer 0 links (every point)") 1579 ax.plot([], [], color=HNSW_C, lw=3.5, label="layer 1 links (A, E, G)") 1580 for name, (x, y) in TOY_POINTS.items(): 1581 ax.scatter(x, y, s=160, color="white", edgecolors="#374151", lw=1.5, zorder=2) 1582 ax.text(x, y, name, ha="center", va="center", fontsize=9, weight="bold", zorder=3) 1583 query = (5, 4) 1584 path = tiny_hnsw_search(query) 1585 for (_, a, _), (_, b, _) in zip(path, path[1:]): 1586 if a != b: 1587 ax.annotate("", xy=TOY_POINTS[b], xytext=TOY_POINTS[a], zorder=4, 1588 arrowprops=dict(arrowstyle="->", color=HOT, lw=2.5, shrinkA=9, shrinkB=9)) 1589 ax.scatter(*query, marker="*", s=300, color="#facc15", edgecolors="black", zorder=5, label="query (5, 4)") 1590 ax.set_xlim(-0.7, 5.8) 1591 ax.set_ylim(-0.7, 5.8) 1592 ax.set_aspect("equal") 1593 ax.grid(alpha=0.3) 1594 ax.set_title("Eight points: highway hop A→E, street hop E→H") 1595 ax.legend(frameon=False, loc="lower right", fontsize=8) 1596 figs["toy_map"] = fig 1597 1598 # --- 1. The recall/work trade-off for HNSW and IVF ---------------------- 1599 n, dim = 2000, 32 1600 X = clustered_vectors(n, dim, seed=0) 1601 queries = clustered_vectors(50, dim, seed=1) 1602 truth = ground_truth(X, queries) 1603 hnsw = HNSWIndex(dim, M=12, ef_construction=60) 1604 hnsw.add(X) 1605 ivf = IVFIndex(dim, nlist=45) 1606 ivf.add(X) 1607 h_pts, i_pts = [], [] 1608 for ef in (10, 15, 20, 30, 50, 80, 120, 200): 1609 hnsw.ef_search = ef 1610 r = evaluate(hnsw, queries, truth) 1611 h_pts.append((100 * r["ndist"] / n, r["recall"], ef)) 1612 for nprobe in (1, 2, 3, 5, 8, 12, 20, 45): 1613 ivf.nprobe = nprobe 1614 r = evaluate(ivf, queries, truth) 1615 i_pts.append((100 * r["ndist"] / n, r["recall"], nprobe)) 1616 fig, ax = plt.subplots(figsize=(6.4, 4)) 1617 for pts, color, label, knob in [(h_pts, HNSW_C, "HNSW", "ef"), (i_pts, IVF_C, "IVF", "nprobe")]: 1618 xs, ys, ks = zip(*pts) 1619 ax.plot(xs, ys, "o-", color=color, label=f"{label} (labels: {knob})") 1620 for n_pt, (x, y, kv) in enumerate(zip(xs, ys, ks)): 1621 # The curves run close together, so HNSW labels sit above its line and IVF labels below its own, and the 1622 # last point's label steps left to stay clear of the flat-scan line. An opaque box covers any line left. 1623 above = label == "HNSW" 1624 dx = -14 if n_pt == len(xs) - 1 else (-9 if above else 4) 1625 ax.annotate(str(kv), (x, y), textcoords="offset points", xytext=(dx, 6 if above else -11), fontsize=7, 1626 color=color, zorder=3, bbox=dict(facecolor="white", edgecolor="none", pad=0.5)) 1627 ax.axvline(100, color=MUTED, ls="--") 1628 ax.text(95, 0.45, "flat scan:\nevery vector,\nrecall 1.0", ha="right", color=MUTED, fontsize=8) 1629 ax.set_xscale("log") 1630 ax.set_ylim(0, 1.12) 1631 ax.set_xlabel("% of the corpus compared per query (log scale)") 1632 ax.set_ylabel("recall@10 vs. exact search") 1633 ax.set_title(f"Turning the dial: recall vs. work ({n:,} vectors, {dim}-d)") 1634 ax.legend(frameon=False, loc="upper left") # the empty corner: the flat-scan line crosses the lower right 1635 figs["recall_vs_work"] = fig 1636 1637 # --- 2. An HNSW search, layer by layer, on data we can draw ------------- 1638 V, xy = planar_vectors(300, seed=0) 1639 g = HNSWIndex(3, M=6, ef_construction=40, ef_search=10, seed=0) 1640 g.add(V) 1641 qv, qxy = planar_vectors(1, seed=5) 1642 trace = g.search_trace(qv[0], k=5) 1643 shown = list(range(min(g.max_level, 2), -1, -1)) 1644 fig, axes = plt.subplots(1, len(shown), figsize=(4 * len(shown), 4.2)) 1645 for ax, layer in zip(np.atleast_1d(axes), shown): 1646 on = [i for i, lv in enumerate(g.levels) if lv >= layer] 1647 for i in on: 1648 for j in g.links[i][layer]: 1649 if i < j: 1650 ax.plot(*xy[[i, j]].T, color=MUTED, lw=0.4, zorder=1) 1651 ax.scatter(*xy[on].T, s=12 if layer == 0 else 28, color="#374151", zorder=2) 1652 path = [node for lv, node, _ in trace if lv == layer] 1653 if path: 1654 ax.plot(*xy[path].T, "-o", color=HOT, lw=2, ms=5, zorder=3) 1655 ax.scatter(*xy[path[0]], s=90, facecolors="none", edgecolors=HOT, lw=2, zorder=4) 1656 ax.scatter(*qxy[0], marker="*", s=260, color="#facc15", edgecolors="black", zorder=5) 1657 ax.set_title(f"layer {layer}: {len(on)} nodes" + (" (every vector)" if layer == 0 else "")) 1658 ax.set_xticks([]) 1659 ax.set_yticks([]) 1660 ax.set_aspect("equal") 1661 fig.suptitle("One HNSW query: long hops up top, a careful local search at the bottom (★ = query)") 1662 fig.tight_layout() 1663 figs["hnsw_search_path"] = fig 1664 1665 # --- 3. IVF cells and which ones a query probes ------------------------- 1666 V2, xy2 = planar_vectors(600, seed=2) 1667 ivf2 = IVFIndex(3, nlist=12, nprobe=2, seed=0) 1668 ivf2.add(V2) 1669 q2, qxy2 = planar_vectors(1, seed=9) 1670 cell = (V2 @ ivf2.centroids.T).argmax(1) 1671 probed = top_k(ivf2.centroids @ q2[0], 2) 1672 cxy = ivf2.centroids[:, :2] / ivf2.centroids[:, 2:3] # back to plane coordinates 1673 fig, ax = plt.subplots(figsize=(5.6, 5)) 1674 cmap = plt.get_cmap("tab20") 1675 for c in range(len(cxy)): 1676 members = xy2[cell == c] 1677 hit = c in probed 1678 ax.scatter(*members.T, s=14 if hit else 8, color=cmap(c % 20), alpha=1.0 if hit else 0.25, zorder=2) 1679 ax.scatter(*cxy.T, marker="X", s=80, color="black", zorder=3, label="centroids") 1680 ax.scatter(*cxy[probed].T, marker="X", s=160, color=HOT, zorder=4, label="probed (nprobe = 2)") 1681 ax.scatter(*qxy2[0], marker="*", s=260, color="#facc15", edgecolors="black", zorder=5, label="query") 1682 ax.set_xticks([]) 1683 ax.set_yticks([]) 1684 ax.set_aspect("equal") 1685 ax.set_title("IVF: 12 clusters, the query scans only the 2 nearest") 1686 ax.legend(frameon=False, loc="upper right", fontsize=8) 1687 figs["ivf_cells"] = fig 1688 1689 # --- 4. PQ: bytes per vector vs. recall --------------------------------- 1690 n3, dim3 = 1200, 64 1691 X3 = clustered_vectors(n3, dim3, seed=3) 1692 q3 = clustered_vectors(40, dim3, seed=4) 1693 t3 = ground_truth(X3, q3) 1694 ms = (2, 4, 8, 16, 32) 1695 raw, rescored = [], [] 1696 for m in ms: 1697 a, b = PQIndex(dim3, m=m), PQIndex(dim3, m=m, rerank=100) 1698 a.add(X3) 1699 b.pq = a.pq # same codebooks: the only difference is the exact re-scoring step 1700 b.add(X3) 1701 raw.append(evaluate(a, q3, t3)["recall"]) 1702 rescored.append(evaluate(b, q3, t3)["recall"]) 1703 fig, ax = plt.subplots(figsize=(6.2, 3.8)) 1704 ax.plot(ms, raw, "o-", color=PQ_C, label="PQ codes only") 1705 ax.plot(ms, rescored, "o-", color=HNSW_C, label="PQ shortlist of 100, re-scored exactly") 1706 ax.set_xscale("log", base=2) 1707 ax.set_xticks(ms, [f"{m} B\n({dim3 * 4 // m}× smaller)" for m in ms]) 1708 ax.set_ylim(0, 1.05) 1709 ax.set_xlabel(f"bytes per vector (raw float32 = {dim3 * 4} B)") 1710 ax.set_ylabel("recall@10") 1711 ax.set_title("Product quantization: memory vs. accuracy") 1712 ax.legend(frameon=False, loc="lower right") 1713 figs["pq_tradeoff"] = fig 1714 1715 return figs 1716 1717 1718# --------------------------------------------------------------------------- 1719# 7. Narrated walkthrough 1720# --------------------------------------------------------------------------- 1721 1722 1723def demo(n: int = 5000, dim: int = 64, n_queries: int = 100, k: int = 10) -> None: 1724 banner("0. Eight points on a map, query at (5, 4): every index by hand") 1725 table(["point", "position", "squared distance"], 1726 [(p, xy, _sqdist(xy, (5, 4))) for p, xy in TOY_POINTS.items()], floatfmt=".0f") 1727 say("Flat search reads all eight rows: the nearest is H (1). Now the shortcuts.") 1728 table(["layer", "at", "squared distance"], tiny_hnsw_search((5, 4)), floatfmt=".0f") 1729 say("HNSW: one highway hop (A to E), drop a layer, one street hop (E to H). Done.") 1730 probed, scanned, best = tiny_ivf_search((5, 4)) 1731 say(f"IVF: nearest cluster is {probed[0]!r}; scan {', '.join(scanned)} only; best is {best}.") 1732 pq = tiny_pq_example() 1733 say( 1734 f"PQ: (0.9, 0.1, -0.2, 0.8) is stored as codes {pq['codes']} (decoded {pq['decoded']}). " 1735 f"Table-lookup score {pq['approx_score']:.1f} vs exact {pq['exact_score']:.1f}: close, not identical." 1736 ) 1737 1738 banner("0b. Why not just brute force? Storage and compute math") 1739 for N, d in [(1_000_000, 768), (10_000_000, 1536), (1_000_000_000, 768)]: 1740 print(f"{N:>13,} vectors × {d:4d} dims × 4 bytes = {storage_estimate(N, d):8.1f} GB raw; " 1741 f"flat query = {N * d / 1e9:6.1f} G multiply-adds") 1742 print() 1743 say("A flat scan touches every byte on every query. ANN indexes touch a tiny fraction.") 1744 1745 X = clustered_vectors(n, dim, seed=0) 1746 queries = clustered_vectors(n_queries, dim, seed=1) 1747 truth = ground_truth(X, queries, k) 1748 1749 banner(f"1. Build every index on {n:,} clustered {dim}-d vectors") 1750 builds = {} 1751 for name, idx in [ 1752 ("Flat", FlatIndex(dim)), 1753 ("IVF (nlist=70)", IVFIndex(dim, nlist=70, nprobe=4)), 1754 ("PQ (m=16, 1 byte each)", PQIndex(dim, m=16)), 1755 ("IVF-PQ (+rerank 50)", IVFPQIndex(dim, nlist=70, nprobe=8, m=16, rerank=50)), 1756 ("HNSW (M=16, efC=100)", HNSWIndex(dim, M=16, ef_construction=100)), 1757 ]: 1758 t0 = time.perf_counter() 1759 idx.add(X) 1760 builds[name] = (idx, time.perf_counter() - t0) 1761 rows = [] 1762 for name, (idx, secs) in builds.items(): 1763 r = evaluate(idx, queries, truth, k) 1764 rows.append((name, f"{secs:.2f}s", r["recall"], f"{r['ms']:.2f}", f"{r['ndist']:.0f}", f"{idx.memory_bytes() / 1e6:.2f} MB")) 1765 table(["index", "build", f"recall@{k}", "ms/query", "dist/query", "memory"], rows, floatfmt=".3f") 1766 say( 1767 """ 1768 Pure-Python timings are only relative (FAISS or hnswlib are ~100× 1769 faster), so watch "dist/query": the fraction of the database each 1770 query touched. HNSW reaches high recall while comparing against a 1771 small fraction of the vectors. PQ uses a fraction of the memory but 1772 its raw scores are approximate; re-scoring a shortlist with the exact 1773 vectors recovers most of the recall. 1774 """ 1775 ) 1776 1777 hnsw = builds["HNSW (M=16, efC=100)"][0] 1778 banner("2. HNSW's layers (highway, main roads, side streets)") 1779 sizes = hnsw.layer_sizes() 1780 table(["layer", "nodes", "share"], [(i, s, s / sizes[0]) for i, s in enumerate(sizes)][::-1], floatfmt=".4f") 1781 say(f"mL = 1/ln(M) = {hnsw.mL:.3f}, so each layer holds ~1/M = {1 / hnsw.M:.3f} of the one below.") 1782 1783 banner("3. The recall/latency dial: HNSW efSearch") 1784 rows = [] 1785 for ef in (10, 20, 40, 80, 160): 1786 hnsw.ef_search = ef 1787 r = evaluate(hnsw, queries, truth, k) 1788 rows.append((ef, r["recall"], f"{r['ms']:.2f}", f"{r['ndist']:.0f}", f"{100 * r['ndist'] / n:.1f}%")) 1789 table(["efSearch", f"recall@{k}", "ms/query", "dist/query", "of corpus"], rows, floatfmt=".3f") 1790 1791 banner("4. The same dial on IVF: nprobe") 1792 ivf = builds["IVF (nlist=70)"][0] 1793 rows = [] 1794 for nprobe in (1, 2, 4, 8, 16, 70): 1795 ivf.nprobe = nprobe 1796 r = evaluate(ivf, queries, truth, k) 1797 rows.append((nprobe, r["recall"], f"{r['ms']:.2f}", f"{r['ndist']:.0f}")) 1798 table(["nprobe", f"recall@{k}", "ms/query", "dist/query"], rows, floatfmt=".3f") 1799 say("At nprobe = nlist, IVF scans everything and matches the flat index exactly.") 1800 1801 banner("5. PQ: bytes per vector vs. recall (and why we re-score)") 1802 rows = [] 1803 for m in (4, 8, 16, 32): 1804 for rerank in (0, 100): 1805 pq = PQIndex(dim, m=m, rerank=rerank) 1806 pq.add(X) 1807 r = evaluate(pq, queries, truth, k) 1808 rows.append((m, f"{dim * 4 // m}×", rerank or "-", r["recall"])) 1809 table(["m (bytes/vec)", "compression", "rerank top", f"recall@{k}"], rows, floatfmt=".3f") 1810 takeaway( 1811 "Every ANN index has a recall-vs-cost dial: efSearch for HNSW, nprobe for IVF, " 1812 "bytes-per-vector for PQ. Measure recall@k against a flat index on your own data while you turn it." 1813 ) 1814 1815 1816if __name__ == "__main__": 1817 demo()
862def normalize(X: np.ndarray) -> np.ndarray:
863    """L2-normalize rows (or a single vector) so dot product = cosine similarity."""
864    X = np.asarray(X, dtype=np.float32)
865    norms = np.linalg.norm(X, axis=-1, keepdims=True)
866    return X / np.where(norms == 0, 1, norms)
L2-normalize rows (or a single vector) so dot product = cosine similarity.
869def top_k(scores: np.ndarray, k: int) -> np.ndarray:
870    """Indices of the k highest scores, best first.
871
872    `argpartition` finds the top k in O(N) without fully sorting all N
873    scores; then we sort only those k. Real libraries use a small heap.
874    """
875    k = min(k, len(scores))
876    if k == 0:
877        return np.array([], dtype=int)
878    idx = np.argpartition(-scores, k - 1)[:k]
879    return idx[np.argsort(-scores[idx], kind="stable")]
Indices of the k highest scores, best first.
argpartition finds the top k in O(N) without fully sorting all N
scores; then we sort only those k. Real libraries use a small heap.
882def kmeans(X: np.ndarray, k: int, iters: int = 20, seed: int = 0) -> tuple[np.ndarray, np.ndarray]:
883    """Plain Lloyd's k-means. Returns (centroids (k, d), assignment (N,)).
884
885    Used by IVF (coarse clusters) and PQ (per-sub-space codebooks).
886    1. Start from k random data points.
887    2. Assign every point to its nearest centroid.
888    3. Move each centroid to the mean of its points. Repeat.
889    Empty clusters are re-seeded from random points so k stays k.
890    """
891    rng = np.random.default_rng(seed)
892    X = np.asarray(X, dtype=np.float32)
893    k = min(k, len(X))
894    C = X[rng.choice(len(X), size=k, replace=False)].copy()
895    assign = np.zeros(len(X), dtype=int)
896    for _ in range(iters):
897        # Squared L2 distance via ||x||² - 2x·c + ||c||², all at once.
898        d2 = (X**2).sum(1, keepdims=True) - 2 * X @ C.T + (C**2).sum(1)
899        assign = d2.argmin(1)
900        for j in range(k):
901            members = X[assign == j]
902            C[j] = members.mean(0) if len(members) else X[rng.integers(len(X))]
903    return C, assign
Plain Lloyd's k-means. Returns (centroids (k, d), assignment (N,)).
Used by IVF (coarse clusters) and PQ (per-sub-space codebooks).
- Start from k random data points.
- Assign every point to its nearest centroid.
- Move each centroid to the mean of its points. Repeat. Empty clusters are re-seeded from random points so k stays k.
953def tiny_hnsw_search(query: tuple[float, float], entry: str = "A") -> list[tuple[int, str, float]]:
954    """Greedy HNSW search on the eight-point map. Returns every stop as (layer, point, squared distance).
955
956    On each layer: look at the current point's neighbours; hop to the closest
957    one if it beats where you stand; stop when none does; then drop to the
958    layer below *at the same point*. (A real HNSW keeps a beam of `ef`
959    candidates at layer 0 rather than a single one; with ef = 1 it is exactly
960    this greedy walk.)
961    """
962    here = entry
963    path: list[tuple[int, str, float]] = []
964    for layer in sorted(TOY_LAYERS, reverse=True):
965        path.append((layer, here, _sqdist(TOY_POINTS[here], query)))
966        while True:
967            best = min(TOY_LAYERS[layer][here], key=lambda p: _sqdist(TOY_POINTS[p], query))
968            if _sqdist(TOY_POINTS[best], query) >= _sqdist(TOY_POINTS[here], query):
969                break  # no neighbour is closer: a local best on this layer
970            here = best
971            path.append((layer, here, _sqdist(TOY_POINTS[here], query)))
972    return path
Greedy HNSW search on the eight-point map. Returns every stop as (layer, point, squared distance).
On each layer: look at the current point's neighbours; hop to the closest
one if it beats where you stand; stop when none does; then drop to the
layer below at the same point. (A real HNSW keeps a beam of ef
candidates at layer 0 rather than a single one; with ef = 1 it is exactly
this greedy walk.)
979def tiny_ivf_search(query: tuple[float, float], nprobe: int = 1) -> tuple[list[str], list[str], str]:
980    """IVF on the eight-point map: compare to the cluster centres, scan only the nearest `nprobe`.
981
982    Returns (probed clusters, points scanned, nearest point found).
983    """
984    centroids = {
985        name: tuple(np.mean([TOY_POINTS[p] for p in members], axis=0)) for name, members in TOY_CLUSTERS.items()
986    }
987    probed = sorted(centroids, key=lambda c: _sqdist(centroids[c], query))[:nprobe]
988    scanned = [p for c in probed for p in TOY_CLUSTERS[c]]
989    best = min(scanned, key=lambda p: _sqdist(TOY_POINTS[p], query))
990    return probed, scanned, best
IVF on the eight-point map: compare to the cluster centres, scan only the nearest nprobe.
Returns (probed clusters, points scanned, nearest point found).
 993def tiny_pq_example() -> dict:
 994    """Product quantization on one 4-number vector, small enough to do by hand.
 995
 996    Split x = (0.9, 0.1, -0.2, 0.8) into two halves. Each half is replaced by
 997    the nearest of four "catalogue" entries (the four compass directions),
 998    so the whole vector is stored as two small codes instead of four floats.
 999    """
1000    pq = ProductQuantizer(dim=4, m=2, nbits=2)
1001    compass = np.array([[1, 0], [0, 1], [-1, 0], [0, -1]], dtype=np.float32)
1002    pq.codebooks = np.stack([compass, compass])  # hand-set instead of learned by k-means
1003    x = np.array([[0.9, 0.1, -0.2, 0.8]], dtype=np.float32)
1004    q = np.array([1, 0, 0, 1], dtype=np.float32)
1005    codes = pq.encode(x)
1006    table = pq.lookup_table(q)
1007    return dict(
1008        codes=codes[0].tolist(),
1009        decoded=pq.decode(codes)[0].tolist(),
1010        table=table.tolist(),
1011        approx_score=float(pq.adc_scores(table, codes)[0]),
1012        exact_score=float(x[0] @ q),
1013    )
Product quantization on one 4-number vector, small enough to do by hand.
Split x = (0.9, 0.1, -0.2, 0.8) into two halves. Each half is replaced by the nearest of four "catalogue" entries (the four compass directions), so the whole vector is stored as two small codes instead of four floats.
1021class FlatIndex(_Index):
1022    """Exact search: score the query against every stored vector.
1023
1024    O(N·d) per query. Always the reference when measuring ANN recall.
1025    """
1026
1027    def __init__(self, dim: int):
1028        super().__init__(dim)
1029        self.X = np.zeros((0, dim), dtype=np.float32)
1030
1031    def add(self, vectors: np.ndarray) -> None:
1032        self.X = np.vstack([self.X, np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim)])
1033
1034    def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]:
1035        scores = self.X @ np.asarray(query, dtype=np.float32)  # one dot product per stored vector
1036        self.ndist += len(self.X)
1037        ids = top_k(scores, k)
1038        return ids, scores[ids]
1039
1040    def __len__(self) -> int:
1041        return len(self.X)
1042
1043    def memory_bytes(self) -> int:
1044        return self.X.nbytes  # N · d · 4 bytes of float32
Exact search: score the query against every stored vector.
O(N·d) per query. Always the reference when measuring ANN recall.
1052class IVFIndex(_Index):
1053    """Inverted-file index: k-means coarse quantizer + per-cluster lists.
1054
1055    Args:
1056        nlist: number of clusters. Rule of thumb ≈ sqrt(N).
1057        nprobe: clusters scanned per query, the recall/latency dial.
1058    """
1059
1060    def __init__(self, dim: int, nlist: int = 64, nprobe: int = 4, seed: int = 0):
1061        super().__init__(dim)
1062        self.nlist, self.nprobe, self.seed = nlist, nprobe, seed
1063        self.centroids: np.ndarray | None = None
1064        self.lists: list[list[int]] = []
1065        self.X = np.zeros((0, dim), dtype=np.float32)
1066
1067    def train(self, sample: np.ndarray) -> None:
1068        """Learn the clusters. Real systems train on a sample, then add everything."""
1069        self.centroids, _ = kmeans(sample, self.nlist, seed=self.seed)
1070        self.lists = [[] for _ in range(len(self.centroids))]
1071
1072    def add(self, vectors: np.ndarray) -> None:
1073        vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim)
1074        if self.centroids is None:
1075            self.train(vectors)  # convenience: train on the first batch
1076        start = len(self.X)
1077        self.X = np.vstack([self.X, vectors])
1078        # Each vector goes on the list of its nearest centroid (by dot product,
1079        # since we search by dot product).
1080        for offset, c in enumerate((vectors @ self.centroids.T).argmax(1)):
1081            self.lists[c].append(start + offset)
1082
1083    def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]:
1084        q = np.asarray(query, dtype=np.float32)
1085        # Step 1: which clusters look closest? (nlist comparisons)
1086        centroid_scores = self.centroids @ q
1087        probe = top_k(centroid_scores, self.nprobe)
1088        # Step 2: scan only those clusters' members.
1089        cand = np.array([i for c in probe for i in self.lists[c]], dtype=int)
1090        self.ndist += len(self.centroids) + len(cand)
1091        if len(cand) == 0:
1092            return np.array([], dtype=int), np.array([])
1093        scores = self.X[cand] @ q
1094        order = top_k(scores, k)
1095        return cand[order], scores[order]
1096
1097    def __len__(self) -> int:
1098        return len(self.X)
1099
1100    def memory_bytes(self) -> int:
1101        return self.X.nbytes + self.centroids.nbytes + 8 * len(self.X)  # vectors + centroids + list ids
Inverted-file index: k-means coarse quantizer + per-cluster lists.
Arguments:
- nlist: number of clusters. Rule of thumb ≈ sqrt(N).
- nprobe: clusters scanned per query, the recall/latency dial.
1060    def __init__(self, dim: int, nlist: int = 64, nprobe: int = 4, seed: int = 0):
1061        super().__init__(dim)
1062        self.nlist, self.nprobe, self.seed = nlist, nprobe, seed
1063        self.centroids: np.ndarray | None = None
1064        self.lists: list[list[int]] = []
1065        self.X = np.zeros((0, dim), dtype=np.float32)
1067    def train(self, sample: np.ndarray) -> None:
1068        """Learn the clusters. Real systems train on a sample, then add everything."""
1069        self.centroids, _ = kmeans(sample, self.nlist, seed=self.seed)
1070        self.lists = [[] for _ in range(len(self.centroids))]
Learn the clusters. Real systems train on a sample, then add everything.
1072    def add(self, vectors: np.ndarray) -> None:
1073        vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim)
1074        if self.centroids is None:
1075            self.train(vectors)  # convenience: train on the first batch
1076        start = len(self.X)
1077        self.X = np.vstack([self.X, vectors])
1078        # Each vector goes on the list of its nearest centroid (by dot product,
1079        # since we search by dot product).
1080        for offset, c in enumerate((vectors @ self.centroids.T).argmax(1)):
1081            self.lists[c].append(start + offset)
1083    def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]:
1084        q = np.asarray(query, dtype=np.float32)
1085        # Step 1: which clusters look closest? (nlist comparisons)
1086        centroid_scores = self.centroids @ q
1087        probe = top_k(centroid_scores, self.nprobe)
1088        # Step 2: scan only those clusters' members.
1089        cand = np.array([i for c in probe for i in self.lists[c]], dtype=int)
1090        self.ndist += len(self.centroids) + len(cand)
1091        if len(cand) == 0:
1092            return np.array([], dtype=int), np.array([])
1093        scores = self.X[cand] @ q
1094        order = top_k(scores, k)
1095        return cand[order], scores[order]
1109class ProductQuantizer:
1110    """Splits d dims into m sub-spaces, each with a 2^nbits-entry codebook.
1111
1112    - `ProductQuantizer.encode`: vector -> m small integer codes (1 byte each at nbits=8).
1113    - `ProductQuantizer.decode`: codes -> the concatenation of the chosen centroids (lossy).
1114    - `ProductQuantizer.lookup_table`: for a query, table[j, c] = q_j · centroid_j[c],
1115      so the approximate dot product with any code is sum_j table[j, code_j].
1116    """
1117
1118    def __init__(self, dim: int, m: int = 8, nbits: int = 8, seed: int = 0):
1119        assert dim % m == 0, "dim must split evenly into m sub-vectors"
1120        self.dim, self.m, self.ksub, self.dsub, self.seed = dim, m, 2**nbits, dim // m, seed
1121        self.codebooks: np.ndarray | None = None  # (m, ksub, dsub)
1122
1123    def _chunks(self, X: np.ndarray) -> np.ndarray:
1124        # (N, d) -> (N, m, dsub): the j-th slice is sub-vector j.
1125        return X.reshape(len(X), self.m, self.dsub)
1126
1127    def train(self, X: np.ndarray) -> None:
1128        chunks = self._chunks(np.asarray(X, dtype=np.float32))
1129        books = []
1130        for j in range(self.m):
1131            C, _ = kmeans(chunks[:, j, :], self.ksub, iters=15, seed=self.seed + j)
1132            if len(C) < self.ksub:  # tiny training sets: pad by repeating
1133                C = np.vstack([C, C[np.arange(self.ksub - len(C)) % len(C)]])
1134            books.append(C)
1135        self.codebooks = np.stack(books)
1136
1137    def encode(self, X: np.ndarray) -> np.ndarray:
1138        chunks = self._chunks(np.asarray(X, dtype=np.float32))
1139        codes = np.empty((len(X), self.m), dtype=np.uint8 if self.ksub <= 256 else np.uint16)
1140        for j in range(self.m):
1141            C = self.codebooks[j]
1142            d2 = (chunks[:, j, :] ** 2).sum(1, keepdims=True) - 2 * chunks[:, j, :] @ C.T + (C**2).sum(1)
1143            codes[:, j] = d2.argmin(1)  # nearest centroid in this sub-space
1144        return codes
1145
1146    def decode(self, codes: np.ndarray) -> np.ndarray:
1147        return np.concatenate([self.codebooks[j][codes[:, j]] for j in range(self.m)], axis=1)
1148
1149    def lookup_table(self, q: np.ndarray) -> np.ndarray:
1150        """(m, ksub) table of partial dot products: the heart of ADC."""
1151        qc = np.asarray(q, dtype=np.float32).reshape(self.m, self.dsub)
1152        return np.einsum("jd,jkd->jk", qc, self.codebooks)
1153
1154    def adc_scores(self, table: np.ndarray, codes: np.ndarray) -> np.ndarray:
1155        """Asymmetric distance computation: m lookups + adds per stored vector."""
1156        return table[np.arange(self.m), codes].sum(axis=1)
Splits d dims into m sub-spaces, each with a 2^nbits-entry codebook.
ProductQuantizer.encode: vector -> m small integer codes (1 byte each at nbits=8).ProductQuantizer.decode: codes -> the concatenation of the chosen centroids (lossy).ProductQuantizer.lookup_table: for a query, table[j, c] = q_j · centroid_j[c], so the approximate dot product with any code is sum_j table[j, code_j].
1118    def __init__(self, dim: int, m: int = 8, nbits: int = 8, seed: int = 0):
1119        assert dim % m == 0, "dim must split evenly into m sub-vectors"
1120        self.dim, self.m, self.ksub, self.dsub, self.seed = dim, m, 2**nbits, dim // m, seed
1121        self.codebooks: np.ndarray | None = None  # (m, ksub, dsub)
1127    def train(self, X: np.ndarray) -> None:
1128        chunks = self._chunks(np.asarray(X, dtype=np.float32))
1129        books = []
1130        for j in range(self.m):
1131            C, _ = kmeans(chunks[:, j, :], self.ksub, iters=15, seed=self.seed + j)
1132            if len(C) < self.ksub:  # tiny training sets: pad by repeating
1133                C = np.vstack([C, C[np.arange(self.ksub - len(C)) % len(C)]])
1134            books.append(C)
1135        self.codebooks = np.stack(books)
1137    def encode(self, X: np.ndarray) -> np.ndarray:
1138        chunks = self._chunks(np.asarray(X, dtype=np.float32))
1139        codes = np.empty((len(X), self.m), dtype=np.uint8 if self.ksub <= 256 else np.uint16)
1140        for j in range(self.m):
1141            C = self.codebooks[j]
1142            d2 = (chunks[:, j, :] ** 2).sum(1, keepdims=True) - 2 * chunks[:, j, :] @ C.T + (C**2).sum(1)
1143            codes[:, j] = d2.argmin(1)  # nearest centroid in this sub-space
1144        return codes
1149    def lookup_table(self, q: np.ndarray) -> np.ndarray:
1150        """(m, ksub) table of partial dot products: the heart of ADC."""
1151        qc = np.asarray(q, dtype=np.float32).reshape(self.m, self.dsub)
1152        return np.einsum("jd,jkd->jk", qc, self.codebooks)
(m, ksub) table of partial dot products: the heart of ADC.
1159class PQIndex(_Index):
1160    """Flat scan over PQ codes. Tiny memory; approximate scores.
1161
1162    `rerank`: re-score this many top candidates with the exact vectors
1163    (if you kept them, e.g. on disk). 0 = pure PQ.
1164    """
1165
1166    def __init__(self, dim: int, m: int = 8, nbits: int = 8, rerank: int = 0, seed: int = 0):
1167        super().__init__(dim)
1168        self.pq = ProductQuantizer(dim, m, nbits, seed)
1169        self.rerank = rerank
1170        self.codes = np.zeros((0, m), dtype=np.uint8)
1171        self.X = np.zeros((0, dim), dtype=np.float32)  # only used for re-scoring
1172
1173    def add(self, vectors: np.ndarray) -> None:
1174        vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim)
1175        if self.pq.codebooks is None:
1176            self.pq.train(vectors)
1177        self.codes = np.vstack([self.codes, self.pq.encode(vectors)])
1178        self.X = np.vstack([self.X, vectors])
1179
1180    def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]:
1181        table = self.pq.lookup_table(query)
1182        approx = self.pq.adc_scores(table, self.codes)
1183        self.ndist += len(self.codes)  # cheap lookups, but still touches all N
1184        if not self.rerank:
1185            ids = top_k(approx, k)
1186            return ids, approx[ids]
1187        shortlist = top_k(approx, max(k, self.rerank))
1188        exact = self.X[shortlist] @ np.asarray(query, dtype=np.float32)
1189        self.ndist += len(shortlist)
1190        order = top_k(exact, k)
1191        return shortlist[order], exact[order]
1192
1193    def __len__(self) -> int:
1194        return len(self.codes)
1195
1196    def memory_bytes(self) -> int:
1197        # Only the codes (and codebooks) must live in RAM; re-scoring vectors
1198        # can stay on disk. That is the entire point of PQ.
1199        return self.codes.nbytes + self.pq.codebooks.nbytes
Flat scan over PQ codes. Tiny memory; approximate scores.
rerank: re-score this many top candidates with the exact vectors
(if you kept them, e.g. on disk). 0 = pure PQ.
1166    def __init__(self, dim: int, m: int = 8, nbits: int = 8, rerank: int = 0, seed: int = 0):
1167        super().__init__(dim)
1168        self.pq = ProductQuantizer(dim, m, nbits, seed)
1169        self.rerank = rerank
1170        self.codes = np.zeros((0, m), dtype=np.uint8)
1171        self.X = np.zeros((0, dim), dtype=np.float32)  # only used for re-scoring
1180    def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]:
1181        table = self.pq.lookup_table(query)
1182        approx = self.pq.adc_scores(table, self.codes)
1183        self.ndist += len(self.codes)  # cheap lookups, but still touches all N
1184        if not self.rerank:
1185            ids = top_k(approx, k)
1186            return ids, approx[ids]
1187        shortlist = top_k(approx, max(k, self.rerank))
1188        exact = self.X[shortlist] @ np.asarray(query, dtype=np.float32)
1189        self.ndist += len(shortlist)
1190        order = top_k(exact, k)
1191        return shortlist[order], exact[order]
1202class IVFPQIndex(_Index):
1203    """IVF coarse clustering + PQ-encoded *residuals* (vector minus its centroid).
1204
1205    Score decomposes exactly as q·x = q·c + q·r, and PQ approximates q·r.
1206    Residuals are small and centered, so the same bytes buy more precision
1207    than encoding raw vectors. This is FAISS's `IndexIVFPQ`.
1208    """
1209
1210    def __init__(self, dim: int, nlist: int = 64, nprobe: int = 4, m: int = 8, nbits: int = 8, rerank: int = 0, seed: int = 0):
1211        super().__init__(dim)
1212        self.nlist, self.nprobe, self.rerank, self.seed = nlist, nprobe, rerank, seed
1213        self.pq = ProductQuantizer(dim, m, nbits, seed)
1214        self.centroids: np.ndarray | None = None
1215        self.lists: list[list[int]] = []
1216        self.assign = np.zeros(0, dtype=int)
1217        self.codes = np.zeros((0, m), dtype=np.uint8)
1218        self.X = np.zeros((0, dim), dtype=np.float32)
1219
1220    def add(self, vectors: np.ndarray) -> None:
1221        vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim)
1222        if self.centroids is None:
1223            self.centroids, _ = kmeans(vectors, self.nlist, seed=self.seed)
1224            self.lists = [[] for _ in range(len(self.centroids))]
1225            a = (vectors @ self.centroids.T).argmax(1)
1226            self.pq.train(vectors - self.centroids[a])
1227        a = (vectors @ self.centroids.T).argmax(1)
1228        start = len(self.X)
1229        for offset, c in enumerate(a):
1230            self.lists[c].append(start + offset)
1231        self.assign = np.concatenate([self.assign, a])
1232        self.codes = np.vstack([self.codes, self.pq.encode(vectors - self.centroids[a])])
1233        self.X = np.vstack([self.X, vectors])
1234
1235    def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]:
1236        q = np.asarray(query, dtype=np.float32)
1237        cscores = self.centroids @ q
1238        probe = top_k(cscores, self.nprobe)
1239        cand = np.array([i for c in probe for i in self.lists[c]], dtype=int)
1240        self.ndist += len(self.centroids) + len(cand)
1241        if len(cand) == 0:
1242            return np.array([], dtype=int), np.array([])
1243        table = self.pq.lookup_table(q)  # the residual table is query-only, shared by all lists
1244        approx = cscores[self.assign[cand]] + self.pq.adc_scores(table, self.codes[cand])
1245        if not self.rerank:
1246            order = top_k(approx, k)
1247            return cand[order], approx[order]
1248        short = cand[top_k(approx, max(k, self.rerank))]
1249        exact = self.X[short] @ q
1250        self.ndist += len(short)
1251        order = top_k(exact, k)
1252        return short[order], exact[order]
1253
1254    def __len__(self) -> int:
1255        return len(self.codes)
1256
1257    def memory_bytes(self) -> int:
1258        return self.codes.nbytes + self.pq.codebooks.nbytes + self.centroids.nbytes + 8 * len(self.codes)
IVF coarse clustering + PQ-encoded residuals (vector minus its centroid).
Score decomposes exactly as q·x = q·c + q·r, and PQ approximates q·r.
Residuals are small and centered, so the same bytes buy more precision
than encoding raw vectors. This is FAISS's IndexIVFPQ.
1210    def __init__(self, dim: int, nlist: int = 64, nprobe: int = 4, m: int = 8, nbits: int = 8, rerank: int = 0, seed: int = 0):
1211        super().__init__(dim)
1212        self.nlist, self.nprobe, self.rerank, self.seed = nlist, nprobe, rerank, seed
1213        self.pq = ProductQuantizer(dim, m, nbits, seed)
1214        self.centroids: np.ndarray | None = None
1215        self.lists: list[list[int]] = []
1216        self.assign = np.zeros(0, dtype=int)
1217        self.codes = np.zeros((0, m), dtype=np.uint8)
1218        self.X = np.zeros((0, dim), dtype=np.float32)
1220    def add(self, vectors: np.ndarray) -> None:
1221        vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim)
1222        if self.centroids is None:
1223            self.centroids, _ = kmeans(vectors, self.nlist, seed=self.seed)
1224            self.lists = [[] for _ in range(len(self.centroids))]
1225            a = (vectors @ self.centroids.T).argmax(1)
1226            self.pq.train(vectors - self.centroids[a])
1227        a = (vectors @ self.centroids.T).argmax(1)
1228        start = len(self.X)
1229        for offset, c in enumerate(a):
1230            self.lists[c].append(start + offset)
1231        self.assign = np.concatenate([self.assign, a])
1232        self.codes = np.vstack([self.codes, self.pq.encode(vectors - self.centroids[a])])
1233        self.X = np.vstack([self.X, vectors])
1235    def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]:
1236        q = np.asarray(query, dtype=np.float32)
1237        cscores = self.centroids @ q
1238        probe = top_k(cscores, self.nprobe)
1239        cand = np.array([i for c in probe for i in self.lists[c]], dtype=int)
1240        self.ndist += len(self.centroids) + len(cand)
1241        if len(cand) == 0:
1242            return np.array([], dtype=int), np.array([])
1243        table = self.pq.lookup_table(q)  # the residual table is query-only, shared by all lists
1244        approx = cscores[self.assign[cand]] + self.pq.adc_scores(table, self.codes[cand])
1245        if not self.rerank:
1246            order = top_k(approx, k)
1247            return cand[order], approx[order]
1248        short = cand[top_k(approx, max(k, self.rerank))]
1249        exact = self.X[short] @ q
1250        self.ndist += len(short)
1251        order = top_k(exact, k)
1252        return short[order], exact[order]
1266class HNSWIndex(_Index):
1267    """HNSW graph index (Malkov & Yashunin, 2016), written for readability.
1268
1269    Similarity is the dot product (vectors assumed L2-normalized), so
1270    "closer" means "higher score" everywhere below.
1271
1272    Args:
1273        M: links per node on upper layers; layer 0 allows M0 = 2·M.
1274        ef_construction: beam width while inserting (graph quality).
1275        ef_search: beam width while querying (the recall/latency dial).
1276    """
1277
1278    def __init__(self, dim: int, M: int = 16, ef_construction: int = 100, ef_search: int = 50, seed: int = 0):
1279        super().__init__(dim)
1280        self.M, self.M0 = M, 2 * M
1281        self.ef_construction, self.ef_search = ef_construction, ef_search
1282        # mL normalizes the level distribution: P(level >= l) = M^-l, so each
1283        # layer has ~1/M as many nodes as the one below (like a skip list).
1284        self.mL = 1.0 / math.log(M)
1285        self.rng = np.random.default_rng(seed)
1286        self._X = np.zeros((16, dim), dtype=np.float32)  # grows by doubling
1287        self.n = 0
1288        # links[node][layer] -> list of neighbor ids on that layer.
1289        self.links: list[list[list[int]]] = []
1290        self.levels: list[int] = []
1291        self.entry: int | None = None
1292        self.max_level = -1
1293
1294    # -- small utilities --------------------------------------------------
1295
1296    @property
1297    def X(self) -> np.ndarray:
1298        return self._X[: self.n]
1299
1300    def _sims(self, q: np.ndarray, ids: list[int]) -> np.ndarray:
1301        """Similarity of q to several nodes at once (and count the work)."""
1302        self.ndist += len(ids)
1303        return self._X[ids] @ q
1304
1305    def _random_level(self) -> int:
1306        # Exponentially decaying: floor(-ln U · mL). With M=16, ~94% of nodes
1307        # are level 0, ~6% reach level 1, ~0.4% level 2...
1308        return int(-math.log(1.0 - self.rng.random()) * self.mL)
1309
1310    # -- the core routine: beam search on one layer -----------------------
1311
1312    def _search_layer(
1313        self, q: np.ndarray, entry_points: list[int], ef: int, layer: int, trace: list | None = None
1314    ) -> list[tuple[float, int]]:
1315        """Best-first beam search on a single layer. Returns [(sim, id)], best first.
1316
1317        Two heaps:
1318          * `candidates`: nodes still to expand, best first (a max-heap, stored
1319            as negated sims because heapq is a min-heap).
1320          * `results`: the best `ef` nodes seen, worst on top (a min-heap), so
1321            we can cheaply evict the worst when something better shows up.
1322        Stop when the best unexpanded candidate is worse than the worst
1323        result: nothing reachable from here can improve the beam.
1324        """
1325        visited = set(entry_points)
1326        sims = self._sims(q, entry_points)
1327        candidates = [(-s, e) for s, e in zip(sims.tolist(), entry_points)]
1328        heapq.heapify(candidates)
1329        results = [(s, e) for s, e in zip(sims.tolist(), entry_points)]
1330        heapq.heapify(results)
1331        while len(results) > ef:
1332            heapq.heappop(results)
1333
1334        while candidates:
1335            neg_s, c = heapq.heappop(candidates)
1336            if -neg_s < results[0][0]:
1337                break  # closest remaining candidate is worse than our worst result
1338            if trace is not None:
1339                trace.append((layer, c, -neg_s))  # record each node we expand, for figures
1340            fresh = [n for n in self.links[c][layer] if n not in visited]
1341            if not fresh:
1342                continue
1343            visited.update(fresh)
1344            for s, n in zip(self._sims(q, fresh).tolist(), fresh):
1345                if len(results) < ef or s > results[0][0]:
1346                    heapq.heappush(candidates, (-s, n))
1347                    heapq.heappush(results, (s, n))
1348                    if len(results) > ef:
1349                        heapq.heappop(results)
1350        return sorted(results, reverse=True)
1351
1352    def _select_neighbors(self, candidates: list[tuple[float, int]], M: int) -> list[int]:
1353        """HNSW's diversity heuristic (Algorithm 4 in the paper).
1354
1355        Walk candidates from closest to farthest. Keep candidate e only if it
1356        is closer to the base point than to every neighbor kept so far.
1357        Otherwise some kept neighbor already "covers" e's direction, and
1358        greedy search can reach e through it. The result: links that fan out
1359        in different directions, including long "bridges" between clusters.
1360        """
1361        selected: list[int] = []
1362        for s, e in candidates:
1363            if len(selected) >= M:
1364                break
1365            if not selected or float((self._X[selected] @ self._X[e]).max()) < s:
1366                selected.append(e)
1367        return selected
1368
1369    # -- build ---------------------------------------------------------------
1370
1371    def _insert(self, idx: int) -> None:
1372        q = self._X[idx]
1373        level = self._random_level()
1374        self.levels.append(level)
1375        self.links.append([[] for _ in range(level + 1)])
1376
1377        if self.entry is None:  # the very first node
1378            self.entry, self.max_level = idx, level
1379            return
1380
1381        # Phase 1: greedy descent (beam width 1) through layers above `level`.
1382        ep = [self.entry]
1383        for layer in range(self.max_level, level, -1):
1384            ep = [self._search_layer(q, ep, 1, layer)[0][1]]
1385
1386        # Phase 2: on every layer this node lives on, find neighbors and link.
1387        for layer in range(min(level, self.max_level), -1, -1):
1388            found = self._search_layer(q, ep, self.ef_construction, layer)
1389            neighbors = self._select_neighbors(found, self.M)
1390            self.links[idx][layer] = neighbors
1391            max_degree = self.M0 if layer == 0 else self.M
1392            for nb in neighbors:
1393                nb_links = self.links[nb][layer]
1394                nb_links.append(idx)  # links are bidirectional
1395                if len(nb_links) > max_degree:
1396                    # Too many links: re-select the best-spread subset for nb.
1397                    sims = (self._X[nb_links] @ self._X[nb]).tolist()
1398                    ranked = sorted(zip(sims, nb_links), reverse=True)
1399                    self.links[nb][layer] = self._select_neighbors(ranked, max_degree)
1400            ep = [e for _, e in found]  # next layer starts from everything we found
1401
1402        if level > self.max_level:  # new tallest node becomes the entry point
1403            self.entry, self.max_level = idx, level
1404
1405    def add(self, vectors: np.ndarray) -> None:
1406        vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim)
1407        while self.n + len(vectors) > len(self._X):
1408            self._X = np.vstack([self._X, np.zeros_like(self._X)])
1409        for v in vectors:
1410            self._X[self.n] = v
1411            self.n += 1
1412            self._insert(self.n - 1)
1413
1414    # -- query -----------------------------------------------------------------
1415
1416    def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]:
1417        if self.entry is None:
1418            return np.array([], dtype=int), np.array([])
1419        q = np.asarray(query, dtype=np.float32)
1420        ep = [self.entry]
1421        # Highways and main roads: greedy, one best node per layer.
1422        for layer in range(self.max_level, 0, -1):
1423            ep = [self._search_layer(q, ep, 1, layer)[0][1]]
1424        # Side streets: a wide beam at layer 0. ef must be at least k.
1425        found = self._search_layer(q, ep, max(self.ef_search, k), 0)[:k]
1426        return np.array([i for _, i in found], dtype=int), np.array([s for s, _ in found])
1427
1428    def search_trace(self, query: np.ndarray, k: int = 10) -> list[tuple[int, int, float]]:
1429        """Same as `search`, but return every node expanded as (layer, id, sim).
1430
1431        Plotting this shows the idea in one picture: a few long hops on the
1432        top layers, then a careful local search at the bottom.
1433        """
1434        q = np.asarray(query, dtype=np.float32)
1435        trace: list[tuple[int, int, float]] = []
1436        ep = [self.entry]
1437        for layer in range(self.max_level, 0, -1):
1438            ep = [self._search_layer(q, ep, 1, layer, trace)[0][1]]
1439        self._search_layer(q, ep, max(self.ef_search, k), 0, trace)
1440        return trace
1441
1442    def __len__(self) -> int:
1443        return self.n
1444
1445    def layer_sizes(self) -> list[int]:
1446        """How many nodes live on each layer (bottom first). Shrinks ~M× per layer."""
1447        return [sum(1 for lv in self.levels if lv >= layer) for layer in range(self.max_level + 1)]
1448
1449    def memory_bytes(self) -> int:
1450        n_links = sum(len(nbrs) for node in self.links for nbrs in node)
1451        return self.X.nbytes + 4 * n_links  # vectors + 4-byte neighbor ids
HNSW graph index (Malkov & Yashunin, 2016), written for readability.
Similarity is the dot product (vectors assumed L2-normalized), so "closer" means "higher score" everywhere below.
Arguments:
- M: links per node on upper layers; layer 0 allows M0 = 2·M.
- ef_construction: beam width while inserting (graph quality).
- ef_search: beam width while querying (the recall/latency dial).
1278    def __init__(self, dim: int, M: int = 16, ef_construction: int = 100, ef_search: int = 50, seed: int = 0):
1279        super().__init__(dim)
1280        self.M, self.M0 = M, 2 * M
1281        self.ef_construction, self.ef_search = ef_construction, ef_search
1282        # mL normalizes the level distribution: P(level >= l) = M^-l, so each
1283        # layer has ~1/M as many nodes as the one below (like a skip list).
1284        self.mL = 1.0 / math.log(M)
1285        self.rng = np.random.default_rng(seed)
1286        self._X = np.zeros((16, dim), dtype=np.float32)  # grows by doubling
1287        self.n = 0
1288        # links[node][layer] -> list of neighbor ids on that layer.
1289        self.links: list[list[list[int]]] = []
1290        self.levels: list[int] = []
1291        self.entry: int | None = None
1292        self.max_level = -1
1405    def add(self, vectors: np.ndarray) -> None:
1406        vectors = np.asarray(vectors, dtype=np.float32).reshape(-1, self.dim)
1407        while self.n + len(vectors) > len(self._X):
1408            self._X = np.vstack([self._X, np.zeros_like(self._X)])
1409        for v in vectors:
1410            self._X[self.n] = v
1411            self.n += 1
1412            self._insert(self.n - 1)
1416    def search(self, query: np.ndarray, k: int = 10) -> tuple[np.ndarray, np.ndarray]:
1417        if self.entry is None:
1418            return np.array([], dtype=int), np.array([])
1419        q = np.asarray(query, dtype=np.float32)
1420        ep = [self.entry]
1421        # Highways and main roads: greedy, one best node per layer.
1422        for layer in range(self.max_level, 0, -1):
1423            ep = [self._search_layer(q, ep, 1, layer)[0][1]]
1424        # Side streets: a wide beam at layer 0. ef must be at least k.
1425        found = self._search_layer(q, ep, max(self.ef_search, k), 0)[:k]
1426        return np.array([i for _, i in found], dtype=int), np.array([s for s, _ in found])
1428    def search_trace(self, query: np.ndarray, k: int = 10) -> list[tuple[int, int, float]]:
1429        """Same as `search`, but return every node expanded as (layer, id, sim).
1430
1431        Plotting this shows the idea in one picture: a few long hops on the
1432        top layers, then a careful local search at the bottom.
1433        """
1434        q = np.asarray(query, dtype=np.float32)
1435        trace: list[tuple[int, int, float]] = []
1436        ep = [self.entry]
1437        for layer in range(self.max_level, 0, -1):
1438            ep = [self._search_layer(q, ep, 1, layer, trace)[0][1]]
1439        self._search_layer(q, ep, max(self.ef_search, k), 0, trace)
1440        return trace
Same as search, but return every node expanded as (layer, id, sim).
Plotting this shows the idea in one picture: a few long hops on the top layers, then a careful local search at the bottom.
1445    def layer_sizes(self) -> list[int]:
1446        """How many nodes live on each layer (bottom first). Shrinks ~M× per layer."""
1447        return [sum(1 for lv in self.levels if lv >= layer) for layer in range(self.max_level + 1)]
How many nodes live on each layer (bottom first). Shrinks ~M× per layer.
1459def clustered_vectors(n: int, dim: int, n_clusters: int = 50, spread: float = 0.35, seed: int = 0) -> np.ndarray:
1460    """Normalized vectors drawn around random cluster centers.
1461
1462    Real embeddings are clustered (topics, languages, document types), not
1463    uniform. Uniform random high-dimensional data is the hardest case for
1464    ANN, because all distances look alike (the curse of dimensionality).
1465    """
1466    rng = np.random.default_rng(seed)
1467    centers = normalize(rng.standard_normal((n_clusters, dim)))
1468    which = rng.integers(n_clusters, size=n)
1469    return normalize(centers[which] + spread * rng.standard_normal((n, dim)) / np.sqrt(dim) * 3)
Normalized vectors drawn around random cluster centers.
Real embeddings are clustered (topics, languages, document types), not uniform. Uniform random high-dimensional data is the hardest case for ANN, because all distances look alike (the curse of dimensionality).
1472def planar_vectors(n: int, width: float = 0.6, seed: int = 0) -> tuple[np.ndarray, np.ndarray]:
1473    """Unit vectors in a small cap around the north pole, plus their 2-D (x, y).
1474
1475    For points (x, y, 1) normalized with x and y small, ranking by dot product
1476    matches ranking by ordinary distance in the (x, y) plane. That lets us
1477    *draw* what an index does to high-dimensional data.
1478    """
1479    rng = np.random.default_rng(seed)
1480    xy = rng.uniform(-width / 2, width / 2, size=(n, 2))
1481    return normalize(np.hstack([xy, np.ones((n, 1))])), xy
Unit vectors in a small cap around the north pole, plus their 2-D (x, y).
For points (x, y, 1) normalized with x and y small, ranking by dot product matches ranking by ordinary distance in the (x, y) plane. That lets us draw what an index does to high-dimensional data.
1490def small_hnsw_map() -> tuple[HNSWIndex, np.ndarray, dict[str, np.ndarray]]:
1491    """A 60-point HNSW graph on the plane, small enough to draw every link.
1492
1493    Returns (index, xy of each point, {query name: float32 unit vector}).
1494    M = 4 keeps each point to a handful of links, so the picture stays
1495    legible; this seed happens to give four layers (60, 15, 3 and 2 nodes),
1496    so a search takes a real hop on every layer before the bottom.
1497    """
1498    vectors, xy = planar_vectors(60, seed=0)
1499    index = HNSWIndex(3, M=4, ef_construction=20, ef_search=1, seed=7)
1500    index.add(vectors)
1501    queries = {
1502        name: normalize(np.array([[x, y, 1.0]]))[0].astype(np.float32) for name, (x, y) in HNSW_MAP_QUERIES.items()
1503    }
1504    return index, xy, queries
A 60-point HNSW graph on the plane, small enough to draw every link.
Returns (index, xy of each point, {query name: float32 unit vector}). M = 4 keeps each point to a handful of links, so the picture stays legible; this seed happens to give four layers (60, 15, 3 and 2 nodes), so a search takes a real hop on every layer before the bottom.
1507def recall_at_k(found: np.ndarray, truth: np.ndarray) -> float:
1508    """Fraction of the true top-k that the index returned."""
1509    return len(set(found.tolist()) & set(truth.tolist())) / max(1, len(truth))
Fraction of the true top-k that the index returned.
1512def evaluate(index: _Index, queries: np.ndarray, truth: list[np.ndarray], k: int = 10) -> dict[str, float]:
1513    """Mean recall@k, mean latency (ms) and distance computations per query."""
1514    index.ndist = 0
1515    t0 = time.perf_counter()
1516    recalls = [recall_at_k(index.search(q, k)[0], t) for q, t in zip(queries, truth)]
1517    ms = (time.perf_counter() - t0) * 1000 / len(queries)
1518    return dict(recall=float(np.mean(recalls)), ms=ms, ndist=index.ndist / len(queries))
Mean recall@k, mean latency (ms) and distance computations per query.
1527def storage_estimate(n: int, dim: int, bytes_per_value: int = 4) -> float:
1528    """Raw vector storage in GB: n · dim · bytes. (10M × 1536 × 4 ≈ 61 GB.)"""
1529    return n * dim * bytes_per_value / 1e9
Raw vector storage in GB: n · dim · bytes. (10M × 1536 × 4 ≈ 61 GB.)
1532def viz_data() -> dict:
1533    """The graph the site's interactive HNSW widget searches, step by step."""
1534    index, xy, queries = small_hnsw_map()
1535    # float() of a float32 is exact, so the widget searches the very numbers
1536    # the index stores and its sims agree with the lesson's to the last digit
1537    # that matters; the (x, y) positions are only for drawing, so they round.
1538    return {
1539        "hnsw-search": {
1540            "points": [[round(float(x), 4), round(float(y), 4)] for x, y in xy],
1541            "vectors": [[float(v) for v in row] for row in index.X],
1542            "links": index.links,
1543            "entry": index.entry,
1544            "max_level": index.max_level,
1545            "queries": [
1546                {"name": name, "xy": list(HNSW_MAP_QUERIES[name]), "vector": [float(v) for v in q]}
1547                for name, q in queries.items()
1548            ],
1549            "ef_options": [1, 2, 4, 8],
1550        }
1551    }
The graph the site's interactive HNSW widget searches, step by step.
1559def figures() -> dict:
1560    """Plot this lesson's data. matplotlib is imported here, and only here,
1561    so the lesson itself needs nothing beyond NumPy."""
1562    import matplotlib
1563
1564    matplotlib.use("Agg")
1565    import matplotlib.pyplot as plt
1566
1567    HNSW_C, IVF_C, PQ_C, MUTED, HOT = "#2563eb", "#059669", "#d97706", "#9ca3af", "#dc2626"
1568    figs = {}
1569
1570    # --- 0. The eight-point map with both HNSW layers and the search path ----
1571    fig, ax = plt.subplots(figsize=(5.2, 5))
1572    for layer, width, color in [(0, 1, MUTED), (1, 3.5, HNSW_C)]:
1573        for a, nbrs in TOY_LAYERS[layer].items():
1574            for b in nbrs:
1575                if a < b:
1576                    (xa, ya), (xb, yb) = TOY_POINTS[a], TOY_POINTS[b]
1577                    ax.plot([xa, xb], [ya, yb], color=color, lw=width, alpha=0.8, zorder=1,
1578                            label=None)
1579    ax.plot([], [], color=MUTED, lw=1, label="layer 0 links (every point)")
1580    ax.plot([], [], color=HNSW_C, lw=3.5, label="layer 1 links (A, E, G)")
1581    for name, (x, y) in TOY_POINTS.items():
1582        ax.scatter(x, y, s=160, color="white", edgecolors="#374151", lw=1.5, zorder=2)
1583        ax.text(x, y, name, ha="center", va="center", fontsize=9, weight="bold", zorder=3)
1584    query = (5, 4)
1585    path = tiny_hnsw_search(query)
1586    for (_, a, _), (_, b, _) in zip(path, path[1:]):
1587        if a != b:
1588            ax.annotate("", xy=TOY_POINTS[b], xytext=TOY_POINTS[a], zorder=4,
1589                        arrowprops=dict(arrowstyle="->", color=HOT, lw=2.5, shrinkA=9, shrinkB=9))
1590    ax.scatter(*query, marker="*", s=300, color="#facc15", edgecolors="black", zorder=5, label="query (5, 4)")
1591    ax.set_xlim(-0.7, 5.8)
1592    ax.set_ylim(-0.7, 5.8)
1593    ax.set_aspect("equal")
1594    ax.grid(alpha=0.3)
1595    ax.set_title("Eight points: highway hop A→E, street hop E→H")
1596    ax.legend(frameon=False, loc="lower right", fontsize=8)
1597    figs["toy_map"] = fig
1598
1599    # --- 1. The recall/work trade-off for HNSW and IVF ----------------------
1600    n, dim = 2000, 32
1601    X = clustered_vectors(n, dim, seed=0)
1602    queries = clustered_vectors(50, dim, seed=1)
1603    truth = ground_truth(X, queries)
1604    hnsw = HNSWIndex(dim, M=12, ef_construction=60)
1605    hnsw.add(X)
1606    ivf = IVFIndex(dim, nlist=45)
1607    ivf.add(X)
1608    h_pts, i_pts = [], []
1609    for ef in (10, 15, 20, 30, 50, 80, 120, 200):
1610        hnsw.ef_search = ef
1611        r = evaluate(hnsw, queries, truth)
1612        h_pts.append((100 * r["ndist"] / n, r["recall"], ef))
1613    for nprobe in (1, 2, 3, 5, 8, 12, 20, 45):
1614        ivf.nprobe = nprobe
1615        r = evaluate(ivf, queries, truth)
1616        i_pts.append((100 * r["ndist"] / n, r["recall"], nprobe))
1617    fig, ax = plt.subplots(figsize=(6.4, 4))
1618    for pts, color, label, knob in [(h_pts, HNSW_C, "HNSW", "ef"), (i_pts, IVF_C, "IVF", "nprobe")]:
1619        xs, ys, ks = zip(*pts)
1620        ax.plot(xs, ys, "o-", color=color, label=f"{label} (labels: {knob})")
1621        for n_pt, (x, y, kv) in enumerate(zip(xs, ys, ks)):
1622            # The curves run close together, so HNSW labels sit above its line and IVF labels below its own, and the
1623            # last point's label steps left to stay clear of the flat-scan line. An opaque box covers any line left.
1624            above = label == "HNSW"
1625            dx = -14 if n_pt == len(xs) - 1 else (-9 if above else 4)
1626            ax.annotate(str(kv), (x, y), textcoords="offset points", xytext=(dx, 6 if above else -11), fontsize=7,
1627                        color=color, zorder=3, bbox=dict(facecolor="white", edgecolor="none", pad=0.5))
1628    ax.axvline(100, color=MUTED, ls="--")
1629    ax.text(95, 0.45, "flat scan:\nevery vector,\nrecall 1.0", ha="right", color=MUTED, fontsize=8)
1630    ax.set_xscale("log")
1631    ax.set_ylim(0, 1.12)
1632    ax.set_xlabel("% of the corpus compared per query (log scale)")
1633    ax.set_ylabel("recall@10 vs. exact search")
1634    ax.set_title(f"Turning the dial: recall vs. work ({n:,} vectors, {dim}-d)")
1635    ax.legend(frameon=False, loc="upper left")  # the empty corner: the flat-scan line crosses the lower right
1636    figs["recall_vs_work"] = fig
1637
1638    # --- 2. An HNSW search, layer by layer, on data we can draw -------------
1639    V, xy = planar_vectors(300, seed=0)
1640    g = HNSWIndex(3, M=6, ef_construction=40, ef_search=10, seed=0)
1641    g.add(V)
1642    qv, qxy = planar_vectors(1, seed=5)
1643    trace = g.search_trace(qv[0], k=5)
1644    shown = list(range(min(g.max_level, 2), -1, -1))
1645    fig, axes = plt.subplots(1, len(shown), figsize=(4 * len(shown), 4.2))
1646    for ax, layer in zip(np.atleast_1d(axes), shown):
1647        on = [i for i, lv in enumerate(g.levels) if lv >= layer]
1648        for i in on:
1649            for j in g.links[i][layer]:
1650                if i < j:
1651                    ax.plot(*xy[[i, j]].T, color=MUTED, lw=0.4, zorder=1)
1652        ax.scatter(*xy[on].T, s=12 if layer == 0 else 28, color="#374151", zorder=2)
1653        path = [node for lv, node, _ in trace if lv == layer]
1654        if path:
1655            ax.plot(*xy[path].T, "-o", color=HOT, lw=2, ms=5, zorder=3)
1656            ax.scatter(*xy[path[0]], s=90, facecolors="none", edgecolors=HOT, lw=2, zorder=4)
1657        ax.scatter(*qxy[0], marker="*", s=260, color="#facc15", edgecolors="black", zorder=5)
1658        ax.set_title(f"layer {layer}: {len(on)} nodes" + ("  (every vector)" if layer == 0 else ""))
1659        ax.set_xticks([])
1660        ax.set_yticks([])
1661        ax.set_aspect("equal")
1662    fig.suptitle("One HNSW query: long hops up top, a careful local search at the bottom (★ = query)")
1663    fig.tight_layout()
1664    figs["hnsw_search_path"] = fig
1665
1666    # --- 3. IVF cells and which ones a query probes -------------------------
1667    V2, xy2 = planar_vectors(600, seed=2)
1668    ivf2 = IVFIndex(3, nlist=12, nprobe=2, seed=0)
1669    ivf2.add(V2)
1670    q2, qxy2 = planar_vectors(1, seed=9)
1671    cell = (V2 @ ivf2.centroids.T).argmax(1)
1672    probed = top_k(ivf2.centroids @ q2[0], 2)
1673    cxy = ivf2.centroids[:, :2] / ivf2.centroids[:, 2:3]  # back to plane coordinates
1674    fig, ax = plt.subplots(figsize=(5.6, 5))
1675    cmap = plt.get_cmap("tab20")
1676    for c in range(len(cxy)):
1677        members = xy2[cell == c]
1678        hit = c in probed
1679        ax.scatter(*members.T, s=14 if hit else 8, color=cmap(c % 20), alpha=1.0 if hit else 0.25, zorder=2)
1680    ax.scatter(*cxy.T, marker="X", s=80, color="black", zorder=3, label="centroids")
1681    ax.scatter(*cxy[probed].T, marker="X", s=160, color=HOT, zorder=4, label="probed (nprobe = 2)")
1682    ax.scatter(*qxy2[0], marker="*", s=260, color="#facc15", edgecolors="black", zorder=5, label="query")
1683    ax.set_xticks([])
1684    ax.set_yticks([])
1685    ax.set_aspect("equal")
1686    ax.set_title("IVF: 12 clusters, the query scans only the 2 nearest")
1687    ax.legend(frameon=False, loc="upper right", fontsize=8)
1688    figs["ivf_cells"] = fig
1689
1690    # --- 4. PQ: bytes per vector vs. recall ---------------------------------
1691    n3, dim3 = 1200, 64
1692    X3 = clustered_vectors(n3, dim3, seed=3)
1693    q3 = clustered_vectors(40, dim3, seed=4)
1694    t3 = ground_truth(X3, q3)
1695    ms = (2, 4, 8, 16, 32)
1696    raw, rescored = [], []
1697    for m in ms:
1698        a, b = PQIndex(dim3, m=m), PQIndex(dim3, m=m, rerank=100)
1699        a.add(X3)
1700        b.pq = a.pq  # same codebooks: the only difference is the exact re-scoring step
1701        b.add(X3)
1702        raw.append(evaluate(a, q3, t3)["recall"])
1703        rescored.append(evaluate(b, q3, t3)["recall"])
1704    fig, ax = plt.subplots(figsize=(6.2, 3.8))
1705    ax.plot(ms, raw, "o-", color=PQ_C, label="PQ codes only")
1706    ax.plot(ms, rescored, "o-", color=HNSW_C, label="PQ shortlist of 100, re-scored exactly")
1707    ax.set_xscale("log", base=2)
1708    ax.set_xticks(ms, [f"{m} B\n({dim3 * 4 // m}× smaller)" for m in ms])
1709    ax.set_ylim(0, 1.05)
1710    ax.set_xlabel(f"bytes per vector (raw float32 = {dim3 * 4} B)")
1711    ax.set_ylabel("recall@10")
1712    ax.set_title("Product quantization: memory vs. accuracy")
1713    ax.legend(frameon=False, loc="lower right")
1714    figs["pq_tradeoff"] = fig
1715
1716    return figs
Plot this lesson's data. matplotlib is imported here, and only here, so the lesson itself needs nothing beyond NumPy.
1724def demo(n: int = 5000, dim: int = 64, n_queries: int = 100, k: int = 10) -> None:
1725    banner("0. Eight points on a map, query at (5, 4): every index by hand")
1726    table(["point", "position", "squared distance"],
1727          [(p, xy, _sqdist(xy, (5, 4))) for p, xy in TOY_POINTS.items()], floatfmt=".0f")
1728    say("Flat search reads all eight rows: the nearest is H (1). Now the shortcuts.")
1729    table(["layer", "at", "squared distance"], tiny_hnsw_search((5, 4)), floatfmt=".0f")
1730    say("HNSW: one highway hop (A to E), drop a layer, one street hop (E to H). Done.")
1731    probed, scanned, best = tiny_ivf_search((5, 4))
1732    say(f"IVF: nearest cluster is {probed[0]!r}; scan {', '.join(scanned)} only; best is {best}.")
1733    pq = tiny_pq_example()
1734    say(
1735        f"PQ: (0.9, 0.1, -0.2, 0.8) is stored as codes {pq['codes']} (decoded {pq['decoded']}). "
1736        f"Table-lookup score {pq['approx_score']:.1f} vs exact {pq['exact_score']:.1f}: close, not identical."
1737    )
1738
1739    banner("0b. Why not just brute force? Storage and compute math")
1740    for N, d in [(1_000_000, 768), (10_000_000, 1536), (1_000_000_000, 768)]:
1741        print(f"{N:>13,} vectors × {d:4d} dims × 4 bytes = {storage_estimate(N, d):8.1f} GB raw; "
1742              f"flat query = {N * d / 1e9:6.1f} G multiply-adds")
1743    print()
1744    say("A flat scan touches every byte on every query. ANN indexes touch a tiny fraction.")
1745
1746    X = clustered_vectors(n, dim, seed=0)
1747    queries = clustered_vectors(n_queries, dim, seed=1)
1748    truth = ground_truth(X, queries, k)
1749
1750    banner(f"1. Build every index on {n:,} clustered {dim}-d vectors")
1751    builds = {}
1752    for name, idx in [
1753        ("Flat", FlatIndex(dim)),
1754        ("IVF (nlist=70)", IVFIndex(dim, nlist=70, nprobe=4)),
1755        ("PQ (m=16, 1 byte each)", PQIndex(dim, m=16)),
1756        ("IVF-PQ (+rerank 50)", IVFPQIndex(dim, nlist=70, nprobe=8, m=16, rerank=50)),
1757        ("HNSW (M=16, efC=100)", HNSWIndex(dim, M=16, ef_construction=100)),
1758    ]:
1759        t0 = time.perf_counter()
1760        idx.add(X)
1761        builds[name] = (idx, time.perf_counter() - t0)
1762    rows = []
1763    for name, (idx, secs) in builds.items():
1764        r = evaluate(idx, queries, truth, k)
1765        rows.append((name, f"{secs:.2f}s", r["recall"], f"{r['ms']:.2f}", f"{r['ndist']:.0f}", f"{idx.memory_bytes() / 1e6:.2f} MB"))
1766    table(["index", "build", f"recall@{k}", "ms/query", "dist/query", "memory"], rows, floatfmt=".3f")
1767    say(
1768        """
1769        Pure-Python timings are only relative (FAISS or hnswlib are ~100×
1770        faster), so watch "dist/query": the fraction of the database each
1771        query touched. HNSW reaches high recall while comparing against a
1772        small fraction of the vectors. PQ uses a fraction of the memory but
1773        its raw scores are approximate; re-scoring a shortlist with the exact
1774        vectors recovers most of the recall.
1775        """
1776    )
1777
1778    hnsw = builds["HNSW (M=16, efC=100)"][0]
1779    banner("2. HNSW's layers (highway, main roads, side streets)")
1780    sizes = hnsw.layer_sizes()
1781    table(["layer", "nodes", "share"], [(i, s, s / sizes[0]) for i, s in enumerate(sizes)][::-1], floatfmt=".4f")
1782    say(f"mL = 1/ln(M) = {hnsw.mL:.3f}, so each layer holds ~1/M = {1 / hnsw.M:.3f} of the one below.")
1783
1784    banner("3. The recall/latency dial: HNSW efSearch")
1785    rows = []
1786    for ef in (10, 20, 40, 80, 160):
1787        hnsw.ef_search = ef
1788        r = evaluate(hnsw, queries, truth, k)
1789        rows.append((ef, r["recall"], f"{r['ms']:.2f}", f"{r['ndist']:.0f}", f"{100 * r['ndist'] / n:.1f}%"))
1790    table(["efSearch", f"recall@{k}", "ms/query", "dist/query", "of corpus"], rows, floatfmt=".3f")
1791
1792    banner("4. The same dial on IVF: nprobe")
1793    ivf = builds["IVF (nlist=70)"][0]
1794    rows = []
1795    for nprobe in (1, 2, 4, 8, 16, 70):
1796        ivf.nprobe = nprobe
1797        r = evaluate(ivf, queries, truth, k)
1798        rows.append((nprobe, r["recall"], f"{r['ms']:.2f}", f"{r['ndist']:.0f}"))
1799    table(["nprobe", f"recall@{k}", "ms/query", "dist/query"], rows, floatfmt=".3f")
1800    say("At nprobe = nlist, IVF scans everything and matches the flat index exactly.")
1801
1802    banner("5. PQ: bytes per vector vs. recall (and why we re-score)")
1803    rows = []
1804    for m in (4, 8, 16, 32):
1805        for rerank in (0, 100):
1806            pq = PQIndex(dim, m=m, rerank=rerank)
1807            pq.add(X)
1808            r = evaluate(pq, queries, truth, k)
1809            rows.append((m, f"{dim * 4 // m}×", rerank or "-", r["recall"]))
1810    table(["m (bytes/vec)", "compression", "rerank top", f"recall@{k}"], rows, floatfmt=".3f")
1811    takeaway(
1812        "Every ANN index has a recall-vs-cost dial: efSearch for HNSW, nprobe for IVF, "
1813        "bytes-per-vector for PQ. Measure recall@k against a flat index on your own data while you turn it."
1814    )