primer.agents.rag
Retrieval-augmented generation (RAG), end to end
Run: python -m primer.agents.rag
This lesson builds on keyword search, embeddings and reranking from
primer.ml.embeddings.retrieval, on prompt assembly from
primer.agents.context, and on the tool-calling loop from
primer.agents.agent_loop.
Level 1: The practitioner's guide
In one sentence. Retrieval-augmented generation (RAG) fetches the few passages of your own documents most likely to answer a question, puts them in the prompt, and has the model answer from those passages with citations, so the model can use knowledge it was never trained on and a reader can check where each fact came from.
When you need it. When the answer lives in documents the model has not seen (your policies, tickets, contracts, product manuals), when those documents change faster than you could retrain, when every answer must name its source, or when different users may read different documents. You don't need it when the model already knows the subject (public, stable knowledge), when you want to change how the model behaves rather than what it knows (that is fine-tuning: it teaches format and style, not facts that change), or when the whole collection fits in the prompt. Anthropic's contextual retrieval post puts that last threshold at about 200,000 tokens, roughly 500 pages: below it, put everything in the prompt and skip the pipeline. The tell: your model answers a question about the 2023 travel policy confidently and wrongly, because it never saw the 2026 one.
Your options. From the cheapest to the most capable, each one usually added on top of the last:
| Option | What it does | What it guarantees | What it costs | Where it lives |
|---|---|---|---|---|
| Everything in the prompt | Sends the whole collection with every question | Nothing is ever missed by a search | Every token, every call; only up to a few hundred pages | Your prompt |
| Keyword search (BM25) | Ranks passages by the question's rarer words | Exact identifiers (ERR-4012, ticket numbers) are found |
An inverted index; misses synonyms and paraphrase | A search engine |
| Dense search | Ranks passages by embedding similarity, meaning over words | Paraphrases are found ("scam message" finds the phishing guide) | An embedding model at ingest and per query, a vector index; blurs exact codes | A vector index |
| Hybrid search | Runs both and fuses the rankings by rank (RRF), never by score | Both kinds of question, and no score scales to reconcile | Two indexes, two searches per question | Both indexes plus a fusion step |
| Reranking | A cross-encoder reads the question next to each of the top candidates | Far better ordering of the top few | One model score per candidate, so only over a shortlist | A reranking model between search and the prompt |
| Retrieval upgrades | Contextual chunks, query rewriting, HyDE, multi-query, date filters, parent-child | Each fixes one named failure | Model calls at ingest (context lines) or per query (rewrites, drafts) | Ingestion or query time |
| Agentic RAG | The model decides when, how often and with what words to search | Multi-part and vague questions handled; no search for small talk | Several model calls and a step budget per question | An agent loop with a search tool |
| GraphRAG | Extracts entities and relations first, answers by walking the graph or summarizing clusters | Questions about connections and whole-collection themes | A model pass over every document at ingest, and a graph to maintain | Ingestion, plus a graph store |
How to choose. Start from the questions people actually ask, with a labelled set of at least a dozen where you know the right document.
- Questions full of exact identifiers and paraphrases both, which is what
enterprise data looks like: hybrid search with a reranker. In this
lesson's toy set, dense search alone never finds
ERR-4012and plateaus at 92% recall; hybrid reaches 100% by the second result; reranking the hybrid shortlist lifts the share of questions answered by the first result from 75% to 92%. - Chunks that lose their meaning when cut from the document (a fix that never names the error it fixes): contextual chunks. Prefixing each chunk with where it comes from turns "not in the top 20" into "second" here; Anthropic measured a 49% drop in top-20 retrieval failures from contextual embeddings and contextual BM25, and 67% with a reranker added.
- Follow-up questions and vague phrasing: query rewriting and HyDE, which searches with a model-written draft answer.
- Two questions in one, or a question the first search doesn't settle: agentic RAG.
- "What depends on X?" and "what are the themes?": GraphRAG, and only then, because it is the most expensive to build and keep current.
- Whatever you pick: filter by permissions and date before ranking, and verify citations before the answer reaches anyone. Retrieval quality is decided in the first boxes (parsing, chunking, search), never by the prompt.
What it costs. Ingestion costs an embedding per chunk, a keyword index, and for contextual chunks a model call per chunk: with prompt caching, Anthropic's post prices that at \$1.02 per million document tokens. A query costs one embedding, two searches, a reranker score for each of a handful of candidates (8 here, kept to 3), and one generation whose input is the question plus those passages; that prompt is what the answer's latency and token bill mostly consist of. Agentic RAG multiplies the model calls by the number of searches (two for the two-part question in this lesson, zero for "thanks, that's all!") and needs a step limit. Quality costs come from the front of the pipeline: a table flattened by a naive PDF extractor, so that the hotel cap floats free of its grade, is a failure no later stage can repair. Effort goes mostly into the labelled question set and the parsing, not the model.
What breaks.
- The right passage is not in the index. Parsing garbled it, chunking split it from its context, or the permission sync dropped it. Check ingestion before touching anything downstream.
- The right passage is in the index but not in the top k. Measure recall@k on the labelled set. If it is low, change retrieval (hybrid, reranker, rewriting, HyDE, contextual chunks); a prompt cannot fix it.
- Permission leaks. Filtering after generation strips the citation and leaves the fact: in this lesson the restricted forecast's "41 million dollars" reaches an employee who may not read it. Copy each document's access list onto its chunks and filter before ranking; sync revocations promptly.
- Stale sources. A superseded 2023 policy outranks the current one. Carry the date on every chunk and filter or prefer by it.
- Confident answers with no support. Instruct the model to answer only from the sources and to decline otherwise, then check that every cited id was in the context and that its passage supports the claim.
- Blaming the model. With dense-only retrieval this lesson's twelve questions produce five wrong answers, of which only one is a retrieval miss; switching to hybrid removes that one, and the two that remain are generation and data problems. Each needs a different fix, so diagnose first.
In the wild. The name comes from Lewis et al. (2020), who paired a retriever with a generator over a document index. Keyword search is BM25 in Lucene, Elasticsearch and OpenSearch; dense search runs on vector indexes such as FAISS and hosted services such as Pinecone; Elasticsearch documents RRF for fusing the two. HyDE is Gao et al. (2022). Contextual retrieval and prompt caching are described in Anthropic's post, and Claude's citations feature returns the exact passage behind each claim for PDF, plain-text and custom documents. GraphRAG is Microsoft's open implementation of Edge et al. (2024). RAGAS evaluates a RAG pipeline on retrieval and generation separately, which is exactly the split the debugging section relies on.
Go deeper. Level 2 builds the whole pipeline in plain Python: a PDF extractor's damage repaired step by step, chunks that carry their metadata, BM25 and dense search fused by a one-line formula, a reranker, a prompt that tags every source, a citation check, the permission leak reproduced, each upgrade as a working function with its before and after, and the diagnosis figure you can rerun on your own questions. If you only needed to choose, you are done.
Level 2: How it works, from scratch
What follows builds every box of the pipeline from scratch, in the order a question travels through them, then the upgrades, then how to tell a retrieval failure from a generation failure.
An open-book exam with a librarian. Before you answer, the librarian fetches the few pages most likely to contain the answer; you answer from those pages and write down which page each fact came from. If the pages don't contain the answer, you say so instead of guessing.
Retrieval-augmented generation is that arrangement for a language model. The model's training knowledge is frozen and doesn't include your company's documents, so before each answer the system retrieves relevant passages from your documents and puts them in the prompt, and the model generates an answer from them, with citations. It's how you give a model knowledge that changes, or that must be cited, without retraining it.
flowchart LR
  subgraph ING["Ingestion, ahead of time"]
    D[Documents] --> P[Parse] --> C[Chunk + metadata] --> E[Embed + keyword index]
  end
  E --> IX[(Index)]
  subgraph QRY["Query time, per question"]
    Q[Question] --> F[Filter by permissions<br/>and date] --> R[Retrieve: hybrid] --> RR[Rerank] --> AC[Assemble context] --> G[Generate + cite] --> V[Verify citations]
  end
  IX --> F
Reading it: the top row runs once per document, whenever documents change; the bottom row runs for every question. Everything the answer can contain has to survive every box, left to right: a table mangled at Parse or a passage missing at Retrieve can't be fixed by a better prompt at Generate. That's why most RAG quality work happens in the first boxes, not the last.
In code: RAGIndex is the top row: it chunks every document and builds
the keyword and dense indexes. answer is the bottom row, from filtered
retrieval to verified citations, and returns a RAGResult.
The rest of this lesson walks the boxes in order, then covers the upgrades and how to debug a wrong answer.
Parsing: where quality dies first
Everyday picture. Photocopy a newspaper page and read it straight across: you get the first line of one column, then the first line of the next story, and nothing makes sense. Text extracted from PDFs has the same problems: running headers and page numbers mixed into the text, words broken across lines, and tables flattened into a row of numbers with no columns.
Worked example. MESSY_PDF is two pages of a travel policy as a naive
extractor returns it. clean_extracted_text repairs it in four steps:
| Damage | Before | After |
|---|---|---|
| Header repeated on every page | Northwind Ltd Travel Policy 2026 … CONFIDENTIAL |
removed (it appears on 2 of 2 pages) |
| Page-number footer | Page 1 of 2 |
removed |
| Word hyphenated across a line break | all em- / ployees travelling |
all employees travelling |
| Table flattened | L1-L3 150 60 L4-L6 200 75 |
kept as rows, then one sentence per row |
The table is the dangerous one. Flattened, "200" floats free of its grade.
table_rows_as_sentences turns each row into a self-contained sentence,
Grade L4-L6: hotel cap 200, meal cap 75., so any row can be retrieved on
its own and still says what its numbers mean.
flowchart LR
  RAW[Raw extracted text] --> H[Drop lines repeated<br/>on most pages]
  H --> N[Drop page numbers]
  N --> J[Rejoin hyphenated words,<br/>unwrap paragraphs]
  J --> T{Table rows?}
  T -->|yes| S[One sentence per row,<br/>headers repeated]
  T -->|no| P[Paragraphs]
  S --> OUT[Clean text for chunking]
  P --> OUT
Reading it: each box removes one kind of extraction damage. The diamond is the important decision: prose and tables need different handling, because a table's meaning lives in its columns. Real pipelines add layout-aware parsers and OCR (optical character recognition: reading text from an image of a page) for scanned documents, with a quality check on the output.
Why it matters. Enterprise documents are scanned, multi-column, full of tables that span pages. If parsing garbles the numbers, no retriever or model can recover them, and the failure looks like a model error.
In code: extract_table finds a table by its header row in the cleaned
text and returns each row as a dict, ready for table_rows_as_sentences.
Chunking, with metadata that travels
Everyday picture. Index cards. Each card holds one idea, small enough to match a question precisely, and in its corner a label: which document, which date, who may read it.
Worked example. With a 15-word limit, it-004 splits into two passages:
| Passage id | Text | Updated | Readers |
|---|---|---|---|
it-004#0 |
ERR-4012 means the VPN tunnel could not be established, usually because the client is out of date. | 2026-04-10 | everyone |
it-004#1 |
Update AnyConnect to version 5.1 or later and reboot. | 2026-04-10 | everyone |
(The limit is tiny because the toy documents are tiny; real systems use a few
hundred tokens.) Split on the document's structure (sentences, paragraphs,
sections), not at fixed character counts that cut a sentence in half.
primer.ml.embeddings.retrieval compares chunking strategies in depth.
Why it matters. Small chunks match precisely but can lose context (the second card doesn't say which error it fixes; see contextual retrieval below). The metadata is what makes permission and date filters possible later.
In code: chunk_document splits a document on sentence boundaries into
Passages, and each Passage carries its id, title, department, date and
readers.
Retrieval: keyword and meaning, fused
Everyday picture. Two librarians: one searches the catalogue for your exact words, the other understands what you mean even when you use different words. You take the books both of them rank highly.
- Keyword search (BM25) scores passages by the question's words,
giving more weight to rare words and less to long passages. It nails
exact identifiers like
ERR-4012and misses synonyms. - Dense search compares embeddings (vectors where closeness means
similar meaning; see
primer.ml.embeddings). It finds "scam message in my inbox" → the phishing guide with no shared words, but blurs exact codes. - Hybrid search runs both and merges the two rankings with reciprocal rank fusion (RRF), which only needs the ranks, never the scores. BM25 scores and cosine similarities live on different scales, so adding them would be meaningless.
Level 3: the formula and its symbols
$$ \text{RRF}(d) = \sum_{i} \frac{1}{k + \text{rank}_i(d)} $$
Symbols
| Symbol | Meaning here | Worked example |
|---|---|---|
| $d$ | one passage | it-004#0 |
| $i$ | one of the rankings being fused (keyword, dense) | 2 rankings |
| $\text{rank}_i(d)$ | position of $d$ in ranking $i$ (1 = best); rankings that miss $d$ contribute nothing | 1st, 3rd |
| $k$ | a damping constant; 60 is the usual choice | 60 |
| $\sum_i$ | add up over the rankings |
In words: each ranking gives a passage a vote worth one over sixty-plus its position, and the votes are added.
On the worked example: a passage ranked 1st by dense search and 3rd by keyword search scores 1/61 + 1/63 = 0.0323. A passage ranked 1st by one list and absent from the other scores only 1/61 = 0.0164. Passages that both methods agree on rise to the top.
Level 3: in Python
In Python:
k = 60
# 1st by dense, 3rd by keyword: Σ_i 1/(k + rank_i(d))
round(1 / (k + 1) + 1 / (k + 3), 4)  # → 0.0323
# 1st in one list, absent from the other
round(1 / (k + 1), 4)  # → 0.0164
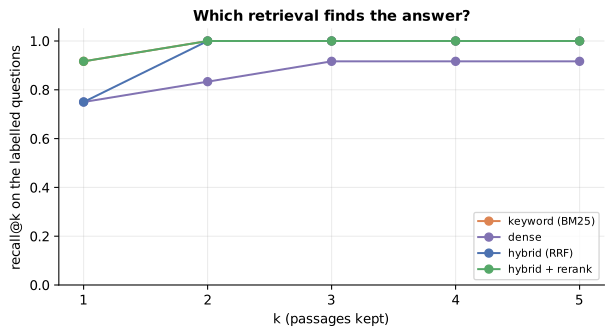
Reading it: the x-axis is how many passages you keep (k); the y-axis is
recall@k, the share of the 12 labelled questions whose correct document
is among those k. On this small set many questions reuse the documents'
own words, so keyword search is already strong. Dense search plateaus at
92% because it never finds ERR-4012. Hybrid reaches 100% by k = 2 but only
75% at k = 1. Reranking the hybrid shortlist lifts the top-1 result to 92%.
Run this measurement on your questions before choosing a method.
Level 3: the formula and its symbols
$$ \text{recall@}k = \frac{1}{|Q|} \sum_{q \in Q} \mathbb{1}\bigl[\text{a relevant document is in the top } k \text{ for } q\bigr] $$
Symbols
| Symbol | Meaning here |
|---|---|
| $Q$ | the labelled questions; $\lvert Q\rvert$ is how many (12 here) |
| $q$ | one question |
| $\mathbb{1}[\ldots]$ | 1 if true, 0 if not |
In words: the share of questions for which the right document made it into the top k.
On the worked example: dense search at k = 3 finds the right document for
11 of 12 questions (all but ERR-4012): 11/12 = 0.92.
Level 3: in Python
In Python:
# 𝟙[...] for each of the 12 questions; ERR-4012 is the 0
found = [1] * 11 + [0]
# (1/|Q|) Σ over q in Q
round(sum(found) / len(found), 2)  # → 0.92
In code: RAGIndex.retrieve ranks the allowed passages with
primer.ml.embeddings.retrieval.BM25, with dense similarity, or with both
fused by primer.ml.embeddings.retrieval.reciprocal_rank_fusion, depending
on the mode you ask for. recall_curve measures recall@k for each method.
Reranking: read the question and each passage together
Everyday picture. The librarians bring back twenty books quickly; an expert then reads your question next to each book and picks the best three.
A reranker (usually a cross-encoder: a model that reads the question
and one passage together and outputs a relevance score) is far more
precise than comparing precomputed vectors, and far too slow to run over
every passage. So retrieval casts a wide, cheap net (here 8 candidates) and
the reranker keeps the best few (here 3). This module reuses the toy
cross-encoder from primer.ml.embeddings.retrieval.
In code: RAGIndex.rerank scores each (question, passage) pair with
primer.ml.embeddings.retrieval.CrossEncoder and keeps the best few.
Assemble, generate, cite, verify
Worked example. "What does ERR-4012 mean?" becomes this context (each
source escaped and tagged with its id; the question last; see
primer.agents.context):
<sources>
<source id="it-004#1" title="Error ERR-4012: VPN tunnel failed" updated="2026-04-10">Update AnyConnect to version 5.1 or later and reboot.</source>
<source id="it-004#0" title="Error ERR-4012: VPN tunnel failed" updated="2026-04-10">ERR-4012 means the VPN tunnel could not be established, usually because the client is out of date.</source>
<source id="it-002#2" title="Password policy" updated="2025-11-20">This policy applies to all employees and contractors.</source>
</sources>
<question>What does ERR-4012 mean?</question>
and the answer is "ERR-4012 means the VPN tunnel could not be established,
usually because the client is out of date. [it-004#0]". verify_citations
then checks that every cited id was really in the context and that the
cited passage supports the claim before it; a question the sources don't
cover gets "I don't know based on the provided sources."
sequenceDiagram
  participant U as User
  participant A as RAG service
  participant I as Index
  participant M as Model
  U->>A: What does ERR-4012 mean?
  A->>I: hybrid search, filtered to what this user may read
  I-->>A: 8 candidate passages
  A->>A: rerank, keep 3
  A->>M: rules + tagged sources + question
  M-->>A: answer with [it-004#0]
  A->>A: verify: id was in context, passage supports claim
  A-->>U: answer + clickable citation
Reading it: time runs downward. Note the order: the permission filter runs at the index, before any passage is fetched; the model only ever sees three passages; and nothing reaches the user until the citations check out. Citations are what let a person verify an answer in seconds, which is most of what makes people trust the system.
In code: assemble_context builds the tagged sources and the question.
generate sends them to the model with the answer-from-sources rules, and
grounded_policy is the offline stand-in model that honours them. answer
chains retrieve, rerank, assemble, generate and verify_citations.
Permission-aware retrieval: filter before, never after
Everyday picture. A librarian checks your library card before fetching from the restricted archive. Checking it after you've read the document is pointless.
Each passage carries its access-control list (ACL: the groups allowed to
read it), copied from the source system (SharePoint, Google Drive, a wiki).
RAGIndex.retrieve drops every passage the user can't read before
ranking, so restricted text can't reach the context, the model, or the
answer.
Worked example. "What is the Q3 revenue forecast?" (the forecast
document is readable only by finance and exec):
| Who asks | How it's filtered | Answer |
|---|---|---|
| finance user | before retrieval | "Q3 revenue is forecast at 41 million dollars… [fin-006#0]" |
| anyone else | before retrieval | "I don't know based on the provided sources." |
| anyone else | after generation (citation removed) | "Q3 revenue is forecast at 41 million dollars…" |
sequenceDiagram
  participant U as Employee (not finance)
  participant A as RAG service
  participant M as Model
  rect rgb(250, 225, 225)
  Note over A,M: Wrong: filter after generation
  A->>M: sources include the restricted forecast
  M-->>A: "…41 million dollars [fin-006#0]"
  A->>A: strip the restricted citation
  A-->>U: "…41 million dollars" (leaked)
  end
  rect rgb(225, 240, 225)
  Note over A,M: Right: filter before retrieval
  A->>A: drop passages the user can't read
  A->>M: sources without the forecast
  M-->>A: "I don't know…"
  A-->>U: nothing restricted
  end
Reading it: in the red box the model saw the restricted passage, so the number is already in its words, and deleting the citation marker afterwards leaves the fact behind. In the green box the passage never left the index. Permission changes in the source system must also sync to the index quickly, or a revoked user keeps access until the next re-index.
In code: post_generation_filter_answer is the wrong way, kept so the
leak can be shown: it retrieves for every group, generates, then strips the
restricted citation markers.
Retrieval upgrades
Each upgrade below is a working function, and each fixes a failure you can
reproduce in demo():
| Upgrade | Everyday picture | Before → after (top 3) |
|---|---|---|
Query rewriting (rewrite_query) |
Repeating the earlier topic when you ask a follow-up | "what if it fails?" after a VPN question: printer guide → VPN setup and ERR-4012 |
HyDE (hyde_search) |
Telling the librarian "I'm looking for a page that says something like…" | "a weird message asking for my bank details": nothing relevant → phishing guide first |
Multi-query (multi_query_search) |
Asking three librarians in three different phrasings | "two step login setup": no MFA guide → MFA guide in top 3 |
Metadata filter (updated_after) |
Ignoring the out-of-date binder on the shelf | superseded 2023 travel policy first → gone |
Contextual retrieval (RAGIndex(contextual=True)) |
Writing the chapter title on every index card | "how do I fix ERR-4012": fix sentence missing → found |
Parent-child (retrieve_parents) |
Find the sentence, hand over the whole page | a matching sentence → its full document |
HyDE (Hypothetical Document Embeddings) deserves a picture, because it sounds backwards: you ask a model to invent an answer, then search with it.
flowchart LR
  Q["Question:<br/>'weird message asking<br/>for my bank details'"] --> M[Model drafts a<br/>plausible answer]
  M --> H["Draft: 'This sounds like a phishing<br/>email… report it in Outlook'"]
  H --> E[Embed the draft]
  E --> S[Dense search]
  S --> R[Phishing guide, rank 1]
Reading it: questions and answers are written differently. The user's words ("weird", "bank details") appear nowhere in the phishing guide, but the drafted answer uses the vocabulary answers use ("phishing", "report", "suspicious"), so its embedding lands next to the real passage. The draft may be wrong in its details; that's fine, because it's only used to search and is never shown to the user.
Contextual retrieval fixes the "second index card" problem from the chunking section: before indexing, each passage gets a short line saying where it comes from. Here that's just the title and department; Anthropic's version asks a model to write one sentence situating the chunk in its document.
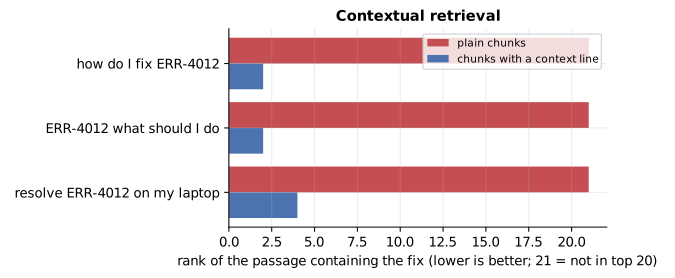
Reading it: three ways of asking how to fix ERR-4012; each pair of bars is the rank of the passage "Update AnyConnect to version 5.1 or later and reboot." (shorter is better, and 21 means not in the top 20). Without context the passage never mentions ERR-4012, and for all three phrasings it doesn't make the top 20 at all. With the title prefixed it ranks 2nd, 2nd and 4th: in the top five every time, though "resolve ERR-4012 on my laptop" still ranks three passages from the laptop guide above it. A context line turns "never found" into "found", and ranking the right passage first is then the reranker's job.
Agentic RAG: let the model decide when and what to search
Everyday picture. A researcher rather than a librarian: reads the question, decides what to look up, reads the results, and searches again if something's missing.
Plain RAG searches exactly once, with the user's words. In agentic RAG search is a tool the model calls: zero times for small talk, several times for a multi-part question, with its own reformulated queries.
Worked example. "What is the per-diem for meals and how do I upload
expense receipts?" produces two searches ("What is the per-diem for meals",
"how do I upload expense receipts") and an answer citing both fin-002#2
and fin-004#0. "thanks, that's all!" produces no search at all.
sequenceDiagram
  participant U as User
  participant M as Model
  participant S as search_kb tool
  U->>M: per-diem for meals AND how to upload receipts?
  M->>S: search_kb("per-diem for meals")
  S-->>M: fin-002 passages
  M->>S: search_kb("how do I upload expense receipts")
  S-->>M: fin-004 passages
  M-->>U: both answers, each with its citation
Reading it: the model, not a fixed pipeline, decides how many searches
to run and with which words. That handles multi-part and vague questions
better, at the cost of more model calls, more latency, and a loop that needs
the usual step budget (primer.agents.agent_loop). The search tool here also
applies the freshness filter itself, so the agent can't forget it.
In code: agentic_answer offers the model one search tool and runs the
loop: each search retrieves, reranks and returns tagged passages, until the
model answers or the step limit is hit.
GraphRAG: questions about connections
Everyday picture. A detective's corkboard: photos of people and places joined by string, each string labelled with the note that established it.
Some questions aren't answered by any single passage: "what depends on
two-factor authentication?" or "what are the main themes across these
contracts?". GraphRAG first extracts entities (named things:
systems, people, products) and the relationships between them into a graph,
then answers by walking it, or by summarizing groups of connected entities.
build_graph does the smallest honest version: two entities are linked when
one sentence mentions both, and each link remembers which document said so.
flowchart LR
  TF((two-factor)) ---|it-006| VPN((VPN))
  TF ---|it-006| EM((email))
  TF ---|it-006| AA((authenticator app))
  TF ---|it-003| AC((AnyConnect))
  TF ---|it-003| SC((software center))
  TF ---|hr-003| LT((laptop))
  AC ---|it-003| SC
  VPN ---|it-006| EM
  AA ---|it-001| SSP((self-service portal))
Reading it: each circle is an entity found in the knowledge base; each line is a sentence that mentioned both ends, labelled with its source document. "What depends on two-factor?" is answered by reading the neighbours of one circle, with citations for free. Real GraphRAG uses a model to extract typed relations ("requires", "replaces") and to write a summary for each cluster, which is what makes broad, whole-collection questions answerable.
In code: communities groups the graph from build_graph into
connected clusters of entities, the "themes" a real GraphRAG system would
summarize.
Debugging a confident wrong answer
Everyday picture. A student gets an exam question wrong. Either the librarian brought the wrong book, or the student misread the right one. The fixes are completely different, so find out which before changing anything.
Worked example. debug_wrong_answers runs the 12 labelled questions and
classifies each: retrieval miss (no relevant document in the top 3: no
prompt can fix it), generation miss (the right document was there but the
answer didn't use it), or ok. With dense-only retrieval, "what does ERR-4012
mean" is a retrieval miss and recall@3 is 0.92; switching to hybrid fixes it
(recall@3 = 1.00). What's left are generation misses. One of them,
"per-diem for meals when traveling", is answered from the superseded 2023
policy: a data problem that a date filter fixes. The other, "enroll in
MFA", is a limit of this lesson's stand-in model rather than of RAG: it
matches words literally, so "enroll" misses the passage's "enrolling", and
with only "MFA" in common it declines to answer. A real model would read
it-006 and answer.
flowchart TD
  W[Confident wrong answer] --> R{Right passage in<br/>the top k?}
  R -->|no| P{Is it in the<br/>index at all?}
  P -->|no| FIXI[Fix ingestion:<br/>parsing, chunking, permissions sync]
  P -->|yes| FIXR[Fix retrieval:<br/>hybrid, rerank, rewrite, HyDE, filters]
  R -->|yes| C{Was it in the<br/>final context?}
  C -->|no| FIXC[Fix assembly:<br/>reranker, budget, top_n]
  C -->|yes| FIXG[Fix generation:<br/>instructions, citations, stale sources]
Reading it: start at the top and answer each question with a measurement, not a guess. Most teams jump straight to the bottom-right box and edit the prompt; the diagram says to rule out the three earlier failure points first, because they're more common and a prompt can't fix them.
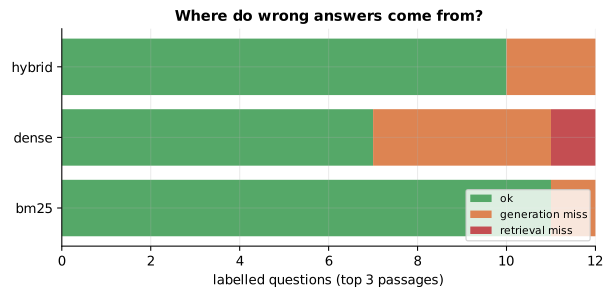
Reading it: each bar is one retrieval method over the 12 labelled questions, split into ok (green), generation misses (orange) and retrieval misses (red). Dense search has a retrieval miss (the error code); hybrid removes it. The orange that remains is where to look next, and it's not retrieval.
In 20 seconds
- RAG retrieves relevant passages at question time and has the model answer from them with citations: knowledge that changes or must be cited, with no retraining.
- Quality is decided early: parsing (tables!), chunking with metadata, and hybrid retrieval with reranking.
- Filter by permissions before retrieval, never after generation.
- Upgrades: query rewriting, HyDE, multi-query, date filters, contextual retrieval, parent-child; agentic RAG for multi-part questions; GraphRAG for questions about connections.
- Debug by measuring retrieval (recall@k) first, then generation.
Self-test questions
Your RAG system gives confident wrong answers. Debug it step by step. Take the failing questions (and build a labelled set if you don't have one). First, is the right passage in the index at all? If not, it's ingestion: parsing, chunking or permission sync. Second, is it in the top k? Measure recall@k; if not, fix retrieval: hybrid search, a reranker, query rewriting or HyDE, metadata filters, contextual chunks, domain-tuned embeddings. Third, did it survive into the final context? If not, fix reranking or the context budget. Only then look at generation: instructions to answer only from sources and to decline otherwise, citation checks, stale or contradictory sources. Add every case to the golden set.
Why does hybrid search beat pure vector search on enterprise data? Enterprise questions are full of exact identifiers (error codes, product names, ticket numbers) that embeddings blur, and full of paraphrases that keyword search misses. Hybrid gets both, and RRF merges the rankings without having to reconcile incompatible score scales.
How do you make RAG respect document permissions? Copy each document's access-control list onto every chunk at ingestion, filter candidates by the user's groups before ranking, and sync permission changes from the source system promptly. Never filter after generation: the model has already used the restricted text.
When would you use agentic RAG instead of a single retrieval step? For multi-part or vague questions, and when the model needs to judge whether results are good enough and search again. It costs more calls and latency, so keep single-shot retrieval for simple lookups.
RAG or fine-tuning for a company knowledge assistant?
RAG for knowledge: it updates by re-indexing, cites sources, and respects
permissions. Fine-tuning teaches behaviour and format, not facts that
change. Most systems are RAG plus a good prompt (see
primer.ml.training_stages).
The papers behind this lesson
- Lewis et al., Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks (2020), https://arxiv.org/abs/2005.11401. Coined the term and showed that pairing a generator with a retriever over a document index beats a model relying on its weights alone for knowledge-heavy questions. annotated companion
- Gao, Ma, Lin & Callan, Precise Zero-Shot Dense Retrieval without Relevance Labels (2022), https://arxiv.org/abs/2212.10496. Introduced HyDE: search with an embedding of a model-written hypothetical answer. annotated companion
- Edge et al., From Local to Global: A Graph RAG Approach to Query-Focused Summarization (2024), https://arxiv.org/abs/2404.16130. Builds an entity graph and community summaries so that whole-collection questions can be answered.
Further reading
- Anthropic, Introducing Contextual Retrieval: https://www.anthropic.com/news/contextual-retrieval
- Anthropic citations docs: https://docs.claude.com/en/docs/build-with-claude/citations
- Microsoft GraphRAG documentation: https://microsoft.github.io/graphrag/
- RAGAS documentation (RAG evaluation): https://docs.ragas.io/
- The retrieval lesson in this repo, with BM25, RRF, cross-encoders and chunking in depth:
primer.ml.embeddings.retrieval
1r""" 2# Retrieval-augmented generation (RAG), end to end 3 4Run: `python -m primer.agents.rag` 5 6This lesson builds on keyword search, embeddings and reranking from 7`primer.ml.embeddings.retrieval`, on prompt assembly from 8`primer.agents.context`, and on the tool-calling loop from 9`primer.agents.agent_loop`. 10 11## Level 1: The practitioner's guide 12 13**In one sentence.** Retrieval-augmented generation (RAG) fetches the few 14passages of your own documents most likely to answer a question, puts them 15in the prompt, and has the model answer from those passages with citations, 16so the model can use knowledge it was never trained on and a reader can 17check where each fact came from. 18 19**When you need it.** When the answer lives in documents the model has not 20seen (your policies, tickets, contracts, product manuals), when those 21documents change faster than you could retrain, when every answer must name 22its source, or when different users may read different documents. You don't 23need it when the model already knows the subject (public, stable knowledge), 24when you want to change *how* the model behaves rather than *what* it 25knows (that is fine-tuning: it teaches format and style, not facts that 26change), or when the whole collection fits in the prompt. Anthropic's 27contextual retrieval post puts that last threshold at about 200,000 tokens, 28roughly 500 pages: below it, put everything in the prompt and skip the 29pipeline. The tell: your model answers a question about the 2023 travel 30policy confidently and wrongly, because it never saw the 2026 one. 31 32**Your options.** From the cheapest to the most capable, each one usually 33added on top of the last: 34 35| Option | What it does | What it guarantees | What it costs | Where it lives | 36|---|---|---|---|---| 37| Everything in the prompt | Sends the whole collection with every question | Nothing is ever missed by a search | Every token, every call; only up to a few hundred pages | Your prompt | 38| Keyword search (BM25) | Ranks passages by the question's rarer words | Exact identifiers (`ERR-4012`, ticket numbers) are found | An inverted index; misses synonyms and paraphrase | A search engine | 39| Dense search | Ranks passages by embedding similarity, meaning over words | Paraphrases are found ("scam message" finds the phishing guide) | An embedding model at ingest and per query, a vector index; blurs exact codes | A vector index | 40| Hybrid search | Runs both and fuses the rankings by rank (RRF), never by score | Both kinds of question, and no score scales to reconcile | Two indexes, two searches per question | Both indexes plus a fusion step | 41| Reranking | A cross-encoder reads the question next to each of the top candidates | Far better ordering of the top few | One model score per candidate, so only over a shortlist | A reranking model between search and the prompt | 42| Retrieval upgrades | Contextual chunks, query rewriting, HyDE, multi-query, date filters, parent-child | Each fixes one named failure | Model calls at ingest (context lines) or per query (rewrites, drafts) | Ingestion or query time | 43| Agentic RAG | The model decides when, how often and with what words to search | Multi-part and vague questions handled; no search for small talk | Several model calls and a step budget per question | An agent loop with a search tool | 44| GraphRAG | Extracts entities and relations first, answers by walking the graph or summarizing clusters | Questions about connections and whole-collection themes | A model pass over every document at ingest, and a graph to maintain | Ingestion, plus a graph store | 45 46**How to choose.** Start from the questions people actually ask, with a 47labelled set of at least a dozen where you know the right document. 48 49- Questions full of exact identifiers and paraphrases both, which is what 50 enterprise data looks like: hybrid search with a reranker. In this 51 lesson's toy set, dense search alone never finds `ERR-4012` and plateaus 52 at 92% recall; hybrid reaches 100% by the second result; reranking the 53 hybrid shortlist lifts the share of questions answered by the first 54 result from 75% to 92%. 55- Chunks that lose their meaning when cut from the document (a fix that 56 never names the error it fixes): contextual chunks. Prefixing each chunk 57 with where it comes from turns "not in the top 20" into "second" here; 58 Anthropic measured a 49% drop in top-20 retrieval failures from 59 contextual embeddings and contextual BM25, and 67% with a reranker added. 60- Follow-up questions and vague phrasing: query rewriting and HyDE, which 61 searches with a model-written draft answer. 62- Two questions in one, or a question the first search doesn't settle: 63 agentic RAG. 64- "What depends on X?" and "what are the themes?": GraphRAG, and only then, 65 because it is the most expensive to build and keep current. 66- Whatever you pick: filter by permissions and date *before* ranking, and 67 verify citations before the answer reaches anyone. Retrieval quality is 68 decided in the first boxes (parsing, chunking, search), never by the 69 prompt. 70 71**What it costs.** Ingestion costs an embedding per chunk, a keyword index, 72and for contextual chunks a model call per chunk: with prompt caching, 73Anthropic's post prices that at \$1.02 per million document tokens. A query 74costs one embedding, two searches, a reranker score for each of a handful 75of candidates (8 here, kept to 3), and one generation whose input is the 76question plus those passages; that prompt is what the answer's latency and 77token bill mostly consist of. Agentic RAG multiplies the model calls by the 78number of searches (two for the two-part question in this lesson, zero for 79"thanks, that's all!") and needs a step limit. Quality costs come from the 80front of the pipeline: a table flattened by a naive PDF extractor, so that 81the hotel cap floats free of its grade, is a failure no later stage can 82repair. Effort goes mostly into the labelled question set and the parsing, 83not the model. 84 85**What breaks.** 86 87- **The right passage is not in the index.** Parsing garbled it, chunking 88 split it from its context, or the permission sync dropped it. Check 89 ingestion before touching anything downstream. 90- **The right passage is in the index but not in the top k.** Measure 91 recall@k on the labelled set. If it is low, change retrieval (hybrid, 92 reranker, rewriting, HyDE, contextual chunks); a prompt cannot fix it. 93- **Permission leaks.** Filtering after generation strips the citation and 94 leaves the fact: in this lesson the restricted forecast's "41 million 95 dollars" reaches an employee who may not read it. Copy each document's 96 access list onto its chunks and filter before ranking; sync revocations 97 promptly. 98- **Stale sources.** A superseded 2023 policy outranks the current one. 99 Carry the date on every chunk and filter or prefer by it. 100- **Confident answers with no support.** Instruct the model to answer only 101 from the sources and to decline otherwise, then check that every cited id 102 was in the context and that its passage supports the claim. 103- **Blaming the model.** With dense-only retrieval this lesson's twelve 104 questions produce five wrong answers, of which only one is a retrieval 105 miss; switching to hybrid removes that one, and the two that remain are 106 generation and data problems. Each needs a different fix, so diagnose 107 first. 108 109**In the wild.** The name comes from Lewis et al. (2020), who paired a 110retriever with a generator over a document index. Keyword search is BM25 111in Lucene, Elasticsearch and OpenSearch; dense search runs on vector 112indexes such as FAISS and hosted services such as Pinecone; Elasticsearch 113documents RRF for fusing the two. HyDE is Gao et al. (2022). Contextual 114retrieval and prompt caching are described in Anthropic's post, and 115Claude's citations feature returns the exact passage behind each claim for 116PDF, plain-text and custom documents. GraphRAG is Microsoft's open 117implementation of Edge et al. (2024). RAGAS evaluates a RAG pipeline on 118retrieval and generation separately, which is exactly the split the 119debugging section relies on. 120 121**Go deeper.** Level 2 builds the whole pipeline in plain Python: a PDF 122extractor's damage repaired step by step, chunks that carry their 123metadata, BM25 and dense search fused by a one-line formula, a reranker, a 124prompt that tags every source, a citation check, the permission leak 125reproduced, each upgrade as a working function with its before and after, 126and the diagnosis figure you can rerun on your own questions. If you only 127needed to choose, you are done. 128 129## Level 2: How it works, from scratch 130 131What follows builds every box of the pipeline from scratch, in the order a 132question travels through them, then the upgrades, then how to tell a 133retrieval failure from a generation failure. 134 135An open-book exam with a librarian. Before you answer, the librarian fetches 136the few pages most likely to contain the answer; you answer from those 137pages and write down which page each fact came from. If the pages don't 138contain the answer, you say so instead of guessing. 139 140**Retrieval-augmented generation** is that arrangement for a language 141model. The model's training knowledge is frozen and doesn't include your 142company's documents, so before each answer the system *retrieves* relevant 143passages from your documents and puts them in the prompt, and the model 144*generates* an answer from them, with citations. It's how you give a model 145knowledge that changes, or that must be cited, without retraining it. 146 147```mermaid 148flowchart LR 149 subgraph ING["Ingestion, ahead of time"] 150 D[Documents] --> P[Parse] --> C[Chunk + metadata] --> E[Embed + keyword index] 151 end 152 E --> IX[(Index)] 153 subgraph QRY["Query time, per question"] 154 Q[Question] --> F[Filter by permissions<br/>and date] --> R[Retrieve: hybrid] --> RR[Rerank] --> AC[Assemble context] --> G[Generate + cite] --> V[Verify citations] 155 end 156 IX --> F 157``` 158 159**Reading it:** the top row runs once per document, whenever documents 160change; the bottom row runs for every question. Everything the answer can 161contain has to survive every box, left to right: a table mangled at *Parse* 162or a passage missing at *Retrieve* can't be fixed by a better prompt at 163*Generate*. That's why most RAG quality work happens in the first boxes, not 164the last. 165 166**In code:** `RAGIndex` is the top row: it chunks every document and builds 167the keyword and dense indexes. `answer` is the bottom row, from filtered 168retrieval to verified citations, and returns a `RAGResult`. 169 170The rest of this lesson walks the boxes in order, then covers the upgrades 171and how to debug a wrong answer. 172 173## Parsing: where quality dies first 174 175**Everyday picture.** Photocopy a newspaper page and read it straight 176across: you get the first line of one column, then the first line of the 177next story, and nothing makes sense. Text extracted from PDFs has the same 178problems: running headers and page numbers mixed into the text, words 179broken across lines, and tables flattened into a row of numbers with no 180columns. 181 182**Worked example.** `MESSY_PDF` is two pages of a travel policy as a naive 183extractor returns it. `clean_extracted_text` repairs it in four steps: 184 185| Damage | Before | After | 186|---|---|---| 187| Header repeated on every page | `Northwind Ltd Travel Policy 2026 … CONFIDENTIAL` | removed (it appears on 2 of 2 pages) | 188| Page-number footer | `Page 1 of 2` | removed | 189| Word hyphenated across a line break | `all em-` / `ployees travelling` | `all employees travelling` | 190| Table flattened | `L1-L3 150 60 L4-L6 200 75` | kept as rows, then one sentence per row | 191 192The table is the dangerous one. Flattened, "200" floats free of its grade. 193`table_rows_as_sentences` turns each row into a self-contained sentence, 194`Grade L4-L6: hotel cap 200, meal cap 75.`, so any row can be retrieved on 195its own and still says what its numbers mean. 196 197```mermaid 198flowchart LR 199 RAW[Raw extracted text] --> H[Drop lines repeated<br/>on most pages] 200 H --> N[Drop page numbers] 201 N --> J[Rejoin hyphenated words,<br/>unwrap paragraphs] 202 J --> T{Table rows?} 203 T -->|yes| S[One sentence per row,<br/>headers repeated] 204 T -->|no| P[Paragraphs] 205 S --> OUT[Clean text for chunking] 206 P --> OUT 207``` 208 209**Reading it:** each box removes one kind of extraction damage. The diamond 210is the important decision: prose and tables need different handling, because 211a table's meaning lives in its columns. Real pipelines add layout-aware 212parsers and **OCR** (optical character recognition: reading text from an 213image of a page) for scanned documents, with a quality check on the output. 214 215**Why it matters.** Enterprise documents are scanned, multi-column, full of 216tables that span pages. If parsing garbles the numbers, no retriever or 217model can recover them, and the failure looks like a *model* error. 218 219**In code:** `extract_table` finds a table by its header row in the cleaned 220text and returns each row as a dict, ready for `table_rows_as_sentences`. 221 222## Chunking, with metadata that travels 223 224**Everyday picture.** Index cards. Each card holds one idea, small enough to 225match a question precisely, and in its corner a label: which document, 226which date, who may read it. 227 228**Worked example.** With a 15-word limit, `it-004` splits into two passages: 229 230| Passage id | Text | Updated | Readers | 231|---|---|---|---| 232| `it-004#0` | ERR-4012 means the VPN tunnel could not be established, usually because the client is out of date. | 2026-04-10 | everyone | 233| `it-004#1` | Update AnyConnect to version 5.1 or later and reboot. | 2026-04-10 | everyone | 234 235(The limit is tiny because the toy documents are tiny; real systems use a few 236hundred tokens.) Split on the document's structure (sentences, paragraphs, 237sections), not at fixed character counts that cut a sentence in half. 238`primer.ml.embeddings.retrieval` compares chunking strategies in depth. 239 240**Why it matters.** Small chunks match precisely but can lose context (the 241second card doesn't say *which* error it fixes; see contextual retrieval 242below). The metadata is what makes permission and date filters possible 243later. 244 245**In code:** `chunk_document` splits a document on sentence boundaries into 246`Passage`s, and each `Passage` carries its id, title, department, date and 247readers. 248 249## Retrieval: keyword and meaning, fused 250 251**Everyday picture.** Two librarians: one searches the catalogue for your 252exact words, the other understands what you *mean* even when you use 253different words. You take the books both of them rank highly. 254 255* **Keyword search (BM25)** scores passages by the question's words, 256 giving more weight to rare words and less to long passages. It nails 257 exact identifiers like `ERR-4012` and misses synonyms. 258* **Dense search** compares **embeddings** (vectors where closeness means 259 similar meaning; see `primer.ml.embeddings`). It finds "scam message in my 260 inbox" → the phishing guide with no shared words, but blurs exact codes. 261* **Hybrid search** runs both and merges the two rankings with **reciprocal 262 rank fusion (RRF)**, which only needs the ranks, never the scores. BM25 263 scores and cosine similarities live on different scales, so adding them 264 would be meaningless. 265 266$$ 267\text{RRF}(d) = \sum_{i} \frac{1}{k + \text{rank}_i(d)} 268$$ 269 270**Symbols** 271 272| Symbol | Meaning here | Worked example | 273|---|---|---| 274| $d$ | one passage | it-004#0 | 275| $i$ | one of the rankings being fused (keyword, dense) | 2 rankings | 276| $\text{rank}_i(d)$ | position of $d$ in ranking $i$ (1 = best); rankings that miss $d$ contribute nothing | 1st, 3rd | 277| $k$ | a damping constant; 60 is the usual choice | 60 | 278| $\sum_i$ | add up over the rankings | | 279 280**In words:** each ranking gives a passage a vote worth one over sixty-plus 281its position, and the votes are added. 282 283**On the worked example:** a passage ranked 1st by dense search and 3rd by 284keyword search scores 1/61 + 1/63 = 0.0323. A passage ranked 1st by one 285list and absent from the other scores only 1/61 = 0.0164. Passages that both 286methods agree on rise to the top. 287 288**In Python:** 289 290```python 291k = 60 292# 1st by dense, 3rd by keyword: Σ_i 1/(k + rank_i(d)) 293round(1 / (k + 1) + 1 / (k + 3), 4) # → 0.0323 294# 1st in one list, absent from the other 295round(1 / (k + 1), 4) # → 0.0164 296``` 297 298 299 300**Reading it:** the x-axis is how many passages you keep (k); the y-axis is 301**recall@k**, the share of the 12 labelled questions whose correct document 302is among those k. On this small set many questions reuse the documents' 303own words, so keyword search is already strong. Dense search plateaus at 30492% because it never finds `ERR-4012`. Hybrid reaches 100% by k = 2 but only 30575% at k = 1. Reranking the hybrid shortlist lifts the top-1 result to 92%. 306Run this measurement on *your* questions before choosing a method. 307 308$$ 309\text{recall@}k = \frac{1}{|Q|} \sum_{q \in Q} \mathbb{1}\bigl[\text{a relevant document is in the top } k \text{ for } q\bigr] 310$$ 311 312**Symbols** 313 314| Symbol | Meaning here | 315|---|---| 316| $Q$ | the labelled questions; $\lvert Q\rvert$ is how many (12 here) | 317| $q$ | one question | 318| $\mathbb{1}[\ldots]$ | 1 if true, 0 if not | 319 320**In words:** the share of questions for which the right document made it 321into the top k. 322 323**On the worked example:** dense search at k = 3 finds the right document for 32411 of 12 questions (all but `ERR-4012`): 11/12 = 0.92. 325 326**In Python:** 327 328```python 329# 𝟙[...] for each of the 12 questions; ERR-4012 is the 0 330found = [1] * 11 + [0] 331# (1/|Q|) Σ over q in Q 332round(sum(found) / len(found), 2) # → 0.92 333``` 334 335**In code:** `RAGIndex.retrieve` ranks the allowed passages with 336`primer.ml.embeddings.retrieval.BM25`, with dense similarity, or with both 337fused by `primer.ml.embeddings.retrieval.reciprocal_rank_fusion`, depending 338on the mode you ask for. `recall_curve` measures recall@k for each method. 339 340## Reranking: read the question and each passage together 341 342**Everyday picture.** The librarians bring back twenty books quickly; an 343expert then reads your question next to each book and picks the best three. 344 345A **reranker** (usually a **cross-encoder**: a model that reads the question 346and one passage *together* and outputs a relevance score) is far more 347precise than comparing precomputed vectors, and far too slow to run over 348every passage. So retrieval casts a wide, cheap net (here 8 candidates) and 349the reranker keeps the best few (here 3). This module reuses the toy 350cross-encoder from `primer.ml.embeddings.retrieval`. 351 352**In code:** `RAGIndex.rerank` scores each (question, passage) pair with 353`primer.ml.embeddings.retrieval.CrossEncoder` and keeps the best few. 354 355## Assemble, generate, cite, verify 356 357**Worked example.** "What does ERR-4012 mean?" becomes this context (each 358source escaped and tagged with its id; the question last; see 359`primer.agents.context`): 360 361```text 362<sources> 363<source id="it-004#1" title="Error ERR-4012: VPN tunnel failed" updated="2026-04-10">Update AnyConnect to version 5.1 or later and reboot.</source> 364<source id="it-004#0" title="Error ERR-4012: VPN tunnel failed" updated="2026-04-10">ERR-4012 means the VPN tunnel could not be established, usually because the client is out of date.</source> 365<source id="it-002#2" title="Password policy" updated="2025-11-20">This policy applies to all employees and contractors.</source> 366</sources> 367<question>What does ERR-4012 mean?</question> 368``` 369 370and the answer is *"ERR-4012 means the VPN tunnel could not be established, 371usually because the client is out of date. [it-004#0]"*. `verify_citations` 372then checks that every cited id was really in the context and that the 373cited passage supports the claim before it; a question the sources don't 374cover gets "I don't know based on the provided sources." 375 376```mermaid 377sequenceDiagram 378 participant U as User 379 participant A as RAG service 380 participant I as Index 381 participant M as Model 382 U->>A: What does ERR-4012 mean? 383 A->>I: hybrid search, filtered to what this user may read 384 I-->>A: 8 candidate passages 385 A->>A: rerank, keep 3 386 A->>M: rules + tagged sources + question 387 M-->>A: answer with [it-004#0] 388 A->>A: verify: id was in context, passage supports claim 389 A-->>U: answer + clickable citation 390``` 391 392**Reading it:** time runs downward. Note the order: the permission filter 393runs at the index, before any passage is fetched; the model only ever sees 394three passages; and nothing reaches the user until the citations check out. 395Citations are what let a person verify an answer in seconds, which is most 396of what makes people trust the system. 397 398**In code:** `assemble_context` builds the tagged sources and the question. 399`generate` sends them to the model with the answer-from-sources rules, and 400`grounded_policy` is the offline stand-in model that honours them. `answer` 401chains retrieve, rerank, assemble, generate and `verify_citations`. 402 403## Permission-aware retrieval: filter before, never after 404 405**Everyday picture.** A librarian checks your library card *before* 406fetching from the restricted archive. Checking it after you've read the 407document is pointless. 408 409Each passage carries its **access-control list** (ACL: the groups allowed to 410read it), copied from the source system (SharePoint, Google Drive, a wiki). 411`RAGIndex.retrieve` drops every passage the user can't read *before* 412ranking, so restricted text can't reach the context, the model, or the 413answer. 414 415**Worked example.** "What is the Q3 revenue forecast?" (the forecast 416document is readable only by `finance` and `exec`): 417 418| Who asks | How it's filtered | Answer | 419|---|---|---| 420| finance user | before retrieval | "Q3 revenue is forecast at 41 million dollars… [fin-006#0]" | 421| anyone else | before retrieval | "I don't know based on the provided sources." | 422| anyone else | **after** generation (citation removed) | "Q3 revenue is forecast at **41 million dollars**…" | 423 424```mermaid 425sequenceDiagram 426 participant U as Employee (not finance) 427 participant A as RAG service 428 participant M as Model 429 rect rgb(250, 225, 225) 430 Note over A,M: Wrong: filter after generation 431 A->>M: sources include the restricted forecast 432 M-->>A: "…41 million dollars [fin-006#0]" 433 A->>A: strip the restricted citation 434 A-->>U: "…41 million dollars" (leaked) 435 end 436 rect rgb(225, 240, 225) 437 Note over A,M: Right: filter before retrieval 438 A->>A: drop passages the user can't read 439 A->>M: sources without the forecast 440 M-->>A: "I don't know…" 441 A-->>U: nothing restricted 442 end 443``` 444 445**Reading it:** in the red box the model saw the restricted passage, so the 446number is already in its words, and deleting the citation marker afterwards 447leaves the fact behind. In the green box the passage never left the index. 448Permission changes in the source system must also sync to the index 449quickly, or a revoked user keeps access until the next re-index. 450 451**In code:** `post_generation_filter_answer` is the wrong way, kept so the 452leak can be shown: it retrieves for every group, generates, then strips the 453restricted citation markers. 454 455## Retrieval upgrades 456 457Each upgrade below is a working function, and each fixes a failure you can 458reproduce in `demo()`: 459 460| Upgrade | Everyday picture | Before → after (top 3) | 461|---|---|---| 462| **Query rewriting** (`rewrite_query`) | Repeating the earlier topic when you ask a follow-up | "what if it fails?" after a VPN question: printer guide → VPN setup and ERR-4012 | 463| **HyDE** (`hyde_search`) | Telling the librarian "I'm looking for a page that says something like…" | "a weird message asking for my bank details": nothing relevant → phishing guide first | 464| **Multi-query** (`multi_query_search`) | Asking three librarians in three different phrasings | "two step login setup": no MFA guide → MFA guide in top 3 | 465| **Metadata filter** (`updated_after`) | Ignoring the out-of-date binder on the shelf | superseded 2023 travel policy first → gone | 466| **Contextual retrieval** (`RAGIndex(contextual=True)`) | Writing the chapter title on every index card | "how do I fix ERR-4012": fix sentence missing → found | 467| **Parent-child** (`retrieve_parents`) | Find the sentence, hand over the whole page | a matching sentence → its full document | 468 469**HyDE** (Hypothetical Document Embeddings) deserves a picture, because it 470sounds backwards: you ask a model to *invent* an answer, then search with 471it. 472 473```mermaid 474flowchart LR 475 Q["Question:<br/>'weird message asking<br/>for my bank details'"] --> M[Model drafts a<br/>plausible answer] 476 M --> H["Draft: 'This sounds like a phishing<br/>email… report it in Outlook'"] 477 H --> E[Embed the draft] 478 E --> S[Dense search] 479 S --> R[Phishing guide, rank 1] 480``` 481 482**Reading it:** questions and answers are written differently. The user's 483words ("weird", "bank details") appear nowhere in the phishing guide, but 484the drafted answer uses the vocabulary answers use ("phishing", "report", 485"suspicious"), so its embedding lands next to the real passage. The draft 486may be wrong in its details; that's fine, because it's only used to search 487and is never shown to the user. 488 489**Contextual retrieval** fixes the "second index card" problem from the 490chunking section: before indexing, each passage gets a short line saying 491where it comes from. Here that's just the title and department; Anthropic's 492version asks a model to write one sentence situating the chunk in its 493document. 494 495 496 497**Reading it:** three ways of asking how to fix ERR-4012; each pair of bars 498is the rank of the passage "Update AnyConnect to version 5.1 or later and 499reboot." (shorter is better, and 21 means not in the top 20). Without 500context the passage never mentions ERR-4012, and for all three phrasings it 501doesn't make the top 20 at all. With the title prefixed it ranks 2nd, 2nd 502and 4th: in the top five every time, though "resolve ERR-4012 on my 503laptop" still ranks three passages from the laptop guide above it. A context line turns 504"never found" into "found", and ranking the right passage first is then 505the reranker's job. 506 507## Agentic RAG: let the model decide when and what to search 508 509**Everyday picture.** A researcher rather than a librarian: reads the 510question, decides what to look up, reads the results, and searches again if 511something's missing. 512 513Plain RAG searches exactly once, with the user's words. In **agentic RAG** 514search is a tool the model calls: zero times for small talk, several times 515for a multi-part question, with its own reformulated queries. 516 517**Worked example.** "What is the per-diem for meals and how do I upload 518expense receipts?" produces two searches ("What is the per-diem for meals", 519"how do I upload expense receipts") and an answer citing both `fin-002#2` 520and `fin-004#0`. "thanks, that's all!" produces no search at all. 521 522```mermaid 523sequenceDiagram 524 participant U as User 525 participant M as Model 526 participant S as search_kb tool 527 U->>M: per-diem for meals AND how to upload receipts? 528 M->>S: search_kb("per-diem for meals") 529 S-->>M: fin-002 passages 530 M->>S: search_kb("how do I upload expense receipts") 531 S-->>M: fin-004 passages 532 M-->>U: both answers, each with its citation 533``` 534 535**Reading it:** the model, not a fixed pipeline, decides how many searches 536to run and with which words. That handles multi-part and vague questions 537better, at the cost of more model calls, more latency, and a loop that needs 538the usual step budget (`primer.agents.agent_loop`). The search tool here also 539applies the freshness filter itself, so the agent can't forget it. 540 541**In code:** `agentic_answer` offers the model one search tool and runs the 542loop: each search retrieves, reranks and returns tagged passages, until the 543model answers or the step limit is hit. 544 545## GraphRAG: questions about connections 546 547**Everyday picture.** A detective's corkboard: photos of people and places 548joined by string, each string labelled with the note that established it. 549 550Some questions aren't answered by any single passage: "what depends on 551two-factor authentication?" or "what are the main themes across these 552contracts?". **GraphRAG** first extracts **entities** (named things: 553systems, people, products) and the relationships between them into a graph, 554then answers by walking it, or by summarizing groups of connected entities. 555`build_graph` does the smallest honest version: two entities are linked when 556one sentence mentions both, and each link remembers which document said so. 557 558```mermaid 559flowchart LR 560 TF((two-factor)) ---|it-006| VPN((VPN)) 561 TF ---|it-006| EM((email)) 562 TF ---|it-006| AA((authenticator app)) 563 TF ---|it-003| AC((AnyConnect)) 564 TF ---|it-003| SC((software center)) 565 TF ---|hr-003| LT((laptop)) 566 AC ---|it-003| SC 567 VPN ---|it-006| EM 568 AA ---|it-001| SSP((self-service portal)) 569``` 570 571**Reading it:** each circle is an entity found in the knowledge base; each 572line is a sentence that mentioned both ends, labelled with its source 573document. "What depends on two-factor?" is answered by reading the 574neighbours of one circle, with citations for free. Real GraphRAG uses a 575model to extract typed relations ("requires", "replaces") and to write a 576summary for each cluster, which is what makes broad, whole-collection 577questions answerable. 578 579**In code:** `communities` groups the graph from `build_graph` into 580connected clusters of entities, the "themes" a real GraphRAG system would 581summarize. 582 583## Debugging a confident wrong answer 584 585**Everyday picture.** A student gets an exam question wrong. Either the 586librarian brought the wrong book, or the student misread the right one. The 587fixes are completely different, so find out which before changing anything. 588 589**Worked example.** `debug_wrong_answers` runs the 12 labelled questions and 590classifies each: **retrieval miss** (no relevant document in the top 3: no 591prompt can fix it), **generation miss** (the right document was there but the 592answer didn't use it), or ok. With dense-only retrieval, "what does ERR-4012 593mean" is a retrieval miss and recall@3 is 0.92; switching to hybrid fixes it 594(recall@3 = 1.00). What's left are generation misses. One of them, 595"per-diem for meals when traveling", is answered from the superseded 2023 596policy: a *data* problem that a date filter fixes. The other, "enroll in 597MFA", is a limit of this lesson's stand-in model rather than of RAG: it 598matches words literally, so "enroll" misses the passage's "enrolling", and 599with only "MFA" in common it declines to answer. A real model would read 600it-006 and answer. 601 602```mermaid 603flowchart TD 604 W[Confident wrong answer] --> R{Right passage in<br/>the top k?} 605 R -->|no| P{Is it in the<br/>index at all?} 606 P -->|no| FIXI[Fix ingestion:<br/>parsing, chunking, permissions sync] 607 P -->|yes| FIXR[Fix retrieval:<br/>hybrid, rerank, rewrite, HyDE, filters] 608 R -->|yes| C{Was it in the<br/>final context?} 609 C -->|no| FIXC[Fix assembly:<br/>reranker, budget, top_n] 610 C -->|yes| FIXG[Fix generation:<br/>instructions, citations, stale sources] 611``` 612 613**Reading it:** start at the top and answer each question with a 614measurement, not a guess. Most teams jump straight to the bottom-right box 615and edit the prompt; the diagram says to rule out the three earlier failure 616points first, because they're more common and a prompt can't fix them. 617 618 619 620**Reading it:** each bar is one retrieval method over the 12 labelled 621questions, split into ok (green), generation misses (orange) and retrieval 622misses (red). Dense search has a retrieval miss (the error code); hybrid 623removes it. The orange that remains is where to look next, and it's not 624retrieval. 625 626## In 20 seconds 627- RAG retrieves relevant passages at question time and has the model answer 628 from them with citations: knowledge that changes or must be cited, with no 629 retraining. 630- Quality is decided early: parsing (tables!), chunking with metadata, and 631 hybrid retrieval with reranking. 632- Filter by permissions before retrieval, never after generation. 633- Upgrades: query rewriting, HyDE, multi-query, date filters, contextual 634 retrieval, parent-child; agentic RAG for multi-part questions; GraphRAG 635 for questions about connections. 636- Debug by measuring retrieval (recall@k) first, then generation. 637 638## Self-test questions 639 640**Your RAG system gives confident wrong answers. Debug it step by step.** 641Take the failing questions (and build a labelled set if you don't have one). 642First, is the right passage in the index at all? If not, it's ingestion: 643parsing, chunking or permission sync. Second, is it in the top k? Measure 644recall@k; if not, fix retrieval: hybrid search, a reranker, query rewriting 645or HyDE, metadata filters, contextual chunks, domain-tuned embeddings. 646Third, did it survive into the final context? If not, fix reranking or the 647context budget. Only then look at generation: instructions to answer only 648from sources and to decline otherwise, citation checks, stale or 649contradictory sources. Add every case to the golden set. 650 651**Why does hybrid search beat pure vector search on enterprise data?** 652Enterprise questions are full of exact identifiers (error codes, product 653names, ticket numbers) that embeddings blur, and full of paraphrases that 654keyword search misses. Hybrid gets both, and RRF merges the rankings without 655having to reconcile incompatible score scales. 656 657**How do you make RAG respect document permissions?** 658Copy each document's access-control list onto every chunk at ingestion, 659filter candidates by the user's groups before ranking, and sync permission 660changes from the source system promptly. Never filter after generation: the 661model has already used the restricted text. 662 663**When would you use agentic RAG instead of a single retrieval step?** 664For multi-part or vague questions, and when the model needs to judge whether 665results are good enough and search again. It costs more calls and latency, 666so keep single-shot retrieval for simple lookups. 667 668**RAG or fine-tuning for a company knowledge assistant?** 669RAG for knowledge: it updates by re-indexing, cites sources, and respects 670permissions. Fine-tuning teaches behaviour and format, not facts that 671change. Most systems are RAG plus a good prompt (see 672`primer.ml.training_stages`). 673 674## The papers behind this lesson 675 676- Lewis et al., *Retrieval-Augmented Generation for Knowledge-Intensive NLP 677 Tasks* (2020), https://arxiv.org/abs/2005.11401. Coined the term and 678 showed that pairing a generator with a retriever over a document index 679 beats a model relying on its weights alone for knowledge-heavy questions. 680 [annotated companion](../../papers/rag.html) 681- Gao, Ma, Lin & Callan, *Precise Zero-Shot Dense Retrieval without 682 Relevance Labels* (2022), https://arxiv.org/abs/2212.10496. Introduced 683 HyDE: search with an embedding of a model-written hypothetical answer. 684 [annotated companion](../../papers/hyde.html) 685- Edge et al., *From Local to Global: A Graph RAG Approach to Query-Focused 686 Summarization* (2024), https://arxiv.org/abs/2404.16130. Builds an entity 687 graph and community summaries so that whole-collection questions can be 688 answered. 689 690## Further reading 691- Anthropic, *Introducing Contextual Retrieval*: https://www.anthropic.com/news/contextual-retrieval 692- Anthropic citations docs: https://docs.claude.com/en/docs/build-with-claude/citations 693- Microsoft GraphRAG documentation: https://microsoft.github.io/graphrag/ 694- RAGAS documentation (RAG evaluation): https://docs.ragas.io/ 695- The retrieval lesson in this repo, with BM25, RRF, cross-encoders and chunking in depth: `primer.ml.embeddings.retrieval` 696""" 697 698from __future__ import annotations 699 700import re 701from dataclasses import dataclass, field 702from typing import Any 703 704import numpy as np 705 706from primer._show import banner, say, table, takeaway 707from primer.agents.context import xml_wrap 708from primer.agents.guardrails import claim_support 709from primer.agents.llm import ScriptedLLM, ToolCall, last_user_text, tool_result_block, tool_results 710from primer.common.corpus import DOCS, DOCS_BY_ID, LABELED_QUERIES, Doc 711from primer.common.embedder import ConceptEmbedder 712from primer.common.text import tokenize 713from primer.ml.embeddings.retrieval import BM25, CrossEncoder, ideas, reciprocal_rank_fusion 714 715# =========================================================================== 716# 1. INGESTION: parse, chunk, index 717# =========================================================================== 718 719# What a PDF looks like after naive text extraction: a header and footer on 720# every page, words hyphenated across line breaks, and a table whose columns 721# survive only as runs of spaces. 722MESSY_PDF = ( 723 "Northwind Ltd Travel Policy 2026 CONFIDENTIAL\n" 724 "Hotel and meal limits apply to all em-\n" 725 "ployees travelling on company busi-\n" 726 "ness. Book through the travel portal.\n" 727 "Grade Hotel cap Meal cap\n" 728 "L1-L3 150 60\n" 729 "L4-L6 200 75\n" 730 "Page 1 of 2\n" 731 "\f" 732 "Northwind Ltd Travel Policy 2026 CONFIDENTIAL\n" 733 "Economy class is required for flights un-\n" 734 "der six hours.\n" 735 "Page 2 of 2\n" 736) 737 738_PAGE_NUMBER = re.compile(r"^page \d+ of \d+$", re.I) 739_COLUMNS = re.compile(r"\s{2,}") # two or more spaces separate table columns 740 741 742def clean_extracted_text(raw: str) -> str: 743 """Repair the usual damage of PDF text extraction. 744 745 1. Drop lines repeated on two or more pages (running headers/footers). 746 2. Drop "Page n of m" footers. 747 3. Rejoin words hyphenated across line breaks ("em-" + "ployees"). 748 4. Unwrap prose lines into paragraphs; keep table rows on their own lines. 749 """ 750 pages = [p.strip("\n").split("\n") for p in raw.split("\f")] 751 seen_on: dict[str, int] = {} 752 for lines in pages: 753 for line in set(l.strip() for l in lines): 754 seen_on[line] = seen_on.get(line, 0) + 1 755 kept = [l.strip() for lines in pages for l in lines 756 if l.strip() and seen_on[l.strip()] < 2 and not _PAGE_NUMBER.match(l.strip())] 757 758 out: list[str] = [] 759 for line in kept: 760 is_table_row = len(_COLUMNS.split(line)) > 1 761 if out and not is_table_row and not out[-1].endswith("\n"): 762 prev = out.pop() 763 if prev.endswith("-") and line[:1].islower(): 764 out.append(prev[:-1] + line) # hyphenated word: join with no space 765 else: 766 out.append(prev + " " + line) 767 else: 768 out.append(line + ("\n" if is_table_row else "")) 769 return "\n".join(s.rstrip("\n") for s in out) 770 771 772def extract_table(raw: str, header: list[str]) -> list[dict[str, str]]: 773 """Find the table whose header row matches `header` and return its rows as dicts.""" 774 lines = [l.strip() for l in raw.split("\n")] 775 for i, line in enumerate(lines): 776 if _COLUMNS.split(line) == header: 777 rows = [] 778 for row in lines[i + 1 :]: 779 cells = _COLUMNS.split(row) 780 if len(cells) != len(header): 781 break 782 rows.append(dict(zip(header, cells))) 783 return rows 784 return [] 785 786 787def table_rows_as_sentences(rows: list[dict[str, str]]) -> list[str]: 788 """One self-contained sentence per row, so each row can be retrieved on its own.""" 789 out = [] 790 for row in rows: 791 key, *rest = list(row) 792 out.append(f"{key} {row[key]}: " + ", ".join(f"{h.lower()} {row[h]}" for h in rest) + ".") 793 return out 794 795 796@dataclass(frozen=True) 797class Passage: 798 """A retrievable piece of a document, with the metadata filters need.""" 799 800 id: str # "<doc id>#<position>" 801 doc_id: str 802 title: str 803 text: str 804 department: str 805 updated: str 806 acl: frozenset[str] 807 index_text: str = "" # what BM25 and the embedder actually see 808 809 810def _sentences(text: str) -> list[str]: 811 return [s for s in re.split(r"(?<=[.!?])\s+", text.strip()) if s] 812 813 814def chunk_document(doc: Doc, max_words: int = 15, contextual: bool = False) -> list[Passage]: 815 """Split a document on sentence boundaries into passages of at most ~max_words words. 816 817 With `contextual=True`, each passage is indexed with a short line saying 818 where it comes from (title and department), so a sentence like "Update 819 AnyConnect and reboot" still says which error it fixes. 820 """ 821 groups: list[list[str]] = [] 822 for s in _sentences(doc.text): 823 if groups and len(" ".join(groups[-1] + [s]).split()) <= max_words: 824 groups[-1].append(s) 825 else: 826 groups.append([s]) 827 out = [] 828 for i, g in enumerate(groups): 829 text = " ".join(g) 830 prefix = f"{doc.title} ({doc.department}): " if contextual else "" 831 out.append(Passage(f"{doc.id}#{i}", doc.id, doc.title, text, doc.department, doc.updated, doc.acl, prefix + text)) 832 return out 833 834 835ALL_GROUPS = frozenset(g for d in DOCS for g in d.acl) 836 837 838class RAGIndex: 839 """Passages from every document, indexed for keyword (BM25) and dense search.""" 840 841 def __init__(self, docs: list[Doc] = DOCS, contextual: bool = False, embedder: ConceptEmbedder | None = None, max_words: int = 15): 842 self.passages = [p for d in docs for p in chunk_document(d, max_words, contextual)] 843 self.by_id = {p.id: p for p in self.passages} 844 self.embedder = embedder or ConceptEmbedder() 845 self.bm25 = BM25([tokenize(p.index_text) for p in self.passages]) 846 self.vectors = self.embedder.encode([p.index_text for p in self.passages]) # (n_passages, dim), unit rows 847 self.reranker = CrossEncoder(self.embedder) 848 849 def retrieve(self, query: str, user_groups: set[str], k: int = 5, mode: str = "hybrid", 850 updated_after: str | None = None, depth: int = 10) -> list[Passage]: 851 """Top-k passages the user may see, ranked by BM25, dense, or both fused. 852 853 The permission and date filters run FIRST, on the candidate set, 854 before anything is ranked, so restricted text can't leak into the 855 results, the context, or the answer. 856 """ 857 allowed = [i for i, p in enumerate(self.passages) 858 if p.acl & set(user_groups) and (updated_after is None or p.updated >= updated_after)] 859 rankings = [] 860 if mode in ("bm25", "hybrid"): 861 s = self.bm25.scores(tokenize(query)) 862 rankings.append([self.passages[i].id for i in sorted(allowed, key=lambda i: -s[i]) if s[i] > 0][:depth]) 863 if mode in ("dense", "hybrid"): 864 sims = self.vectors @ self.embedder.encode(query) 865 rankings.append([self.passages[i].id for i in sorted(allowed, key=lambda i: -sims[i])][:depth]) 866 fused = rankings[0] if len(rankings) == 1 else [pid for pid, _ in reciprocal_rank_fusion(rankings)] 867 return [self.by_id[pid] for pid in fused[:k]] 868 869 def rerank(self, query: str, passages: list[Passage], top_n: int = 3) -> list[Passage]: 870 """Second stage: score each (question, passage) pair together; keep the best few.""" 871 as_docs = {p.id: Doc(p.id, p.title, p.text, p.department, p.updated, p.acl) for p in passages} 872 return sorted(passages, key=lambda p: -self.reranker.score(query, as_docs[p.id]))[:top_n] 873 874 def retrieve_parents(self, query: str, user_groups: set[str], k: int = 3) -> list[Doc]: 875 """Search small passages (precise matches), return their whole documents (full context).""" 876 seen: list[str] = [] 877 for p in self.retrieve(query, user_groups, k=k * 4): 878 if p.doc_id not in seen: 879 seen.append(p.doc_id) 880 return [DOCS_BY_ID[d] for d in seen[:k]] 881 882 883# =========================================================================== 884# 2. QUERY TIME: assemble context, generate, verify 885# =========================================================================== 886 887SYSTEM = ("Answer only from the sources. Cite the id of each source you use in square brackets. " 888 "If the sources don't contain the answer, say you don't know.") 889DONT_KNOW = "I don't know based on the provided sources." 890 891 892def assemble_context(question: str, passages: list[Passage]) -> str: 893 """Sources in escaped, id-tagged blocks; the question last (see primer.agents.context).""" 894 sources = "\n".join(xml_wrap("source", p.text, id=p.id, title=p.title, updated=p.updated) for p in passages) 895 return f"<sources>\n{sources}\n</sources>\n<question>{question}</question>" 896 897 898def _overlap(question: str, sentence: str) -> int: 899 """Shared ideas between question and sentence; identifiers (with digits) count double.""" 900 shared = set(ideas(question)) & set(ideas(sentence)) 901 return sum(2 if any(c.isdigit() for c in i) else 1 for i in shared) 902 903 904def grounded_policy(system: str, messages: list[dict], tools: list[dict] | None) -> str: # noqa: ARG001 905 """Offline stand-in for a model that answers only from tagged sources, with citations. 906 907 It picks the source sentence sharing the most ideas with the question 908 and cites it; if nothing shares at least two, it declines. A real model 909 writes more fluent answers, but the contract (answer from sources, cite, 910 or decline) is the same one you'd put in its system prompt. 911 """ 912 text = last_user_text(messages) 913 question = re.search(r"<question>(.*?)</question>", text, re.S).group(1) 914 best, best_score = None, 0 915 for sid, body in re.findall(r'<source id="([^"]+)"[^>]*>(.*?)</source>', text, re.S): 916 for sentence in _sentences(body): 917 score = _overlap(question, sentence) 918 if score > best_score: 919 best, best_score = (sentence, sid), score 920 if best is None or best_score < 2: 921 return DONT_KNOW 922 return f"{best[0]} [{best[1]}]" 923 924 925def generate(question: str, passages: list[Passage], llm: Any = None) -> str: 926 llm = llm or ScriptedLLM(grounded_policy) 927 reply = llm.complete(system=SYSTEM, messages=[{"role": "user", "content": assemble_context(question, passages)}]) 928 return reply.text 929 930 931_CITATION = re.compile(r"\[([\w-]+#\d+)\]") 932_CLAIM_THEN_CITATION = re.compile(r"([^\[\]]+?)\s*\[([\w-]+#\d+)\]") 933 934 935def verify_citations(answer_text: str, passages: list[Passage]) -> dict[str, list[str]]: 936 """Check that every cited id was actually in the context and supports its sentence.""" 937 by_id = {p.id: p for p in passages} 938 cited = _CITATION.findall(answer_text) 939 unknown = [c for c in cited if c not in by_id] 940 unsupported = [] 941 # Each citation vouches for the text between the previous citation and itself. 942 for claim, c in _CLAIM_THEN_CITATION.findall(answer_text): 943 claim = claim.strip(" .") 944 if c in by_id and claim_support(claim, [by_id[c].text]) < 0.6: 945 unsupported.append(claim) 946 return {"cited": cited, "unknown_ids": unknown, "unsupported": unsupported} 947 948 949@dataclass 950class RAGResult: 951 answer: str 952 passages: list[Passage] 953 context: str 954 citations: dict[str, list[str]] = field(default_factory=dict) 955 956 957def answer(index: RAGIndex, question: str, user_groups: set[str], k: int = 8, top_n: int = 3, llm: Any = None) -> RAGResult: 958 """The whole query-time pipeline: retrieve (filtered) -> rerank -> assemble -> generate -> verify.""" 959 candidates = index.retrieve(question, user_groups, k=k) 960 passages = index.rerank(question, candidates, top_n) if candidates else [] 961 text = generate(question, passages, llm) 962 return RAGResult(text, passages, assemble_context(question, passages), verify_citations(text, passages)) 963 964 965def post_generation_filter_answer(index: RAGIndex, question: str, user_groups: set[str]) -> str: 966 """The WRONG way: retrieve everything, generate, then strip restricted citations. 967 968 The citation markers go; the restricted facts the model already wrote stay. 969 """ 970 result = answer(index, question, set(ALL_GROUPS)) 971 allowed = {p.id for p in index.passages if p.acl & set(user_groups)} 972 return _CITATION.sub(lambda m: m.group(0) if m.group(1) in allowed else "", result.answer).strip() 973 974 975# =========================================================================== 976# 3. RETRIEVAL UPGRADES 977# =========================================================================== 978 979_REFERRING = re.compile(r"\b(it|that|this|they|those|them|what about|and for)\b", re.I) 980 981 982def rewrite_query(question: str, history: list[str], llm: Any = None) -> str: 983 """Turn a follow-up into a standalone search query. 984 985 Deterministic stand-in: if the follow-up leans on earlier context ("it", 986 "that", "what about"), append the content words of the previous user 987 turn. In production a small model does this with an instruction like 988 "rewrite the last question so it can be understood without the chat". 989 """ 990 if llm is not None: 991 prompt = "Rewrite the last question as a standalone search query.\n" + "\n".join(history + [question]) 992 return llm.complete(system="", messages=[{"role": "user", "content": prompt}]).text 993 if not history or not _REFERRING.search(question): 994 return question 995 extra = [t for t in tokenize(history[-1]) if t not in tokenize(question)] 996 return f"{question} {' '.join(extra)}" 997 998 999# What a model might write as a hypothetical answer. HyDE only uses the draft 1000# to *search*; its details may be wrong, and it's never shown to the user. 1001HYDE_DRAFTS = { 1002 "I got a weird message asking for my bank details": 1003 "This sounds like a phishing email. Don't click links; report the suspicious email with the Report phishing button in Outlook.", 1004 "why can't my computer reach the office network from home?": 1005 "Remote access to internal systems needs the VPN. Install AnyConnect, sign in, and connect from home.", 1006} 1007 1008 1009def _draft_policy(system, messages, tools): # noqa: ARG001 1010 q = last_user_text(messages) 1011 return HYDE_DRAFTS.get(q, q) 1012 1013 1014def hyde_search(index: RAGIndex, question: str, user_groups: set[str], k: int = 5, llm: Any = None) -> list[Passage]: 1015 """Hypothetical Document Embeddings: search with a drafted answer instead of the question. 1016 1017 Answers look like documents; questions don't. Embedding a plausible 1018 answer lands closer to the real passage than embedding the question. 1019 """ 1020 llm = llm or ScriptedLLM(_draft_policy) 1021 draft = llm.complete(system="Write a short passage that answers the question.", 1022 messages=[{"role": "user", "content": question}]).text 1023 return index.retrieve(draft, user_groups, k=k, mode="dense") 1024 1025 1026# Alternative phrasings a model might write for multi-query retrieval. 1027MULTI_QUERY_DRAFTS = { 1028 "two step login setup": ["two-factor authentication setup", "MFA enrollment authenticator app QR code"], 1029} 1030 1031 1032def _phrasings_policy(system, messages, tools): # noqa: ARG001 1033 q = last_user_text(messages) 1034 return "\n".join(MULTI_QUERY_DRAFTS.get(q, [])) 1035 1036 1037def multi_query_search(index: RAGIndex, question: str, user_groups: set[str], k: int = 5, llm: Any = None) -> list[Passage]: 1038 """Search several phrasings of the question and fuse the rankings with RRF.""" 1039 llm = llm or ScriptedLLM(_phrasings_policy) 1040 reply = llm.complete(system="Write two alternative search queries, one per line.", messages=[{"role": "user", "content": question}]) 1041 phrasings = [question] + [l for l in reply.text.split("\n") if l.strip()] 1042 rankings = [[p.id for p in index.retrieve(q, user_groups, k=10)] for q in phrasings] 1043 return [index.by_id[pid] for pid, _ in reciprocal_rank_fusion(rankings)[:k]] 1044 1045 1046# =========================================================================== 1047# 4. AGENTIC RAG: the model decides whether and what to search 1048# =========================================================================== 1049 1050SEARCH_TOOL = {"name": "search_kb", "description": "Search the company knowledge base. Returns passages with ids.", 1051 "input_schema": {"type": "object", "properties": {"query": {"type": "string"}}, "required": ["query"]}} 1052_SMALL_TALK = re.compile(r"^\s*(thanks|thank you|hi|hello|ok|great|bye)\b", re.I) 1053 1054 1055def _agentic_policy(system, messages, tools): # noqa: ARG001 1056 """Split multi-part questions, search once per part, then answer every part with citations.""" 1057 question = last_user_text(messages) 1058 if _SMALL_TALK.match(question): 1059 return "You're welcome!" 1060 parts = [p.strip(" ?") for p in re.split(r"\band\b", question) if len(tokenize(p)) >= 2] 1061 done = tool_results(messages) 1062 if len(done) < len(parts): 1063 return ToolCall("", "search_kb", {"query": parts[len(done)]}) 1064 answers = [] 1065 for part, result in zip(parts, done): 1066 sub = grounded_policy("", [{"role": "user", "content": f"{result['content']}\n<question>{part}</question>"}], None) 1067 answers.append(sub) 1068 return " ".join(answers) 1069 1070 1071def agentic_answer(index: RAGIndex, question: str, user_groups: set[str], max_steps: int = 6, llm: Any = None) -> dict[str, Any]: 1072 llm = llm or ScriptedLLM(_agentic_policy) 1073 messages: list[dict] = [{"role": "user", "content": question}] 1074 searches: list[str] = [] 1075 reply = None 1076 for _ in range(max_steps): 1077 reply = llm.complete(system=SYSTEM, messages=messages, tools=[SEARCH_TOOL]) 1078 messages.append({"role": "assistant", "content": reply.assistant_content}) 1079 if reply.stop_reason != "tool_use": 1080 break 1081 results = [] 1082 for call in reply.tool_calls: 1083 q = call.input["query"] 1084 searches.append(q) 1085 # The tool applies the freshness filter, so superseded policies never come back. 1086 hits = index.rerank(q, index.retrieve(q, user_groups, k=8, updated_after="2024-01-01"), top_n=3) 1087 body = "<sources>" + "".join(xml_wrap("source", p.text, id=p.id) for p in hits) + "</sources>" 1088 results.append(tool_result_block(call.id, body)) 1089 messages.append({"role": "user", "content": results}) 1090 return {"answer": reply.text if reply else "", "searches": searches} 1091 1092 1093# =========================================================================== 1094# 5. GRAPHRAG, in miniature 1095# =========================================================================== 1096 1097ENTITIES: dict[str, str] = { 1098 "two-factor": r"two-factor|\bmfa\b", 1099 "VPN": r"\bvpn\b", 1100 "AnyConnect": r"anyconnect", 1101 "software center": r"software center", 1102 "authenticator app": r"authenticator app", 1103 "email": r"\bemails?\b", 1104 "Outlook": r"outlook", 1105 "travel portal": r"travel portal", 1106 "HR portal": r"hr portal", 1107 "IT portal": r"it portal", 1108 "expense tool": r"expense tool", 1109 "self-service portal": r"self-service portal", 1110 "payroll": r"payroll", 1111 "laptop": r"\blaptops?\b", 1112} 1113 1114 1115def build_graph(docs: list[Doc] = DOCS) -> dict[str, dict[str, set[str]]]: 1116 """Entity graph: two entities are linked when a sentence mentions both. 1117 1118 Each link remembers which documents stated it, so answers drawn from the 1119 graph can still cite sources. Real GraphRAG uses a model to extract 1120 entities and typed relations ("requires", "replaces") and then 1121 summarizes communities of related entities. 1122 """ 1123 graph: dict[str, dict[str, set[str]]] = {} 1124 for d in docs: 1125 for sentence in _sentences(f"{d.title}. {d.text}"): 1126 found = sorted(name for name, pat in ENTITIES.items() if re.search(pat, sentence, re.I)) 1127 for a in found: 1128 for b in found: 1129 if a != b: 1130 graph.setdefault(a, {}).setdefault(b, set()).add(d.id) 1131 return graph 1132 1133 1134def communities(graph: dict[str, dict[str, set[str]]]) -> list[set[str]]: 1135 """Connected groups of entities: the "themes" GraphRAG summarizes.""" 1136 seen: set[str] = set() 1137 groups = [] 1138 for start in graph: 1139 if start in seen: 1140 continue 1141 stack, comp = [start], set() 1142 while stack: 1143 n = stack.pop() 1144 if n not in comp: 1145 comp.add(n) 1146 stack.extend(graph.get(n, {})) 1147 seen |= comp 1148 groups.append(comp) 1149 return sorted(groups, key=len, reverse=True) 1150 1151 1152# =========================================================================== 1153# 6. DEBUGGING a confident wrong answer 1154# =========================================================================== 1155 1156 1157def debug_wrong_answers(index: RAGIndex, mode: str = "hybrid", k: int = 3, queries: list[tuple[str, set[str]]] = LABELED_QUERIES) -> dict[str, Any]: 1158 """Separate retrieval failures from generation failures on a labelled set. 1159 1160 For each question: if no relevant document is in the top k, it's a 1161 retrieval miss (no prompt change can fix it). If one is there but the 1162 answer doesn't cite it, it's a generation miss. 1163 """ 1164 by_query: dict[str, str] = {} 1165 for q, relevant in queries: 1166 passages = index.retrieve(q, set(ALL_GROUPS), k=k, mode=mode) 1167 if not relevant & {p.doc_id for p in passages}: 1168 by_query[q] = "retrieval miss" 1169 continue 1170 text = generate(q, passages) 1171 cited_docs = {c.split("#")[0] for c in _CITATION.findall(text)} 1172 by_query[q] = "ok" if cited_docs & relevant else "generation miss" 1173 misses = sum(v == "retrieval miss" for v in by_query.values()) 1174 return {"by_query": by_query, "recall_at_k": 1 - misses / len(queries)} 1175 1176 1177def recall_curve(index: RAGIndex, mode: str, ks: list[int], rerank: bool = False, 1178 queries: list[tuple[str, set[str]]] = LABELED_QUERIES) -> list[float]: 1179 """recall@k for each k: share of questions with a relevant document in the top k.""" 1180 out = [] 1181 for k in ks: 1182 hits = 0 1183 for q, relevant in queries: 1184 if rerank: 1185 passages = index.rerank(q, index.retrieve(q, set(ALL_GROUPS), k=10, mode=mode), top_n=k) 1186 else: 1187 passages = index.retrieve(q, set(ALL_GROUPS), k=k, mode=mode) 1188 hits += bool(relevant & {p.doc_id for p in passages}) 1189 out.append(hits / len(queries)) 1190 return out 1191 1192 1193# =========================================================================== 1194# Figures and demo 1195# =========================================================================== 1196 1197 1198def figures() -> dict[str, Any]: 1199 import matplotlib 1200 1201 matplotlib.use("Agg") 1202 import matplotlib.pyplot as plt 1203 1204 figs: dict[str, Any] = {} 1205 index = RAGIndex() 1206 ks = [1, 2, 3, 4, 5] 1207 fig, ax = plt.subplots(figsize=(6.5, 3.6)) 1208 for label, mode, rr, color in [("keyword (BM25)", "bm25", False, "#dd8452"), ("dense", "dense", False, "#8172b2"), 1209 ("hybrid (RRF)", "hybrid", False, "#4c72b0"), ("hybrid + rerank", "hybrid", True, "#55a868")]: 1210 ax.plot(ks, recall_curve(index, mode, ks, rr), "o-", label=label, color=color) 1211 ax.set_xticks(ks) 1212 ax.set_xlabel("k (passages kept)") 1213 ax.set_ylabel("recall@k on the labelled questions") 1214 ax.set_ylim(0, 1.05) 1215 ax.set_title("Which retrieval finds the answer?") 1216 ax.legend(fontsize=8, loc="lower right") 1217 fig.tight_layout() 1218 figs["recall"] = fig 1219 1220 fig, ax = plt.subplots(figsize=(6.5, 3.2)) 1221 kinds = ["ok", "generation miss", "retrieval miss"] 1222 colors = {"ok": "#55a868", "generation miss": "#dd8452", "retrieval miss": "#c44e52"} 1223 modes = ["bm25", "dense", "hybrid"] 1224 left = np.zeros(len(modes)) 1225 for kind in kinds: 1226 counts = np.array([list(debug_wrong_answers(index, m)["by_query"].values()).count(kind) for m in modes]) 1227 ax.barh(modes, counts, left=left, color=colors[kind], label=kind) 1228 left += counts 1229 ax.set_xlabel("labelled questions (top 3 passages)") 1230 ax.set_title("Where do wrong answers come from?") 1231 ax.legend(fontsize=8, loc="lower right") 1232 fig.tight_layout() 1233 figs["diagnosis"] = fig 1234 1235 plain, ctx = RAGIndex(), RAGIndex(contextual=True) 1236 fix = "Update AnyConnect to version 5.1 or later and reboot." 1237 qs = ["how do I fix ERR-4012", "ERR-4012 what should I do", "resolve ERR-4012 on my laptop"] 1238 1239 def rank_of(idx, q): 1240 ids = [p.text for p in idx.retrieve(q, {"everyone"}, k=20)] 1241 return ids.index(fix) + 1 if fix in ids else 21 1242 1243 fig, ax = plt.subplots(figsize=(6.5, 3)) 1244 y = np.arange(len(qs)) 1245 ax.barh(y - 0.2, [rank_of(plain, q) for q in qs], 0.4, color="#c44e52", label="plain chunks") 1246 ax.barh(y + 0.2, [rank_of(ctx, q) for q in qs], 0.4, color="#4c72b0", label="chunks with a context line") 1247 ax.set_yticks(y, qs) 1248 ax.invert_yaxis() 1249 ax.set_xlabel("rank of the passage containing the fix (lower is better; 21 = not in top 20)") 1250 ax.set_title("Contextual retrieval") 1251 ax.legend(fontsize=8) 1252 fig.tight_layout() 1253 figs["contextual"] = fig 1254 return figs 1255 1256 1257def demo() -> None: 1258 index = RAGIndex() 1259 banner("1. Parsing: repair the extraction before anything else") 1260 print(clean_extracted_text(MESSY_PDF)) 1261 print() 1262 for s in table_rows_as_sentences(extract_table(MESSY_PDF, ["Grade", "Hotel cap", "Meal cap"])): 1263 print("row ->", s) 1264 print() 1265 1266 banner("2. The pipeline, end to end") 1267 r = answer(index, "What does ERR-4012 mean?", {"everyone"}) 1268 print(r.context) 1269 print() 1270 print("answer:", r.answer) 1271 print("citations:", r.citations) 1272 print() 1273 1274 banner("3. Permissions are filtered before retrieval, not after generation") 1275 print("finance user :", answer(index, "What is the Q3 revenue forecast?", {"everyone", "finance"}).answer) 1276 print("other user :", answer(index, "What is the Q3 revenue forecast?", {"everyone"}).answer) 1277 print("post-filtered:", post_generation_filter_answer(index, "What is the Q3 revenue forecast?", {"everyone"})) 1278 print() 1279 say("Post-filtering removed the citation but the number had already been written. Filter first.") 1280 1281 banner("4. Retrieval upgrades") 1282 ctx = RAGIndex(contextual=True) 1283 rows = [ 1284 ("hybrid vs dense on 'what does ERR-4012 mean'", [p.doc_id for p in index.retrieve("what does ERR-4012 mean", {"everyone"}, 3, "dense")], [p.doc_id for p in index.retrieve("what does ERR-4012 mean", {"everyone"}, 3)]), 1285 ("date filter on the travel policy", [p.doc_id for p in index.retrieve("business class flights over four hours", {"everyone"}, 3)], [p.doc_id for p in index.retrieve("business class flights over four hours", {"everyone"}, 3, updated_after="2024-01-01")]), 1286 ("contextual chunks for 'how do I fix ERR-4012'", [p.id for p in index.retrieve("how do I fix ERR-4012", {"everyone"}, 3)], [p.id for p in ctx.retrieve("how do I fix ERR-4012", {"everyone"}, 3)]), 1287 ("rewrite 'what if it fails?' after a VPN question", [p.doc_id for p in index.retrieve("what if it fails?", {"everyone"}, 3)], [p.doc_id for p in index.retrieve(rewrite_query("what if it fails?", ["How do I set up the VPN?"]), {"everyone"}, 3)]), 1288 ("HyDE for 'weird message asking for my bank details'", [p.doc_id for p in index.retrieve("I got a weird message asking for my bank details", {"everyone"}, 3, "dense")], [p.doc_id for p in hyde_search(index, "I got a weird message asking for my bank details", {"everyone"}, 3)]), 1289 ("multi-query for 'two step login setup'", [p.doc_id for p in index.retrieve("two step login setup", {"everyone"}, 3)], [p.doc_id for p in multi_query_search(index, "two step login setup", {"everyone"}, 3)]), 1290 ] 1291 table(["upgrade", "before", "after"], rows) 1292 1293 banner("5. Agentic RAG") 1294 print(agentic_answer(index, "What is the per-diem for meals and how do I upload expense receipts?", {"everyone"})) 1295 print(agentic_answer(index, "thanks, that's all!", {"everyone"})) 1296 print() 1297 1298 banner("6. GraphRAG in miniature") 1299 g = build_graph() 1300 for n, docs in sorted(g["two-factor"].items()): 1301 print(f"two-factor -- {n} (stated in {sorted(docs)})") 1302 print("communities:", communities(g)) 1303 print() 1304 1305 banner("7. Debugging confident wrong answers: retrieval or generation?") 1306 for mode in ("dense", "hybrid"): 1307 rep = debug_wrong_answers(index, mode) 1308 misses = {q: v for q, v in rep["by_query"].items() if v != "ok"} 1309 print(f"{mode:6s} recall@3 {rep['recall_at_k']:.2f} problems: {misses}") 1310 print() 1311 takeaway("Measure retrieval first. If the right passage isn't in the top k, no prompt can fix the answer.") 1312 1313 1314if __name__ == "__main__": 1315 demo()
743def clean_extracted_text(raw: str) -> str:
744    """Repair the usual damage of PDF text extraction.
745
746    1. Drop lines repeated on two or more pages (running headers/footers).
747    2. Drop "Page n of m" footers.
748    3. Rejoin words hyphenated across line breaks ("em-" + "ployees").
749    4. Unwrap prose lines into paragraphs; keep table rows on their own lines.
750    """
751    pages = [p.strip("\n").split("\n") for p in raw.split("\f")]
752    seen_on: dict[str, int] = {}
753    for lines in pages:
754        for line in set(l.strip() for l in lines):
755            seen_on[line] = seen_on.get(line, 0) + 1
756    kept = [l.strip() for lines in pages for l in lines
757            if l.strip() and seen_on[l.strip()] < 2 and not _PAGE_NUMBER.match(l.strip())]
758
759    out: list[str] = []
760    for line in kept:
761        is_table_row = len(_COLUMNS.split(line)) > 1
762        if out and not is_table_row and not out[-1].endswith("\n"):
763            prev = out.pop()
764            if prev.endswith("-") and line[:1].islower():
765                out.append(prev[:-1] + line)  # hyphenated word: join with no space
766            else:
767                out.append(prev + " " + line)
768        else:
769            out.append(line + ("\n" if is_table_row else ""))
770    return "\n".join(s.rstrip("\n") for s in out)
Repair the usual damage of PDF text extraction.
- Drop lines repeated on two or more pages (running headers/footers).
- Drop "Page n of m" footers.
- Rejoin words hyphenated across line breaks ("em-" + "ployees").
- Unwrap prose lines into paragraphs; keep table rows on their own lines.
773def extract_table(raw: str, header: list[str]) -> list[dict[str, str]]:
774    """Find the table whose header row matches `header` and return its rows as dicts."""
775    lines = [l.strip() for l in raw.split("\n")]
776    for i, line in enumerate(lines):
777        if _COLUMNS.split(line) == header:
778            rows = []
779            for row in lines[i + 1 :]:
780                cells = _COLUMNS.split(row)
781                if len(cells) != len(header):
782                    break
783                rows.append(dict(zip(header, cells)))
784            return rows
785    return []
Find the table whose header row matches header and return its rows as dicts.
788def table_rows_as_sentences(rows: list[dict[str, str]]) -> list[str]:
789    """One self-contained sentence per row, so each row can be retrieved on its own."""
790    out = []
791    for row in rows:
792        key, *rest = list(row)
793        out.append(f"{key} {row[key]}: " + ", ".join(f"{h.lower()} {row[h]}" for h in rest) + ".")
794    return out
One self-contained sentence per row, so each row can be retrieved on its own.
797@dataclass(frozen=True)
798class Passage:
799    """A retrievable piece of a document, with the metadata filters need."""
800
801    id: str  # "<doc id>#<position>"
802    doc_id: str
803    title: str
804    text: str
805    department: str
806    updated: str
807    acl: frozenset[str]
808    index_text: str = ""  # what BM25 and the embedder actually see
A retrievable piece of a document, with the metadata filters need.
815def chunk_document(doc: Doc, max_words: int = 15, contextual: bool = False) -> list[Passage]:
816    """Split a document on sentence boundaries into passages of at most ~max_words words.
817
818    With `contextual=True`, each passage is indexed with a short line saying
819    where it comes from (title and department), so a sentence like "Update
820    AnyConnect and reboot" still says which error it fixes.
821    """
822    groups: list[list[str]] = []
823    for s in _sentences(doc.text):
824        if groups and len(" ".join(groups[-1] + [s]).split()) <= max_words:
825            groups[-1].append(s)
826        else:
827            groups.append([s])
828    out = []
829    for i, g in enumerate(groups):
830        text = " ".join(g)
831        prefix = f"{doc.title} ({doc.department}): " if contextual else ""
832        out.append(Passage(f"{doc.id}#{i}", doc.id, doc.title, text, doc.department, doc.updated, doc.acl, prefix + text))
833    return out
Split a document on sentence boundaries into passages of at most ~max_words words.
With contextual=True, each passage is indexed with a short line saying
where it comes from (title and department), so a sentence like "Update
AnyConnect and reboot" still says which error it fixes.
839class RAGIndex:
840    """Passages from every document, indexed for keyword (BM25) and dense search."""
841
842    def __init__(self, docs: list[Doc] = DOCS, contextual: bool = False, embedder: ConceptEmbedder | None = None, max_words: int = 15):
843        self.passages = [p for d in docs for p in chunk_document(d, max_words, contextual)]
844        self.by_id = {p.id: p for p in self.passages}
845        self.embedder = embedder or ConceptEmbedder()
846        self.bm25 = BM25([tokenize(p.index_text) for p in self.passages])
847        self.vectors = self.embedder.encode([p.index_text for p in self.passages])  # (n_passages, dim), unit rows
848        self.reranker = CrossEncoder(self.embedder)
849
850    def retrieve(self, query: str, user_groups: set[str], k: int = 5, mode: str = "hybrid",
851                 updated_after: str | None = None, depth: int = 10) -> list[Passage]:
852        """Top-k passages the user may see, ranked by BM25, dense, or both fused.
853
854        The permission and date filters run FIRST, on the candidate set,
855        before anything is ranked, so restricted text can't leak into the
856        results, the context, or the answer.
857        """
858        allowed = [i for i, p in enumerate(self.passages)
859                   if p.acl & set(user_groups) and (updated_after is None or p.updated >= updated_after)]
860        rankings = []
861        if mode in ("bm25", "hybrid"):
862            s = self.bm25.scores(tokenize(query))
863            rankings.append([self.passages[i].id for i in sorted(allowed, key=lambda i: -s[i]) if s[i] > 0][:depth])
864        if mode in ("dense", "hybrid"):
865            sims = self.vectors @ self.embedder.encode(query)
866            rankings.append([self.passages[i].id for i in sorted(allowed, key=lambda i: -sims[i])][:depth])
867        fused = rankings[0] if len(rankings) == 1 else [pid for pid, _ in reciprocal_rank_fusion(rankings)]
868        return [self.by_id[pid] for pid in fused[:k]]
869
870    def rerank(self, query: str, passages: list[Passage], top_n: int = 3) -> list[Passage]:
871        """Second stage: score each (question, passage) pair together; keep the best few."""
872        as_docs = {p.id: Doc(p.id, p.title, p.text, p.department, p.updated, p.acl) for p in passages}
873        return sorted(passages, key=lambda p: -self.reranker.score(query, as_docs[p.id]))[:top_n]
874
875    def retrieve_parents(self, query: str, user_groups: set[str], k: int = 3) -> list[Doc]:
876        """Search small passages (precise matches), return their whole documents (full context)."""
877        seen: list[str] = []
878        for p in self.retrieve(query, user_groups, k=k * 4):
879            if p.doc_id not in seen:
880                seen.append(p.doc_id)
881        return [DOCS_BY_ID[d] for d in seen[:k]]
Passages from every document, indexed for keyword (BM25) and dense search.
842    def __init__(self, docs: list[Doc] = DOCS, contextual: bool = False, embedder: ConceptEmbedder | None = None, max_words: int = 15):
843        self.passages = [p for d in docs for p in chunk_document(d, max_words, contextual)]
844        self.by_id = {p.id: p for p in self.passages}
845        self.embedder = embedder or ConceptEmbedder()
846        self.bm25 = BM25([tokenize(p.index_text) for p in self.passages])
847        self.vectors = self.embedder.encode([p.index_text for p in self.passages])  # (n_passages, dim), unit rows
848        self.reranker = CrossEncoder(self.embedder)
850    def retrieve(self, query: str, user_groups: set[str], k: int = 5, mode: str = "hybrid",
851                 updated_after: str | None = None, depth: int = 10) -> list[Passage]:
852        """Top-k passages the user may see, ranked by BM25, dense, or both fused.
853
854        The permission and date filters run FIRST, on the candidate set,
855        before anything is ranked, so restricted text can't leak into the
856        results, the context, or the answer.
857        """
858        allowed = [i for i, p in enumerate(self.passages)
859                   if p.acl & set(user_groups) and (updated_after is None or p.updated >= updated_after)]
860        rankings = []
861        if mode in ("bm25", "hybrid"):
862            s = self.bm25.scores(tokenize(query))
863            rankings.append([self.passages[i].id for i in sorted(allowed, key=lambda i: -s[i]) if s[i] > 0][:depth])
864        if mode in ("dense", "hybrid"):
865            sims = self.vectors @ self.embedder.encode(query)
866            rankings.append([self.passages[i].id for i in sorted(allowed, key=lambda i: -sims[i])][:depth])
867        fused = rankings[0] if len(rankings) == 1 else [pid for pid, _ in reciprocal_rank_fusion(rankings)]
868        return [self.by_id[pid] for pid in fused[:k]]
Top-k passages the user may see, ranked by BM25, dense, or both fused.
The permission and date filters run FIRST, on the candidate set, before anything is ranked, so restricted text can't leak into the results, the context, or the answer.
870    def rerank(self, query: str, passages: list[Passage], top_n: int = 3) -> list[Passage]:
871        """Second stage: score each (question, passage) pair together; keep the best few."""
872        as_docs = {p.id: Doc(p.id, p.title, p.text, p.department, p.updated, p.acl) for p in passages}
873        return sorted(passages, key=lambda p: -self.reranker.score(query, as_docs[p.id]))[:top_n]
Second stage: score each (question, passage) pair together; keep the best few.
875    def retrieve_parents(self, query: str, user_groups: set[str], k: int = 3) -> list[Doc]:
876        """Search small passages (precise matches), return their whole documents (full context)."""
877        seen: list[str] = []
878        for p in self.retrieve(query, user_groups, k=k * 4):
879            if p.doc_id not in seen:
880                seen.append(p.doc_id)
881        return [DOCS_BY_ID[d] for d in seen[:k]]
Search small passages (precise matches), return their whole documents (full context).
893def assemble_context(question: str, passages: list[Passage]) -> str:
894    """Sources in escaped, id-tagged blocks; the question last (see primer.agents.context)."""
895    sources = "\n".join(xml_wrap("source", p.text, id=p.id, title=p.title, updated=p.updated) for p in passages)
896    return f"<sources>\n{sources}\n</sources>\n<question>{question}</question>"
Sources in escaped, id-tagged blocks; the question last (see primer.agents.context).
905def grounded_policy(system: str, messages: list[dict], tools: list[dict] | None) -> str:  # noqa: ARG001
906    """Offline stand-in for a model that answers only from tagged sources, with citations.
907
908    It picks the source sentence sharing the most ideas with the question
909    and cites it; if nothing shares at least two, it declines. A real model
910    writes more fluent answers, but the contract (answer from sources, cite,
911    or decline) is the same one you'd put in its system prompt.
912    """
913    text = last_user_text(messages)
914    question = re.search(r"<question>(.*?)</question>", text, re.S).group(1)
915    best, best_score = None, 0
916    for sid, body in re.findall(r'<source id="([^"]+)"[^>]*>(.*?)</source>', text, re.S):
917        for sentence in _sentences(body):
918            score = _overlap(question, sentence)
919            if score > best_score:
920                best, best_score = (sentence, sid), score
921    if best is None or best_score < 2:
922        return DONT_KNOW
923    return f"{best[0]} [{best[1]}]"
Offline stand-in for a model that answers only from tagged sources, with citations.
It picks the source sentence sharing the most ideas with the question and cites it; if nothing shares at least two, it declines. A real model writes more fluent answers, but the contract (answer from sources, cite, or decline) is the same one you'd put in its system prompt.
936def verify_citations(answer_text: str, passages: list[Passage]) -> dict[str, list[str]]:
937    """Check that every cited id was actually in the context and supports its sentence."""
938    by_id = {p.id: p for p in passages}
939    cited = _CITATION.findall(answer_text)
940    unknown = [c for c in cited if c not in by_id]
941    unsupported = []
942    # Each citation vouches for the text between the previous citation and itself.
943    for claim, c in _CLAIM_THEN_CITATION.findall(answer_text):
944        claim = claim.strip(" .")
945        if c in by_id and claim_support(claim, [by_id[c].text]) < 0.6:
946            unsupported.append(claim)
947    return {"cited": cited, "unknown_ids": unknown, "unsupported": unsupported}
Check that every cited id was actually in the context and supports its sentence.
950@dataclass
951class RAGResult:
952    answer: str
953    passages: list[Passage]
954    context: str
955    citations: dict[str, list[str]] = field(default_factory=dict)
958def answer(index: RAGIndex, question: str, user_groups: set[str], k: int = 8, top_n: int = 3, llm: Any = None) -> RAGResult:
959    """The whole query-time pipeline: retrieve (filtered) -> rerank -> assemble -> generate -> verify."""
960    candidates = index.retrieve(question, user_groups, k=k)
961    passages = index.rerank(question, candidates, top_n) if candidates else []
962    text = generate(question, passages, llm)
963    return RAGResult(text, passages, assemble_context(question, passages), verify_citations(text, passages))
The whole query-time pipeline: retrieve (filtered) -> rerank -> assemble -> generate -> verify.
966def post_generation_filter_answer(index: RAGIndex, question: str, user_groups: set[str]) -> str:
967    """The WRONG way: retrieve everything, generate, then strip restricted citations.
968
969    The citation markers go; the restricted facts the model already wrote stay.
970    """
971    result = answer(index, question, set(ALL_GROUPS))
972    allowed = {p.id for p in index.passages if p.acl & set(user_groups)}
973    return _CITATION.sub(lambda m: m.group(0) if m.group(1) in allowed else "", result.answer).strip()
The WRONG way: retrieve everything, generate, then strip restricted citations.
The citation markers go; the restricted facts the model already wrote stay.
983def rewrite_query(question: str, history: list[str], llm: Any = None) -> str:
984    """Turn a follow-up into a standalone search query.
985
986    Deterministic stand-in: if the follow-up leans on earlier context ("it",
987    "that", "what about"), append the content words of the previous user
988    turn. In production a small model does this with an instruction like
989    "rewrite the last question so it can be understood without the chat".
990    """
991    if llm is not None:
992        prompt = "Rewrite the last question as a standalone search query.\n" + "\n".join(history + [question])
993        return llm.complete(system="", messages=[{"role": "user", "content": prompt}]).text
994    if not history or not _REFERRING.search(question):
995        return question
996    extra = [t for t in tokenize(history[-1]) if t not in tokenize(question)]
997    return f"{question} {' '.join(extra)}"
Turn a follow-up into a standalone search query.
Deterministic stand-in: if the follow-up leans on earlier context ("it", "that", "what about"), append the content words of the previous user turn. In production a small model does this with an instruction like "rewrite the last question so it can be understood without the chat".
1015def hyde_search(index: RAGIndex, question: str, user_groups: set[str], k: int = 5, llm: Any = None) -> list[Passage]:
1016    """Hypothetical Document Embeddings: search with a drafted answer instead of the question.
1017
1018    Answers look like documents; questions don't. Embedding a plausible
1019    answer lands closer to the real passage than embedding the question.
1020    """
1021    llm = llm or ScriptedLLM(_draft_policy)
1022    draft = llm.complete(system="Write a short passage that answers the question.",
1023                         messages=[{"role": "user", "content": question}]).text
1024    return index.retrieve(draft, user_groups, k=k, mode="dense")
Hypothetical Document Embeddings: search with a drafted answer instead of the question.
Answers look like documents; questions don't. Embedding a plausible answer lands closer to the real passage than embedding the question.
1038def multi_query_search(index: RAGIndex, question: str, user_groups: set[str], k: int = 5, llm: Any = None) -> list[Passage]:
1039    """Search several phrasings of the question and fuse the rankings with RRF."""
1040    llm = llm or ScriptedLLM(_phrasings_policy)
1041    reply = llm.complete(system="Write two alternative search queries, one per line.", messages=[{"role": "user", "content": question}])
1042    phrasings = [question] + [l for l in reply.text.split("\n") if l.strip()]
1043    rankings = [[p.id for p in index.retrieve(q, user_groups, k=10)] for q in phrasings]
1044    return [index.by_id[pid] for pid, _ in reciprocal_rank_fusion(rankings)[:k]]
Search several phrasings of the question and fuse the rankings with RRF.
1072def agentic_answer(index: RAGIndex, question: str, user_groups: set[str], max_steps: int = 6, llm: Any = None) -> dict[str, Any]:
1073    llm = llm or ScriptedLLM(_agentic_policy)
1074    messages: list[dict] = [{"role": "user", "content": question}]
1075    searches: list[str] = []
1076    reply = None
1077    for _ in range(max_steps):
1078        reply = llm.complete(system=SYSTEM, messages=messages, tools=[SEARCH_TOOL])
1079        messages.append({"role": "assistant", "content": reply.assistant_content})
1080        if reply.stop_reason != "tool_use":
1081            break
1082        results = []
1083        for call in reply.tool_calls:
1084            q = call.input["query"]
1085            searches.append(q)
1086            # The tool applies the freshness filter, so superseded policies never come back.
1087            hits = index.rerank(q, index.retrieve(q, user_groups, k=8, updated_after="2024-01-01"), top_n=3)
1088            body = "<sources>" + "".join(xml_wrap("source", p.text, id=p.id) for p in hits) + "</sources>"
1089            results.append(tool_result_block(call.id, body))
1090        messages.append({"role": "user", "content": results})
1091    return {"answer": reply.text if reply else "", "searches": searches}
1116def build_graph(docs: list[Doc] = DOCS) -> dict[str, dict[str, set[str]]]:
1117    """Entity graph: two entities are linked when a sentence mentions both.
1118
1119    Each link remembers which documents stated it, so answers drawn from the
1120    graph can still cite sources. Real GraphRAG uses a model to extract
1121    entities and typed relations ("requires", "replaces") and then
1122    summarizes communities of related entities.
1123    """
1124    graph: dict[str, dict[str, set[str]]] = {}
1125    for d in docs:
1126        for sentence in _sentences(f"{d.title}. {d.text}"):
1127            found = sorted(name for name, pat in ENTITIES.items() if re.search(pat, sentence, re.I))
1128            for a in found:
1129                for b in found:
1130                    if a != b:
1131                        graph.setdefault(a, {}).setdefault(b, set()).add(d.id)
1132    return graph
Entity graph: two entities are linked when a sentence mentions both.
Each link remembers which documents stated it, so answers drawn from the graph can still cite sources. Real GraphRAG uses a model to extract entities and typed relations ("requires", "replaces") and then summarizes communities of related entities.
1135def communities(graph: dict[str, dict[str, set[str]]]) -> list[set[str]]:
1136    """Connected groups of entities: the "themes" GraphRAG summarizes."""
1137    seen: set[str] = set()
1138    groups = []
1139    for start in graph:
1140        if start in seen:
1141            continue
1142        stack, comp = [start], set()
1143        while stack:
1144            n = stack.pop()
1145            if n not in comp:
1146                comp.add(n)
1147                stack.extend(graph.get(n, {}))
1148        seen |= comp
1149        groups.append(comp)
1150    return sorted(groups, key=len, reverse=True)
Connected groups of entities: the "themes" GraphRAG summarizes.
1158def debug_wrong_answers(index: RAGIndex, mode: str = "hybrid", k: int = 3, queries: list[tuple[str, set[str]]] = LABELED_QUERIES) -> dict[str, Any]:
1159    """Separate retrieval failures from generation failures on a labelled set.
1160
1161    For each question: if no relevant document is in the top k, it's a
1162    retrieval miss (no prompt change can fix it). If one is there but the
1163    answer doesn't cite it, it's a generation miss.
1164    """
1165    by_query: dict[str, str] = {}
1166    for q, relevant in queries:
1167        passages = index.retrieve(q, set(ALL_GROUPS), k=k, mode=mode)
1168        if not relevant & {p.doc_id for p in passages}:
1169            by_query[q] = "retrieval miss"
1170            continue
1171        text = generate(q, passages)
1172        cited_docs = {c.split("#")[0] for c in _CITATION.findall(text)}
1173        by_query[q] = "ok" if cited_docs & relevant else "generation miss"
1174    misses = sum(v == "retrieval miss" for v in by_query.values())
1175    return {"by_query": by_query, "recall_at_k": 1 - misses / len(queries)}
Separate retrieval failures from generation failures on a labelled set.
For each question: if no relevant document is in the top k, it's a retrieval miss (no prompt change can fix it). If one is there but the answer doesn't cite it, it's a generation miss.
1178def recall_curve(index: RAGIndex, mode: str, ks: list[int], rerank: bool = False,
1179                 queries: list[tuple[str, set[str]]] = LABELED_QUERIES) -> list[float]:
1180    """recall@k for each k: share of questions with a relevant document in the top k."""
1181    out = []
1182    for k in ks:
1183        hits = 0
1184        for q, relevant in queries:
1185            if rerank:
1186                passages = index.rerank(q, index.retrieve(q, set(ALL_GROUPS), k=10, mode=mode), top_n=k)
1187            else:
1188                passages = index.retrieve(q, set(ALL_GROUPS), k=k, mode=mode)
1189            hits += bool(relevant & {p.doc_id for p in passages})
1190        out.append(hits / len(queries))
1191    return out
recall@k for each k: share of questions with a relevant document in the top k.
1199def figures() -> dict[str, Any]:
1200    import matplotlib
1201
1202    matplotlib.use("Agg")
1203    import matplotlib.pyplot as plt
1204
1205    figs: dict[str, Any] = {}
1206    index = RAGIndex()
1207    ks = [1, 2, 3, 4, 5]
1208    fig, ax = plt.subplots(figsize=(6.5, 3.6))
1209    for label, mode, rr, color in [("keyword (BM25)", "bm25", False, "#dd8452"), ("dense", "dense", False, "#8172b2"),
1210                                   ("hybrid (RRF)", "hybrid", False, "#4c72b0"), ("hybrid + rerank", "hybrid", True, "#55a868")]:
1211        ax.plot(ks, recall_curve(index, mode, ks, rr), "o-", label=label, color=color)
1212    ax.set_xticks(ks)
1213    ax.set_xlabel("k (passages kept)")
1214    ax.set_ylabel("recall@k on the labelled questions")
1215    ax.set_ylim(0, 1.05)
1216    ax.set_title("Which retrieval finds the answer?")
1217    ax.legend(fontsize=8, loc="lower right")
1218    fig.tight_layout()
1219    figs["recall"] = fig
1220
1221    fig, ax = plt.subplots(figsize=(6.5, 3.2))
1222    kinds = ["ok", "generation miss", "retrieval miss"]
1223    colors = {"ok": "#55a868", "generation miss": "#dd8452", "retrieval miss": "#c44e52"}
1224    modes = ["bm25", "dense", "hybrid"]
1225    left = np.zeros(len(modes))
1226    for kind in kinds:
1227        counts = np.array([list(debug_wrong_answers(index, m)["by_query"].values()).count(kind) for m in modes])
1228        ax.barh(modes, counts, left=left, color=colors[kind], label=kind)
1229        left += counts
1230    ax.set_xlabel("labelled questions (top 3 passages)")
1231    ax.set_title("Where do wrong answers come from?")
1232    ax.legend(fontsize=8, loc="lower right")
1233    fig.tight_layout()
1234    figs["diagnosis"] = fig
1235
1236    plain, ctx = RAGIndex(), RAGIndex(contextual=True)
1237    fix = "Update AnyConnect to version 5.1 or later and reboot."
1238    qs = ["how do I fix ERR-4012", "ERR-4012 what should I do", "resolve ERR-4012 on my laptop"]
1239
1240    def rank_of(idx, q):
1241        ids = [p.text for p in idx.retrieve(q, {"everyone"}, k=20)]
1242        return ids.index(fix) + 1 if fix in ids else 21
1243
1244    fig, ax = plt.subplots(figsize=(6.5, 3))
1245    y = np.arange(len(qs))
1246    ax.barh(y - 0.2, [rank_of(plain, q) for q in qs], 0.4, color="#c44e52", label="plain chunks")
1247    ax.barh(y + 0.2, [rank_of(ctx, q) for q in qs], 0.4, color="#4c72b0", label="chunks with a context line")
1248    ax.set_yticks(y, qs)
1249    ax.invert_yaxis()
1250    ax.set_xlabel("rank of the passage containing the fix (lower is better; 21 = not in top 20)")
1251    ax.set_title("Contextual retrieval")
1252    ax.legend(fontsize=8)
1253    fig.tight_layout()
1254    figs["contextual"] = fig
1255    return figs
1258def demo() -> None:
1259    index = RAGIndex()
1260    banner("1. Parsing: repair the extraction before anything else")
1261    print(clean_extracted_text(MESSY_PDF))
1262    print()
1263    for s in table_rows_as_sentences(extract_table(MESSY_PDF, ["Grade", "Hotel cap", "Meal cap"])):
1264        print("row ->", s)
1265    print()
1266
1267    banner("2. The pipeline, end to end")
1268    r = answer(index, "What does ERR-4012 mean?", {"everyone"})
1269    print(r.context)
1270    print()
1271    print("answer:", r.answer)
1272    print("citations:", r.citations)
1273    print()
1274
1275    banner("3. Permissions are filtered before retrieval, not after generation")
1276    print("finance user :", answer(index, "What is the Q3 revenue forecast?", {"everyone", "finance"}).answer)
1277    print("other user   :", answer(index, "What is the Q3 revenue forecast?", {"everyone"}).answer)
1278    print("post-filtered:", post_generation_filter_answer(index, "What is the Q3 revenue forecast?", {"everyone"}))
1279    print()
1280    say("Post-filtering removed the citation but the number had already been written. Filter first.")
1281
1282    banner("4. Retrieval upgrades")
1283    ctx = RAGIndex(contextual=True)
1284    rows = [
1285        ("hybrid vs dense on 'what does ERR-4012 mean'", [p.doc_id for p in index.retrieve("what does ERR-4012 mean", {"everyone"}, 3, "dense")], [p.doc_id for p in index.retrieve("what does ERR-4012 mean", {"everyone"}, 3)]),
1286        ("date filter on the travel policy", [p.doc_id for p in index.retrieve("business class flights over four hours", {"everyone"}, 3)], [p.doc_id for p in index.retrieve("business class flights over four hours", {"everyone"}, 3, updated_after="2024-01-01")]),
1287        ("contextual chunks for 'how do I fix ERR-4012'", [p.id for p in index.retrieve("how do I fix ERR-4012", {"everyone"}, 3)], [p.id for p in ctx.retrieve("how do I fix ERR-4012", {"everyone"}, 3)]),
1288        ("rewrite 'what if it fails?' after a VPN question", [p.doc_id for p in index.retrieve("what if it fails?", {"everyone"}, 3)], [p.doc_id for p in index.retrieve(rewrite_query("what if it fails?", ["How do I set up the VPN?"]), {"everyone"}, 3)]),
1289        ("HyDE for 'weird message asking for my bank details'", [p.doc_id for p in index.retrieve("I got a weird message asking for my bank details", {"everyone"}, 3, "dense")], [p.doc_id for p in hyde_search(index, "I got a weird message asking for my bank details", {"everyone"}, 3)]),
1290        ("multi-query for 'two step login setup'", [p.doc_id for p in index.retrieve("two step login setup", {"everyone"}, 3)], [p.doc_id for p in multi_query_search(index, "two step login setup", {"everyone"}, 3)]),
1291    ]
1292    table(["upgrade", "before", "after"], rows)
1293
1294    banner("5. Agentic RAG")
1295    print(agentic_answer(index, "What is the per-diem for meals and how do I upload expense receipts?", {"everyone"}))
1296    print(agentic_answer(index, "thanks, that's all!", {"everyone"}))
1297    print()
1298
1299    banner("6. GraphRAG in miniature")
1300    g = build_graph()
1301    for n, docs in sorted(g["two-factor"].items()):
1302        print(f"two-factor -- {n}  (stated in {sorted(docs)})")
1303    print("communities:", communities(g))
1304    print()
1305
1306    banner("7. Debugging confident wrong answers: retrieval or generation?")
1307    for mode in ("dense", "hybrid"):
1308        rep = debug_wrong_answers(index, mode)
1309        misses = {q: v for q, v in rep["by_query"].items() if v != "ok"}
1310        print(f"{mode:6s} recall@3 {rep['recall_at_k']:.2f}  problems: {misses}")
1311    print()
1312    takeaway("Measure retrieval first. If the right passage isn't in the top k, no prompt can fix the answer.")