primer.agents.llm
Talking to a model: messages, and what tool calling really is
Run: python -m primer.agents.llm
New to the notation? primer.notation explains every symbol used here from
zero. This is the first lesson of the agents part: it builds on how a model
produces text (primer.ml.inference), and every later agent lesson builds on
it.
Level 1: The practitioner's guide
In one sentence. Talking to a model means sending it the whole
conversation so far as a list of messages and getting one message back, and
tool calling is the case where that message is a structured request ("run
get_weather with {"city": "Paris"}") that your code may carry out and
answer.
When you need it. Every system built on a language model does this,
from a one-shot classifier to a multi-agent research team, so the message
format is not optional. Tool calling is. You need it the moment the model
must reach past its own weights: look something up, run a query, compute a
number, send an email, change a record. You don't need it when the answer is
words the model already knows, and you don't need it when one structured
answer is enough (a label, a JSON row): that is structured output
(primer.ml.structured_output), which is a tool call without the "run it and
come back" step. The tell: if your code reads the model's prose to decide
which function to call, or scrapes a city name out of a sentence, you need
tool calling. The model was trained to hand you that request as data.
Two facts about the exchange decide most of what follows, and both come from
this lesson's traced example. First, the model executes nothing: the reply
to "What's the weather in Paris?" is a tool_use block asking for
get_weather, and the 18°C comes from your code running the function and
sending the result back. Second, the model keeps no state between calls, so
every call carries the whole history again. In the lesson's ten-call loop,
that turns a conversation 7,000 tokens long into 42,500 input tokens billed.
Your options. Five ways to get an action out of a model, from the cheapest to the most certain:
| Option | What it does | What it guarantees | What it costs | Where it lives |
|---|---|---|---|---|
| A scripted stand-in | A function you write plays the model, replying by rule | The exact reply you scripted, every run, offline | Nothing per call; proves nothing about a real model | Your tests and demos |
| A local open model, text only | Weights on your own machine answer in plain text | Privacy: nothing leaves the box; no per-token bill | Hardware, smaller models, and your own parsing if you need actions | Your machine (Ollama and similar) |
| Text you parse | Ask the model to write the action in prose, then match it with a regular expression | Nothing; it works until the wording drifts | A parser you maintain and a retry loop | Your code |
| Native tool calling | The model replies with a typed tool_use block: a name, an id, and the arguments as a parsed JSON object |
A request in your schema's shape; with strict mode, exactly your schema | Tokens for the tool definitions, a tool-use system prompt the API adds (286 tokens on Claude Opus 5, per the pricing page), and one extra round trip per call | The model server produces it; your code runs it |
| Server-side tools | The provider runs the tool (web search, web fetch, code execution) and returns the result in the same reply | The result arrives with no handler code on your side | Per-use fees on some tools (Claude's web search is \$10 per 1,000 searches) and no control over execution | The model server |
How to choose. Start from what has to happen, and who is allowed to make it happen.
- Testing the code around the model (a loop, a budget, an approval step): the scripted stand-in. It reproduces a model that loops, calls the wrong tool or follows an injected instruction on cue, which a real model rarely does when you want it to.
- Private data, no budget, or a laptop on a plane: a local open model. Keep it to text unless the model and server both support tool calling (Ollama does, for models trained for it; this lesson's local adapter is text only).
- Anything a program acts on: native tool calling, never parsed prose. Turn on strict mode when the arguments feed straight into code.
- Web search or sandboxed code that you would otherwise host yourself: a server-side tool, if its fees and its lack of a hook for your own checks suit you.
- Whatever you pick, your code stays the only thing that acts. Validate the arguments, check permissions, then run the tool; the model only asks.
What it costs. Input tokens are billed on the whole history, every call,
so the cost of a loop grows with the square of its length: the lesson's ten
calls bill 42,500 tokens, six times the 7,000-token conversation they end
with, and the tenth call alone re-sends 6,500. At Claude Opus 5's list price
of \$5 per million input tokens (the pricing page, fetched for this guide)
that is about 21 cents per ten-step task before any output; on Haiku 4.5 at
\$1 per million, about 4 cents. Prompt caching sells re-read tokens at a
tenth of the price, which is why it is the first lever on any loop
(primer.agents.cost). Tool definitions ride along on every call too, so a
long tool list is a standing charge. Latency is one network round trip per
model call plus the tool's own time, and a tool call always means at least
two model calls.
What breaks.
- Dropping the assistant turn. Append the exact content blocks the model returned, not just their text: the ids in them are how the next call matches results to requests, and real APIs can include blocks (thinking) that must go back unchanged.
- Unmatched ids. A
tool_resultwhosetool_use_idmatches no request answers nothing. Return one result per request, and all of them in a single user message when the model asked for several. - Swallowing failures. A tool that throws and returns nothing leaves the model waiting. Send a result flagged as an error with a message the model can act on, so it can retry or ask.
- Trusting the request. Arguments arrive as a parsed object in the shape of your schema, not as safe values. Validate them and check permissions before running anything; the model is never a security boundary.
- Ignoring
stop_reason.tool_usemeans run tools and call again;end_turnmeans done;max_tokensmeans the reply was cut off and its JSON may be incomplete;refusalmeans the model declined. A loop that checks only for text gets all four wrong. - Missing arguments guessed. Asked for the weather with no city, a model may invent one rather than ask (Claude's tool-use docs call the asking behaviour model-dependent and not guaranteed). Make optional what is optional, and validate the rest.
In the wild. Claude's Messages API is the shape this lesson uses
directly: tool_use and tool_result blocks, stop_reason, parallel tool
calls, strict: true for schema-exact arguments, and server tools (web
search, web fetch, code execution) alongside the client tools you run. Its
SDKs add a tool runner that drives the request, run, reply loop for you.
OpenAI's function calling is the same five-step round trip in different
field names, with its own strict mode; the guide recommends turning it on.
Ollama exposes tool calling for local models, where again the model returns
the call and your code runs it. Every agent framework, from the smallest
loop to a multi-agent system, is built on this exchange, and the papers
behind it (Toolformer, ReAct) are in this lesson's papers section.
Go deeper. Level 2 traces the four messages of one tool call by hand, lays out the message format field by field, shows the one interface that a scripted model and a real one both implement, and derives the quadratic cost of a loop with a formula you can rerun. If you only needed to choose, you are done.
Level 2: How it works, from scratch
Every applied-AI system in this primer, from a one-shot classifier to a multi-agent research team, talks to the model the same way: it sends a list of messages and gets one message back. This lesson shows that exchange exactly, and then the one feature that turns a chatbot into an agent: tool calling.
The everyday picture
Think of the model as a brilliant consultant who works by post. You mail a letter with your whole conversation so far (the consultant keeps no notes between letters) and get one letter back. The reply is either an answer, or a filled-in request form: "please look up the weather in Paris and send me the result." The consultant never picks up the phone themselves. You decide whether to run the request, run it, and mail back the result, together with the whole conversation again.
Two facts fall straight out of this picture, and they explain most of the behaviour of real systems:
- The model executes nothing. A tool call is a request. Your code is the only thing that acts, so your code is where safety lives.
- Every call resends everything. The model has no memory between calls, so each request carries the full history. Long conversations cost more on every single turn.
A tiny worked example: one tool call, traced
A user asks "What's the weather in Paris?" and the application offers one
tool, get_weather. Four messages later, the user has an answer:
| # | Role | Content | Who produced it |
|---|---|---|---|
| 1 | user | "What's the weather in Paris?" | the user |
| 2 | assistant | tool_use id=toolu_1, name=get_weather, input={"city": "Paris"} |
the model (1st call) |
| 3 | user | tool_result for toolu_1: "18°C, sunny" |
your code, after running the tool |
| 4 | assistant | "It's 18°C and sunny in Paris." | the model (2nd call) |
Message 3 has role user even though no human typed it: tool results always
travel back in the user's turn. The id in message 2 and the tool_use_id
in message 3 match, which is how the model knows which request a result
answers when it asked for several at once. trace_tool_call_round_trip()
produces exactly this transcript.
sequenceDiagram
  participant U as User
  participant A as Your code
  participant M as Model
  participant T as get_weather tool
  U->>A: What's the weather in Paris?
  A->>M: messages [1] + tool definitions
  M-->>A: tool_use get_weather {city: Paris}  (stop_reason: tool_use)
  A->>A: validate the arguments, check permissions
  A->>T: get_weather("Paris")
  T-->>A: 18°C, sunny
  A->>M: messages [1, 2, 3 = tool_result]
  M-->>A: It's 18°C and sunny in Paris.  (stop_reason: end_turn)
  A-->>U: It's 18°C and sunny in Paris.
Reading it: time runs downwards. Solid arrows are requests and dashed
arrows are replies. Notice that the model never talks to the tool: every
arrow into get_weather starts at your code, and the self-arrow on your
code ("validate, check permissions") is where production systems put their
guardrails. Notice too that the second call to the model carries messages
1 to 3, not just the new result: the model is stateless, so the history
travels every time.
In code: ToolCall holds the request in message 2, and
tool_result_block builds the reply in message 3, carrying the matching id.
The message format
Messages use the Anthropic Messages API shape directly, so what you learn here maps one-to-one onto production code:
{"role": "user", "content": "What's our PTO policy?"}
{"role": "assistant", "content": [
    {"type": "text", "text": "Let me look that up."},
    {"type": "tool_use", "id": "toolu_1", "name": "search_kb", "input": {"query": "PTO"}},
]}
{"role": "user", "content": [
    {"type": "tool_result", "tool_use_id": "toolu_1", "content": "hr-001: ..."},
]}
| Field | Meaning |
|---|---|
role |
user (the human, or your code returning tool results) or assistant (the model) |
content |
a plain string, or a list of content blocks |
text block |
ordinary words |
tool_use block |
the model asking for a tool: id, name, and input (a JSON object matching the tool's schema) |
tool_result block |
your answer to one tool_use, matched by tool_use_id; set is_error: true when the tool failed |
stop_reason |
why the reply ended: end_turn (finished), tool_use (wants a tool), max_tokens (ran out of room), refusal (declined) |
A tool definition is a name, a description and a JSON Schema for the
input. The model chooses tools by reading those descriptions, so writing
them well is prompt engineering (see primer.agents.tools).
In code: LLMResponse is one reply, normalized: its text, its
ToolCall list, its stop reason, its Usage and the exact content blocks
to append as the assistant turn. content_blocks, last_user_text,
tool_results and tool_calls_so_far read a conversation in this format.
Two implementations of one interface
Every agent lesson is written against one small interface, LLM, with one
method, LLM.complete(system=..., messages=..., tools=...). Two classes
implement it:
flowchart LR
  L["LLM interface<br/>complete(system, messages, tools)"]
  L --> S["ScriptedLLM<br/>a Python function decides the reply<br/>offline, instant, deterministic"]
  L --> C["ClaudeLLM<br/>the real model via the anthropic SDK<br/>needs an API key"]
  S --> D["demos and tests<br/>reproduce any failure on purpose"]
  C --> P["production<br/>same agent code, real behaviour"]
Reading it: the agent code on the right-hand side never knows which
box it's talking to. ScriptedLLM lets every lesson run offline and
deterministically, and lets tests stage a model that loops, calls the wrong
tool or follows an injected instruction, which is hard to get a real model
to do on cue. Swapping in ClaudeLLM runs the identical loop against the
real thing.
In code: ClaudeLLM.complete builds its request with claude_request
and turns the API's reply into an LLMResponse. OllamaLLM is a third
implementation for a local open model (text only), using ollama_request
and parse_ollama_reply.
Cost: why every call pays for the whole conversation
Because the model is stateless, input tokens are billed per call on the entire history. In an agent loop with $n$ calls, where each call adds about $t$ new tokens to a history that started at $h_0$ tokens, the total input billed is:
Level 3: the formula and its symbols
$$ \text{input tokens} \approx \sum_{i=1}^{n} \left(h_0 + (i-1)\,t\right) = n\,h_0 + t\,\frac{n(n-1)}{2} $$
Symbols
| Symbol | Meaning here | In the example |
|---|---|---|
| $n$ | number of model calls in the loop | 10 |
| $h_0$ | tokens in the first request (system prompt, tools, question) | 2,000 |
| $t$ | tokens each step adds (the model's tool call plus the tool's result) | 500 |
| $i$ | which call we're on, 1 to $n$ | |
| $\sum_{i=1}^{n}$ | add up the cost of every call | |
| $\frac{n(n-1)}{2}$ | 0 + 1 + … + (n − 1): how many "steps of history" pile up in total | 45 |
In words: "each call pays for the starting prompt plus everything added so far, so the history term grows with the square of the number of steps."
With the numbers: 10 × 2,000 + 500 × 45 = 20,000 + 22,500 = 42,500 input tokens for a task whose final conversation is only 7,000 tokens long: the tenth call re-sends 6,500 tokens, and its own 500-token step brings the history to 7,000.
Level 3: in Python
In Python:
n, h_0, t = 10, 2000, 500
# call i re-sends h_0 and i - 1 steps
calls = [h_0 + (i - 1) * t for i in range(1, n + 1)]
calls[0], calls[-1]  # → (2000, 6500)
# Σ over every call
sum(calls)  # → 42500
# the shortcut on the right agrees
n * h_0 + t * n * (n - 1) // 2  # → 42500
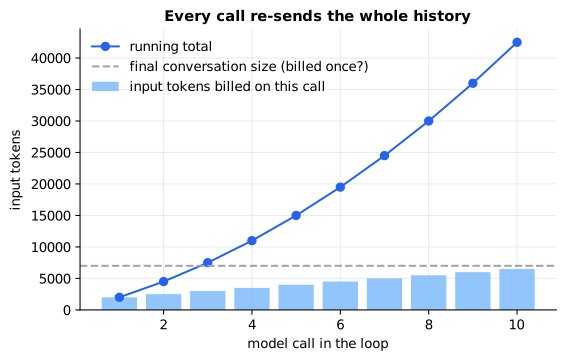
Reading it: the bars are the input tokens billed on each call. They grow
by the same amount every step, because each call re-sends the whole history.
The line is the running total, and it curves upwards (quadratic growth). The
dashed line is what you might naively expect: the size of the final
conversation, billed once. The gap between the dashed line and the curve is
why prompt caching, trimming tool outputs and keeping loops short are the
main cost levers (primer.agents.cost, primer.agents.context).
In code: loop_input_tokens lists the tokens billed on each call of
such a loop. estimate_tokens is the four-characters-per-token rule of
thumb, and conversation_chars measures everything a call resends, which is
how ScriptedLLM gives its fake replies realistic Usage.
In 20 seconds
- A model call sends the full list of messages and returns one message; the model keeps no state between calls.
- A tool call is a structured request (
tool_use). Your code validates it, runs it, and returns atool_resultwith the matching id. The model executes nothing. stop_reasontells you what to do next:tool_usemeans run tools and call again,end_turnmeans done.- Every call re-sends the whole history, so input cost grows quadratically with the number of steps in a loop.
Self-test questions
What exactly happens when a model "uses a tool"?
You send tool definitions (name, description, JSON Schema) with the
messages. The model replies with a tool_use block and stop_reason:
tool_use. Your code validates the arguments, runs the function, and sends a
new request with the history plus a tool_result block carrying the same
id. The model then answers or asks for another tool.
Why is the model never a security boundary for tool use? It only produces requests. Everything that actually happens goes through your code, so validation, permissions, approvals and rate limits all belong there, and a manipulated model can only ever ask.
The model asks for three tools in one reply. How do you send the results?
Run them (concurrently if independent) and return all three tool_result
blocks in a single user message, each with its own tool_use_id. For one
that failed, return a tool_result with is_error: true and an actionable
message rather than dropping it.
A 20-step agent loop costs far more than 20 times a single call. Why? Each call re-sends the full, growing history, so the input billed is a sum that grows with the square of the number of steps. Caching the stable prefix and trimming tool outputs attack exactly this.
Why test agents against a scripted model at all? Real models are non-deterministic and rarely misbehave on cue. A scripted model reproduces loops, bad arguments and injected instructions exactly, so the code that must handle them can be tested every time.
The papers behind this lesson
- Schick et al., Toolformer: Language Models Can Teach Themselves to Use Tools (2023): https://arxiv.org/abs/2302.04761. Showed a model can learn when to call external tools and how to use their results. Annotated companion
- Yao et al., ReAct: Synergizing Reasoning and Acting in Language Models (2022): https://arxiv.org/abs/2210.03629. The pattern of interleaving reasoning with tool calls that modern agent loops descend from. Annotated companion
Further reading
- Tool use overview: https://docs.claude.com/en/docs/agents-and-tools/tool-use/overview
- Implementing tool use: https://docs.claude.com/en/docs/agents-and-tools/tool-use/implement-tool-use
- Messages API reference: https://docs.claude.com/en/api/messages
- Python SDK: https://github.com/anthropics/anthropic-sdk-python
- Anthropic, Building effective agents: https://www.anthropic.com/engineering/building-effective-agents
1r""" 2# Talking to a model: messages, and what tool calling really is 3 4Run: `python -m primer.agents.llm` 5 6New to the notation? `primer.notation` explains every symbol used here from 7zero. This is the first lesson of the agents part: it builds on how a model 8produces text (`primer.ml.inference`), and every later agent lesson builds on 9it. 10 11## Level 1: The practitioner's guide 12 13**In one sentence.** Talking to a model means sending it the whole 14conversation so far as a list of messages and getting one message back, and 15tool calling is the case where that message is a structured request ("run 16`get_weather` with `{"city": "Paris"}`") that your code may carry out and 17answer. 18 19**When you need it.** Every system built on a language model does this, 20from a one-shot classifier to a multi-agent research team, so the message 21format is not optional. Tool calling is. You need it the moment the model 22must reach past its own weights: look something up, run a query, compute a 23number, send an email, change a record. You don't need it when the answer is 24words the model already knows, and you don't need it when one structured 25answer is enough (a label, a JSON row): that is structured output 26(`primer.ml.structured_output`), which is a tool call without the "run it and 27come back" step. The tell: if your code reads the model's prose to decide 28which function to call, or scrapes a city name out of a sentence, you need 29tool calling. The model was trained to hand you that request as data. 30 31Two facts about the exchange decide most of what follows, and both come from 32this lesson's traced example. First, the model executes nothing: the reply 33to "What's the weather in Paris?" is a `tool_use` block asking for 34`get_weather`, and the 18°C comes from your code running the function and 35sending the result back. Second, the model keeps no state between calls, so 36every call carries the whole history again. In the lesson's ten-call loop, 37that turns a conversation 7,000 tokens long into 42,500 input tokens billed. 38 39**Your options.** Five ways to get an action out of a model, from the 40cheapest to the most certain: 41 42| Option | What it does | What it guarantees | What it costs | Where it lives | 43|---|---|---|---|---| 44| A scripted stand-in | A function you write plays the model, replying by rule | The exact reply you scripted, every run, offline | Nothing per call; proves nothing about a real model | Your tests and demos | 45| A local open model, text only | Weights on your own machine answer in plain text | Privacy: nothing leaves the box; no per-token bill | Hardware, smaller models, and your own parsing if you need actions | Your machine (Ollama and similar) | 46| Text you parse | Ask the model to write the action in prose, then match it with a regular expression | Nothing; it works until the wording drifts | A parser you maintain and a retry loop | Your code | 47| Native tool calling | The model replies with a typed `tool_use` block: a name, an id, and the arguments as a parsed JSON object | A request in your schema's shape; with strict mode, exactly your schema | Tokens for the tool definitions, a tool-use system prompt the API adds (286 tokens on Claude Opus 5, per the pricing page), and one extra round trip per call | The model server produces it; your code runs it | 48| Server-side tools | The provider runs the tool (web search, web fetch, code execution) and returns the result in the same reply | The result arrives with no handler code on your side | Per-use fees on some tools (Claude's web search is \$10 per 1,000 searches) and no control over execution | The model server | 49 50**How to choose.** Start from what has to happen, and who is allowed to make 51it happen. 52 53- Testing the code around the model (a loop, a budget, an approval step): 54 the scripted stand-in. It reproduces a model that loops, calls the wrong 55 tool or follows an injected instruction on cue, which a real model rarely 56 does when you want it to. 57- Private data, no budget, or a laptop on a plane: a local open model. Keep 58 it to text unless the model and server both support tool calling (Ollama 59 does, for models trained for it; this lesson's local adapter is text only). 60- Anything a program acts on: native tool calling, never parsed prose. Turn 61 on strict mode when the arguments feed straight into code. 62- Web search or sandboxed code that you would otherwise host yourself: a 63 server-side tool, if its fees and its lack of a hook for your own checks 64 suit you. 65- Whatever you pick, your code stays the only thing that acts. Validate the 66 arguments, check permissions, then run the tool; the model only asks. 67 68**What it costs.** Input tokens are billed on the whole history, every call, 69so the cost of a loop grows with the square of its length: the lesson's ten 70calls bill 42,500 tokens, six times the 7,000-token conversation they end 71with, and the tenth call alone re-sends 6,500. At Claude Opus 5's list price 72of \$5 per million input tokens (the pricing page, fetched for this guide) 73that is about 21 cents per ten-step task before any output; on Haiku 4.5 at 74\$1 per million, about 4 cents. Prompt caching sells re-read tokens at a 75tenth of the price, which is why it is the first lever on any loop 76(`primer.agents.cost`). Tool definitions ride along on every call too, so a 77long tool list is a standing charge. Latency is one network round trip per 78model call plus the tool's own time, and a tool call always means at least 79two model calls. 80 81**What breaks.** 82 83- **Dropping the assistant turn.** Append the exact content blocks the model 84 returned, not just their text: the ids in them are how the next call 85 matches results to requests, and real APIs can include blocks (thinking) 86 that must go back unchanged. 87- **Unmatched ids.** A `tool_result` whose `tool_use_id` matches no request 88 answers nothing. Return one result per request, and all of them in a single 89 user message when the model asked for several. 90- **Swallowing failures.** A tool that throws and returns nothing leaves the 91 model waiting. Send a result flagged as an error with a message the model 92 can act on, so it can retry or ask. 93- **Trusting the request.** Arguments arrive as a parsed object in the 94 shape of your schema, not as safe values. Validate them and check 95 permissions before running anything; the model is never a security 96 boundary. 97- **Ignoring `stop_reason`.** `tool_use` means run tools and call again; 98 `end_turn` means done; `max_tokens` means the reply was cut off and its 99 JSON may be incomplete; `refusal` means the model declined. A loop that 100 checks only for text gets all four wrong. 101- **Missing arguments guessed.** Asked for the weather with no city, a model 102 may invent one rather than ask (Claude's tool-use docs call the asking 103 behaviour model-dependent and not guaranteed). Make optional what is optional, and validate the 104 rest. 105 106**In the wild.** Claude's Messages API is the shape this lesson uses 107directly: `tool_use` and `tool_result` blocks, `stop_reason`, parallel tool 108calls, `strict: true` for schema-exact arguments, and server tools (web 109search, web fetch, code execution) alongside the client tools you run. Its 110SDKs add a tool runner that drives the request, run, reply loop for you. 111OpenAI's function calling is the same five-step round trip in different 112field names, with its own strict mode; the guide recommends turning it on. 113Ollama exposes tool calling for local models, where again the model returns 114the call and your code runs it. Every agent framework, from the smallest 115loop to a multi-agent system, is built on this exchange, and the papers 116behind it (Toolformer, ReAct) are in this lesson's papers section. 117 118**Go deeper.** Level 2 traces the four messages of one tool call by hand, 119lays out the message format field by field, shows the one interface that a 120scripted model and a real one both implement, and derives the quadratic 121cost of a loop with a formula you can rerun. If you only needed to choose, 122you are done. 123 124## Level 2: How it works, from scratch 125 126Every applied-AI system in this primer, from a one-shot classifier to a 127multi-agent research team, talks to the model the same way: it sends a list 128of **messages** and gets one message back. This lesson shows that exchange 129exactly, and then the one feature that turns a chatbot into an agent: **tool 130calling**. 131 132## The everyday picture 133 134Think of the model as a brilliant consultant who works by post. You mail a 135letter with your whole conversation so far (the consultant keeps no notes 136between letters) and get one letter back. The reply is either an answer, or 137a **filled-in request form**: "please look up the weather in Paris and send me 138the result." The consultant never picks up the phone themselves. *You* decide 139whether to run the request, run it, and mail back the result, together with 140the whole conversation again. 141 142Two facts fall straight out of this picture, and they explain most of the 143behaviour of real systems: 144 1451. **The model executes nothing.** A tool call is a request. Your code is 146 the only thing that acts, so your code is where safety lives. 1472. **Every call resends everything.** The model has no memory between calls, 148 so each request carries the full history. Long conversations cost more on 149 every single turn. 150 151## A tiny worked example: one tool call, traced 152 153A user asks "What's the weather in Paris?" and the application offers one 154tool, `get_weather`. Four messages later, the user has an answer: 155 156| # | Role | Content | Who produced it | 157|---|---|---|---| 158| 1 | user | "What's the weather in Paris?" | the user | 159| 2 | assistant | `tool_use` id=`toolu_1`, name=`get_weather`, input=`{"city": "Paris"}` | the model (1st call) | 160| 3 | user | `tool_result` for `toolu_1`: "18°C, sunny" | **your code**, after running the tool | 161| 4 | assistant | "It's 18°C and sunny in Paris." | the model (2nd call) | 162 163Message 3 has role `user` even though no human typed it: tool results always 164travel back in the user's turn. The `id` in message 2 and the `tool_use_id` 165in message 3 match, which is how the model knows which request a result 166answers when it asked for several at once. `trace_tool_call_round_trip()` 167produces exactly this transcript. 168 169```mermaid 170sequenceDiagram 171 participant U as User 172 participant A as Your code 173 participant M as Model 174 participant T as get_weather tool 175 U->>A: What's the weather in Paris? 176 A->>M: messages [1] + tool definitions 177 M-->>A: tool_use get_weather {city: Paris} (stop_reason: tool_use) 178 A->>A: validate the arguments, check permissions 179 A->>T: get_weather("Paris") 180 T-->>A: 18°C, sunny 181 A->>M: messages [1, 2, 3 = tool_result] 182 M-->>A: It's 18°C and sunny in Paris. (stop_reason: end_turn) 183 A-->>U: It's 18°C and sunny in Paris. 184``` 185 186**Reading it:** time runs downwards. Solid arrows are requests and dashed 187arrows are replies. Notice that the model never talks to the tool: every 188arrow into `get_weather` starts at *your code*, and the self-arrow on your 189code ("validate, check permissions") is where production systems put their 190guardrails. Notice too that the second call to the model carries messages 1911 to 3, not just the new result: the model is stateless, so the history 192travels every time. 193 194**In code:** `ToolCall` holds the request in message 2, and 195`tool_result_block` builds the reply in message 3, carrying the matching id. 196 197## The message format 198 199Messages use the Anthropic Messages API shape directly, so what you learn 200here maps one-to-one onto production code: 201 202```python 203{"role": "user", "content": "What's our PTO policy?"} 204{"role": "assistant", "content": [ 205 {"type": "text", "text": "Let me look that up."}, 206 {"type": "tool_use", "id": "toolu_1", "name": "search_kb", "input": {"query": "PTO"}}, 207]} 208{"role": "user", "content": [ 209 {"type": "tool_result", "tool_use_id": "toolu_1", "content": "hr-001: ..."}, 210]} 211``` 212 213| Field | Meaning | 214|---|---| 215| `role` | `user` (the human, or your code returning tool results) or `assistant` (the model) | 216| `content` | a plain string, or a list of **content blocks** | 217| `text` block | ordinary words | 218| `tool_use` block | the model asking for a tool: `id`, `name`, and `input` (a JSON object matching the tool's schema) | 219| `tool_result` block | your answer to one `tool_use`, matched by `tool_use_id`; set `is_error: true` when the tool failed | 220| `stop_reason` | why the reply ended: `end_turn` (finished), `tool_use` (wants a tool), `max_tokens` (ran out of room), `refusal` (declined) | 221 222A **tool definition** is a name, a description and a JSON Schema for the 223input. The model chooses tools by reading those descriptions, so writing 224them well is prompt engineering (see `primer.agents.tools`). 225 226**In code:** `LLMResponse` is one reply, normalized: its text, its 227`ToolCall` list, its stop reason, its `Usage` and the exact content blocks 228to append as the assistant turn. `content_blocks`, `last_user_text`, 229`tool_results` and `tool_calls_so_far` read a conversation in this format. 230 231## Two implementations of one interface 232 233Every agent lesson is written against one small interface, `LLM`, with one 234method, `LLM.complete(system=..., messages=..., tools=...)`. Two classes 235implement it: 236 237```mermaid 238flowchart LR 239 L["LLM interface<br/>complete(system, messages, tools)"] 240 L --> S["ScriptedLLM<br/>a Python function decides the reply<br/>offline, instant, deterministic"] 241 L --> C["ClaudeLLM<br/>the real model via the anthropic SDK<br/>needs an API key"] 242 S --> D["demos and tests<br/>reproduce any failure on purpose"] 243 C --> P["production<br/>same agent code, real behaviour"] 244``` 245 246**Reading it:** the agent code on the right-hand side never knows which 247box it's talking to. `ScriptedLLM` lets every lesson run offline and 248deterministically, and lets tests stage a model that loops, calls the wrong 249tool or follows an injected instruction, which is hard to get a real model 250to do on cue. Swapping in `ClaudeLLM` runs the identical loop against the 251real thing. 252 253**In code:** `ClaudeLLM.complete` builds its request with `claude_request` 254and turns the API's reply into an `LLMResponse`. `OllamaLLM` is a third 255implementation for a local open model (text only), using `ollama_request` 256and `parse_ollama_reply`. 257 258## Cost: why every call pays for the whole conversation 259 260Because the model is stateless, input tokens are billed per call on the 261entire history. In an agent loop with $n$ calls, where each call adds about 262$t$ new tokens to a history that started at $h_0$ tokens, the total input 263billed is: 264 265$$ 266\text{input tokens} \approx \sum_{i=1}^{n} \left(h_0 + (i-1)\,t\right) = n\,h_0 + t\,\frac{n(n-1)}{2} 267$$ 268 269**Symbols** 270 271| Symbol | Meaning here | In the example | 272|---|---|---| 273| $n$ | number of model calls in the loop | 10 | 274| $h_0$ | tokens in the first request (system prompt, tools, question) | 2,000 | 275| $t$ | tokens each step adds (the model's tool call plus the tool's result) | 500 | 276| $i$ | which call we're on, 1 to $n$ | | 277| $\sum_{i=1}^{n}$ | add up the cost of every call | | 278| $\frac{n(n-1)}{2}$ | 0 + 1 + … + (n − 1): how many "steps of history" pile up in total | 45 | 279 280**In words:** "each call pays for the starting prompt plus everything added 281so far, so the history term grows with the square of the number of steps." 282 283**With the numbers:** 10 × 2,000 + 500 × 45 = 20,000 + 22,500 = **42,500 input 284tokens** for a task whose final conversation is only 7,000 tokens long: 285the tenth call re-sends 6,500 tokens, and its own 500-token step brings 286the history to 7,000. 287 288**In Python:** 289 290```python 291n, h_0, t = 10, 2000, 500 292# call i re-sends h_0 and i - 1 steps 293calls = [h_0 + (i - 1) * t for i in range(1, n + 1)] 294calls[0], calls[-1] # → (2000, 6500) 295# Σ over every call 296sum(calls) # → 42500 297# the shortcut on the right agrees 298n * h_0 + t * n * (n - 1) // 2 # → 42500 299``` 300 301 302 303**Reading it:** the bars are the input tokens billed on each call. They grow 304by the same amount every step, because each call re-sends the whole history. 305The line is the running total, and it curves upwards (quadratic growth). The 306dashed line is what you might naively expect: the size of the final 307conversation, billed once. The gap between the dashed line and the curve is 308why prompt caching, trimming tool outputs and keeping loops short are the 309main cost levers (`primer.agents.cost`, `primer.agents.context`). 310 311**In code:** `loop_input_tokens` lists the tokens billed on each call of 312such a loop. `estimate_tokens` is the four-characters-per-token rule of 313thumb, and `conversation_chars` measures everything a call resends, which is 314how `ScriptedLLM` gives its fake replies realistic `Usage`. 315 316## In 20 seconds 317 318- A model call sends the full list of messages and returns one message; the 319 model keeps no state between calls. 320- A tool call is a structured *request* (`tool_use`). Your code validates it, 321 runs it, and returns a `tool_result` with the matching id. The model 322 executes nothing. 323- `stop_reason` tells you what to do next: `tool_use` means run tools and 324 call again, `end_turn` means done. 325- Every call re-sends the whole history, so input cost grows quadratically 326 with the number of steps in a loop. 327 328## Self-test questions 329 330**What exactly happens when a model "uses a tool"?** 331You send tool definitions (name, description, JSON Schema) with the 332messages. The model replies with a `tool_use` block and `stop_reason: 333tool_use`. Your code validates the arguments, runs the function, and sends a 334new request with the history plus a `tool_result` block carrying the same 335id. The model then answers or asks for another tool. 336 337**Why is the model never a security boundary for tool use?** 338It only produces requests. Everything that actually happens goes through 339your code, so validation, permissions, approvals and rate limits all belong 340there, and a manipulated model can only ever ask. 341 342**The model asks for three tools in one reply. How do you send the results?** 343Run them (concurrently if independent) and return all three `tool_result` 344blocks in a single user message, each with its own `tool_use_id`. For one 345that failed, return a `tool_result` with `is_error: true` and an actionable 346message rather than dropping it. 347 348**A 20-step agent loop costs far more than 20 times a single call. Why?** 349Each call re-sends the full, growing history, so the input billed is a sum 350that grows with the square of the number of steps. Caching the stable prefix 351and trimming tool outputs attack exactly this. 352 353**Why test agents against a scripted model at all?** 354Real models are non-deterministic and rarely misbehave on cue. A scripted 355model reproduces loops, bad arguments and injected instructions exactly, so 356the code that must handle them can be tested every time. 357 358## The papers behind this lesson 359 360- **Schick et al., *Toolformer: Language Models Can Teach Themselves to Use 361 Tools* (2023)**: https://arxiv.org/abs/2302.04761. Showed a model can learn 362 when to call external tools and how to use their results. 363 [Annotated companion](../../papers/toolformer.html) 364- **Yao et al., *ReAct: Synergizing Reasoning and Acting in Language Models* 365 (2022)**: https://arxiv.org/abs/2210.03629. The pattern of interleaving 366 reasoning with tool calls that modern agent loops descend from. 367 [Annotated companion](../../papers/react.html) 368 369## Further reading 370 371- Tool use overview: https://docs.claude.com/en/docs/agents-and-tools/tool-use/overview 372- Implementing tool use: https://docs.claude.com/en/docs/agents-and-tools/tool-use/implement-tool-use 373- Messages API reference: https://docs.claude.com/en/api/messages 374- Python SDK: https://github.com/anthropics/anthropic-sdk-python 375- Anthropic, *Building effective agents*: https://www.anthropic.com/engineering/building-effective-agents 376""" 377 378from __future__ import annotations 379 380import itertools 381import json 382import math 383from dataclasses import dataclass, field 384from typing import Any, Callable, Literal, Protocol 385 386StopReason = Literal["end_turn", "tool_use", "max_tokens", "refusal"] 387 388# Default model for the real adapter. Opus 5 is the current default Claude 389# model for new code; pass `model=` to use another (e.g. "claude-haiku-4-5" 390# for cheap routing/classification steps; see primer.agents.cost). 391DEFAULT_MODEL = "claude-opus-5" 392 393 394def estimate_tokens(text: str) -> int: 395 """Rule-of-thumb token count: ~4 characters per token for English prose. 396 397 Good enough for budgeting demos. For real numbers, use the provider's 398 token-counting endpoint, since vocabularies differ between models. 399 https://docs.claude.com/en/docs/build-with-claude/token-counting 400 """ 401 return max(1, math.ceil(len(text) / 4)) 402 403 404@dataclass 405class ToolCall: 406 """One `tool_use` block: the model *asking* to run a tool.""" 407 408 id: str 409 name: str 410 input: dict[str, Any] 411 412 413@dataclass 414class Usage: 415 input_tokens: int = 0 416 output_tokens: int = 0 417 418 def __iadd__(self, other: "Usage") -> "Usage": 419 self.input_tokens += other.input_tokens 420 self.output_tokens += other.output_tokens 421 return self 422 423 424@dataclass 425class LLMResponse: 426 """What an `LLM.complete` call returns, normalized across implementations. 427 428 `assistant_content` is the exact list of content blocks to append to the 429 conversation as the assistant turn. Always append *that* (not just the 430 text): with the real API it can include thinking blocks that must be sent 431 back unchanged. 432 """ 433 434 text: str 435 tool_calls: list[ToolCall] 436 stop_reason: StopReason 437 usage: Usage 438 model: str 439 assistant_content: list[dict[str, Any]] = field(default_factory=list) 440 441 442class LLM(Protocol): 443 """The one method agents need.""" 444 445 def complete( 446 self, 447 *, 448 system: str, 449 messages: list[dict[str, Any]], 450 tools: list[dict[str, Any]] | None = None, 451 max_tokens: int = 4096, 452 ) -> LLMResponse: ... 453 454 455# ---------------------------------------------------------------------------- 456# Helpers for reading a conversation (useful inside ScriptedLLM policies) 457# ---------------------------------------------------------------------------- 458 459 460def content_blocks(message: dict[str, Any]) -> list[dict[str, Any]]: 461 """A message's content as a list of blocks (a bare string becomes one text block).""" 462 c = message["content"] 463 return [{"type": "text", "text": c}] if isinstance(c, str) else list(c) 464 465 466def last_user_text(messages: list[dict[str, Any]]) -> str: 467 """Text of the most recent user message that contains text (not just tool results).""" 468 for m in reversed(messages): 469 if m["role"] != "user": 470 continue 471 texts = [b["text"] for b in content_blocks(m) if b.get("type") == "text"] 472 if texts: 473 return "\n".join(texts) 474 return "" 475 476 477def tool_results(messages: list[dict[str, Any]]) -> list[dict[str, Any]]: 478 """All `tool_result` blocks in the conversation, oldest first.""" 479 return [b for m in messages if m["role"] == "user" for b in content_blocks(m) if b.get("type") == "tool_result"] 480 481 482def tool_calls_so_far(messages: list[dict[str, Any]]) -> list[dict[str, Any]]: 483 """All `tool_use` blocks the assistant has emitted, oldest first.""" 484 return [b for m in messages if m["role"] == "assistant" for b in content_blocks(m) if b.get("type") == "tool_use"] 485 486 487def conversation_chars(system: str, messages: list[dict[str, Any]], tools: list[dict[str, Any]] | None) -> int: 488 """Rough size of everything sent to the model (for token estimates).""" 489 return len(system) + len(json.dumps(messages, default=str)) + len(json.dumps(tools or [])) 490 491 492# ---------------------------------------------------------------------------- 493# ScriptedLLM: deterministic offline "model" 494# ---------------------------------------------------------------------------- 495 496# A policy decides the next assistant turn. It returns either: 497# * a string -> final text answer (stop_reason end_turn) 498# * a ToolCall or list[ToolCall] -> tool request(s) (stop_reason tool_use) 499# * (text, [ToolCall, ...]) -> text plus tool requests 500# * an LLMResponse -> used as-is (e.g. to simulate a refusal) 501PolicyResult = Any 502Policy = Callable[[str, list[dict[str, Any]], list[dict[str, Any]] | None], PolicyResult] 503 504 505class ScriptedLLM: 506 """A fake LLM driven by a Python function, for offline demos and tests. 507 508 Examples: 509 >>> def policy(system, messages, tools): 510 ... if not tool_results(messages): 511 ... return ToolCall("t1", "get_time", {}) 512 ... return "It is " + tool_results(messages)[-1]["content"] 513 >>> llm = ScriptedLLM(policy) 514 >>> r = llm.complete(system="", messages=[{"role": "user", "content": "time?"}]) 515 >>> r.stop_reason, r.tool_calls[0].name 516 ('tool_use', 'get_time') 517 518 Token usage is *estimated* from characters so cost demos have realistic 519 shapes: input grows with the whole conversation each call, which is the 520 single most important cost fact about agent loops. 521 """ 522 523 def __init__(self, policy: Policy | list[PolicyResult], model: str = "scripted-large"): 524 if isinstance(policy, list): 525 # A fixed script: return each item in turn, repeating the last one. 526 script = list(policy) 527 counter = itertools.count() 528 529 def policy_fn(system, messages, tools): # noqa: ARG001 530 return script[min(next(counter), len(script) - 1)] 531 532 self.policy: Policy = policy_fn 533 else: 534 self.policy = policy 535 self.model = model 536 self.calls = 0 537 self.total_usage = Usage() 538 self._ids = itertools.count(1) 539 540 def complete(self, *, system, messages, tools=None, max_tokens=4096) -> LLMResponse: # noqa: ARG002 541 self.calls += 1 542 out = self.policy(system, messages, tools) 543 if isinstance(out, LLMResponse): 544 self.total_usage += out.usage 545 return out 546 547 text, calls = "", [] 548 if isinstance(out, str): 549 text = out 550 elif isinstance(out, ToolCall): 551 calls = [out] 552 elif isinstance(out, tuple): 553 text, calls = out 554 elif isinstance(out, list): 555 calls = out 556 else: 557 raise TypeError(f"policy returned unsupported {type(out).__name__}") 558 559 # Give tool calls unique ids if the policy didn't bother. 560 calls = [c if c.id else ToolCall(f"toolu_{next(self._ids)}", c.name, c.input) for c in calls] 561 562 blocks: list[dict[str, Any]] = [] 563 if text: 564 blocks.append({"type": "text", "text": text}) 565 blocks += [{"type": "tool_use", "id": c.id, "name": c.name, "input": c.input} for c in calls] 566 567 usage = Usage( 568 input_tokens=estimate_tokens("x" * conversation_chars(system, messages, tools)), 569 output_tokens=estimate_tokens(json.dumps(blocks)), 570 ) 571 self.total_usage += usage 572 return LLMResponse( 573 text=text, 574 tool_calls=calls, 575 stop_reason="tool_use" if calls else "end_turn", 576 usage=usage, 577 model=self.model, 578 assistant_content=blocks, 579 ) 580 581 582# ---------------------------------------------------------------------------- 583# ClaudeLLM: the real model via the Anthropic SDK 584# ---------------------------------------------------------------------------- 585 586 587class ClaudeLLM: 588 """Adapter from the `LLM` interface to the Anthropic Messages API. 589 590 Requires `pip install anthropic` and credentials (`ANTHROPIC_API_KEY`, or 591 `ant auth login`). Nothing else in this repo needs it. 592 593 Args: 594 model: model id, default `claude-opus-5`. 595 fallbacks: when True (default), opts into server-side refusal 596 fallbacks, so if a safety classifier declines the request the API 597 retries on a fallback model instead of returning 598 `stop_reason == "refusal"`. Set False if your account or proxy 599 rejects the beta header. We still check for `"refusal"` either way. 600 601 Notes: 602 * Adaptive thinking is on by default for Opus 5. The response may 603 contain `thinking` blocks; `assistant_content` preserves them so the 604 agent loop can send them back unchanged, as the API requires. 605 * Tool inputs are parsed JSON dicts, never raw strings. Don't 606 string-match serialized input. 607 """ 608 609 def __init__(self, model: str = DEFAULT_MODEL, fallbacks: bool = True, effort: str | None = None): 610 import anthropic # imported lazily so the rest of the repo has no hard dependency 611 612 self._anthropic = anthropic 613 self.client = anthropic.Anthropic() 614 self.model = model 615 self.fallbacks = fallbacks 616 self.effort = effort 617 618 def complete(self, *, system, messages, tools=None, max_tokens=16000) -> LLMResponse: 619 kwargs = claude_request( 620 model=self.model, system=system, messages=messages, tools=tools, 621 max_tokens=max_tokens, effort=self.effort, fallbacks=self.fallbacks, 622 ) 623 resp = self.client.messages.create(**kwargs) 624 625 blocks = [b.model_dump(exclude_none=True) for b in resp.content] 626 text = "".join(b.text for b in resp.content if b.type == "text") 627 calls = [ToolCall(b.id, b.name, dict(b.input)) for b in resp.content if b.type == "tool_use"] 628 stop = resp.stop_reason if resp.stop_reason in ("end_turn", "tool_use", "max_tokens", "refusal") else "end_turn" 629 return LLMResponse( 630 text=text, 631 tool_calls=calls, 632 stop_reason=stop, # type: ignore[arg-type] 633 usage=Usage(resp.usage.input_tokens, resp.usage.output_tokens), 634 model=resp.model, 635 assistant_content=blocks, 636 ) 637 638 639def claude_request(*, model, system, messages, tools, max_tokens, effort, fallbacks) -> dict[str, Any]: 640 """The keyword arguments for `client.messages.create`, built without touching the network. 641 642 `effort` ("low" to "max") trades thinking depth for speed and cost. Low suits 643 short, grounded tasks such as a two-sentence explanation, where default-depth 644 thinking could spend a small `max_tokens` cap before writing any text. 645 """ 646 kwargs: dict[str, Any] = dict(model=model, max_tokens=max_tokens, system=system, messages=messages) 647 if tools: 648 kwargs["tools"] = tools 649 extra_body: dict[str, Any] = {} 650 if fallbacks: 651 # Server-side refusal fallback (beta): route by refusal category. 652 kwargs["extra_headers"] = {"anthropic-beta": "server-side-fallback-2026-07-01"} 653 extra_body["fallbacks"] = "default" 654 if effort: 655 extra_body["output_config"] = {"effort": effort} 656 if extra_body: 657 kwargs["extra_body"] = extra_body 658 return kwargs 659 660 661# ---------------------------------------------------------------------------- 662# OllamaLLM: an open model running on your own machine 663# ---------------------------------------------------------------------------- 664 665OLLAMA_HOST = "http://127.0.0.1:11434" 666 667 668def _plain_text(content: Any) -> str: 669 """Ollama messages carry plain strings; join the text of any content blocks.""" 670 if isinstance(content, str): 671 return content 672 return "\n".join(b.get("text", "") or str(b.get("content", "")) for b in content if isinstance(b, dict)) 673 674 675def ollama_request(*, model: str, system: str, messages: list[dict[str, Any]], max_tokens: int, 676 temperature: float = 0.2, keep_alive: str = "30m") -> dict[str, Any]: 677 """The JSON body for Ollama's /api/chat, built without touching the network. 678 679 `think: False` matters: some small open models "think out loud" by default and 680 would spend the whole token budget reasoning instead of answering. 681 `keep_alive` keeps the weights in memory between calls, so only the first 682 call pays to load them. 683 """ 684 msgs = ([{"role": "system", "content": system}] if system else []) + [ 685 {"role": m["role"], "content": _plain_text(m["content"])} for m in messages 686 ] 687 return { 688 "model": model, 689 "messages": msgs, 690 "stream": False, 691 "think": False, 692 "keep_alive": keep_alive, 693 "options": {"temperature": temperature, "num_predict": max_tokens}, 694 } 695 696 697def parse_ollama_reply(data: dict[str, Any]) -> LLMResponse: 698 """Normalize Ollama's /api/chat reply into an `LLMResponse`.""" 699 text = (data.get("message") or {}).get("content", "").strip() 700 stop: StopReason = "max_tokens" if data.get("done_reason") == "length" else "end_turn" 701 return LLMResponse( 702 text=text, 703 tool_calls=[], 704 stop_reason=stop, 705 usage=Usage(data.get("prompt_eval_count", 0), data.get("eval_count", 0)), 706 model=data.get("model", ""), 707 assistant_content=[{"type": "text", "text": text}] if text else [], 708 ) 709 710 711class OllamaLLM: 712 """Adapter from the `LLM` interface to a local model served by Ollama. 713 714 Free, private and offline: nothing leaves your machine. Text only (no tool 715 calling here). Start Ollama and download the model first 716 (`ollama pull qwen3:1.7b`). 717 """ 718 719 def __init__(self, model: str = "qwen3:1.7b", host: str = OLLAMA_HOST, temperature: float = 0.2): 720 self.model, self.host, self.temperature = model, host, temperature 721 722 def complete(self, *, system, messages, tools=None, max_tokens=300) -> LLMResponse: 723 import urllib.request 724 725 if tools: 726 raise NotImplementedError("OllamaLLM here handles text only; use ClaudeLLM for tool calling") 727 body = ollama_request(model=self.model, system=system, messages=messages, 728 max_tokens=max_tokens, temperature=self.temperature) 729 req = urllib.request.Request(f"{self.host}/api/chat", json.dumps(body).encode(), {"Content-Type": "application/json"}) 730 with urllib.request.urlopen(req, timeout=120) as r: 731 return parse_ollama_reply(json.load(r)) 732 733 734def tool_result_block(tool_use_id: str, content: str, is_error: bool = False) -> dict[str, Any]: 735 """Build a `tool_result` block. On failure, set `is_error=True` with an 736 actionable message the model can use to fix its next call.""" 737 block: dict[str, Any] = {"type": "tool_result", "tool_use_id": tool_use_id, "content": content} 738 if is_error: 739 block["is_error"] = True 740 return block 741 742 743# ---------------------------------------------------------------------------- 744# The worked example, as code 745# ---------------------------------------------------------------------------- 746 747WEATHER_TOOL = { 748 "name": "get_weather", 749 "description": "Current weather for a city. Use for any question about today's weather.", 750 "input_schema": {"type": "object", "properties": {"city": {"type": "string"}}, "required": ["city"]}, 751} 752 753 754def _get_weather(city: str) -> str: 755 return {"paris": "18°C, sunny"}.get(city.lower(), "no data") 756 757 758def trace_tool_call_round_trip() -> list[dict[str, Any]]: 759 """Run the lesson's worked example and return the full transcript (4 messages).""" 760 761 def policy(system, messages, tools): 762 results = tool_results(messages) 763 if not results: # first call: ask for the tool 764 return ToolCall("", "get_weather", {"city": "Paris"}) 765 return f"It's {results[-1]['content'].replace(', ', ' and ')} in Paris." 766 767 llm = ScriptedLLM(policy) 768 messages: list[dict[str, Any]] = [{"role": "user", "content": "What's the weather in Paris?"}] 769 while True: 770 reply = llm.complete(system="You are helpful.", messages=messages, tools=[WEATHER_TOOL]) 771 messages.append({"role": "assistant", "content": reply.assistant_content}) 772 if reply.stop_reason != "tool_use": 773 return messages 774 # Your code, not the model, runs the tool. 775 messages.append( 776 {"role": "user", "content": [tool_result_block(c.id, _get_weather(**c.input)) for c in reply.tool_calls]} 777 ) 778 779 780def loop_input_tokens(n_calls: int, first: int, per_step: int) -> list[int]: 781 """Input tokens billed on each call of a loop that re-sends its growing history.""" 782 return [first + i * per_step for i in range(n_calls)] 783 784 785def figures() -> dict: 786 import matplotlib 787 788 matplotlib.use("Agg") 789 import matplotlib.pyplot as plt 790 import numpy as np 791 792 per_call = loop_input_tokens(10, 2000, 500) 793 fig, ax = plt.subplots(figsize=(6.4, 3.8)) 794 x = np.arange(1, 11) 795 ax.bar(x, per_call, color="#93c5fd", label="input tokens billed on this call") 796 ax.plot(x, np.cumsum(per_call), "o-", color="#2563eb", label="running total") 797 ax.axhline(per_call[-1] + 500, ls="--", color="#9ca3af", label="final conversation size (billed once?)") 798 ax.set_xlabel("model call in the loop") 799 ax.set_ylabel("input tokens") 800 ax.set_title("Every call re-sends the whole history") 801 ax.legend(frameon=False) 802 return {"loop_tokens": fig} 803 804 805def demo() -> None: 806 from primer._show import banner, say, table, takeaway 807 808 banner("1. One tool call, traced message by message") 809 for i, m in enumerate(trace_tool_call_round_trip(), 1): 810 for b in content_blocks(m): 811 detail = b.get("text") or (f"{b['name']}({b['input']}) id={b['id']}" if b["type"] == "tool_use" else f"result for {b['tool_use_id']}: {b['content']}") 812 print(f" {i}. {m['role']:9s} {b['type']:11s} {detail}") 813 print() 814 takeaway("The model asked; your code ran the tool; the model answered. The model executed nothing.") 815 816 banner("2. Every call pays for the whole conversation") 817 per_call = loop_input_tokens(10, 2000, 500) 818 table(["call", "input tokens", "running total"], [(i + 1, t, sum(per_call[: i + 1])) for i, t in enumerate(per_call)]) 819 say("10 calls bill 42,500 input tokens for a conversation that ends 7,000 tokens long.") 820 821 822if __name__ == "__main__": 823 demo()
395def estimate_tokens(text: str) -> int:
396    """Rule-of-thumb token count: ~4 characters per token for English prose.
397
398    Good enough for budgeting demos. For real numbers, use the provider's
399    token-counting endpoint, since vocabularies differ between models.
400    https://docs.claude.com/en/docs/build-with-claude/token-counting
401    """
402    return max(1, math.ceil(len(text) / 4))
Rule-of-thumb token count: ~4 characters per token for English prose.
Good enough for budgeting demos. For real numbers, use the provider's token-counting endpoint, since vocabularies differ between models. https://docs.claude.com/en/docs/build-with-claude/token-counting
405@dataclass
406class ToolCall:
407    """One `tool_use` block: the model *asking* to run a tool."""
408
409    id: str
410    name: str
411    input: dict[str, Any]
One tool_use block: the model asking to run a tool.
414@dataclass
415class Usage:
416    input_tokens: int = 0
417    output_tokens: int = 0
418
419    def __iadd__(self, other: "Usage") -> "Usage":
420        self.input_tokens += other.input_tokens
421        self.output_tokens += other.output_tokens
422        return self
425@dataclass
426class LLMResponse:
427    """What an `LLM.complete` call returns, normalized across implementations.
428
429    `assistant_content` is the exact list of content blocks to append to the
430    conversation as the assistant turn. Always append *that* (not just the
431    text): with the real API it can include thinking blocks that must be sent
432    back unchanged.
433    """
434
435    text: str
436    tool_calls: list[ToolCall]
437    stop_reason: StopReason
438    usage: Usage
439    model: str
440    assistant_content: list[dict[str, Any]] = field(default_factory=list)
What an LLM.complete call returns, normalized across implementations.
assistant_content is the exact list of content blocks to append to the
conversation as the assistant turn. Always append that (not just the
text): with the real API it can include thinking blocks that must be sent
back unchanged.
443class LLM(Protocol):
444    """The one method agents need."""
445
446    def complete(
447        self,
448        *,
449        system: str,
450        messages: list[dict[str, Any]],
451        tools: list[dict[str, Any]] | None = None,
452        max_tokens: int = 4096,
453    ) -> LLMResponse: ...
The one method agents need.
1771def _no_init_or_replace_init(self, *args, **kwargs):
1772    cls = type(self)
1773
1774    if cls._is_protocol:
1775        raise TypeError('Protocols cannot be instantiated')
1776
1777    # Already using a custom `__init__`. No need to calculate correct
1778    # `__init__` to call. This can lead to RecursionError. See bpo-45121.
1779    if cls.__init__ is not _no_init_or_replace_init:
1780        return
1781
1782    # Initially, `__init__` of a protocol subclass is set to `_no_init_or_replace_init`.
1783    # The first instantiation of the subclass will call `_no_init_or_replace_init` which
1784    # searches for a proper new `__init__` in the MRO. The new `__init__`
1785    # replaces the subclass' old `__init__` (ie `_no_init_or_replace_init`). Subsequent
1786    # instantiation of the protocol subclass will thus use the new
1787    # `__init__` and no longer call `_no_init_or_replace_init`.
1788    for base in cls.__mro__:
1789        init = base.__dict__.get('__init__', _no_init_or_replace_init)
1790        if init is not _no_init_or_replace_init:
1791            cls.__init__ = init
1792            break
1793    else:
1794        # should not happen
1795        cls.__init__ = object.__init__
1796
1797    cls.__init__(self, *args, **kwargs)
461def content_blocks(message: dict[str, Any]) -> list[dict[str, Any]]:
462    """A message's content as a list of blocks (a bare string becomes one text block)."""
463    c = message["content"]
464    return [{"type": "text", "text": c}] if isinstance(c, str) else list(c)
A message's content as a list of blocks (a bare string becomes one text block).
467def last_user_text(messages: list[dict[str, Any]]) -> str:
468    """Text of the most recent user message that contains text (not just tool results)."""
469    for m in reversed(messages):
470        if m["role"] != "user":
471            continue
472        texts = [b["text"] for b in content_blocks(m) if b.get("type") == "text"]
473        if texts:
474            return "\n".join(texts)
475    return ""
Text of the most recent user message that contains text (not just tool results).
478def tool_results(messages: list[dict[str, Any]]) -> list[dict[str, Any]]:
479    """All `tool_result` blocks in the conversation, oldest first."""
480    return [b for m in messages if m["role"] == "user" for b in content_blocks(m) if b.get("type") == "tool_result"]
All tool_result blocks in the conversation, oldest first.
483def tool_calls_so_far(messages: list[dict[str, Any]]) -> list[dict[str, Any]]:
484    """All `tool_use` blocks the assistant has emitted, oldest first."""
485    return [b for m in messages if m["role"] == "assistant" for b in content_blocks(m) if b.get("type") == "tool_use"]
All tool_use blocks the assistant has emitted, oldest first.
488def conversation_chars(system: str, messages: list[dict[str, Any]], tools: list[dict[str, Any]] | None) -> int:
489    """Rough size of everything sent to the model (for token estimates)."""
490    return len(system) + len(json.dumps(messages, default=str)) + len(json.dumps(tools or []))
Rough size of everything sent to the model (for token estimates).
506class ScriptedLLM:
507    """A fake LLM driven by a Python function, for offline demos and tests.
508
509    Examples:
510        >>> def policy(system, messages, tools):
511        ...     if not tool_results(messages):
512        ...         return ToolCall("t1", "get_time", {})
513        ...     return "It is " + tool_results(messages)[-1]["content"]
514        >>> llm = ScriptedLLM(policy)
515        >>> r = llm.complete(system="", messages=[{"role": "user", "content": "time?"}])
516        >>> r.stop_reason, r.tool_calls[0].name
517        ('tool_use', 'get_time')
518
519    Token usage is *estimated* from characters so cost demos have realistic
520    shapes: input grows with the whole conversation each call, which is the
521    single most important cost fact about agent loops.
522    """
523
524    def __init__(self, policy: Policy | list[PolicyResult], model: str = "scripted-large"):
525        if isinstance(policy, list):
526            # A fixed script: return each item in turn, repeating the last one.
527            script = list(policy)
528            counter = itertools.count()
529
530            def policy_fn(system, messages, tools):  # noqa: ARG001
531                return script[min(next(counter), len(script) - 1)]
532
533            self.policy: Policy = policy_fn
534        else:
535            self.policy = policy
536        self.model = model
537        self.calls = 0
538        self.total_usage = Usage()
539        self._ids = itertools.count(1)
540
541    def complete(self, *, system, messages, tools=None, max_tokens=4096) -> LLMResponse:  # noqa: ARG002
542        self.calls += 1
543        out = self.policy(system, messages, tools)
544        if isinstance(out, LLMResponse):
545            self.total_usage += out.usage
546            return out
547
548        text, calls = "", []
549        if isinstance(out, str):
550            text = out
551        elif isinstance(out, ToolCall):
552            calls = [out]
553        elif isinstance(out, tuple):
554            text, calls = out
555        elif isinstance(out, list):
556            calls = out
557        else:
558            raise TypeError(f"policy returned unsupported {type(out).__name__}")
559
560        # Give tool calls unique ids if the policy didn't bother.
561        calls = [c if c.id else ToolCall(f"toolu_{next(self._ids)}", c.name, c.input) for c in calls]
562
563        blocks: list[dict[str, Any]] = []
564        if text:
565            blocks.append({"type": "text", "text": text})
566        blocks += [{"type": "tool_use", "id": c.id, "name": c.name, "input": c.input} for c in calls]
567
568        usage = Usage(
569            input_tokens=estimate_tokens("x" * conversation_chars(system, messages, tools)),
570            output_tokens=estimate_tokens(json.dumps(blocks)),
571        )
572        self.total_usage += usage
573        return LLMResponse(
574            text=text,
575            tool_calls=calls,
576            stop_reason="tool_use" if calls else "end_turn",
577            usage=usage,
578            model=self.model,
579            assistant_content=blocks,
580        )
A fake LLM driven by a Python function, for offline demos and tests.
Examples:
>>> def policy(system, messages, tools):
...     if not tool_results(messages):
...         return ToolCall("t1", "get_time", {})
...     return "It is " + tool_results(messages)[-1]["content"]
>>> llm = ScriptedLLM(policy)
>>> r = llm.complete(system="", messages=[{"role": "user", "content": "time?"}])
>>> r.stop_reason, r.tool_calls[0].name
('tool_use', 'get_time')
Token usage is estimated from characters so cost demos have realistic shapes: input grows with the whole conversation each call, which is the single most important cost fact about agent loops.
524    def __init__(self, policy: Policy | list[PolicyResult], model: str = "scripted-large"):
525        if isinstance(policy, list):
526            # A fixed script: return each item in turn, repeating the last one.
527            script = list(policy)
528            counter = itertools.count()
529
530            def policy_fn(system, messages, tools):  # noqa: ARG001
531                return script[min(next(counter), len(script) - 1)]
532
533            self.policy: Policy = policy_fn
534        else:
535            self.policy = policy
536        self.model = model
537        self.calls = 0
538        self.total_usage = Usage()
539        self._ids = itertools.count(1)
541    def complete(self, *, system, messages, tools=None, max_tokens=4096) -> LLMResponse:  # noqa: ARG002
542        self.calls += 1
543        out = self.policy(system, messages, tools)
544        if isinstance(out, LLMResponse):
545            self.total_usage += out.usage
546            return out
547
548        text, calls = "", []
549        if isinstance(out, str):
550            text = out
551        elif isinstance(out, ToolCall):
552            calls = [out]
553        elif isinstance(out, tuple):
554            text, calls = out
555        elif isinstance(out, list):
556            calls = out
557        else:
558            raise TypeError(f"policy returned unsupported {type(out).__name__}")
559
560        # Give tool calls unique ids if the policy didn't bother.
561        calls = [c if c.id else ToolCall(f"toolu_{next(self._ids)}", c.name, c.input) for c in calls]
562
563        blocks: list[dict[str, Any]] = []
564        if text:
565            blocks.append({"type": "text", "text": text})
566        blocks += [{"type": "tool_use", "id": c.id, "name": c.name, "input": c.input} for c in calls]
567
568        usage = Usage(
569            input_tokens=estimate_tokens("x" * conversation_chars(system, messages, tools)),
570            output_tokens=estimate_tokens(json.dumps(blocks)),
571        )
572        self.total_usage += usage
573        return LLMResponse(
574            text=text,
575            tool_calls=calls,
576            stop_reason="tool_use" if calls else "end_turn",
577            usage=usage,
578            model=self.model,
579            assistant_content=blocks,
580        )
588class ClaudeLLM:
589    """Adapter from the `LLM` interface to the Anthropic Messages API.
590
591    Requires `pip install anthropic` and credentials (`ANTHROPIC_API_KEY`, or
592    `ant auth login`). Nothing else in this repo needs it.
593
594    Args:
595        model: model id, default `claude-opus-5`.
596        fallbacks: when True (default), opts into server-side refusal
597            fallbacks, so if a safety classifier declines the request the API
598            retries on a fallback model instead of returning
599            `stop_reason == "refusal"`. Set False if your account or proxy
600            rejects the beta header. We still check for `"refusal"` either way.
601
602    Notes:
603        * Adaptive thinking is on by default for Opus 5. The response may
604          contain `thinking` blocks; `assistant_content` preserves them so the
605          agent loop can send them back unchanged, as the API requires.
606        * Tool inputs are parsed JSON dicts, never raw strings. Don't
607          string-match serialized input.
608    """
609
610    def __init__(self, model: str = DEFAULT_MODEL, fallbacks: bool = True, effort: str | None = None):
611        import anthropic  # imported lazily so the rest of the repo has no hard dependency
612
613        self._anthropic = anthropic
614        self.client = anthropic.Anthropic()
615        self.model = model
616        self.fallbacks = fallbacks
617        self.effort = effort
618
619    def complete(self, *, system, messages, tools=None, max_tokens=16000) -> LLMResponse:
620        kwargs = claude_request(
621            model=self.model, system=system, messages=messages, tools=tools,
622            max_tokens=max_tokens, effort=self.effort, fallbacks=self.fallbacks,
623        )
624        resp = self.client.messages.create(**kwargs)
625
626        blocks = [b.model_dump(exclude_none=True) for b in resp.content]
627        text = "".join(b.text for b in resp.content if b.type == "text")
628        calls = [ToolCall(b.id, b.name, dict(b.input)) for b in resp.content if b.type == "tool_use"]
629        stop = resp.stop_reason if resp.stop_reason in ("end_turn", "tool_use", "max_tokens", "refusal") else "end_turn"
630        return LLMResponse(
631            text=text,
632            tool_calls=calls,
633            stop_reason=stop,  # type: ignore[arg-type]
634            usage=Usage(resp.usage.input_tokens, resp.usage.output_tokens),
635            model=resp.model,
636            assistant_content=blocks,
637        )
Adapter from the LLM interface to the Anthropic Messages API.
Requires pip install anthropic and credentials (ANTHROPIC_API_KEY, or
ant auth login). Nothing else in this repo needs it.
Arguments:
- model: model id, default
claude-opus-5. - fallbacks: when True (default), opts into server-side refusal
fallbacks, so if a safety classifier declines the request the API
retries on a fallback model instead of returning
stop_reason == "refusal". Set False if your account or proxy rejects the beta header. We still check for"refusal"either way.
Notes:
- Adaptive thinking is on by default for Opus 5. The response may contain
thinkingblocks;assistant_contentpreserves them so the agent loop can send them back unchanged, as the API requires.- Tool inputs are parsed JSON dicts, never raw strings. Don't string-match serialized input.
610    def __init__(self, model: str = DEFAULT_MODEL, fallbacks: bool = True, effort: str | None = None):
611        import anthropic  # imported lazily so the rest of the repo has no hard dependency
612
613        self._anthropic = anthropic
614        self.client = anthropic.Anthropic()
615        self.model = model
616        self.fallbacks = fallbacks
617        self.effort = effort
619    def complete(self, *, system, messages, tools=None, max_tokens=16000) -> LLMResponse:
620        kwargs = claude_request(
621            model=self.model, system=system, messages=messages, tools=tools,
622            max_tokens=max_tokens, effort=self.effort, fallbacks=self.fallbacks,
623        )
624        resp = self.client.messages.create(**kwargs)
625
626        blocks = [b.model_dump(exclude_none=True) for b in resp.content]
627        text = "".join(b.text for b in resp.content if b.type == "text")
628        calls = [ToolCall(b.id, b.name, dict(b.input)) for b in resp.content if b.type == "tool_use"]
629        stop = resp.stop_reason if resp.stop_reason in ("end_turn", "tool_use", "max_tokens", "refusal") else "end_turn"
630        return LLMResponse(
631            text=text,
632            tool_calls=calls,
633            stop_reason=stop,  # type: ignore[arg-type]
634            usage=Usage(resp.usage.input_tokens, resp.usage.output_tokens),
635            model=resp.model,
636            assistant_content=blocks,
637        )
640def claude_request(*, model, system, messages, tools, max_tokens, effort, fallbacks) -> dict[str, Any]:
641    """The keyword arguments for `client.messages.create`, built without touching the network.
642
643    `effort` ("low" to "max") trades thinking depth for speed and cost. Low suits
644    short, grounded tasks such as a two-sentence explanation, where default-depth
645    thinking could spend a small `max_tokens` cap before writing any text.
646    """
647    kwargs: dict[str, Any] = dict(model=model, max_tokens=max_tokens, system=system, messages=messages)
648    if tools:
649        kwargs["tools"] = tools
650    extra_body: dict[str, Any] = {}
651    if fallbacks:
652        # Server-side refusal fallback (beta): route by refusal category.
653        kwargs["extra_headers"] = {"anthropic-beta": "server-side-fallback-2026-07-01"}
654        extra_body["fallbacks"] = "default"
655    if effort:
656        extra_body["output_config"] = {"effort": effort}
657    if extra_body:
658        kwargs["extra_body"] = extra_body
659    return kwargs
The keyword arguments for client.messages.create, built without touching the network.
effort ("low" to "max") trades thinking depth for speed and cost. Low suits
short, grounded tasks such as a two-sentence explanation, where default-depth
thinking could spend a small max_tokens cap before writing any text.
676def ollama_request(*, model: str, system: str, messages: list[dict[str, Any]], max_tokens: int,
677                   temperature: float = 0.2, keep_alive: str = "30m") -> dict[str, Any]:
678    """The JSON body for Ollama's /api/chat, built without touching the network.
679
680    `think: False` matters: some small open models "think out loud" by default and
681    would spend the whole token budget reasoning instead of answering.
682    `keep_alive` keeps the weights in memory between calls, so only the first
683    call pays to load them.
684    """
685    msgs = ([{"role": "system", "content": system}] if system else []) + [
686        {"role": m["role"], "content": _plain_text(m["content"])} for m in messages
687    ]
688    return {
689        "model": model,
690        "messages": msgs,
691        "stream": False,
692        "think": False,
693        "keep_alive": keep_alive,
694        "options": {"temperature": temperature, "num_predict": max_tokens},
695    }
The JSON body for Ollama's /api/chat, built without touching the network.
think: False matters: some small open models "think out loud" by default and
would spend the whole token budget reasoning instead of answering.
keep_alive keeps the weights in memory between calls, so only the first
call pays to load them.
698def parse_ollama_reply(data: dict[str, Any]) -> LLMResponse:
699    """Normalize Ollama's /api/chat reply into an `LLMResponse`."""
700    text = (data.get("message") or {}).get("content", "").strip()
701    stop: StopReason = "max_tokens" if data.get("done_reason") == "length" else "end_turn"
702    return LLMResponse(
703        text=text,
704        tool_calls=[],
705        stop_reason=stop,
706        usage=Usage(data.get("prompt_eval_count", 0), data.get("eval_count", 0)),
707        model=data.get("model", ""),
708        assistant_content=[{"type": "text", "text": text}] if text else [],
709    )
Normalize Ollama's /api/chat reply into an LLMResponse.
712class OllamaLLM:
713    """Adapter from the `LLM` interface to a local model served by Ollama.
714
715    Free, private and offline: nothing leaves your machine. Text only (no tool
716    calling here). Start Ollama and download the model first
717    (`ollama pull qwen3:1.7b`).
718    """
719
720    def __init__(self, model: str = "qwen3:1.7b", host: str = OLLAMA_HOST, temperature: float = 0.2):
721        self.model, self.host, self.temperature = model, host, temperature
722
723    def complete(self, *, system, messages, tools=None, max_tokens=300) -> LLMResponse:
724        import urllib.request
725
726        if tools:
727            raise NotImplementedError("OllamaLLM here handles text only; use ClaudeLLM for tool calling")
728        body = ollama_request(model=self.model, system=system, messages=messages,
729                              max_tokens=max_tokens, temperature=self.temperature)
730        req = urllib.request.Request(f"{self.host}/api/chat", json.dumps(body).encode(), {"Content-Type": "application/json"})
731        with urllib.request.urlopen(req, timeout=120) as r:
732            return parse_ollama_reply(json.load(r))
Adapter from the LLM interface to a local model served by Ollama.
Free, private and offline: nothing leaves your machine. Text only (no tool
calling here). Start Ollama and download the model first
(ollama pull qwen3:1.7b).
723    def complete(self, *, system, messages, tools=None, max_tokens=300) -> LLMResponse:
724        import urllib.request
725
726        if tools:
727            raise NotImplementedError("OllamaLLM here handles text only; use ClaudeLLM for tool calling")
728        body = ollama_request(model=self.model, system=system, messages=messages,
729                              max_tokens=max_tokens, temperature=self.temperature)
730        req = urllib.request.Request(f"{self.host}/api/chat", json.dumps(body).encode(), {"Content-Type": "application/json"})
731        with urllib.request.urlopen(req, timeout=120) as r:
732            return parse_ollama_reply(json.load(r))
735def tool_result_block(tool_use_id: str, content: str, is_error: bool = False) -> dict[str, Any]:
736    """Build a `tool_result` block. On failure, set `is_error=True` with an
737    actionable message the model can use to fix its next call."""
738    block: dict[str, Any] = {"type": "tool_result", "tool_use_id": tool_use_id, "content": content}
739    if is_error:
740        block["is_error"] = True
741    return block
Build a tool_result block. On failure, set is_error=True with an
actionable message the model can use to fix its next call.
759def trace_tool_call_round_trip() -> list[dict[str, Any]]:
760    """Run the lesson's worked example and return the full transcript (4 messages)."""
761
762    def policy(system, messages, tools):
763        results = tool_results(messages)
764        if not results:  # first call: ask for the tool
765            return ToolCall("", "get_weather", {"city": "Paris"})
766        return f"It's {results[-1]['content'].replace(', ', ' and ')} in Paris."
767
768    llm = ScriptedLLM(policy)
769    messages: list[dict[str, Any]] = [{"role": "user", "content": "What's the weather in Paris?"}]
770    while True:
771        reply = llm.complete(system="You are helpful.", messages=messages, tools=[WEATHER_TOOL])
772        messages.append({"role": "assistant", "content": reply.assistant_content})
773        if reply.stop_reason != "tool_use":
774            return messages
775        # Your code, not the model, runs the tool.
776        messages.append(
777            {"role": "user", "content": [tool_result_block(c.id, _get_weather(**c.input)) for c in reply.tool_calls]}
778        )
Run the lesson's worked example and return the full transcript (4 messages).
781def loop_input_tokens(n_calls: int, first: int, per_step: int) -> list[int]:
782    """Input tokens billed on each call of a loop that re-sends its growing history."""
783    return [first + i * per_step for i in range(n_calls)]
Input tokens billed on each call of a loop that re-sends its growing history.
786def figures() -> dict:
787    import matplotlib
788
789    matplotlib.use("Agg")
790    import matplotlib.pyplot as plt
791    import numpy as np
792
793    per_call = loop_input_tokens(10, 2000, 500)
794    fig, ax = plt.subplots(figsize=(6.4, 3.8))
795    x = np.arange(1, 11)
796    ax.bar(x, per_call, color="#93c5fd", label="input tokens billed on this call")
797    ax.plot(x, np.cumsum(per_call), "o-", color="#2563eb", label="running total")
798    ax.axhline(per_call[-1] + 500, ls="--", color="#9ca3af", label="final conversation size (billed once?)")
799    ax.set_xlabel("model call in the loop")
800    ax.set_ylabel("input tokens")
801    ax.set_title("Every call re-sends the whole history")
802    ax.legend(frameon=False)
803    return {"loop_tokens": fig}
806def demo() -> None:
807    from primer._show import banner, say, table, takeaway
808
809    banner("1. One tool call, traced message by message")
810    for i, m in enumerate(trace_tool_call_round_trip(), 1):
811        for b in content_blocks(m):
812            detail = b.get("text") or (f"{b['name']}({b['input']}) id={b['id']}" if b["type"] == "tool_use" else f"result for {b['tool_use_id']}: {b['content']}")
813            print(f"  {i}. {m['role']:9s} {b['type']:11s} {detail}")
814    print()
815    takeaway("The model asked; your code ran the tool; the model answered. The model executed nothing.")
816
817    banner("2. Every call pays for the whole conversation")
818    per_call = loop_input_tokens(10, 2000, 500)
819    table(["call", "input tokens", "running total"], [(i + 1, t, sum(per_call[: i + 1])) for i, t in enumerate(per_call)])
820    say("10 calls bill 42,500 input tokens for a conversation that ends 7,000 tokens long.")