primer.agents.tools
Tools: design, validation and safety
Run: python -m primer.agents.tools
New to the notation? primer.notation explains every symbol used here from
zero. This lesson builds on the tool-call exchange in primer.agents.llm
and on the loop that runs it in primer.agents.agent_loop.
Level 1: The practitioner's guide
In one sentence. A tool is a function you let the model ask for, and tool design is everything that decides whether the request it fills in is the right one, has correct arguments, and is safe to carry out: the definition the model reads, the checks your code runs, and the gates in front of the real system.
When you need it. The moment a model's output does something rather than says something: looks up a record, refunds a payment, sends an email. A chatbot that only answers from its weights has no tools and needs none of this. A one-off script with one read-only tool needs the definition and little else. Everything in this lesson becomes necessary as soon as a tool writes, costs money or can be called by a model that was misled. The tell: if a wrong tool call would be visible to a customer, an auditor or a bank, you need the checks. Two of this lesson's measurements show how much the design decides. The same three tools, described vaguely ("search stuff"), get the right tool for 2 of 6 requests; described precisely (what it does, when to use it, when not to), 6 of 6. And a job that takes five tool calls in a row, each 97% likely to be right, succeeds 85.9% of the time, so about one run in seven fails; as one high-level call it succeeds 97% of the time.
Your options. Six layers of protection between the model's request and the real system, from the cheapest to the most certain. They stack; a production registry has all of them.
| Option | What it does | What it guarantees | What it costs | Where it lives |
|---|---|---|---|---|
| A schema in the definition | A JSON Schema tells the model which fields exist, their types and which are required | Nothing by itself; the model does its best to match | A few tokens per tool per call | Your tool definition |
| Strict mode | The provider constrains the model's output, token by token, to your schema | Arguments in exactly the schema's shape and a tool name that exists (Claude's strict tool use; OpenAI's strict mode) | A schema written to the provider's rules (additionalProperties: false, required fields); the compiled grammar is cached |
The model server |
| Validation in your registry | Checks shape and then business rules, and returns every problem with what a correct value looks like | A wrong call never reaches the system, and the model can fix all its mistakes in one retry (four at once in the lesson's example) | A validator and the rules; error messages worth writing | Your code |
| Descriptions and consolidation | Precise descriptions, few parameters, enums for closed sets, and one high-level tool in place of a chain |
The right tool chosen far more often (6 of 6 against 2 of 6 here), and fewer chances to fail in a row | Writing, and an evaluation set to measure selection | Your tool definitions |
| Loading only the relevant tools | Retrieval over the catalogue picks the few tools a request needs (5 of 30 in the lesson), or the provider searches it on demand | Selection accuracy holds as the catalogue grows; far fewer definition tokens per call | One embedding or search per request; the top few most-used tools kept always loaded | Your code, or the model server (Claude's tool search) |
| Safety gates | Scopes per agent, a dry run that describes instead of acting, human approval over a threshold, an idempotency key on every write | Least privilege, rehearsals, a person's sign-off, and a retry that cannot repeat a refund | A credential model, an approver in the loop, a store of keys and results | Your code, directly in front of the real system |
How to choose. Decide by what the tool can do, not by how clever the model is.
- Read-only lookups: a schema, a good description, and validation that returns actionable errors. Strict mode if the provider offers it; it removes a class of retries for free.
- Anything that writes: all of the above, plus an idempotency key on the
call and business-rule checks before it runs.
C-999fits the pattern^C-\d+$and is still a customer that does not exist. - Anything irreversible or over a money threshold: an approval rule, and a declined message that tells the model not to retry.
- Any agent that reads untrusted text (email, web pages, documents): the narrowest scopes you can give it, so a tricked model cannot refund, not merely should not.
- A catalogue past a few dozen tools: load per request, or route to a sub-agent that holds only its own tools. Claude's docs put the accuracy drop past 30 to 50 tools and recommend search from 10 tools up.
- Whatever you pick, prefer fewer, higher-level tools. A chain of five calls compounds five chances to go wrong; the sequencing belongs in tested code, not in the model.
What it costs. Tokens: every definition is re-sent on every call, so a
long catalogue is a standing charge. Claude's tool-search docs put a
typical multi-server setup (GitHub, Slack, Sentry, Grafana, Splunk) at about
55,000 tokens of definitions before any work is done, and on-demand loading
cuts that by over 85%. Tool results cost tokens too: Anthropic's tool-writing
guide reports that a concise response format used about a third of the
tokens of a detailed one, and that Claude Code caps a tool response at
25,000 tokens by default. Latency: validation is microseconds; an approval
gate is however long a person takes, so the call parks as
awaiting_approval rather than blocking. Quality: descriptions are the
cheapest lever, and the lesson's 2-of-6 to 6-of-6 swing cost only words.
Effort: the registry in this lesson, with every gate, is a few hundred lines,
and the idempotency store can be a dictionary until it needs to survive a
restart.
What breaks.
- Schema-valid, false. Strict mode and schemas prove shape, not truth. Keep the business-rule check, and return an error that says how to find the right id.
- "Invalid input." A bare error makes the model guess. List every problem with the expected format ("date as YYYY-MM-DD"); the model fixes them all in one retry.
- Vague descriptions. A model that cannot tell the tools apart picks the first one every time; in the lesson it got exactly the two requests that happened to belong to that tool.
- Too many tools. Selection accuracy falls and definition tokens climb together. Load per request.
- A retry that pays twice. A refund that times out after the bank processed it gets retried. Without a key the customer gets \$40; with the same key the registry returns the stored result and refunds once. Stripe's API keeps a key's first result and returns it on every repeat.
- A persistent model after a decline. "Declined" alone invites another attempt. Say "do not retry, tell the user".
- One admin credential. If the agent is tricked, it can do anything the credential allows. Scope per tool and per agent.
In the wild. Claude's Messages API accepts strict: true on a tool and
guarantees the arguments match the schema and the name is valid; its tool
search tool defers tool definitions and loads them when the model searches
for them; OpenAI's function calling has a strict mode its guide recommends
always enabling. Anthropic's Writing effective tools for agents is the
design reference behind sections 3 and 4 here: a few thoughtful tools over
one per endpoint, consistent namespacing (asana_search, jira_search),
responses that return meaning rather than identifiers, and evaluations
built from dozens of real prompt and response pairs. Stripe's idempotent
requests are the canonical form of the idempotency key: a client-chosen
key, the first result saved and replayed, keys pruned after 24 hours.
Toolformer (Schick et al., 2023) is the paper that showed a model can learn
when and how to call an API, which is why today's models emit tool calls
at all.
Go deeper. Level 2 writes the tool call out message by message, walks a call through every diamond of the registry in the order they are checked, measures the description experiment and the compounding formula, builds tool retrieval from cosine similarity, and replays the lost-reply refund with and without a key. If you only needed to choose, you are done.
Level 2: How it works, from scratch
A language model can only produce text. A tool is how that text turns into an action: looking up a record, refunding a payment, sending an email. This lesson builds a tool registry from scratch and shows the six things that decide whether tools work in production: how a call really happens, validation, descriptions, granularity, how many tools you expose, and safety.
1. What a tool call really is
Everyday picture. You hire a new assistant who is brilliant but may not touch anything. When they need something done, they fill in a request form ("refund customer C-100, $20") and hand it to you. You decide whether to carry it out, and you hand back a note saying what happened. The assistant is the model. The form is a tool call. You are your code.
Tiny worked example. Here's the whole exchange for "what's 2 + 3?" with one tool, written as the actual messages:
you -> model   tools: [{"name": "add", "description": "Add two integers.",
                        "input_schema": {"type": "object",
                          "properties": {"a": {"type": "integer"}, "b": {"type": "integer"}},
                          "required": ["a", "b"]}}]
               user: "what's 2 + 3?"
model -> you   tool_use {"id": "toolu_1", "name": "add", "input": {"a": 2, "b": 3}}
               stop_reason: "tool_use"          <- "please run this for me"
you            (validate the input, run add(2, 3) -> 5)
you -> model   user: tool_result {"tool_use_id": "toolu_1", "content": "5"}
model -> you   "2 + 3 = 5."   stop_reason: "end_turn"
input_schema is a JSON Schema, a JSON document that describes the
shape other JSON must have: which fields exist, what type each is, and
which are required. It's the "form template" the model fills in.
sequenceDiagram
  participant M as Model
  participant C as Your code
  participant T as The real system
  C->>M: tool definitions (name, description, JSON Schema) + user message
  M-->>C: tool_use: name + arguments (a filled-in form)
  C->>C: check the form (schema, business rules, permissions, approval)
  C->>T: carry it out
  T-->>C: result
  C->>M: tool_result (matched by tool_use_id)
  M-->>C: answer in words
Reading it: follow the arrows top to bottom. The model's only arrow towards the real system goes through your code. Nothing the model writes can touch the real system unless your code decides to act on it. That middle box, "check the form", is where the rest of this lesson lives.
The code. ToolRegistry.register stores a Python function with its
name, description and schema; ToolRegistry.definitions() produces the
list you send to the model; ToolRegistry.call() runs a call through every
check.
Why it matters. The separation is the security model. A model can be wrong or tricked. Your code is where you enforce what's allowed.
2. Validate every call before running it
Everyday picture. A bank clerk checks a withdrawal slip twice. Is it filled in properly: every box, a real date, a positive amount? Then does it make sense: does this account exist, does it have the money? Only then do they open the drawer.
Tiny worked example. A payment tool takes an amount, a currency
(EUR, GBP or USD) and an optional pay_on date. The model sends
{"ammount": 5, "currency": "usd", "pay_on": "next friday"}. The validator
returns every problem at once, each one saying what a correct value looks
like:
$: missing required field 'amount'
$: unexpected field 'ammount' (allowed: amount, currency, pay_on)
$.currency: must be one of ['EUR', 'GBP', 'USD'], got 'usd'
$.pay_on: 'next friday' does not match the required format. Expected: date as YYYY-MM-DD
Compare that to invalid input. With the first, the model fixes all four
mistakes in one retry. With the second, it guesses.
flowchart TD
  A[tool_use from the model] --> U{Tool exists?}
  U -->|no| E1[unknown_tool:<br/>list the real tools]
  U -->|yes| P{Caller has the<br/>required scope?}
  P -->|no| E2[denied]
  P -->|yes| S{Matches the<br/>JSON Schema?}
  S -->|no| E3[invalid:<br/>every problem, with the fix]
  S -->|yes| B{Business rules pass?<br/>e.g. customer exists}
  B -->|no| E4[rejected]
  B -->|yes| D{Dry run?}
  D -->|yes| E5[dry_run:<br/>describe, change nothing]
  D -->|no| H{Needs human<br/>approval?}
  H -->|yes, none given| E6[awaiting_approval]
  H -->|declined| E7[declined]
  H -->|no, or approved| I{Idempotency key<br/>seen before?}
  I -->|yes| E8[duplicate:<br/>return first result]
  I -->|no| X[run the tool: ok]
Reading it: a call enters at the top and must pass every diamond to reach
run the tool at the bottom. Each exit on the side is a named status in
ToolOutcome, and each returns text the model can act on. The order is
deliberate: permissions come before anything that reveals how the tool works, and
cheap checks come before expensive ones. Approval and idempotency sit last,
right next to the action they protect.
Why it matters. "Structured output" and strict mode guarantee the
shape of the arguments, not that they're true. "C-999" matches the
pattern ^C-\d+$ perfectly and is still a customer that doesn't exist.
Schema checks and business-rule checks are both required.
With the Claude API you can add "strict": true to a tool definition
(definitions(strict=True) here). The API then guarantees the model's
arguments validate against the schema. You still need the business-rule
checks.
In code: validate checks a value against a JSON Schema subset and
returns every problem with its path. ToolRegistry.call walks the diamonds
above in order and wraps the result in a ToolOutcome, whose
ToolOutcome.is_error says whether the model should treat it as a failure.
3. Descriptions are prompts
Everyday picture. A wall of drawers labelled "stuff", "things" and "items". Even a careful person opens the wrong one. Relabel them "Policies (PTO, travel, VPN). Not customers", and nobody hesitates.
Tiny worked example. A stand-in model (pick_tool) chooses the tool
whose name and description share the most words with the request. For
"billing status for customer 1042", the vague descriptions share zero words
with every tool (a three-way tie, so it guesses the first). The precise
lookup_record description shares "billing", "status" and "customer" and
wins.
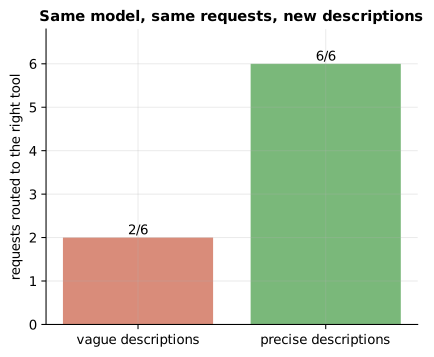
Reading it: two bars, one per set of descriptions, each out of the same six labelled requests. With vague descriptions the model gets 2 of 6, and only the two that happen to belong to the first tool, which it picks every time it can't tell them apart. With descriptions that say what each tool is for, when to use it and when not to, it gets 6 of 6. Only the descriptions changed.
Why it matters. Real models are far better readers than word overlap,
but they choose from exactly the same text. Precise descriptions, a few
parameters, enums instead of free text, and error messages that explain
the fix remove a large share of agent errors.
In code: selection_accuracy runs pick_tool over the labelled
requests and counts the correct picks, which is what the figure plots for
VAGUE_TOOLS and PRECISE_TOOLS.
4. Fewer, higher-level tools
Everyday picture. Asking an assistant to "book my trip to Denver" versus dictating five separate forms (find flight, hold seat, find hotel, reserve room, add to calendar). Every hand-off is another chance to drop something.
flowchart LR
  subgraph Low["Five low-level calls"]
    a1[get_customer] --> a2[get_price_list] --> a3[compute_tax] --> a4[render_pdf] --> a5[send_email]
  end
  subgraph High["One high-level call"]
    b1[create_invoice]
  end
Reading it: on the left the model has to pick five tools in the right order and carry each output into the next input by hand. On the right the same work is one call, and the sequencing lives in ordinary tested code.
The chance that a chain of calls all succeed:
Level 3: the formula and its symbols
$$ P(\text{all succeed}) = p^{\,n} $$
Symbols
| Symbol | Meaning |
|---|---|
| $p$ | probability that one call is chosen and filled in correctly |
| $n$ | number of calls in the chain |
In words: multiply the per-call success rate by itself once per call.
On the example: with $p = 0.97$ and $n = 5$, $0.97^5 = 0.859$, so about 1 run in 7 fails. With one high-level call it's $0.97^1 = 0.97$.
Level 3: in Python
In Python:
p = 0.97
# five calls that must all succeed
round(p ** 5, 3)  # → 0.859
# about 1 run in 7 fails
round(1 - p ** 5, 2)  # → 0.14
# one high-level call
p ** 1  # → 0.97
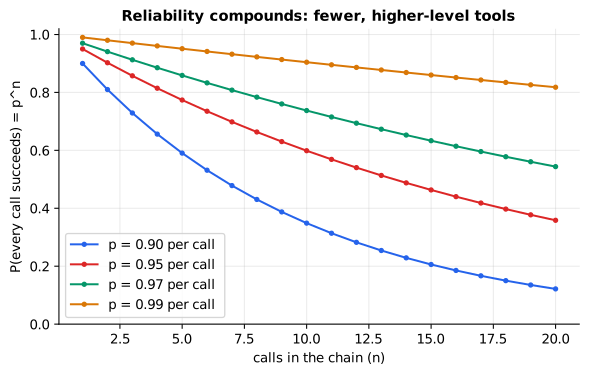
Reading it: the x-axis is how many calls the job takes, and the y-axis is the chance the whole job succeeds. Each curve is a different per-call reliability. Even at 99% per call, twenty calls succeed only about 82% of the time, and at 90% per call, ten calls succeed barely a third of the time. Fewer calls is the cheapest reliability you can buy.
In code: chain_success evaluates $p^{\,n}$.
5. Too many tools: load only the relevant ones
Everyday picture. A warehouse versus a toolbox. You don't send a plumber into a warehouse of 500 tools; you hand them the five they need for today's job.
Tiny worked example. A catalogue of 30 tools. For "I forgot my password and I'm
locked out", select_tools embeds the request, compares it to every tool
description, and sends the model only the top 5, with reset_password
first.
flowchart LR
  R[User request] --> E[Embed request]
  C[(Tool catalogue<br/>30 descriptions,<br/>embedded once)] --> S
  E --> S[Cosine similarity<br/>to every tool]
  S --> K[Top 5 tools]
  K --> M[Model sees<br/>only these 5]
Reading it: this is retrieval, the same machinery as RAG, but the "documents" are tool descriptions. The catalogue is embedded ahead of time; per request you embed one string and take the top matches.
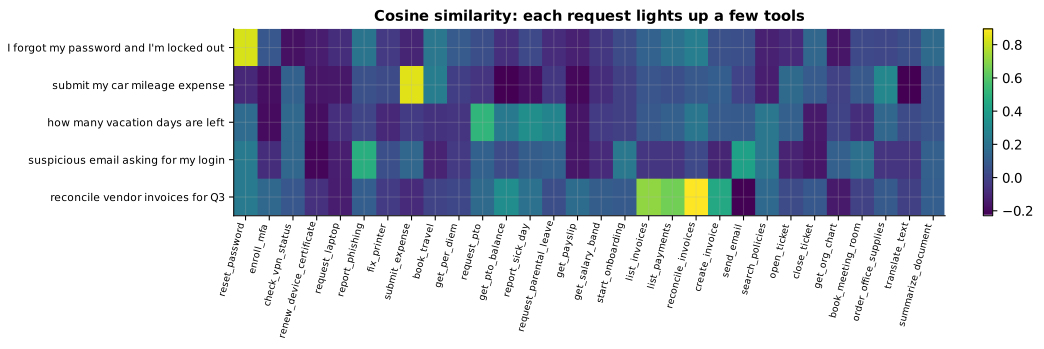
Reading it: each row is a user request and each column a tool from the catalogue. Brighter cells mean more similar. Each request lights up a small cluster of related tools and stays dark everywhere else. Sending only that cluster keeps the model's choice small, which is why accuracy holds up as the catalogue grows.
Why it matters. Selection accuracy drops as the tool list grows past a few dozen, and every definition costs input tokens on every call. The alternatives are routing the request to a sub-agent that holds only the relevant tools, or using a provider's built-in tool search.
6. Safety: idempotency, dry runs, approval, least privilege
Idempotency. Everyday picture: pressing a lift button twice still takes you to the floor once. An operation is idempotent when doing it twice has the same effect as doing it once. Worked example: a refund call times out after the bank processed it, so the agent retries.
sequenceDiagram
  participant A as Agent
  participant R as Registry
  participant B as Bank
  A->>R: refund C-100 $20 (key req-1)
  R->>B: refund
  B-->>R: done
  R--xA: network timeout (reply lost)
  A->>R: retry: refund C-100 $20 (key req-1)
  R-->>A: duplicate: "refunded 20.00 to C-100" (no second refund)
Reading it: the first reply is lost on the way back (the crossed arrow), so the agent can't know the refund happened and sensibly retries. Because the retry carries the same key, the registry returns the stored result instead of refunding again. Without the key, the customer gets $40.
Dry run. A rehearsal: run every check, then describe the action
instead of doing it. Useful for previews and for shadow-mode rollouts
(primer.agents.deployment).
Human approval. Everyday picture: a manager signs off on spending over
a limit. Irreversible actions, or ones over a threshold such as refunds over
$500, park as awaiting_approval until a person decides.
sequenceDiagram
  participant M as Model
  participant R as Registry
  participant H as Human approver
  M->>R: refund C-100 $900
  R->>H: approve refund_payment {amount: 900}?
  alt approved
    H-->>R: yes
    R-->>M: ok: refunded
  else declined
    H-->>R: no
    R-->>M: declined: do not retry, tell the user
  end
Reading it: the approval gate sits between the model's request and the action. Both branches return text the model can act on. "Do not retry" in the declined message matters, because otherwise a persistent model asks again.
Least privilege. Everyday picture: a valet key starts the car but
won't open the boot. Give each agent credentials (scopes, named
permissions such as payments:write) for its job only. An agent that reads
tickets holds tickets:read, so even if a malicious email tricks it, it
cannot issue refunds.
In code: a Tool carries its safety settings: the scopes it needs,
whether it reads, writes or acts irreversibly, and an optional approval
rule, which Tool.requires_approval combines. ToolRegistry.call enforces
them, given the caller's credentials, an idempotency key, a dry-run flag and
an approver.
In 20 seconds
- The model writes a request (
tool_use). Your code validates it, runs it, and returns atool_result. - Validate shape (JSON Schema) and meaning (business rules). Return every problem, each with its fix.
- Descriptions are prompts: say what the tool does, when to use it, and when not to.
- Prefer fewer, higher-level tools: $p^n$ punishes long chains of calls.
- Past a few dozen tools, load only the relevant ones per request.
- Writes get idempotency keys; irreversible or high-value actions get human approval; credentials get the narrowest scopes.
Self-test questions
Q: How do you design tools so the model picks the right one with correct arguments?
A: Give each tool one clear job and a description that says what it does,
when to use it and when not to. Keep parameters few, use enums for closed
sets, and put the format in the schema description ("date as YYYY-MM-DD").
Prefer one high-level tool over several low-level ones. Validate every call
and return actionable errors so the model can self-correct. Measure tool
selection accuracy in evals, and load tools dynamically when there are many.
Q: The schema says customer_id must match ^C-\d+$. Is that enough validation?
A: No. The schema checks shape, not truth. C-999 is well-formed and may not
exist. Add a business-rule check before acting, and return an error that
tells the model how to find the right id.
Q: A refund call timed out. Should the agent retry? A: Only if the call is idempotent. Send an idempotency key with every write, and the retry returns the original result instead of refunding twice.
Q: Why not give the agent one admin credential for everything? A: Blast radius. If the agent is tricked (for example by prompt injection in a document it reads), it can do anything the credential allows. Scope credentials per tool and per agent, and put irreversible actions behind human approval.
The papers behind this lesson
- Schick et al., Toolformer: Language Models Can Teach Themselves to Use Tools (2023). https://arxiv.org/abs/2302.04761. It showed a language model can learn when to call an API, which one and with what arguments, by keeping only the self-generated calls that made its predictions better, which is the idea behind tool calling being trained into today's models. annotated companion
Further reading
- Anthropic, Writing effective tools for agents: https://www.anthropic.com/engineering/writing-tools-for-agents
- Anthropic, Building effective agents (appendix on prompt-engineering tools): https://www.anthropic.com/engineering/building-effective-agents
- Claude tool use overview: https://docs.claude.com/en/docs/agents-and-tools/tool-use/overview
- Implementing tool use: https://docs.claude.com/en/docs/agents-and-tools/tool-use/implement-tool-use
- Understanding JSON Schema: https://json-schema.org/understanding-json-schema
- Stripe, idempotent requests (the canonical explanation): https://docs.stripe.com/api/idempotent_requests
1r""" 2# Tools: design, validation and safety 3 4Run: `python -m primer.agents.tools` 5 6New to the notation? `primer.notation` explains every symbol used here from 7zero. This lesson builds on the tool-call exchange in `primer.agents.llm` 8and on the loop that runs it in `primer.agents.agent_loop`. 9 10## Level 1: The practitioner's guide 11 12**In one sentence.** A tool is a function you let the model ask for, and 13tool design is everything that decides whether the request it fills in is 14the right one, has correct arguments, and is safe to carry out: the 15definition the model reads, the checks your code runs, and the gates in 16front of the real system. 17 18**When you need it.** The moment a model's output does something rather 19than says something: looks up a record, refunds a payment, sends an email. 20A chatbot that only answers from its weights has no tools and needs none of 21this. A one-off script with one read-only tool needs the definition and 22little else. Everything in this lesson becomes necessary as soon as a tool 23writes, costs money or can be called by a model that was misled. The tell: 24if a wrong tool call would be visible to a customer, an auditor or a bank, 25you need the checks. Two of this lesson's measurements show how much the 26design decides. The same three tools, described vaguely ("search stuff"), 27get the right tool for 2 of 6 requests; described precisely (what it does, 28when to use it, when not to), 6 of 6. And a job that takes five tool calls 29in a row, each 97% likely to be right, succeeds 85.9% of the time, so 30about one run in seven fails; as one high-level call it succeeds 97% of 31the time. 32 33**Your options.** Six layers of protection between the model's request and 34the real system, from the cheapest to the most certain. They stack; a 35production registry has all of them. 36 37| Option | What it does | What it guarantees | What it costs | Where it lives | 38|---|---|---|---|---| 39| A schema in the definition | A JSON Schema tells the model which fields exist, their types and which are required | Nothing by itself; the model does its best to match | A few tokens per tool per call | Your tool definition | 40| Strict mode | The provider constrains the model's output, token by token, to your schema | Arguments in exactly the schema's shape and a tool name that exists (Claude's strict tool use; OpenAI's strict mode) | A schema written to the provider's rules (`additionalProperties: false`, required fields); the compiled grammar is cached | The model server | 41| Validation in your registry | Checks shape and then business rules, and returns every problem with what a correct value looks like | A wrong call never reaches the system, and the model can fix all its mistakes in one retry (four at once in the lesson's example) | A validator and the rules; error messages worth writing | Your code | 42| Descriptions and consolidation | Precise descriptions, few parameters, `enum`s for closed sets, and one high-level tool in place of a chain | The right tool chosen far more often (6 of 6 against 2 of 6 here), and fewer chances to fail in a row | Writing, and an evaluation set to measure selection | Your tool definitions | 43| Loading only the relevant tools | Retrieval over the catalogue picks the few tools a request needs (5 of 30 in the lesson), or the provider searches it on demand | Selection accuracy holds as the catalogue grows; far fewer definition tokens per call | One embedding or search per request; the top few most-used tools kept always loaded | Your code, or the model server (Claude's tool search) | 44| Safety gates | Scopes per agent, a dry run that describes instead of acting, human approval over a threshold, an idempotency key on every write | Least privilege, rehearsals, a person's sign-off, and a retry that cannot repeat a refund | A credential model, an approver in the loop, a store of keys and results | Your code, directly in front of the real system | 45 46**How to choose.** Decide by what the tool can do, not by how clever the 47model is. 48 49- Read-only lookups: a schema, a good description, and validation that 50 returns actionable errors. Strict mode if the provider offers it; it 51 removes a class of retries for free. 52- Anything that writes: all of the above, plus an idempotency key on the 53 call and business-rule checks before it runs. `C-999` fits the pattern 54 `^C-\d+$` and is still a customer that does not exist. 55- Anything irreversible or over a money threshold: an approval rule, and a 56 declined message that tells the model not to retry. 57- Any agent that reads untrusted text (email, web pages, documents): the 58 narrowest scopes you can give it, so a tricked model *cannot* refund, not 59 merely should not. 60- A catalogue past a few dozen tools: load per request, or route to a 61 sub-agent that holds only its own tools. Claude's docs put the accuracy 62 drop past 30 to 50 tools and recommend search from 10 tools up. 63- Whatever you pick, prefer fewer, higher-level tools. A chain of five 64 calls compounds five chances to go wrong; the sequencing belongs in 65 tested code, not in the model. 66 67**What it costs.** Tokens: every definition is re-sent on every call, so a 68long catalogue is a standing charge. Claude's tool-search docs put a 69typical multi-server setup (GitHub, Slack, Sentry, Grafana, Splunk) at about 7055,000 tokens of definitions before any work is done, and on-demand loading 71cuts that by over 85%. Tool results cost tokens too: Anthropic's tool-writing 72guide reports that a concise response format used about a third of the 73tokens of a detailed one, and that Claude Code caps a tool response at 7425,000 tokens by default. Latency: validation is microseconds; an approval 75gate is however long a person takes, so the call parks as 76`awaiting_approval` rather than blocking. Quality: descriptions are the 77cheapest lever, and the lesson's 2-of-6 to 6-of-6 swing cost only words. 78Effort: the registry in this lesson, with every gate, is a few hundred lines, 79and the idempotency store can be a dictionary until it needs to survive a 80restart. 81 82**What breaks.** 83 84- **Schema-valid, false.** Strict mode and schemas prove shape, not truth. 85 Keep the business-rule check, and return an error that says how to find 86 the right id. 87- **"Invalid input."** A bare error makes the model guess. List every 88 problem with the expected format ("date as YYYY-MM-DD"); the model fixes 89 them all in one retry. 90- **Vague descriptions.** A model that cannot tell the tools apart picks 91 the first one every time; in the lesson it got exactly the two requests 92 that happened to belong to that tool. 93- **Too many tools.** Selection accuracy falls and definition tokens climb 94 together. Load per request. 95- **A retry that pays twice.** A refund that times out after the bank 96 processed it gets retried. Without a key the customer gets \$40; with the 97 same key the registry returns the stored result and refunds once. 98 Stripe's API keeps a key's first result and returns it on every repeat. 99- **A persistent model after a decline.** "Declined" alone invites another 100 attempt. Say "do not retry, tell the user". 101- **One admin credential.** If the agent is tricked, it can do anything 102 the credential allows. Scope per tool and per agent. 103 104**In the wild.** Claude's Messages API accepts `strict: true` on a tool and 105guarantees the arguments match the schema and the name is valid; its tool 106search tool defers tool definitions and loads them when the model searches 107for them; OpenAI's function calling has a strict mode its guide recommends 108always enabling. Anthropic's *Writing effective tools for agents* is the 109design reference behind sections 3 and 4 here: a few thoughtful tools over 110one per endpoint, consistent namespacing (`asana_search`, `jira_search`), 111responses that return meaning rather than identifiers, and evaluations 112built from dozens of real prompt and response pairs. Stripe's idempotent 113requests are the canonical form of the idempotency key: a client-chosen 114key, the first result saved and replayed, keys pruned after 24 hours. 115Toolformer (Schick et al., 2023) is the paper that showed a model can learn 116when and how to call an API, which is why today's models emit tool calls 117at all. 118 119**Go deeper.** Level 2 writes the tool call out message by message, walks 120a call through every diamond of the registry in the order they are checked, 121measures the description experiment and the compounding formula, builds 122tool retrieval from cosine similarity, and replays the lost-reply refund 123with and without a key. If you only needed to choose, you are done. 124 125## Level 2: How it works, from scratch 126 127A language model can only produce text. A **tool** is how that text turns 128into an action: looking up a record, refunding a payment, sending an email. 129This lesson builds a tool registry from scratch and shows the six things 130that decide whether tools work in production: how a call really happens, 131validation, descriptions, granularity, how many tools you expose, and safety. 132 133## 1. What a tool call really is 134 135**Everyday picture.** You hire a new assistant who is brilliant but may not 136touch anything. When they need something done, they fill in a *request 137form* ("refund customer C-100, $20") and hand it to you. **You** decide 138whether to carry it out, and you hand back a note saying what happened. The 139assistant is the model. The form is a *tool call*. You are your code. 140 141**Tiny worked example.** Here's the whole exchange for "what's 2 + 3?" with 142one tool, written as the actual messages: 143 144```text 145you -> model tools: [{"name": "add", "description": "Add two integers.", 146 "input_schema": {"type": "object", 147 "properties": {"a": {"type": "integer"}, "b": {"type": "integer"}}, 148 "required": ["a", "b"]}}] 149 user: "what's 2 + 3?" 150model -> you tool_use {"id": "toolu_1", "name": "add", "input": {"a": 2, "b": 3}} 151 stop_reason: "tool_use" <- "please run this for me" 152you (validate the input, run add(2, 3) -> 5) 153you -> model user: tool_result {"tool_use_id": "toolu_1", "content": "5"} 154model -> you "2 + 3 = 5." stop_reason: "end_turn" 155``` 156 157`input_schema` is a **JSON Schema**, a JSON document that describes the 158shape other JSON must have: which fields exist, what type each is, and 159which are required. It's the "form template" the model fills in. 160 161```mermaid 162sequenceDiagram 163 participant M as Model 164 participant C as Your code 165 participant T as The real system 166 C->>M: tool definitions (name, description, JSON Schema) + user message 167 M-->>C: tool_use: name + arguments (a filled-in form) 168 C->>C: check the form (schema, business rules, permissions, approval) 169 C->>T: carry it out 170 T-->>C: result 171 C->>M: tool_result (matched by tool_use_id) 172 M-->>C: answer in words 173``` 174 175**Reading it:** follow the arrows top to bottom. The model's only arrow 176towards the real system goes *through your code*. Nothing the model writes 177can touch the real system unless your code decides to act on it. That 178middle box, "check the form", is where the rest of this lesson lives. 179 180**The code.** `ToolRegistry.register` stores a Python function with its 181name, description and schema; `ToolRegistry.definitions()` produces the 182list you send to the model; `ToolRegistry.call()` runs a call through every 183check. 184 185**Why it matters.** The separation is the security model. A model can be 186wrong or tricked. Your code is where you enforce what's allowed. 187 188## 2. Validate every call before running it 189 190**Everyday picture.** A bank clerk checks a withdrawal slip twice. Is it 191filled in properly: every box, a real date, a positive amount? Then does it 192make sense: does this account exist, does it have the money? Only then do 193they open the drawer. 194 195**Tiny worked example.** A payment tool takes an `amount`, a `currency` 196(EUR, GBP or USD) and an optional `pay_on` date. The model sends 197`{"ammount": 5, "currency": "usd", "pay_on": "next friday"}`. The validator 198returns *every* problem at once, each one saying what a correct value looks 199like: 200 201```text 202$: missing required field 'amount' 203$: unexpected field 'ammount' (allowed: amount, currency, pay_on) 204$.currency: must be one of ['EUR', 'GBP', 'USD'], got 'usd' 205$.pay_on: 'next friday' does not match the required format. Expected: date as YYYY-MM-DD 206``` 207 208Compare that to `invalid input`. With the first, the model fixes all four 209mistakes in one retry. With the second, it guesses. 210 211```mermaid 212flowchart TD 213 A[tool_use from the model] --> U{Tool exists?} 214 U -->|no| E1[unknown_tool:<br/>list the real tools] 215 U -->|yes| P{Caller has the<br/>required scope?} 216 P -->|no| E2[denied] 217 P -->|yes| S{Matches the<br/>JSON Schema?} 218 S -->|no| E3[invalid:<br/>every problem, with the fix] 219 S -->|yes| B{Business rules pass?<br/>e.g. customer exists} 220 B -->|no| E4[rejected] 221 B -->|yes| D{Dry run?} 222 D -->|yes| E5[dry_run:<br/>describe, change nothing] 223 D -->|no| H{Needs human<br/>approval?} 224 H -->|yes, none given| E6[awaiting_approval] 225 H -->|declined| E7[declined] 226 H -->|no, or approved| I{Idempotency key<br/>seen before?} 227 I -->|yes| E8[duplicate:<br/>return first result] 228 I -->|no| X[run the tool: ok] 229``` 230 231**Reading it:** a call enters at the top and must pass every diamond to reach 232*run the tool* at the bottom. Each exit on the side is a named `status` in 233`ToolOutcome`, and each returns text the model can act on. The order is 234deliberate: permissions come before anything that reveals how the tool works, and 235cheap checks come before expensive ones. Approval and idempotency sit last, 236right next to the action they protect. 237 238**Why it matters.** "Structured output" and strict mode guarantee the 239*shape* of the arguments, not that they're *true*. `"C-999"` matches the 240pattern `^C-\d+$` perfectly and is still a customer that doesn't exist. 241Schema checks and business-rule checks are both required. 242 243With the Claude API you can add `"strict": true` to a tool definition 244(`definitions(strict=True)` here). The API then guarantees the model's 245arguments validate against the schema. You still need the business-rule 246checks. 247 248**In code:** `validate` checks a value against a JSON Schema subset and 249returns every problem with its path. `ToolRegistry.call` walks the diamonds 250above in order and wraps the result in a `ToolOutcome`, whose 251`ToolOutcome.is_error` says whether the model should treat it as a failure. 252 253## 3. Descriptions are prompts 254 255**Everyday picture.** A wall of drawers labelled "stuff", "things" and 256"items". Even a careful person opens the wrong one. Relabel them "Policies 257(PTO, travel, VPN). Not customers", and nobody hesitates. 258 259**Tiny worked example.** A stand-in model (`pick_tool`) chooses the tool 260whose name and description share the most words with the request. For 261"billing status for customer 1042", the vague descriptions share zero words 262with every tool (a three-way tie, so it guesses the first). The precise 263`lookup_record` description shares "billing", "status" and "customer" and 264wins. 265 266 267 268**Reading it:** two bars, one per set of descriptions, each out of the same six 269labelled requests. With vague descriptions the model gets 2 of 6, and only 270the two that happen to belong to the first tool, which it picks every time it 271can't tell them apart. With descriptions that say *what* each tool is for, 272*when* to use it and *when not to*, it gets 6 of 6. Only the descriptions 273changed. 274 275**Why it matters.** Real models are far better readers than word overlap, 276but they choose from exactly the same text. Precise descriptions, a few 277parameters, `enum`s instead of free text, and error messages that explain 278the fix remove a large share of agent errors. 279 280**In code:** `selection_accuracy` runs `pick_tool` over the labelled 281requests and counts the correct picks, which is what the figure plots for 282`VAGUE_TOOLS` and `PRECISE_TOOLS`. 283 284## 4. Fewer, higher-level tools 285 286**Everyday picture.** Asking an assistant to "book my trip to Denver" versus 287dictating five separate forms (find flight, hold seat, find hotel, reserve 288room, add to calendar). Every hand-off is another chance to drop something. 289 290```mermaid 291flowchart LR 292 subgraph Low["Five low-level calls"] 293 a1[get_customer] --> a2[get_price_list] --> a3[compute_tax] --> a4[render_pdf] --> a5[send_email] 294 end 295 subgraph High["One high-level call"] 296 b1[create_invoice] 297 end 298``` 299 300**Reading it:** on the left the model has to pick five tools in the right 301order and carry each output into the next input by hand. On the right the 302same work is one call, and the sequencing lives in ordinary tested code. 303 304The chance that a chain of calls all succeed: 305 306$$ 307P(\text{all succeed}) = p^{\,n} 308$$ 309 310**Symbols** 311 312| Symbol | Meaning | 313|---|---| 314| $p$ | probability that one call is chosen and filled in correctly | 315| $n$ | number of calls in the chain | 316 317**In words:** multiply the per-call success rate by itself once per call. 318 319**On the example:** with $p = 0.97$ and $n = 5$, $0.97^5 = 0.859$, so about 3201 run in 7 fails. With one high-level call it's $0.97^1 = 0.97$. 321 322**In Python:** 323 324```python 325p = 0.97 326# five calls that must all succeed 327round(p ** 5, 3) # → 0.859 328# about 1 run in 7 fails 329round(1 - p ** 5, 2) # → 0.14 330# one high-level call 331p ** 1 # → 0.97 332``` 333 334 335 336**Reading it:** the x-axis is how many calls the job takes, and the y-axis is the chance 337the whole job succeeds. Each curve is a different per-call reliability. 338Even at 99% per call, twenty calls succeed only about 82% of the time, and at 33990% per call, ten calls succeed barely a third of the time. Fewer calls is 340the cheapest reliability you can buy. 341 342**In code:** `chain_success` evaluates $p^{\,n}$. 343 344## 5. Too many tools: load only the relevant ones 345 346**Everyday picture.** A warehouse versus a toolbox. You don't send a 347plumber into a warehouse of 500 tools; you hand them the five they need for 348today's job. 349 350**Tiny worked example.** A catalogue of 30 tools. For "I forgot my password and I'm 351locked out", `select_tools` embeds the request, compares it to every tool 352description, and sends the model only the top 5, with `reset_password` 353first. 354 355```mermaid 356flowchart LR 357 R[User request] --> E[Embed request] 358 C[(Tool catalogue<br/>30 descriptions,<br/>embedded once)] --> S 359 E --> S[Cosine similarity<br/>to every tool] 360 S --> K[Top 5 tools] 361 K --> M[Model sees<br/>only these 5] 362``` 363 364**Reading it:** this is retrieval, the same machinery as RAG, but the 365"documents" are tool descriptions. The catalogue is embedded ahead of time; 366per request you embed one string and take the top matches. 367 368 369 370**Reading it:** each row is a user request and each column a tool from the 371catalogue. Brighter cells mean more similar. Each request lights up a small 372cluster of related tools and stays dark everywhere else. Sending only 373that cluster keeps the model's choice small, which is why accuracy holds 374up as the catalogue grows. 375 376**Why it matters.** Selection accuracy drops as the tool list grows past a 377few dozen, and every definition costs input tokens on every call. The 378alternatives are routing the request to a sub-agent that holds only the 379relevant tools, or using a provider's built-in tool search. 380 381## 6. Safety: idempotency, dry runs, approval, least privilege 382 383**Idempotency.** *Everyday picture:* pressing a lift button twice still 384takes you to the floor once. An operation is **idempotent** when doing it 385twice has the same effect as doing it once. *Worked example:* a refund call 386times out *after* the bank processed it, so the agent retries. 387 388```mermaid 389sequenceDiagram 390 participant A as Agent 391 participant R as Registry 392 participant B as Bank 393 A->>R: refund C-100 $20 (key req-1) 394 R->>B: refund 395 B-->>R: done 396 R--xA: network timeout (reply lost) 397 A->>R: retry: refund C-100 $20 (key req-1) 398 R-->>A: duplicate: "refunded 20.00 to C-100" (no second refund) 399``` 400 401**Reading it:** the first reply is lost on the way back (the crossed 402arrow), so the agent can't know the refund happened and sensibly retries. 403Because the retry carries the same key, the registry returns the stored 404result instead of refunding again. Without the key, the customer gets $40. 405 406**Dry run.** A rehearsal: run every check, then *describe* the action 407instead of doing it. Useful for previews and for shadow-mode rollouts 408(`primer.agents.deployment`). 409 410**Human approval.** *Everyday picture:* a manager signs off on spending over 411a limit. Irreversible actions, or ones over a threshold such as refunds over 412$500, park as `awaiting_approval` until a person decides. 413 414```mermaid 415sequenceDiagram 416 participant M as Model 417 participant R as Registry 418 participant H as Human approver 419 M->>R: refund C-100 $900 420 R->>H: approve refund_payment {amount: 900}? 421 alt approved 422 H-->>R: yes 423 R-->>M: ok: refunded 424 else declined 425 H-->>R: no 426 R-->>M: declined: do not retry, tell the user 427 end 428``` 429 430**Reading it:** the approval gate sits between the model's request and the 431action. Both branches return text the model can act on. "Do not retry" in 432the declined message matters, because otherwise a persistent model asks again. 433 434**Least privilege.** *Everyday picture:* a valet key starts the car but 435won't open the boot. Give each agent credentials (**scopes**, named 436permissions such as `payments:write`) for its job only. An agent that reads 437tickets holds `tickets:read`, so even if a malicious email tricks it, it 438*cannot* issue refunds. 439 440**In code:** a `Tool` carries its safety settings: the scopes it needs, 441whether it reads, writes or acts irreversibly, and an optional approval 442rule, which `Tool.requires_approval` combines. `ToolRegistry.call` enforces 443them, given the caller's credentials, an idempotency key, a dry-run flag and 444an approver. 445 446## In 20 seconds 447- The model writes a request (`tool_use`). Your code validates it, runs it, and returns a `tool_result`. 448- Validate shape (JSON Schema) *and* meaning (business rules). Return every problem, each with its fix. 449- Descriptions are prompts: say what the tool does, when to use it, and when not to. 450- Prefer fewer, higher-level tools: $p^n$ punishes long chains of calls. 451- Past a few dozen tools, load only the relevant ones per request. 452- Writes get idempotency keys; irreversible or high-value actions get human approval; credentials get the narrowest scopes. 453 454## Self-test questions 455 456**Q: How do you design tools so the model picks the right one with correct arguments?** 457A: Give each tool one clear job and a description that says what it does, 458when to use it and when not to. Keep parameters few, use `enum`s for closed 459sets, and put the format in the schema description ("date as YYYY-MM-DD"). 460Prefer one high-level tool over several low-level ones. Validate every call 461and return actionable errors so the model can self-correct. Measure tool 462selection accuracy in evals, and load tools dynamically when there are many. 463 464**Q: The schema says `customer_id` must match `^C-\d+$`. Is that enough validation?** 465A: No. The schema checks shape, not truth. `C-999` is well-formed and may not 466exist. Add a business-rule check before acting, and return an error that 467tells the model how to find the right id. 468 469**Q: A refund call timed out. Should the agent retry?** 470A: Only if the call is idempotent. Send an idempotency key with every write, 471and the retry returns the original result instead of refunding twice. 472 473**Q: Why not give the agent one admin credential for everything?** 474A: Blast radius. If the agent is tricked (for example by prompt injection in 475a document it reads), it can do anything the credential allows. Scope 476credentials per tool and per agent, and put irreversible actions behind human 477approval. 478 479## The papers behind this lesson 480 481- **Schick et al., *Toolformer: Language Models Can Teach Themselves to Use Tools* (2023).** 482 https://arxiv.org/abs/2302.04761. It showed a language model can learn *when* 483 to call an API, *which* one and *with what arguments*, by keeping only the 484 self-generated calls that made its predictions better, which is the idea behind 485 tool calling being trained into today's models. 486 [annotated companion](../../papers/toolformer.html) 487 488## Further reading 489- Anthropic, *Writing effective tools for agents*: https://www.anthropic.com/engineering/writing-tools-for-agents 490- Anthropic, *Building effective agents* (appendix on prompt-engineering tools): https://www.anthropic.com/engineering/building-effective-agents 491- Claude tool use overview: https://docs.claude.com/en/docs/agents-and-tools/tool-use/overview 492- Implementing tool use: https://docs.claude.com/en/docs/agents-and-tools/tool-use/implement-tool-use 493- *Understanding JSON Schema*: https://json-schema.org/understanding-json-schema 494- Stripe, idempotent requests (the canonical explanation): https://docs.stripe.com/api/idempotent_requests 495""" 496 497from __future__ import annotations 498 499import json 500import re 501from dataclasses import dataclass, field 502from typing import Any, Callable 503 504 505def _json_type(value: Any) -> str: 506 # bool is a subclass of int in Python, so test it first: True must not pass as an integer. 507 if isinstance(value, bool): 508 return "boolean" 509 if isinstance(value, int): 510 return "integer" 511 if isinstance(value, float): 512 return "number" 513 if isinstance(value, str): 514 return "string" 515 if isinstance(value, list): 516 return "array" 517 if isinstance(value, dict): 518 return "object" 519 return "null" if value is None else type(value).__name__ 520 521 522def _type_ok(actual: str, expected: str) -> bool: 523 # JSON Schema's "number" accepts integers too. 524 return actual == expected or (expected == "number" and actual == "integer") 525 526 527def validate(value: Any, schema: dict[str, Any], path: str = "$") -> list[str]: 528 """Check `value` against a JSON Schema subset. Returns every problem found.""" 529 expected = schema.get("type") 530 if expected and not _type_ok(_json_type(value), expected): 531 # Stop here: the other checks assume the right type. 532 return [f"{path}: expected {expected}, got {_json_type(value)} ({value!r})"] 533 534 errors: list[str] = [] 535 if "enum" in schema and value not in schema["enum"]: 536 # Listing the allowed values lets the model fix the call in one retry. 537 errors.append(f"{path}: must be one of {schema['enum']}, got {value!r}") 538 if isinstance(value, str) and "pattern" in schema and not re.search(schema["pattern"], value): 539 hint = schema.get("description", f"a string matching {schema['pattern']}") 540 errors.append(f"{path}: {value!r} does not match the required format. Expected: {hint}") 541 if isinstance(value, (int, float)) and not isinstance(value, bool): 542 if "minimum" in schema and value < schema["minimum"]: 543 errors.append(f"{path}: must be >= {schema['minimum']}, got {value}") 544 if "maximum" in schema and value > schema["maximum"]: 545 errors.append(f"{path}: must be <= {schema['maximum']}, got {value}") 546 if isinstance(value, dict): 547 for name in schema.get("required", []): 548 if name not in value: 549 errors.append(f"{path}: missing required field '{name}'") 550 props = schema.get("properties", {}) 551 for name, sub in value.items(): 552 if name in props: 553 errors += validate(sub, props[name], f"{path}.{name}") 554 elif schema.get("additionalProperties") is False: 555 errors.append(f"{path}: unexpected field '{name}' (allowed: {', '.join(props)})") 556 if isinstance(value, list) and "items" in schema: 557 for i, item in enumerate(value): 558 errors += validate(item, schema["items"], f"{path}[{i}]") 559 return errors 560 561 562@dataclass 563class Tool: 564 name: str 565 description: str 566 input_schema: dict[str, Any] 567 fn: Callable[..., Any] 568 # Business-rule check run after the schema passes: "does this customer exist?" 569 # Returns a list of actionable problems; empty means OK. 570 check: Callable[[dict[str, Any]], list[str]] | None = None 571 # Permissions the caller's credentials must include to run this tool. 572 scopes: frozenset[str] = frozenset() 573 # read | write | irreversible. Writes get idempotency; irreversible ones need approval. 574 side_effect: str = "read" 575 # Extra rule for when a human must approve, e.g. lambda args: args["amount"] > 500. 576 needs_approval: Callable[[dict[str, Any]], bool] | None = None 577 578 def requires_approval(self, args: dict[str, Any]) -> bool: 579 return self.side_effect == "irreversible" or bool(self.needs_approval and self.needs_approval(args)) 580 581 582@dataclass 583class ToolOutcome: 584 """What a tool call produced. `content` is what the model will read.""" 585 586 status: str # ok | invalid | unknown_tool | denied | rejected | awaiting_approval | declined | dry_run | duplicate 587 content: str 588 589 @property 590 def is_error(self) -> bool: 591 return self.status not in ("ok", "dry_run", "duplicate") 592 593 594@dataclass 595class ToolRegistry: 596 tools: dict[str, Tool] = field(default_factory=dict) 597 # idempotency key -> the outcome of the call that first used it. 598 _completed: dict[str, ToolOutcome] = field(default_factory=dict) 599 600 def register( 601 self, name: str, description: str, input_schema: dict[str, Any], fn: Callable[..., Any], **options: Any 602 ) -> Tool: 603 tool = Tool(name, description, input_schema, fn, **options) 604 self.tools[name] = tool 605 return tool 606 607 def definitions(self, strict: bool = False) -> list[dict[str, Any]]: 608 """Tool definitions in the Anthropic Messages API shape. 609 610 `strict=True` adds `"strict": true`, which makes the API guarantee the 611 model's arguments validate against the schema. Strict schemas must 612 forbid unknown fields (`additionalProperties: false`). 613 """ 614 defs = [] 615 for t in self.tools.values(): 616 d: dict[str, Any] = {"name": t.name, "description": t.description, "input_schema": t.input_schema} 617 if strict: 618 d["input_schema"] = {**t.input_schema, "additionalProperties": False} 619 d["strict"] = True 620 defs.append(d) 621 return defs 622 623 def call( 624 self, 625 name: str, 626 args: dict[str, Any], 627 credentials: frozenset[str] = frozenset(), 628 idempotency_key: str | None = None, 629 dry_run: bool = False, 630 approver: Callable[[str, dict[str, Any]], bool] | None = None, 631 ) -> ToolOutcome: 632 """Run a tool call from the model through every check, in order.""" 633 tool = self.tools.get(name) 634 if tool is None: 635 return ToolOutcome("unknown_tool", f"Unknown tool '{name}'. Available: {', '.join(sorted(self.tools))}.") 636 # Permissions first: a caller without the scope learns nothing more about the tool. 637 missing = sorted(tool.scopes - credentials) 638 if missing: 639 return ToolOutcome( 640 "denied", 641 f"Permission denied: {name} needs scope {missing[0]!r}; this agent has {sorted(credentials)}.", 642 ) 643 problems = validate(args, tool.input_schema) 644 if problems: 645 return ToolOutcome("invalid", f"Invalid arguments for {name}:\n" + "\n".join(f"- {p}" for p in problems)) 646 # Well-formed is not the same as valid: "C-999" matches the pattern but may not exist. 647 problems = tool.check(args) if tool.check else [] 648 if problems: 649 return ToolOutcome("rejected", "\n".join(problems)) 650 # Dry run: every check has passed, so describe exactly what would happen, then stop. 651 if dry_run: 652 planned = json.dumps(args, sort_keys=True) 653 return ToolOutcome("dry_run", f"Dry run: would call {name} with {planned}. Nothing was changed.") 654 # Human approval for irreversible or high-value actions. With no approver 655 # attached, the call parks instead of running; a person can approve it later. 656 if tool.requires_approval(args): 657 if approver is None: 658 return ToolOutcome("awaiting_approval", f"{name} needs human approval. It has been queued; tell the user.") 659 if not approver(name, args): 660 return ToolOutcome("declined", f"A human declined {name}. Do not retry; tell the user it was not approved.") 661 # Idempotency: a retry carrying the same key returns the first result instead of acting again. 662 if idempotency_key is not None and idempotency_key in self._completed: 663 return ToolOutcome("duplicate", self._completed[idempotency_key].content) 664 result = tool.fn(**args) 665 outcome = ToolOutcome("ok", result if isinstance(result, str) else json.dumps(result, default=str)) 666 if idempotency_key is not None: 667 self._completed[idempotency_key] = outcome 668 return outcome 669 670 671# --------------------------------------------------------------------------- 672# Tool descriptions are prompts: the model chooses from their words alone 673# --------------------------------------------------------------------------- 674 675# The payment tool from the worked example in section 2. `additionalProperties: 676# False` is what turns a typo like "ammount" into an error instead of a field 677# that is silently ignored. 678PAYMENT_SCHEMA = { 679 "type": "object", 680 "properties": { 681 "amount": {"type": "number", "minimum": 0.01}, 682 "currency": {"type": "string", "enum": ["EUR", "GBP", "USD"]}, 683 "pay_on": {"type": "string", "pattern": r"^\d{4}-\d{2}-\d{2}$", "description": "date as YYYY-MM-DD"}, 684 }, 685 "required": ["amount", "currency"], 686 "additionalProperties": False, 687} 688 689_OBJ = {"type": "object", "properties": {"query": {"type": "string"}}, "required": ["query"]} 690 691VAGUE_TOOLS = [ 692 {"name": "search_docs", "description": "Searches for information.", "input_schema": _OBJ}, 693 {"name": "lookup_record", "description": "Looks up information about things.", "input_schema": _OBJ}, 694 {"name": "find_item", "description": "Finds information in the system.", "input_schema": _OBJ}, 695] 696 697PRECISE_TOOLS = [ 698 { 699 "name": "search_docs", 700 "description": ( 701 "Search the company policy knowledge base: how-to guides and rules for PTO, vacation, travel, " 702 "flights, expenses and VPN. Use for questions about a policy. Not for customers or tickets." 703 ), 704 "input_schema": _OBJ, 705 }, 706 { 707 "name": "lookup_record", 708 "description": ( 709 "Get one customer record by customer id or name: plan, billing status and balance. Use for " 710 "questions about a specific customer. Not for policies or tickets." 711 ), 712 "input_schema": _OBJ, 713 }, 714 { 715 "name": "find_item", 716 "description": ( 717 "Find support tickets by ticket number or status (open, closed, escalated). Use for questions " 718 "about tickets. Not for policies or customers." 719 ), 720 "input_schema": _OBJ, 721 }, 722] 723 724# (user request, the tool that should handle it) 725LABELED_REQUESTS = [ 726 ("what is the travel policy for flights", "search_docs"), 727 ("how many PTO days do I get", "search_docs"), 728 ("billing status for customer 1042", "lookup_record"), 729 ("balance for customer acme", "lookup_record"), 730 ("is ticket 553 still open", "find_item"), 731 ("escalated tickets this week", "find_item"), 732] 733 734 735def pick_tool(request: str, tool_defs: list[dict[str, Any]]) -> str: 736 """A stand-in model: choose the tool whose name + description shares the most words with the request. 737 738 Ties go to the first tool listed, which is how an arbitrary guess looks. 739 """ 740 from primer.common.text import tokenize 741 742 words = set(tokenize(request)) 743 744 def overlap(d: dict[str, Any]) -> int: 745 return len(words & set(tokenize(d["name"].replace("_", " ") + " " + d["description"]))) 746 747 return max(tool_defs, key=overlap)["name"] 748 749 750def selection_accuracy(tool_defs: list[dict[str, Any]], labeled: list[tuple[str, str]]) -> tuple[int, int]: 751 """(correct picks, total requests).""" 752 return sum(pick_tool(q, tool_defs) == want for q, want in labeled), len(labeled) 753 754 755def chain_success(p: float, n_calls: int) -> float: 756 """Probability that n independent calls, each succeeding with probability p, all succeed: p**n.""" 757 return p**n_calls 758 759 760# --------------------------------------------------------------------------- 761# Dynamic tool loading: send only the tools that fit the request 762# --------------------------------------------------------------------------- 763 764_CATALOG_SPEC = [ 765 ("reset_password", "Reset a forgotten password or unlock a locked account."), 766 ("enroll_mfa", "Enroll a user in two-factor authentication with an authenticator app."), 767 ("check_vpn_status", "Check whether the VPN tunnel for remote access is up."), 768 ("renew_device_certificate", "Renew an expired device certificate on a laptop."), 769 ("request_laptop", "Request new laptop hardware or a monitor."), 770 ("report_phishing", "Report a suspicious phishing email to security."), 771 ("fix_printer", "Troubleshoot a broken printer or order toner."), 772 ("submit_expense", "Submit an expense with receipts for reimbursement, including car mileage."), 773 ("book_travel", "Book flights and hotels for a business trip."), 774 ("get_per_diem", "Get the daily per-diem rate for travel meals."), 775 ("request_pto", "Request vacation or PTO days off."), 776 ("get_pto_balance", "Get the remaining PTO and vacation balance."), 777 ("report_sick_day", "Report a sick day or sick leave."), 778 ("request_parental_leave", "Request parental leave for a birth or adoption."), 779 ("get_payslip", "Get a payslip or payroll statement."), 780 ("get_salary_band", "Get the salary band and bonus target for a role."), 781 ("start_onboarding", "Start onboarding for a new hire and schedule orientation."), 782 ("list_invoices", "List vendor invoices for a quarter."), 783 ("list_payments", "List payments sent to vendors."), 784 ("reconcile_invoices", "Reconcile vendor invoices against payments and list mismatches."), 785 ("create_invoice", "Create and send an invoice to a customer."), 786 ("send_email", "Send an email from the shared inbox."), 787 ("search_policies", "Search company policies and guidelines."), 788 ("open_ticket", "Open an IT support ticket for an issue."), 789 ("close_ticket", "Close a resolved IT support ticket."), 790 ("get_org_chart", "Look up who reports to whom in the org chart."), 791 ("book_meeting_room", "Book a meeting room in an office building."), 792 ("order_office_supplies", "Order office supplies such as pens and notebooks."), 793 ("translate_text", "Translate text between languages."), 794 ("summarize_document", "Summarize a long document."), 795] 796 797TOOL_CATALOG: list[dict[str, Any]] = [ 798 {"name": n, "description": d, "input_schema": {"type": "object", "properties": {}}} for n, d in _CATALOG_SPEC 799] 800 801 802def select_tools(request: str, catalog: list[dict[str, Any]], k: int = 5) -> list[dict[str, Any]]: 803 """Return the k tool definitions whose descriptions are most similar to the request. 804 805 Same machinery as retrieval (`primer.agents.rag`): embed the request, embed 806 each description once, rank by cosine similarity. Here it retrieves tools 807 instead of documents. 808 """ 809 from primer.common.embedder import ConceptEmbedder 810 811 emb = ConceptEmbedder() 812 tool_vecs = emb.encode([d["name"].replace("_", " ") + ". " + d["description"] for d in catalog]) 813 scores = tool_vecs @ emb.encode(request) # unit vectors, so dot product = cosine similarity 814 order = sorted(range(len(catalog)), key=lambda i: -scores[i]) 815 return [catalog[i] for i in order[:k]] 816 817 818# --------------------------------------------------------------------------- 819# Figures and walkthrough 820# --------------------------------------------------------------------------- 821 822FIGURE_REQUESTS = [ 823 "I forgot my password and I'm locked out", 824 "submit my car mileage expense", 825 "how many vacation days are left", 826 "suspicious email asking for my login", 827 "reconcile vendor invoices for Q3", 828] 829 830 831def figures() -> dict: 832 """Plots computed from this lesson's own code (matplotlib imported here, not at module level).""" 833 import matplotlib 834 835 matplotlib.use("Agg") 836 import matplotlib.pyplot as plt 837 import numpy as np 838 839 from primer.common.embedder import ConceptEmbedder 840 841 figs = {} 842 843 n = np.arange(1, 21) 844 fig, ax = plt.subplots(figsize=(7, 4)) 845 for p in (0.90, 0.95, 0.97, 0.99): 846 ax.plot(n, [chain_success(p, int(k)) for k in n], "o-", ms=3, label=f"p = {p:.2f} per call") 847 ax.set(xlabel="calls in the chain (n)", ylabel="P(every call succeeds) = p^n", ylim=(0, 1.02), 848 title="Reliability compounds: fewer, higher-level tools") 849 ax.legend() 850 figs["compounding"] = fig 851 852 vague, total = selection_accuracy(VAGUE_TOOLS, LABELED_REQUESTS) 853 precise, _ = selection_accuracy(PRECISE_TOOLS, LABELED_REQUESTS) 854 fig, ax = plt.subplots(figsize=(5, 4)) 855 bars = ax.bar(["vague descriptions", "precise descriptions"], [vague, precise], color=["#d98c7a", "#7ab87a"]) 856 ax.bar_label(bars, labels=[f"{vague}/{total}", f"{precise}/{total}"]) 857 ax.set(ylabel="requests routed to the right tool", ylim=(0, total + 0.8), title="Same model, same requests, new descriptions") 858 figs["selection_accuracy"] = fig 859 860 emb = ConceptEmbedder() 861 tool_vecs = emb.encode([d["name"].replace("_", " ") + ". " + d["description"] for d in TOOL_CATALOG]) 862 sims = emb.encode(FIGURE_REQUESTS) @ tool_vecs.T # (requests, tools) 863 fig, ax = plt.subplots(figsize=(11, 3.8)) 864 im = ax.imshow(sims, cmap="viridis", aspect="auto") 865 ax.set_xticks(range(len(TOOL_CATALOG)), [d["name"] for d in TOOL_CATALOG], rotation=75, ha="right", fontsize=7) 866 ax.set_yticks(range(len(FIGURE_REQUESTS)), FIGURE_REQUESTS, fontsize=8) 867 ax.set_title("Cosine similarity: each request lights up a few tools") 868 fig.colorbar(im, ax=ax, fraction=0.02) 869 fig.tight_layout() 870 figs["tool_similarity"] = fig 871 return figs 872 873 874def demo() -> None: 875 from primer._show import banner, say, table, takeaway 876 877 banner("1. A tool definition is a form template (JSON Schema)") 878 reg = ToolRegistry() 879 reg.register("add", "Add two integers.", {"type": "object", "properties": {"a": {"type": "integer"}, "b": {"type": "integer"}}, "required": ["a", "b"]}, lambda a, b: a + b) 880 print(json.dumps(reg.definitions()[0], indent=2)) 881 print() 882 say("The model fills the form in; your code decides whether to act on it.") 883 for args in ({"a": 2, "b": 3}, {"a": "two"}): 884 o = reg.call("add", args) 885 print(f" add({args}) -> [{o.status}] {o.content}") 886 print() 887 888 banner("2. Validation: every problem at once, each with its fix") 889 bad = {"ammount": 5, "currency": "usd", "pay_on": "next friday"} 890 print(f" arguments: {bad}") 891 for e in validate(bad, PAYMENT_SCHEMA): 892 print(f" - {e}") 893 print() 894 takeaway("'invalid input' makes the model guess. A list of fixes gets it right in one retry.") 895 896 banner("3. Descriptions are prompts") 897 table( 898 ["request", "expected", "vague picks", "precise picks"], 899 [(q, want, pick_tool(q, VAGUE_TOOLS), pick_tool(q, PRECISE_TOOLS)) for q, want in LABELED_REQUESTS], 900 ) 901 v, t = selection_accuracy(VAGUE_TOOLS, LABELED_REQUESTS) 902 p, _ = selection_accuracy(PRECISE_TOOLS, LABELED_REQUESTS) 903 say(f"Vague: {v}/{t} correct. Precise: {p}/{t}. Only the descriptions changed.") 904 905 banner("4. Fewer, higher-level tools: p^n") 906 table(["per-call p", "1 call", "5 calls", "10 calls", "20 calls"], 907 [(pp, *(chain_success(pp, n) for n in (1, 5, 10, 20))) for pp in (0.90, 0.95, 0.97, 0.99)], floatfmt=".3f") 908 909 banner("5. Dynamic tool loading: 30 tools in the catalogue, 5 sent") 910 for q in FIGURE_REQUESTS[:3]: 911 print(f" {q!r:45} -> {[d['name'] for d in select_tools(q, TOOL_CATALOG, k=3)]}") 912 print() 913 914 banner("6. Safety: scopes, dry run, approval, idempotency") 915 ledger: list = [] 916 917 def refund(customer_id: str, amount: float) -> str: 918 ledger.append((customer_id, amount)) 919 return f"refunded {amount:.2f} to {customer_id}" 920 921 pay = ToolRegistry() 922 pay.register( 923 "refund_payment", "Refund a customer payment.", 924 {"type": "object", "properties": {"customer_id": {"type": "string"}, "amount": {"type": "number"}}, "required": ["customer_id", "amount"]}, 925 refund, scopes=frozenset({"payments:write"}), side_effect="write", needs_approval=lambda a: a["amount"] > 500, 926 ) 927 ok = frozenset({"payments:write"}) 928 steps = [ 929 ("ticket-reading agent", dict(credentials=frozenset({"tickets:read"}))), 930 ("dry run", dict(credentials=ok, dry_run=True)), 931 ("$900, no approver", dict(credentials=ok, args={"customer_id": "C-100", "amount": 900})), 932 ("$20, key req-1", dict(credentials=ok, idempotency_key="req-1")), 933 ("retry $20, key req-1", dict(credentials=ok, idempotency_key="req-1")), 934 ] 935 for label, kw in steps: 936 args = kw.pop("args", {"customer_id": "C-100", "amount": 20}) 937 o = pay.call("refund_payment", args, **kw) 938 print(f" {label:22} -> [{o.status}] {o.content}") 939 print(f"\n ledger after all of that: {ledger} (one refund)\n") 940 takeaway("Five attempts, one refund: least privilege, rehearsal, approval and idempotency each did their job.") 941 942 943if __name__ == "__main__": 944 demo()
528def validate(value: Any, schema: dict[str, Any], path: str = "$") -> list[str]:
529    """Check `value` against a JSON Schema subset. Returns every problem found."""
530    expected = schema.get("type")
531    if expected and not _type_ok(_json_type(value), expected):
532        # Stop here: the other checks assume the right type.
533        return [f"{path}: expected {expected}, got {_json_type(value)} ({value!r})"]
534
535    errors: list[str] = []
536    if "enum" in schema and value not in schema["enum"]:
537        # Listing the allowed values lets the model fix the call in one retry.
538        errors.append(f"{path}: must be one of {schema['enum']}, got {value!r}")
539    if isinstance(value, str) and "pattern" in schema and not re.search(schema["pattern"], value):
540        hint = schema.get("description", f"a string matching {schema['pattern']}")
541        errors.append(f"{path}: {value!r} does not match the required format. Expected: {hint}")
542    if isinstance(value, (int, float)) and not isinstance(value, bool):
543        if "minimum" in schema and value < schema["minimum"]:
544            errors.append(f"{path}: must be >= {schema['minimum']}, got {value}")
545        if "maximum" in schema and value > schema["maximum"]:
546            errors.append(f"{path}: must be <= {schema['maximum']}, got {value}")
547    if isinstance(value, dict):
548        for name in schema.get("required", []):
549            if name not in value:
550                errors.append(f"{path}: missing required field '{name}'")
551        props = schema.get("properties", {})
552        for name, sub in value.items():
553            if name in props:
554                errors += validate(sub, props[name], f"{path}.{name}")
555            elif schema.get("additionalProperties") is False:
556                errors.append(f"{path}: unexpected field '{name}' (allowed: {', '.join(props)})")
557    if isinstance(value, list) and "items" in schema:
558        for i, item in enumerate(value):
559            errors += validate(item, schema["items"], f"{path}[{i}]")
560    return errors
Check value against a JSON Schema subset. Returns every problem found.
563@dataclass
564class Tool:
565    name: str
566    description: str
567    input_schema: dict[str, Any]
568    fn: Callable[..., Any]
569    # Business-rule check run after the schema passes: "does this customer exist?"
570    # Returns a list of actionable problems; empty means OK.
571    check: Callable[[dict[str, Any]], list[str]] | None = None
572    # Permissions the caller's credentials must include to run this tool.
573    scopes: frozenset[str] = frozenset()
574    # read | write | irreversible. Writes get idempotency; irreversible ones need approval.
575    side_effect: str = "read"
576    # Extra rule for when a human must approve, e.g. lambda args: args["amount"] > 500.
577    needs_approval: Callable[[dict[str, Any]], bool] | None = None
578
579    def requires_approval(self, args: dict[str, Any]) -> bool:
580        return self.side_effect == "irreversible" or bool(self.needs_approval and self.needs_approval(args))
583@dataclass
584class ToolOutcome:
585    """What a tool call produced. `content` is what the model will read."""
586
587    status: str  # ok | invalid | unknown_tool | denied | rejected | awaiting_approval | declined | dry_run | duplicate
588    content: str
589
590    @property
591    def is_error(self) -> bool:
592        return self.status not in ("ok", "dry_run", "duplicate")
What a tool call produced. content is what the model will read.
595@dataclass
596class ToolRegistry:
597    tools: dict[str, Tool] = field(default_factory=dict)
598    # idempotency key -> the outcome of the call that first used it.
599    _completed: dict[str, ToolOutcome] = field(default_factory=dict)
600
601    def register(
602        self, name: str, description: str, input_schema: dict[str, Any], fn: Callable[..., Any], **options: Any
603    ) -> Tool:
604        tool = Tool(name, description, input_schema, fn, **options)
605        self.tools[name] = tool
606        return tool
607
608    def definitions(self, strict: bool = False) -> list[dict[str, Any]]:
609        """Tool definitions in the Anthropic Messages API shape.
610
611        `strict=True` adds `"strict": true`, which makes the API guarantee the
612        model's arguments validate against the schema. Strict schemas must
613        forbid unknown fields (`additionalProperties: false`).
614        """
615        defs = []
616        for t in self.tools.values():
617            d: dict[str, Any] = {"name": t.name, "description": t.description, "input_schema": t.input_schema}
618            if strict:
619                d["input_schema"] = {**t.input_schema, "additionalProperties": False}
620                d["strict"] = True
621            defs.append(d)
622        return defs
623
624    def call(
625        self,
626        name: str,
627        args: dict[str, Any],
628        credentials: frozenset[str] = frozenset(),
629        idempotency_key: str | None = None,
630        dry_run: bool = False,
631        approver: Callable[[str, dict[str, Any]], bool] | None = None,
632    ) -> ToolOutcome:
633        """Run a tool call from the model through every check, in order."""
634        tool = self.tools.get(name)
635        if tool is None:
636            return ToolOutcome("unknown_tool", f"Unknown tool '{name}'. Available: {', '.join(sorted(self.tools))}.")
637        # Permissions first: a caller without the scope learns nothing more about the tool.
638        missing = sorted(tool.scopes - credentials)
639        if missing:
640            return ToolOutcome(
641                "denied",
642                f"Permission denied: {name} needs scope {missing[0]!r}; this agent has {sorted(credentials)}.",
643            )
644        problems = validate(args, tool.input_schema)
645        if problems:
646            return ToolOutcome("invalid", f"Invalid arguments for {name}:\n" + "\n".join(f"- {p}" for p in problems))
647        # Well-formed is not the same as valid: "C-999" matches the pattern but may not exist.
648        problems = tool.check(args) if tool.check else []
649        if problems:
650            return ToolOutcome("rejected", "\n".join(problems))
651        # Dry run: every check has passed, so describe exactly what would happen, then stop.
652        if dry_run:
653            planned = json.dumps(args, sort_keys=True)
654            return ToolOutcome("dry_run", f"Dry run: would call {name} with {planned}. Nothing was changed.")
655        # Human approval for irreversible or high-value actions. With no approver
656        # attached, the call parks instead of running; a person can approve it later.
657        if tool.requires_approval(args):
658            if approver is None:
659                return ToolOutcome("awaiting_approval", f"{name} needs human approval. It has been queued; tell the user.")
660            if not approver(name, args):
661                return ToolOutcome("declined", f"A human declined {name}. Do not retry; tell the user it was not approved.")
662        # Idempotency: a retry carrying the same key returns the first result instead of acting again.
663        if idempotency_key is not None and idempotency_key in self._completed:
664            return ToolOutcome("duplicate", self._completed[idempotency_key].content)
665        result = tool.fn(**args)
666        outcome = ToolOutcome("ok", result if isinstance(result, str) else json.dumps(result, default=str))
667        if idempotency_key is not None:
668            self._completed[idempotency_key] = outcome
669        return outcome
608    def definitions(self, strict: bool = False) -> list[dict[str, Any]]:
609        """Tool definitions in the Anthropic Messages API shape.
610
611        `strict=True` adds `"strict": true`, which makes the API guarantee the
612        model's arguments validate against the schema. Strict schemas must
613        forbid unknown fields (`additionalProperties: false`).
614        """
615        defs = []
616        for t in self.tools.values():
617            d: dict[str, Any] = {"name": t.name, "description": t.description, "input_schema": t.input_schema}
618            if strict:
619                d["input_schema"] = {**t.input_schema, "additionalProperties": False}
620                d["strict"] = True
621            defs.append(d)
622        return defs
Tool definitions in the Anthropic Messages API shape.
strict=True adds "strict": true, which makes the API guarantee the
model's arguments validate against the schema. Strict schemas must
forbid unknown fields (additionalProperties: false).
624    def call(
625        self,
626        name: str,
627        args: dict[str, Any],
628        credentials: frozenset[str] = frozenset(),
629        idempotency_key: str | None = None,
630        dry_run: bool = False,
631        approver: Callable[[str, dict[str, Any]], bool] | None = None,
632    ) -> ToolOutcome:
633        """Run a tool call from the model through every check, in order."""
634        tool = self.tools.get(name)
635        if tool is None:
636            return ToolOutcome("unknown_tool", f"Unknown tool '{name}'. Available: {', '.join(sorted(self.tools))}.")
637        # Permissions first: a caller without the scope learns nothing more about the tool.
638        missing = sorted(tool.scopes - credentials)
639        if missing:
640            return ToolOutcome(
641                "denied",
642                f"Permission denied: {name} needs scope {missing[0]!r}; this agent has {sorted(credentials)}.",
643            )
644        problems = validate(args, tool.input_schema)
645        if problems:
646            return ToolOutcome("invalid", f"Invalid arguments for {name}:\n" + "\n".join(f"- {p}" for p in problems))
647        # Well-formed is not the same as valid: "C-999" matches the pattern but may not exist.
648        problems = tool.check(args) if tool.check else []
649        if problems:
650            return ToolOutcome("rejected", "\n".join(problems))
651        # Dry run: every check has passed, so describe exactly what would happen, then stop.
652        if dry_run:
653            planned = json.dumps(args, sort_keys=True)
654            return ToolOutcome("dry_run", f"Dry run: would call {name} with {planned}. Nothing was changed.")
655        # Human approval for irreversible or high-value actions. With no approver
656        # attached, the call parks instead of running; a person can approve it later.
657        if tool.requires_approval(args):
658            if approver is None:
659                return ToolOutcome("awaiting_approval", f"{name} needs human approval. It has been queued; tell the user.")
660            if not approver(name, args):
661                return ToolOutcome("declined", f"A human declined {name}. Do not retry; tell the user it was not approved.")
662        # Idempotency: a retry carrying the same key returns the first result instead of acting again.
663        if idempotency_key is not None and idempotency_key in self._completed:
664            return ToolOutcome("duplicate", self._completed[idempotency_key].content)
665        result = tool.fn(**args)
666        outcome = ToolOutcome("ok", result if isinstance(result, str) else json.dumps(result, default=str))
667        if idempotency_key is not None:
668            self._completed[idempotency_key] = outcome
669        return outcome
Run a tool call from the model through every check, in order.
736def pick_tool(request: str, tool_defs: list[dict[str, Any]]) -> str:
737    """A stand-in model: choose the tool whose name + description shares the most words with the request.
738
739    Ties go to the first tool listed, which is how an arbitrary guess looks.
740    """
741    from primer.common.text import tokenize
742
743    words = set(tokenize(request))
744
745    def overlap(d: dict[str, Any]) -> int:
746        return len(words & set(tokenize(d["name"].replace("_", " ") + " " + d["description"])))
747
748    return max(tool_defs, key=overlap)["name"]
A stand-in model: choose the tool whose name + description shares the most words with the request.
Ties go to the first tool listed, which is how an arbitrary guess looks.
751def selection_accuracy(tool_defs: list[dict[str, Any]], labeled: list[tuple[str, str]]) -> tuple[int, int]:
752    """(correct picks, total requests)."""
753    return sum(pick_tool(q, tool_defs) == want for q, want in labeled), len(labeled)
(correct picks, total requests).
756def chain_success(p: float, n_calls: int) -> float:
757    """Probability that n independent calls, each succeeding with probability p, all succeed: p**n."""
758    return p**n_calls
Probability that n independent calls, each succeeding with probability p, all succeed: p**n.
803def select_tools(request: str, catalog: list[dict[str, Any]], k: int = 5) -> list[dict[str, Any]]:
804    """Return the k tool definitions whose descriptions are most similar to the request.
805
806    Same machinery as retrieval (`primer.agents.rag`): embed the request, embed
807    each description once, rank by cosine similarity. Here it retrieves tools
808    instead of documents.
809    """
810    from primer.common.embedder import ConceptEmbedder
811
812    emb = ConceptEmbedder()
813    tool_vecs = emb.encode([d["name"].replace("_", " ") + ". " + d["description"] for d in catalog])
814    scores = tool_vecs @ emb.encode(request)  # unit vectors, so dot product = cosine similarity
815    order = sorted(range(len(catalog)), key=lambda i: -scores[i])
816    return [catalog[i] for i in order[:k]]
Return the k tool definitions whose descriptions are most similar to the request.
Same machinery as retrieval (primer.agents.rag): embed the request, embed
each description once, rank by cosine similarity. Here it retrieves tools
instead of documents.
832def figures() -> dict:
833    """Plots computed from this lesson's own code (matplotlib imported here, not at module level)."""
834    import matplotlib
835
836    matplotlib.use("Agg")
837    import matplotlib.pyplot as plt
838    import numpy as np
839
840    from primer.common.embedder import ConceptEmbedder
841
842    figs = {}
843
844    n = np.arange(1, 21)
845    fig, ax = plt.subplots(figsize=(7, 4))
846    for p in (0.90, 0.95, 0.97, 0.99):
847        ax.plot(n, [chain_success(p, int(k)) for k in n], "o-", ms=3, label=f"p = {p:.2f} per call")
848    ax.set(xlabel="calls in the chain (n)", ylabel="P(every call succeeds) = p^n", ylim=(0, 1.02),
849           title="Reliability compounds: fewer, higher-level tools")
850    ax.legend()
851    figs["compounding"] = fig
852
853    vague, total = selection_accuracy(VAGUE_TOOLS, LABELED_REQUESTS)
854    precise, _ = selection_accuracy(PRECISE_TOOLS, LABELED_REQUESTS)
855    fig, ax = plt.subplots(figsize=(5, 4))
856    bars = ax.bar(["vague descriptions", "precise descriptions"], [vague, precise], color=["#d98c7a", "#7ab87a"])
857    ax.bar_label(bars, labels=[f"{vague}/{total}", f"{precise}/{total}"])
858    ax.set(ylabel="requests routed to the right tool", ylim=(0, total + 0.8), title="Same model, same requests, new descriptions")
859    figs["selection_accuracy"] = fig
860
861    emb = ConceptEmbedder()
862    tool_vecs = emb.encode([d["name"].replace("_", " ") + ". " + d["description"] for d in TOOL_CATALOG])
863    sims = emb.encode(FIGURE_REQUESTS) @ tool_vecs.T  # (requests, tools)
864    fig, ax = plt.subplots(figsize=(11, 3.8))
865    im = ax.imshow(sims, cmap="viridis", aspect="auto")
866    ax.set_xticks(range(len(TOOL_CATALOG)), [d["name"] for d in TOOL_CATALOG], rotation=75, ha="right", fontsize=7)
867    ax.set_yticks(range(len(FIGURE_REQUESTS)), FIGURE_REQUESTS, fontsize=8)
868    ax.set_title("Cosine similarity: each request lights up a few tools")
869    fig.colorbar(im, ax=ax, fraction=0.02)
870    fig.tight_layout()
871    figs["tool_similarity"] = fig
872    return figs
Plots computed from this lesson's own code (matplotlib imported here, not at module level).
875def demo() -> None:
876    from primer._show import banner, say, table, takeaway
877
878    banner("1. A tool definition is a form template (JSON Schema)")
879    reg = ToolRegistry()
880    reg.register("add", "Add two integers.", {"type": "object", "properties": {"a": {"type": "integer"}, "b": {"type": "integer"}}, "required": ["a", "b"]}, lambda a, b: a + b)
881    print(json.dumps(reg.definitions()[0], indent=2))
882    print()
883    say("The model fills the form in; your code decides whether to act on it.")
884    for args in ({"a": 2, "b": 3}, {"a": "two"}):
885        o = reg.call("add", args)
886        print(f"  add({args}) -> [{o.status}] {o.content}")
887    print()
888
889    banner("2. Validation: every problem at once, each with its fix")
890    bad = {"ammount": 5, "currency": "usd", "pay_on": "next friday"}
891    print(f"  arguments: {bad}")
892    for e in validate(bad, PAYMENT_SCHEMA):
893        print(f"  - {e}")
894    print()
895    takeaway("'invalid input' makes the model guess. A list of fixes gets it right in one retry.")
896
897    banner("3. Descriptions are prompts")
898    table(
899        ["request", "expected", "vague picks", "precise picks"],
900        [(q, want, pick_tool(q, VAGUE_TOOLS), pick_tool(q, PRECISE_TOOLS)) for q, want in LABELED_REQUESTS],
901    )
902    v, t = selection_accuracy(VAGUE_TOOLS, LABELED_REQUESTS)
903    p, _ = selection_accuracy(PRECISE_TOOLS, LABELED_REQUESTS)
904    say(f"Vague: {v}/{t} correct. Precise: {p}/{t}. Only the descriptions changed.")
905
906    banner("4. Fewer, higher-level tools: p^n")
907    table(["per-call p", "1 call", "5 calls", "10 calls", "20 calls"],
908          [(pp, *(chain_success(pp, n) for n in (1, 5, 10, 20))) for pp in (0.90, 0.95, 0.97, 0.99)], floatfmt=".3f")
909
910    banner("5. Dynamic tool loading: 30 tools in the catalogue, 5 sent")
911    for q in FIGURE_REQUESTS[:3]:
912        print(f"  {q!r:45} -> {[d['name'] for d in select_tools(q, TOOL_CATALOG, k=3)]}")
913    print()
914
915    banner("6. Safety: scopes, dry run, approval, idempotency")
916    ledger: list = []
917
918    def refund(customer_id: str, amount: float) -> str:
919        ledger.append((customer_id, amount))
920        return f"refunded {amount:.2f} to {customer_id}"
921
922    pay = ToolRegistry()
923    pay.register(
924        "refund_payment", "Refund a customer payment.",
925        {"type": "object", "properties": {"customer_id": {"type": "string"}, "amount": {"type": "number"}}, "required": ["customer_id", "amount"]},
926        refund, scopes=frozenset({"payments:write"}), side_effect="write", needs_approval=lambda a: a["amount"] > 500,
927    )
928    ok = frozenset({"payments:write"})
929    steps = [
930        ("ticket-reading agent", dict(credentials=frozenset({"tickets:read"}))),
931        ("dry run", dict(credentials=ok, dry_run=True)),
932        ("$900, no approver", dict(credentials=ok, args={"customer_id": "C-100", "amount": 900})),
933        ("$20, key req-1", dict(credentials=ok, idempotency_key="req-1")),
934        ("retry $20, key req-1", dict(credentials=ok, idempotency_key="req-1")),
935    ]
936    for label, kw in steps:
937        args = kw.pop("args", {"customer_id": "C-100", "amount": 20})
938        o = pay.call("refund_payment", args, **kw)
939        print(f"  {label:22} -> [{o.status}] {o.content}")
940    print(f"\n  ledger after all of that: {ledger}  (one refund)\n")
941    takeaway("Five attempts, one refund: least privilege, rehearsal, approval and idempotency each did their job.")